初始化项目,由ModelHub XC社区提供模型
Model: tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
51
.gitattributes
vendored
Normal file
51
.gitattributes
vendored
Normal file
@@ -0,0 +1,51 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.gguf* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ggml filter=lfs diff=lfs merge=lfs -text
|
||||
*.llamafile* filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
|
||||
merges.txt filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||
vocab.json filter=lfs diff=lfs merge=lfs -text
|
||||
202
LICENSE
Normal file
202
LICENSE
Normal file
@@ -0,0 +1,202 @@
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright 2024 Alibaba Cloud
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
228
README.md
Normal file
228
README.md
Normal file
@@ -0,0 +1,228 @@
|
||||
---
|
||||
library_name: transformers
|
||||
license: apache-2.0
|
||||
license_link: https://huggingface.co/Qwen/Qwen3-Coder-30B-A3B-Instruct/blob/main/LICENSE
|
||||
pipeline_tag: text-generation
|
||||
tags:
|
||||
- AWQ
|
||||
- 量化修复
|
||||
- vLLM
|
||||
base_model:
|
||||
- Qwen/Qwen3-Coder-30B-A3B-Instruct
|
||||
base_model_relation: quantized
|
||||
---
|
||||
# Qwen3-Coder-30B-A3B-Instruct-AWQ
|
||||
基础型 [Qwen3-Coder-30B-A3B-Instruct](https://www.modelscope.cn/models/Qwen3-Coder-30B-A3B-Instruct)
|
||||
|
||||
|
||||
### 【❗❗提醒❗❗】
|
||||
该模型4比特量化损失较大,需谨慎使用
|
||||
|
||||
|
||||
### 【Vllm 启动命令】
|
||||
<i>注: 4卡启动该模型一定要跟`--enable-expert-parallel` ,否则其专家张量TP整除除不尽;2卡则不需要。 </i>
|
||||
```
|
||||
CONTEXT_LENGTH=32768
|
||||
|
||||
vllm serve \
|
||||
tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ \
|
||||
--served-model-name Qwen3-Coder-30B-A3B-Instruct-AWQ \
|
||||
--enable-expert-parallel \
|
||||
--swap-space 16 \
|
||||
--max-num-seqs 512 \
|
||||
--max-model-len $CONTEXT_LENGTH \
|
||||
--max-seq-len-to-capture $CONTEXT_LENGTH \
|
||||
--gpu-memory-utilization 0.9 \
|
||||
--tensor-parallel-size 4 \
|
||||
--trust-remote-code \
|
||||
--disable-log-requests \
|
||||
--host 0.0.0.0 \
|
||||
--port 8000
|
||||
```
|
||||
|
||||
### 【依赖】
|
||||
|
||||
```
|
||||
vllm==0.10.0
|
||||
```
|
||||
|
||||
### 【模型更新日期】
|
||||
```
|
||||
2025-08-01
|
||||
1. 首次commit
|
||||
```
|
||||
|
||||
### 【模型列表】
|
||||
|
||||
| 文件大小 | 最近更新时间 |
|
||||
|--------|--------------|
|
||||
| `16GB` | `2025-08-01` |
|
||||
|
||||
|
||||
### 【模型下载】
|
||||
|
||||
```python
|
||||
from modelscope import snapshot_download
|
||||
snapshot_download('tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ', cache_dir="本地路径")
|
||||
```
|
||||
|
||||
### 【介绍】
|
||||
# Qwen3-Coder-30B-A3B-Instruct
|
||||
<a href="https://chat.qwen.ai/" target="_blank" style="margin: 2px;">
|
||||
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
||||
</a>
|
||||
|
||||
## Highlights
|
||||
|
||||
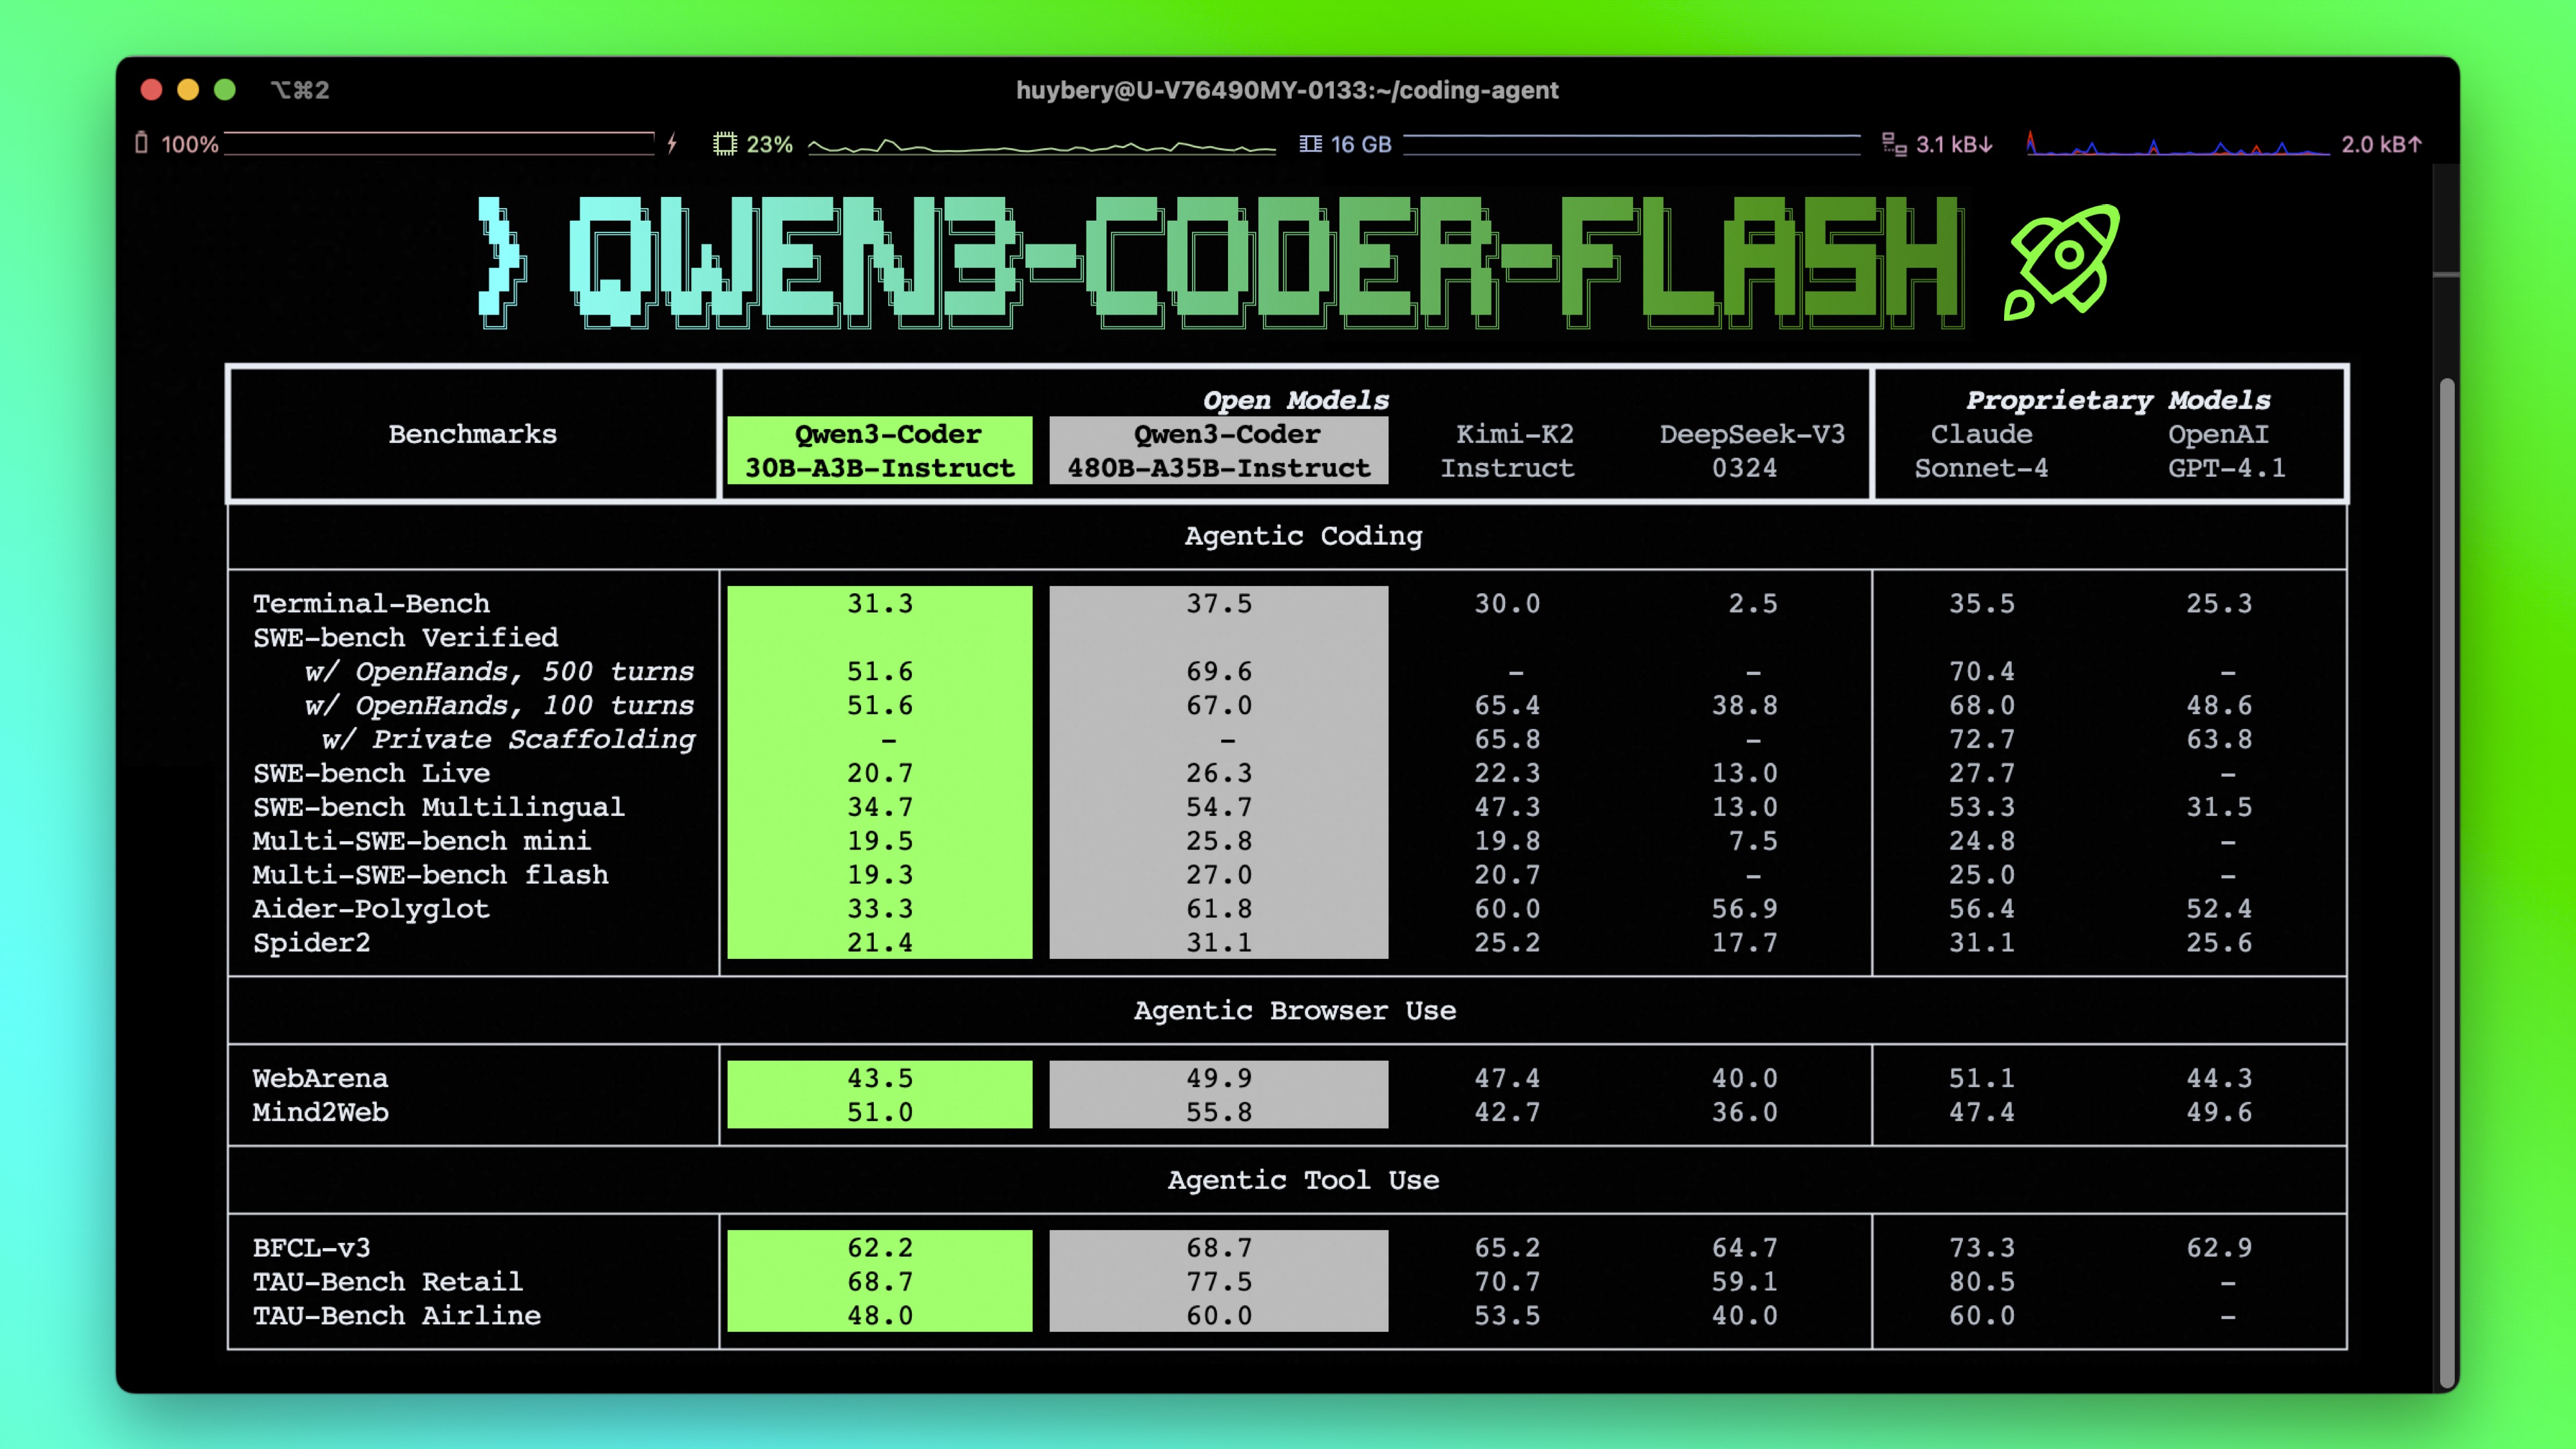
**Qwen3-Coder** is available in multiple sizes. Today, we're excited to introduce **Qwen3-Coder-30B-A3B-Instruct**. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
|
||||
|
||||
- **Significant Performance** among open models on **Agentic Coding**, **Agentic Browser-Use**, and other foundational coding tasks.
|
||||
- **Long-context Capabilities** with native support for **256K** tokens, extendable up to **1M** tokens using Yarn, optimized for repository-scale understanding.
|
||||
- **Agentic Coding** supporting for most platform such as **Qwen Code**, **CLINE**, featuring a specially designed function call format.
|
||||
|
||||
|
||||
|
||||
## Model Overview
|
||||
|
||||
**Qwen3-Coder-30B-A3B-Instruct** has the following features:
|
||||
- Type: Causal Language Models
|
||||
- Training Stage: Pretraining & Post-training
|
||||
- Number of Parameters: 30.5B in total and 3.3B activated
|
||||
- Number of Layers: 48
|
||||
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
|
||||
- Number of Experts: 128
|
||||
- Number of Activated Experts: 8
|
||||
- Context Length: **262,144 natively**.
|
||||
|
||||
**NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
|
||||
|
||||
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-coder/), [GitHub](https://github.com/QwenLM/Qwen3-Coder), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
||||
|
||||
|
||||
## Quickstart
|
||||
|
||||
We advise you to use the latest version of `transformers`.
|
||||
|
||||
With `transformers<4.51.0`, you will encounter the following error:
|
||||
```
|
||||
KeyError: 'qwen3_moe'
|
||||
```
|
||||
|
||||
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct"
|
||||
|
||||
# load the tokenizer and the model
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_name,
|
||||
torch_dtype="auto",
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
# prepare the model input
|
||||
prompt = "Write a quick sort algorithm."
|
||||
messages = [
|
||||
{"role": "user", "content": prompt}
|
||||
]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
)
|
||||
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
||||
|
||||
# conduct text completion
|
||||
generated_ids = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=65536
|
||||
)
|
||||
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
||||
|
||||
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
print("content:", content)
|
||||
```
|
||||
|
||||
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
|
||||
|
||||
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
||||
|
||||
## Agentic Coding
|
||||
|
||||
Qwen3-Coder excels in tool calling capabilities.
|
||||
|
||||
You can simply define or use any tools as following example.
|
||||
```python
|
||||
# Your tool implementation
|
||||
def square_the_number(num: float) -> dict:
|
||||
return num ** 2
|
||||
|
||||
# Define Tools
|
||||
tools=[
|
||||
{
|
||||
"type":"function",
|
||||
"function":{
|
||||
"name": "square_the_number",
|
||||
"description": "output the square of the number.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"required": ["input_num"],
|
||||
"properties": {
|
||||
'input_num': {
|
||||
'type': 'number',
|
||||
'description': 'input_num is a number that will be squared'
|
||||
}
|
||||
},
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
import OpenAI
|
||||
# Define LLM
|
||||
client = OpenAI(
|
||||
# Use a custom endpoint compatible with OpenAI API
|
||||
base_url='http://localhost:8000/v1', # api_base
|
||||
api_key="EMPTY"
|
||||
)
|
||||
|
||||
messages = [{'role': 'user', 'content': 'square the number 1024'}]
|
||||
|
||||
completion = client.chat.completions.create(
|
||||
messages=messages,
|
||||
model="Qwen3-Coder-30B-A3B-Instruct",
|
||||
max_tokens=65536,
|
||||
tools=tools,
|
||||
)
|
||||
|
||||
print(completion.choice[0])
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
To achieve optimal performance, we recommend the following settings:
|
||||
|
||||
1. **Sampling Parameters**:
|
||||
- We suggest using `temperature=0.7`, `top_p=0.8`, `top_k=20`, `repetition_penalty=1.05`.
|
||||
|
||||
2. **Adequate Output Length**: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
|
||||
|
||||
|
||||
### Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite.
|
||||
|
||||
```
|
||||
@misc{qwen3technicalreport,
|
||||
title={Qwen3 Technical Report},
|
||||
author={Qwen Team},
|
||||
year={2025},
|
||||
eprint={2505.09388},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2505.09388},
|
||||
}
|
||||
```
|
||||
48
config.json
Normal file
48
config.json
Normal file
@@ -0,0 +1,48 @@
|
||||
{
|
||||
"name_or_path": "tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ",
|
||||
"architectures": [
|
||||
"Qwen3MoeForCausalLM"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"decoder_sparse_step": 1,
|
||||
"eos_token_id": 151645,
|
||||
"head_dim": 128,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 2048,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 5472,
|
||||
"max_position_embeddings": 262144,
|
||||
"max_window_layers": 28,
|
||||
"mlp_only_layers": [],
|
||||
"model_type": "qwen3_moe",
|
||||
"moe_intermediate_size": 768,
|
||||
"norm_topk_prob": true,
|
||||
"num_attention_heads": 32,
|
||||
"num_experts": 128,
|
||||
"num_experts_per_tok": 8,
|
||||
"num_hidden_layers": 48,
|
||||
"num_key_value_heads": 4,
|
||||
"output_router_logits": false,
|
||||
"qkv_bias": false,
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_scaling": null,
|
||||
"rope_theta": 10000000,
|
||||
"router_aux_loss_coef": 0.0,
|
||||
"shared_expert_intermediate_size": 0,
|
||||
"sliding_window": null,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.52.3",
|
||||
"use_cache": true,
|
||||
"use_qk_norm": true,
|
||||
"use_sliding_window": false,
|
||||
"vocab_size": 151936,
|
||||
"quantization_config": {
|
||||
"quant_method": "awq",
|
||||
"bits": 4,
|
||||
"group_size": 128,
|
||||
"version": "gemm",
|
||||
"zero_point": true,
|
||||
"modules_to_not_convert": [".mlp.gate"]
|
||||
}
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework":"Pytorch","task":"text-generation"}
|
||||
12
generation_config.json
Normal file
12
generation_config.json
Normal file
@@ -0,0 +1,12 @@
|
||||
{
|
||||
"pad_token_id": 151643,
|
||||
"do_sample": true,
|
||||
"eos_token_id": [
|
||||
151645,
|
||||
151643
|
||||
],
|
||||
"repetition_penalty": 1.05,
|
||||
"temperature": 0.7,
|
||||
"top_p": 0.8,
|
||||
"top_k": 20
|
||||
}
|
||||
3
merges.txt
Normal file
3
merges.txt
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:599bab54075088774b1733fde865d5bd747cbcc7a547c5bc12610e874e26f5e3
|
||||
size 1671839
|
||||
3
model-00001-of-00006.safetensors
Normal file
3
model-00001-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9ceb3350115f42be1f5156e6a7121029cfdc837f97f0875b29db4139c4c19920
|
||||
size 3000922256
|
||||
3
model-00002-of-00006.safetensors
Normal file
3
model-00002-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:de1b0798c44741db570d2b1161003a1fde3cc3e52ded204fec343fae8c488a97
|
||||
size 3000967664
|
||||
3
model-00003-of-00006.safetensors
Normal file
3
model-00003-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:25b05653e45380e785f303277d9d6a9c22a96c4a87d7c4310f072a177b09f1d8
|
||||
size 3000968496
|
||||
3
model-00004-of-00006.safetensors
Normal file
3
model-00004-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c0a75553f408cdacefbedcc875930ce67d7ea9f6ed6546b0f25037195a6c7e95
|
||||
size 3000686168
|
||||
3
model-00005-of-00006.safetensors
Normal file
3
model-00005-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:2b036efba3962a1cebd0e4b5a5a5d20fdadf1b72a15e625818c9d8031a17c781
|
||||
size 3000966464
|
||||
3
model-00006-of-00006.safetensors
Normal file
3
model-00006-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:3eef55ae738a8357ec441a3c03e1ecfe0bd71742f1ec6ab2aa3ef0251226f0d2
|
||||
size 1804946136
|
||||
3
model.safetensors.index.json
Normal file
3
model.safetensors.index.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:3dac122ffd7c08d932b184229883862e932e5b4d154c0648da755beb8b629d76
|
||||
size 5077725
|
||||
675
qwen3coder_tool_parser.py
Normal file
675
qwen3coder_tool_parser.py
Normal file
@@ -0,0 +1,675 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
|
||||
import json
|
||||
import re
|
||||
import uuid
|
||||
from collections.abc import Sequence
|
||||
from typing import Union, Optional, Any, List, Dict
|
||||
from enum import Enum
|
||||
|
||||
from vllm.entrypoints.openai.protocol import (
|
||||
ChatCompletionRequest,
|
||||
ChatCompletionToolsParam,
|
||||
DeltaMessage,
|
||||
DeltaToolCall,
|
||||
DeltaFunctionCall,
|
||||
ExtractedToolCallInformation,
|
||||
FunctionCall,
|
||||
ToolCall,
|
||||
)
|
||||
from vllm.entrypoints.openai.tool_parsers.abstract_tool_parser import (
|
||||
ToolParser,
|
||||
ToolParserManager,
|
||||
)
|
||||
from vllm.logger import init_logger
|
||||
from vllm.transformers_utils.tokenizer import AnyTokenizer
|
||||
|
||||
logger = init_logger(__name__)
|
||||
|
||||
|
||||
@ToolParserManager.register_module("qwen3_xml")
|
||||
class Qwen3XMLToolParser(ToolParser):
|
||||
def __init__(self, tokenizer: AnyTokenizer):
|
||||
super().__init__(tokenizer)
|
||||
|
||||
self.current_tool_name_sent: bool = False
|
||||
self.prev_tool_call_arr: list[dict] = []
|
||||
self.current_tool_id: int = -1
|
||||
self.streamed_args_for_tool: list[str] = []
|
||||
|
||||
# Sentinel tokens for streaming mode
|
||||
self.tool_call_start_token: str = "<tool_call>"
|
||||
self.tool_call_end_token: str = "</tool_call>"
|
||||
self.tool_call_prefix: str = "<function="
|
||||
self.function_end_token: str = "</function>"
|
||||
self.parameter_prefix: str = "<parameter="
|
||||
self.parameter_end_token: str = "</parameter>"
|
||||
self.is_tool_call_started: bool = False
|
||||
self.failed_count: int = 0
|
||||
|
||||
# Enhanced streaming state - reset for each new message
|
||||
self._reset_streaming_state()
|
||||
|
||||
# Regex patterns
|
||||
self.tool_call_complete_regex = re.compile(
|
||||
r"<tool_call>(.*?)</tool_call>", re.DOTALL
|
||||
)
|
||||
self.tool_call_regex = re.compile(
|
||||
r"<tool_call>(.*?)</tool_call>|<tool_call>(.*?)$", re.DOTALL
|
||||
)
|
||||
self.tool_call_function_regex = re.compile(
|
||||
r"<function=(.*?)</function>|<function=(.*)$", re.DOTALL
|
||||
)
|
||||
self.tool_call_parameter_regex = re.compile(
|
||||
r"<parameter=(.*?)</parameter>|<parameter=(.*?)$", re.DOTALL
|
||||
)
|
||||
|
||||
if not self.model_tokenizer:
|
||||
raise ValueError(
|
||||
"The model tokenizer must be passed to the ToolParser "
|
||||
"constructor during construction."
|
||||
)
|
||||
|
||||
self.tool_call_start_token_id = self.vocab.get(self.tool_call_start_token)
|
||||
self.tool_call_end_token_id = self.vocab.get(self.tool_call_end_token)
|
||||
|
||||
if self.tool_call_start_token_id is None or self.tool_call_end_token_id is None:
|
||||
raise RuntimeError(
|
||||
"Qwen3 XML Tool parser could not locate tool call start/end "
|
||||
"tokens in the tokenizer!"
|
||||
)
|
||||
|
||||
logger.info(f"vLLM Successfully import tool parser {self.__class__.__name__} !")
|
||||
|
||||
def _generate_tool_call_id(self) -> str:
|
||||
"""Generate a unique tool call ID."""
|
||||
return f"call_{uuid.uuid4().hex[:24]}"
|
||||
|
||||
def _reset_streaming_state(self):
|
||||
"""Reset all streaming state."""
|
||||
self.current_tool_index = 0
|
||||
self.is_tool_call_started = False
|
||||
self.header_sent = False
|
||||
self.current_tool_id = None
|
||||
self.current_function_name = None
|
||||
self.current_param_name = None
|
||||
self.current_param_value = ""
|
||||
self.param_count = 0
|
||||
self.in_param = False
|
||||
self.in_function = False
|
||||
self.accumulated_text = ""
|
||||
self.json_started = False
|
||||
self.json_closed = False
|
||||
|
||||
def _parse_xml_function_call(
|
||||
self, function_call_str: str, tools: Optional[list[ChatCompletionToolsParam]]
|
||||
) -> Optional[ToolCall]:
|
||||
def get_arguments_config(func_name: str) -> dict:
|
||||
if tools is None:
|
||||
return {}
|
||||
for config in tools:
|
||||
if not hasattr(config, "type") or not (
|
||||
hasattr(config, "function") and hasattr(config.function, "name")
|
||||
):
|
||||
continue
|
||||
if config.type == "function" and config.function.name == func_name:
|
||||
if not hasattr(config.function, "parameters"):
|
||||
return {}
|
||||
params = config.function.parameters
|
||||
if isinstance(params, dict) and "properties" in params:
|
||||
return params["properties"]
|
||||
elif isinstance(params, dict):
|
||||
return params
|
||||
else:
|
||||
return {}
|
||||
logger.warning(f"Tool '{func_name}' is not defined in the tools list.")
|
||||
return {}
|
||||
|
||||
def convert_param_value(
|
||||
param_value: str, param_name: str, param_config: dict, func_name: str
|
||||
) -> Any:
|
||||
# Handle null value for any type
|
||||
if param_value.lower() == "null":
|
||||
return None
|
||||
|
||||
if param_name not in param_config:
|
||||
if param_config != {}:
|
||||
logger.warning(
|
||||
f"Parsed parameter '{param_name}' is not defined in the tool "
|
||||
f"parameters for tool '{func_name}', directly returning the string value."
|
||||
)
|
||||
return param_value
|
||||
|
||||
if (
|
||||
isinstance(param_config[param_name], dict)
|
||||
and "type" in param_config[param_name]
|
||||
):
|
||||
param_type = str(param_config[param_name]["type"]).strip().lower()
|
||||
else:
|
||||
param_type = "string"
|
||||
if param_type in ["string", "str", "text", "varchar", "char", "enum"]:
|
||||
return param_value
|
||||
elif (
|
||||
param_type.startswith("int")
|
||||
or param_type.startswith("uint")
|
||||
or param_type.startswith("long")
|
||||
or param_type.startswith("short")
|
||||
or param_type.startswith("unsigned")
|
||||
):
|
||||
try:
|
||||
param_value = int(param_value)
|
||||
except:
|
||||
logger.warning(
|
||||
f"Parsed value '{param_value}' of parameter '{param_name}' is not an integer in tool "
|
||||
f"'{func_name}', degenerating to string."
|
||||
)
|
||||
return param_value
|
||||
elif param_type.startswith("num") or param_type.startswith("float"):
|
||||
try:
|
||||
float_param_value = float(param_value)
|
||||
param_value = float_param_value if float_param_value - int(float_param_value) != 0 else int(float_param_value)
|
||||
except:
|
||||
logger.warning(
|
||||
f"Parsed value '{param_value}' of parameter '{param_name}' is not a float in tool "
|
||||
f"'{func_name}', degenerating to string."
|
||||
)
|
||||
return param_value
|
||||
elif param_type in ["boolean", "bool", "binary"]:
|
||||
param_value = param_value.lower()
|
||||
if param_value not in ["true", "false"]:
|
||||
logger.warning(
|
||||
f"Parsed value '{param_value}' of parameter '{param_name}' is not a boolean (`true` of `false`) in tool '{func_name}', degenerating to false."
|
||||
)
|
||||
return param_value == "true"
|
||||
else:
|
||||
if param_type == "object" or param_type.startswith("dict"):
|
||||
try:
|
||||
param_value = json.loads(param_value)
|
||||
return param_value
|
||||
except:
|
||||
logger.warning(
|
||||
f"Parsed value '{param_value}' of parameter '{param_name}' is not a valid JSON object in tool "
|
||||
f"'{func_name}', will try other methods to parse it."
|
||||
)
|
||||
try:
|
||||
param_value = eval(param_value)
|
||||
except:
|
||||
logger.warning(
|
||||
f"Parsed value '{param_value}' of parameter '{param_name}' cannot be converted via Python `eval()` in tool '{func_name}', degenerating to string."
|
||||
)
|
||||
return param_value
|
||||
|
||||
# Extract function name
|
||||
end_index = function_call_str.index(">")
|
||||
function_name = function_call_str[:end_index]
|
||||
param_config = get_arguments_config(function_name)
|
||||
parameters = function_call_str[end_index + 1 :]
|
||||
param_dict = {}
|
||||
for match in self.tool_call_parameter_regex.findall(parameters):
|
||||
match_text = match[0] if match[0] else match[1]
|
||||
idx = match_text.index(">")
|
||||
param_name = match_text[:idx]
|
||||
param_value = str(match_text[idx + 1 :])
|
||||
# Remove prefix and trailing \n
|
||||
if param_value.startswith("\n"):
|
||||
param_value = param_value[1:]
|
||||
if param_value.endswith("\n"):
|
||||
param_value = param_value[:-1]
|
||||
|
||||
param_dict[param_name] = convert_param_value(
|
||||
param_value, param_name, param_config, function_name
|
||||
)
|
||||
return ToolCall(
|
||||
type="function",
|
||||
function=FunctionCall(
|
||||
name=function_name, arguments=json.dumps(param_dict, ensure_ascii=False)
|
||||
),
|
||||
)
|
||||
|
||||
def _get_function_calls(self, model_output: str) -> List[str]:
|
||||
# Find all tool calls
|
||||
matched_ranges = self.tool_call_regex.findall(model_output)
|
||||
raw_tool_calls = [
|
||||
match[0] if match[0] else match[1] for match in matched_ranges
|
||||
]
|
||||
|
||||
# Back-off strategy if no tool_call tags found
|
||||
if len(raw_tool_calls) == 0:
|
||||
raw_tool_calls = [model_output]
|
||||
|
||||
raw_function_calls = []
|
||||
for tool_call in raw_tool_calls:
|
||||
raw_function_calls.extend(self.tool_call_function_regex.findall(tool_call))
|
||||
|
||||
function_calls = [
|
||||
match[0] if match[0] else match[1] for match in raw_function_calls
|
||||
]
|
||||
return function_calls
|
||||
|
||||
def extract_tool_calls(
|
||||
self,
|
||||
model_output: str,
|
||||
request: ChatCompletionRequest,
|
||||
) -> ExtractedToolCallInformation:
|
||||
# Quick check to avoid unnecessary processing
|
||||
if self.tool_call_prefix not in model_output:
|
||||
return ExtractedToolCallInformation(
|
||||
tools_called=False, tool_calls=[], content=model_output
|
||||
)
|
||||
|
||||
try:
|
||||
function_calls = self._get_function_calls(model_output)
|
||||
if len(function_calls) == 0:
|
||||
return ExtractedToolCallInformation(
|
||||
tools_called=False, tool_calls=[], content=model_output
|
||||
)
|
||||
|
||||
tool_calls = [
|
||||
self._parse_xml_function_call(function_call_str, request.tools)
|
||||
for function_call_str in function_calls
|
||||
]
|
||||
|
||||
# Populate prev_tool_call_arr for serving layer to set finish_reason
|
||||
self.prev_tool_call_arr.clear() # Clear previous calls
|
||||
for tool_call in tool_calls:
|
||||
if tool_call:
|
||||
self.prev_tool_call_arr.append(
|
||||
{
|
||||
"name": tool_call.function.name,
|
||||
"arguments": tool_call.function.arguments,
|
||||
}
|
||||
)
|
||||
|
||||
# Extract content before tool calls
|
||||
content_index = model_output.find(self.tool_call_start_token)
|
||||
content_index = (
|
||||
content_index
|
||||
if content_index >= 0
|
||||
else model_output.find(self.tool_call_prefix)
|
||||
)
|
||||
content = model_output[:content_index] # .rstrip()
|
||||
|
||||
return ExtractedToolCallInformation(
|
||||
tools_called=(len(tool_calls) > 0),
|
||||
tool_calls=tool_calls,
|
||||
content=content if content else None,
|
||||
)
|
||||
|
||||
except Exception:
|
||||
logger.exception("Error in extracting tool call from response.")
|
||||
return ExtractedToolCallInformation(
|
||||
tools_called=False, tool_calls=[], content=model_output
|
||||
)
|
||||
|
||||
def extract_tool_calls_streaming(
|
||||
self,
|
||||
previous_text: str,
|
||||
current_text: str,
|
||||
delta_text: str,
|
||||
previous_token_ids: Sequence[int],
|
||||
current_token_ids: Sequence[int],
|
||||
delta_token_ids: Sequence[int],
|
||||
request: ChatCompletionRequest,
|
||||
) -> Union[DeltaMessage, None]:
|
||||
# If no delta text, return None unless it's an EOS token after tool calls
|
||||
if not delta_text:
|
||||
# Check if this is an EOS token after all tool calls are complete
|
||||
# We check for tool calls in the text even if is_tool_call_started is False
|
||||
# because it might have been reset after processing all tools
|
||||
if delta_token_ids and self.tool_call_end_token_id not in delta_token_ids:
|
||||
# Count complete tool calls
|
||||
complete_calls = len(
|
||||
self.tool_call_complete_regex.findall(current_text)
|
||||
)
|
||||
|
||||
# If we have completed tool calls and populated prev_tool_call_arr
|
||||
if complete_calls > 0 and len(self.prev_tool_call_arr) > 0:
|
||||
# Check if all tool calls are closed
|
||||
open_calls = current_text.count(
|
||||
self.tool_call_start_token
|
||||
) - current_text.count(self.tool_call_end_token)
|
||||
if open_calls == 0:
|
||||
# Return empty delta message to allow finish_reason processing
|
||||
return DeltaMessage(content="")
|
||||
elif not self.is_tool_call_started and current_text:
|
||||
# This is a regular content response that's now complete
|
||||
return DeltaMessage(content="")
|
||||
return None
|
||||
|
||||
# Check if this is the first call (reset state if needed)
|
||||
if not previous_text:
|
||||
self._reset_streaming_state()
|
||||
|
||||
# Update accumulated text
|
||||
self.accumulated_text = current_text
|
||||
|
||||
# Check if we need to advance to next tool
|
||||
if self.json_closed and not self.in_function:
|
||||
# Check if this tool call has ended
|
||||
tool_ends = current_text.count(self.tool_call_end_token)
|
||||
if tool_ends > self.current_tool_index:
|
||||
# This tool has ended, advance to next
|
||||
self.current_tool_index += 1
|
||||
self.header_sent = False
|
||||
self.param_count = 0
|
||||
self.json_started = False
|
||||
self.json_closed = False
|
||||
|
||||
# Check if there are more tool calls
|
||||
tool_starts = current_text.count(self.tool_call_start_token)
|
||||
if self.current_tool_index >= tool_starts:
|
||||
# No more tool calls
|
||||
self.is_tool_call_started = False
|
||||
# Continue processing next tool
|
||||
return None
|
||||
|
||||
# Handle normal content before tool calls
|
||||
if not self.is_tool_call_started:
|
||||
# Check if tool call is starting
|
||||
if (
|
||||
self.tool_call_start_token_id in delta_token_ids
|
||||
or self.tool_call_start_token in delta_text
|
||||
):
|
||||
self.is_tool_call_started = True
|
||||
# Return any content before the tool call
|
||||
if self.tool_call_start_token in delta_text:
|
||||
content_before = delta_text[
|
||||
: delta_text.index(self.tool_call_start_token)
|
||||
]
|
||||
if content_before:
|
||||
return DeltaMessage(content=content_before)
|
||||
return None
|
||||
else:
|
||||
# Check if we're between tool calls - skip whitespace
|
||||
if current_text.rstrip().endswith(self.tool_call_end_token):
|
||||
# We just ended a tool call, skip whitespace
|
||||
if delta_text.strip() == "":
|
||||
return None
|
||||
# Normal content, no tool call
|
||||
return DeltaMessage(content=delta_text)
|
||||
|
||||
# Check if we're between tool calls (waiting for next one)
|
||||
# Count tool calls we've seen vs processed
|
||||
tool_starts_count = current_text.count(self.tool_call_start_token)
|
||||
if self.current_tool_index >= tool_starts_count:
|
||||
# We're past all tool calls, shouldn't be here
|
||||
return None
|
||||
|
||||
# We're in a tool call, find the current tool call portion
|
||||
# Need to find the correct tool call based on current_tool_index
|
||||
tool_starts = []
|
||||
idx = 0
|
||||
while True:
|
||||
idx = current_text.find(self.tool_call_start_token, idx)
|
||||
if idx == -1:
|
||||
break
|
||||
tool_starts.append(idx)
|
||||
idx += len(self.tool_call_start_token)
|
||||
|
||||
if self.current_tool_index >= len(tool_starts):
|
||||
# No more tool calls to process yet
|
||||
return None
|
||||
|
||||
tool_start_idx = tool_starts[self.current_tool_index]
|
||||
# Find where this tool call ends (or current position if not ended yet)
|
||||
tool_end_idx = current_text.find(self.tool_call_end_token, tool_start_idx)
|
||||
if tool_end_idx == -1:
|
||||
tool_text = current_text[tool_start_idx:]
|
||||
else:
|
||||
tool_text = current_text[
|
||||
tool_start_idx : tool_end_idx + len(self.tool_call_end_token)
|
||||
]
|
||||
|
||||
# Looking for function header
|
||||
if not self.header_sent:
|
||||
if self.tool_call_prefix in tool_text:
|
||||
func_start = tool_text.find(self.tool_call_prefix) + len(
|
||||
self.tool_call_prefix
|
||||
)
|
||||
func_end = tool_text.find(">", func_start)
|
||||
|
||||
if func_end != -1:
|
||||
# Found complete function name
|
||||
self.current_function_name = tool_text[func_start:func_end]
|
||||
self.current_tool_id = self._generate_tool_call_id()
|
||||
self.header_sent = True
|
||||
self.in_function = True
|
||||
|
||||
# IMPORTANT: Add to prev_tool_call_arr immediately when we detect a tool call
|
||||
# This ensures finish_reason="tool_calls" even if parsing isn't complete
|
||||
already_added = any(
|
||||
tool.get("name") == self.current_function_name
|
||||
for tool in self.prev_tool_call_arr
|
||||
)
|
||||
if not already_added:
|
||||
self.prev_tool_call_arr.append(
|
||||
{
|
||||
"name": self.current_function_name,
|
||||
"arguments": "{}", # Placeholder, will be updated later
|
||||
}
|
||||
)
|
||||
|
||||
# Send header with function info
|
||||
return DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
id=self.current_tool_id,
|
||||
function=DeltaFunctionCall(
|
||||
name=self.current_function_name, arguments=""
|
||||
),
|
||||
type="function",
|
||||
)
|
||||
]
|
||||
)
|
||||
return None
|
||||
|
||||
# We've sent header, now handle function body
|
||||
if self.in_function:
|
||||
# Send opening brace if not sent yet
|
||||
if not self.json_started and not self.parameter_prefix in delta_text:
|
||||
self.json_started = True
|
||||
return DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
function=DeltaFunctionCall(arguments="{"),
|
||||
)
|
||||
]
|
||||
)
|
||||
|
||||
# Make sure json_started is set if we're processing parameters
|
||||
if not self.json_started:
|
||||
self.json_started = True
|
||||
|
||||
# Check for function end in accumulated text
|
||||
if not self.json_closed and self.function_end_token in tool_text:
|
||||
# Close JSON
|
||||
self.json_closed = True
|
||||
|
||||
# Extract the complete tool call to update prev_tool_call_arr with final arguments
|
||||
# Find the function content
|
||||
func_start = tool_text.find(self.tool_call_prefix) + len(
|
||||
self.tool_call_prefix
|
||||
)
|
||||
func_content_end = tool_text.find(self.function_end_token, func_start)
|
||||
if func_content_end != -1:
|
||||
func_content = tool_text[func_start:func_content_end]
|
||||
# Parse to get the complete arguments
|
||||
try:
|
||||
parsed_tool = self._parse_xml_function_call(
|
||||
func_content, request.tools if request else None
|
||||
)
|
||||
if parsed_tool:
|
||||
# Update existing entry in prev_tool_call_arr with complete arguments
|
||||
for i, tool in enumerate(self.prev_tool_call_arr):
|
||||
if tool.get("name") == parsed_tool.function.name:
|
||||
self.prev_tool_call_arr[i]["arguments"] = (
|
||||
parsed_tool.function.arguments
|
||||
)
|
||||
break
|
||||
except Exception:
|
||||
pass # Ignore parsing errors during streaming
|
||||
|
||||
result = DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
function=DeltaFunctionCall(arguments="}"),
|
||||
)
|
||||
]
|
||||
)
|
||||
|
||||
# Reset state for next tool
|
||||
self.in_function = False
|
||||
self.json_closed = True
|
||||
|
||||
return result
|
||||
|
||||
# Look for parameters
|
||||
# Count how many complete parameters we have processed
|
||||
complete_params = tool_text.count(self.parameter_end_token)
|
||||
|
||||
# Check if we should start a new parameter
|
||||
if not self.in_param and self.param_count < complete_params:
|
||||
# Find the unprocessed parameter
|
||||
# Count parameter starts
|
||||
param_starts = []
|
||||
idx = 0
|
||||
while True:
|
||||
idx = tool_text.find(self.parameter_prefix, idx)
|
||||
if idx == -1:
|
||||
break
|
||||
param_starts.append(idx)
|
||||
idx += len(self.parameter_prefix)
|
||||
|
||||
if len(param_starts) > self.param_count:
|
||||
# Process the next parameter
|
||||
param_idx = param_starts[self.param_count]
|
||||
param_start = param_idx + len(self.parameter_prefix)
|
||||
remaining = tool_text[param_start:]
|
||||
|
||||
if ">" in remaining:
|
||||
# We have the complete parameter name
|
||||
name_end = remaining.find(">")
|
||||
self.current_param_name = remaining[:name_end]
|
||||
|
||||
# Find the parameter value
|
||||
value_start = param_start + name_end + 1
|
||||
value_text = tool_text[value_start:]
|
||||
if value_text.startswith("\n"):
|
||||
value_text = value_text[1:]
|
||||
|
||||
# Find where this parameter ends
|
||||
param_end_idx = value_text.find(self.parameter_end_token)
|
||||
if param_end_idx != -1:
|
||||
# Complete parameter found
|
||||
param_value = value_text[:param_end_idx]
|
||||
if param_value.endswith("\n"):
|
||||
param_value = param_value[:-1]
|
||||
|
||||
# Build complete JSON fragment for this parameter
|
||||
if self.param_count == 0:
|
||||
json_fragment = (
|
||||
'"'
|
||||
+ self.current_param_name
|
||||
+ '": "'
|
||||
+ json.dumps(param_value)[1:-1]
|
||||
+ '"'
|
||||
)
|
||||
else:
|
||||
json_fragment = (
|
||||
', "'
|
||||
+ self.current_param_name
|
||||
+ '": "'
|
||||
+ json.dumps(param_value)[1:-1]
|
||||
+ '"'
|
||||
)
|
||||
|
||||
self.param_count += 1
|
||||
|
||||
return DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
function=DeltaFunctionCall(
|
||||
arguments=json_fragment
|
||||
),
|
||||
)
|
||||
]
|
||||
)
|
||||
|
||||
# Continue parameter value
|
||||
if self.in_param:
|
||||
if self.parameter_end_token in delta_text:
|
||||
# End of parameter
|
||||
end_idx = delta_text.find(self.parameter_end_token)
|
||||
value_chunk = delta_text[:end_idx]
|
||||
|
||||
# Skip past > if at start
|
||||
if not self.current_param_value and ">" in value_chunk:
|
||||
gt_idx = value_chunk.find(">")
|
||||
value_chunk = value_chunk[gt_idx + 1 :]
|
||||
|
||||
if not self.current_param_value and value_chunk.startswith("\n"):
|
||||
value_chunk = value_chunk[1:]
|
||||
|
||||
# Calculate incremental JSON
|
||||
full_value = self.current_param_value + value_chunk
|
||||
prev_escaped = (
|
||||
json.dumps(self.current_param_value)[1:-1]
|
||||
if self.current_param_value
|
||||
else ""
|
||||
)
|
||||
full_escaped = json.dumps(full_value)[1:-1]
|
||||
delta_escaped = full_escaped[len(prev_escaped) :]
|
||||
|
||||
self.in_param = False
|
||||
self.current_param_value = ""
|
||||
|
||||
return DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
function=DeltaFunctionCall(
|
||||
arguments=delta_escaped + '"'
|
||||
),
|
||||
)
|
||||
]
|
||||
)
|
||||
else:
|
||||
# Continue accumulating value
|
||||
value_chunk = delta_text
|
||||
|
||||
# Handle first chunk after param name
|
||||
if not self.current_param_value and ">" in value_chunk:
|
||||
gt_idx = value_chunk.find(">")
|
||||
value_chunk = value_chunk[gt_idx + 1 :]
|
||||
|
||||
if not self.current_param_value and value_chunk.startswith("\n"):
|
||||
value_chunk = value_chunk[1:]
|
||||
|
||||
if value_chunk:
|
||||
# Stream the escaped delta
|
||||
prev_escaped = (
|
||||
json.dumps(self.current_param_value)[1:-1]
|
||||
if self.current_param_value
|
||||
else ""
|
||||
)
|
||||
self.current_param_value += value_chunk
|
||||
full_escaped = json.dumps(self.current_param_value)[1:-1]
|
||||
delta_escaped = full_escaped[len(prev_escaped) :]
|
||||
|
||||
if delta_escaped:
|
||||
return DeltaMessage(
|
||||
tool_calls=[
|
||||
DeltaToolCall(
|
||||
index=self.current_tool_index,
|
||||
function=DeltaFunctionCall(
|
||||
arguments=delta_escaped
|
||||
),
|
||||
)
|
||||
]
|
||||
)
|
||||
|
||||
return None
|
||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:19564a48c4f71a2a1b937cce34c737a1e662b171c5f5d7edf641a15cd896f07d
|
||||
size 7032399
|
||||
239
tokenizer_config.json
Normal file
239
tokenizer_config.json
Normal file
File diff suppressed because one or more lines are too long
BIN
vocab.json
(Stored with Git LFS)
Normal file
BIN
vocab.json
(Stored with Git LFS)
Normal file
Binary file not shown.
Reference in New Issue
Block a user