229 lines
6.7 KiB
Markdown
229 lines
6.7 KiB
Markdown

|
---
|
|||
|
|
library_name: transformers
|
|||
|
|
license: apache-2.0
|
|||
|
|
license_link: https://huggingface.co/Qwen/Qwen3-Coder-30B-A3B-Instruct/blob/main/LICENSE
|
|||
|
|
pipeline_tag: text-generation
|
|||
|
|
tags:
|
|||
|
|
- AWQ
|
|||
|
|
- 量化修复
|
|||
|
|
- vLLM
|
|||
|
|
base_model:
|
|||
|
|
- Qwen/Qwen3-Coder-30B-A3B-Instruct
|
|||
|
|
base_model_relation: quantized
|
|||
|
|
---
|
|||
|
|
# Qwen3-Coder-30B-A3B-Instruct-AWQ
|
|||
|
|
基础型 [Qwen3-Coder-30B-A3B-Instruct](https://www.modelscope.cn/models/Qwen3-Coder-30B-A3B-Instruct)
|
|||
|
|
|
|||
|
|
|
|||
|
|
### 【❗❗提醒❗❗】
|
|||
|
|
该模型4比特量化损失较大,需谨慎使用
|
|||
|
|
|
|||
|
|
|
|||
|
|
### 【Vllm 启动命令】
|
|||
|
|
<i>注: 4卡启动该模型一定要跟`--enable-expert-parallel` ,否则其专家张量TP整除除不尽;2卡则不需要。 </i>
|
|||
|
|
```
|
|||
|
|
CONTEXT_LENGTH=32768
|
|||
|
|
|
|||
|
|
vllm serve \
|
|||
|
|
tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ \
|
|||
|
|
--served-model-name Qwen3-Coder-30B-A3B-Instruct-AWQ \
|
|||
|
|
--enable-expert-parallel \
|
|||
|
|
--swap-space 16 \
|
|||
|
|
--max-num-seqs 512 \
|
|||
|
|
--max-model-len $CONTEXT_LENGTH \
|
|||
|
|
--max-seq-len-to-capture $CONTEXT_LENGTH \
|
|||
|
|
--gpu-memory-utilization 0.9 \
|
|||
|
|
--tensor-parallel-size 4 \
|
|||
|
|
--trust-remote-code \
|
|||
|
|
--disable-log-requests \
|
|||
|
|
--host 0.0.0.0 \
|
|||
|
|
--port 8000
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
### 【依赖】
|
|||
|
|
|
|||
|
|
```
|
|||
|
|
vllm==0.10.0
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
### 【模型更新日期】
|
|||
|
|
```
|
|||
|
|
2025-08-01
|
|||
|
|
1. 首次commit
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
### 【模型列表】
|
|||
|
|
|
|||
|
|
| 文件大小 | 最近更新时间 |
|
|||
|
|
|--------|--------------|
|
|||
|
|
| `16GB` | `2025-08-01` |
|
|||
|
|
|
|||
|
|
|
|||
|
|
### 【模型下载】
|
|||
|
|
|
|||
|
|
```python
|
|||
|
|
from modelscope import snapshot_download
|
|||
|
|
snapshot_download('tclf90/Qwen3-Coder-30B-A3B-Instruct-AWQ', cache_dir="本地路径")
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
### 【介绍】
|
|||
|
|
# Qwen3-Coder-30B-A3B-Instruct
|
|||
|
|
<a href="https://chat.qwen.ai/" target="_blank" style="margin: 2px;">
|
|||
|
|
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
|||
|
|
</a>
|
|||
|
|
|
|||
|
|
## Highlights
|
|||
|
|
|
|||
|
|
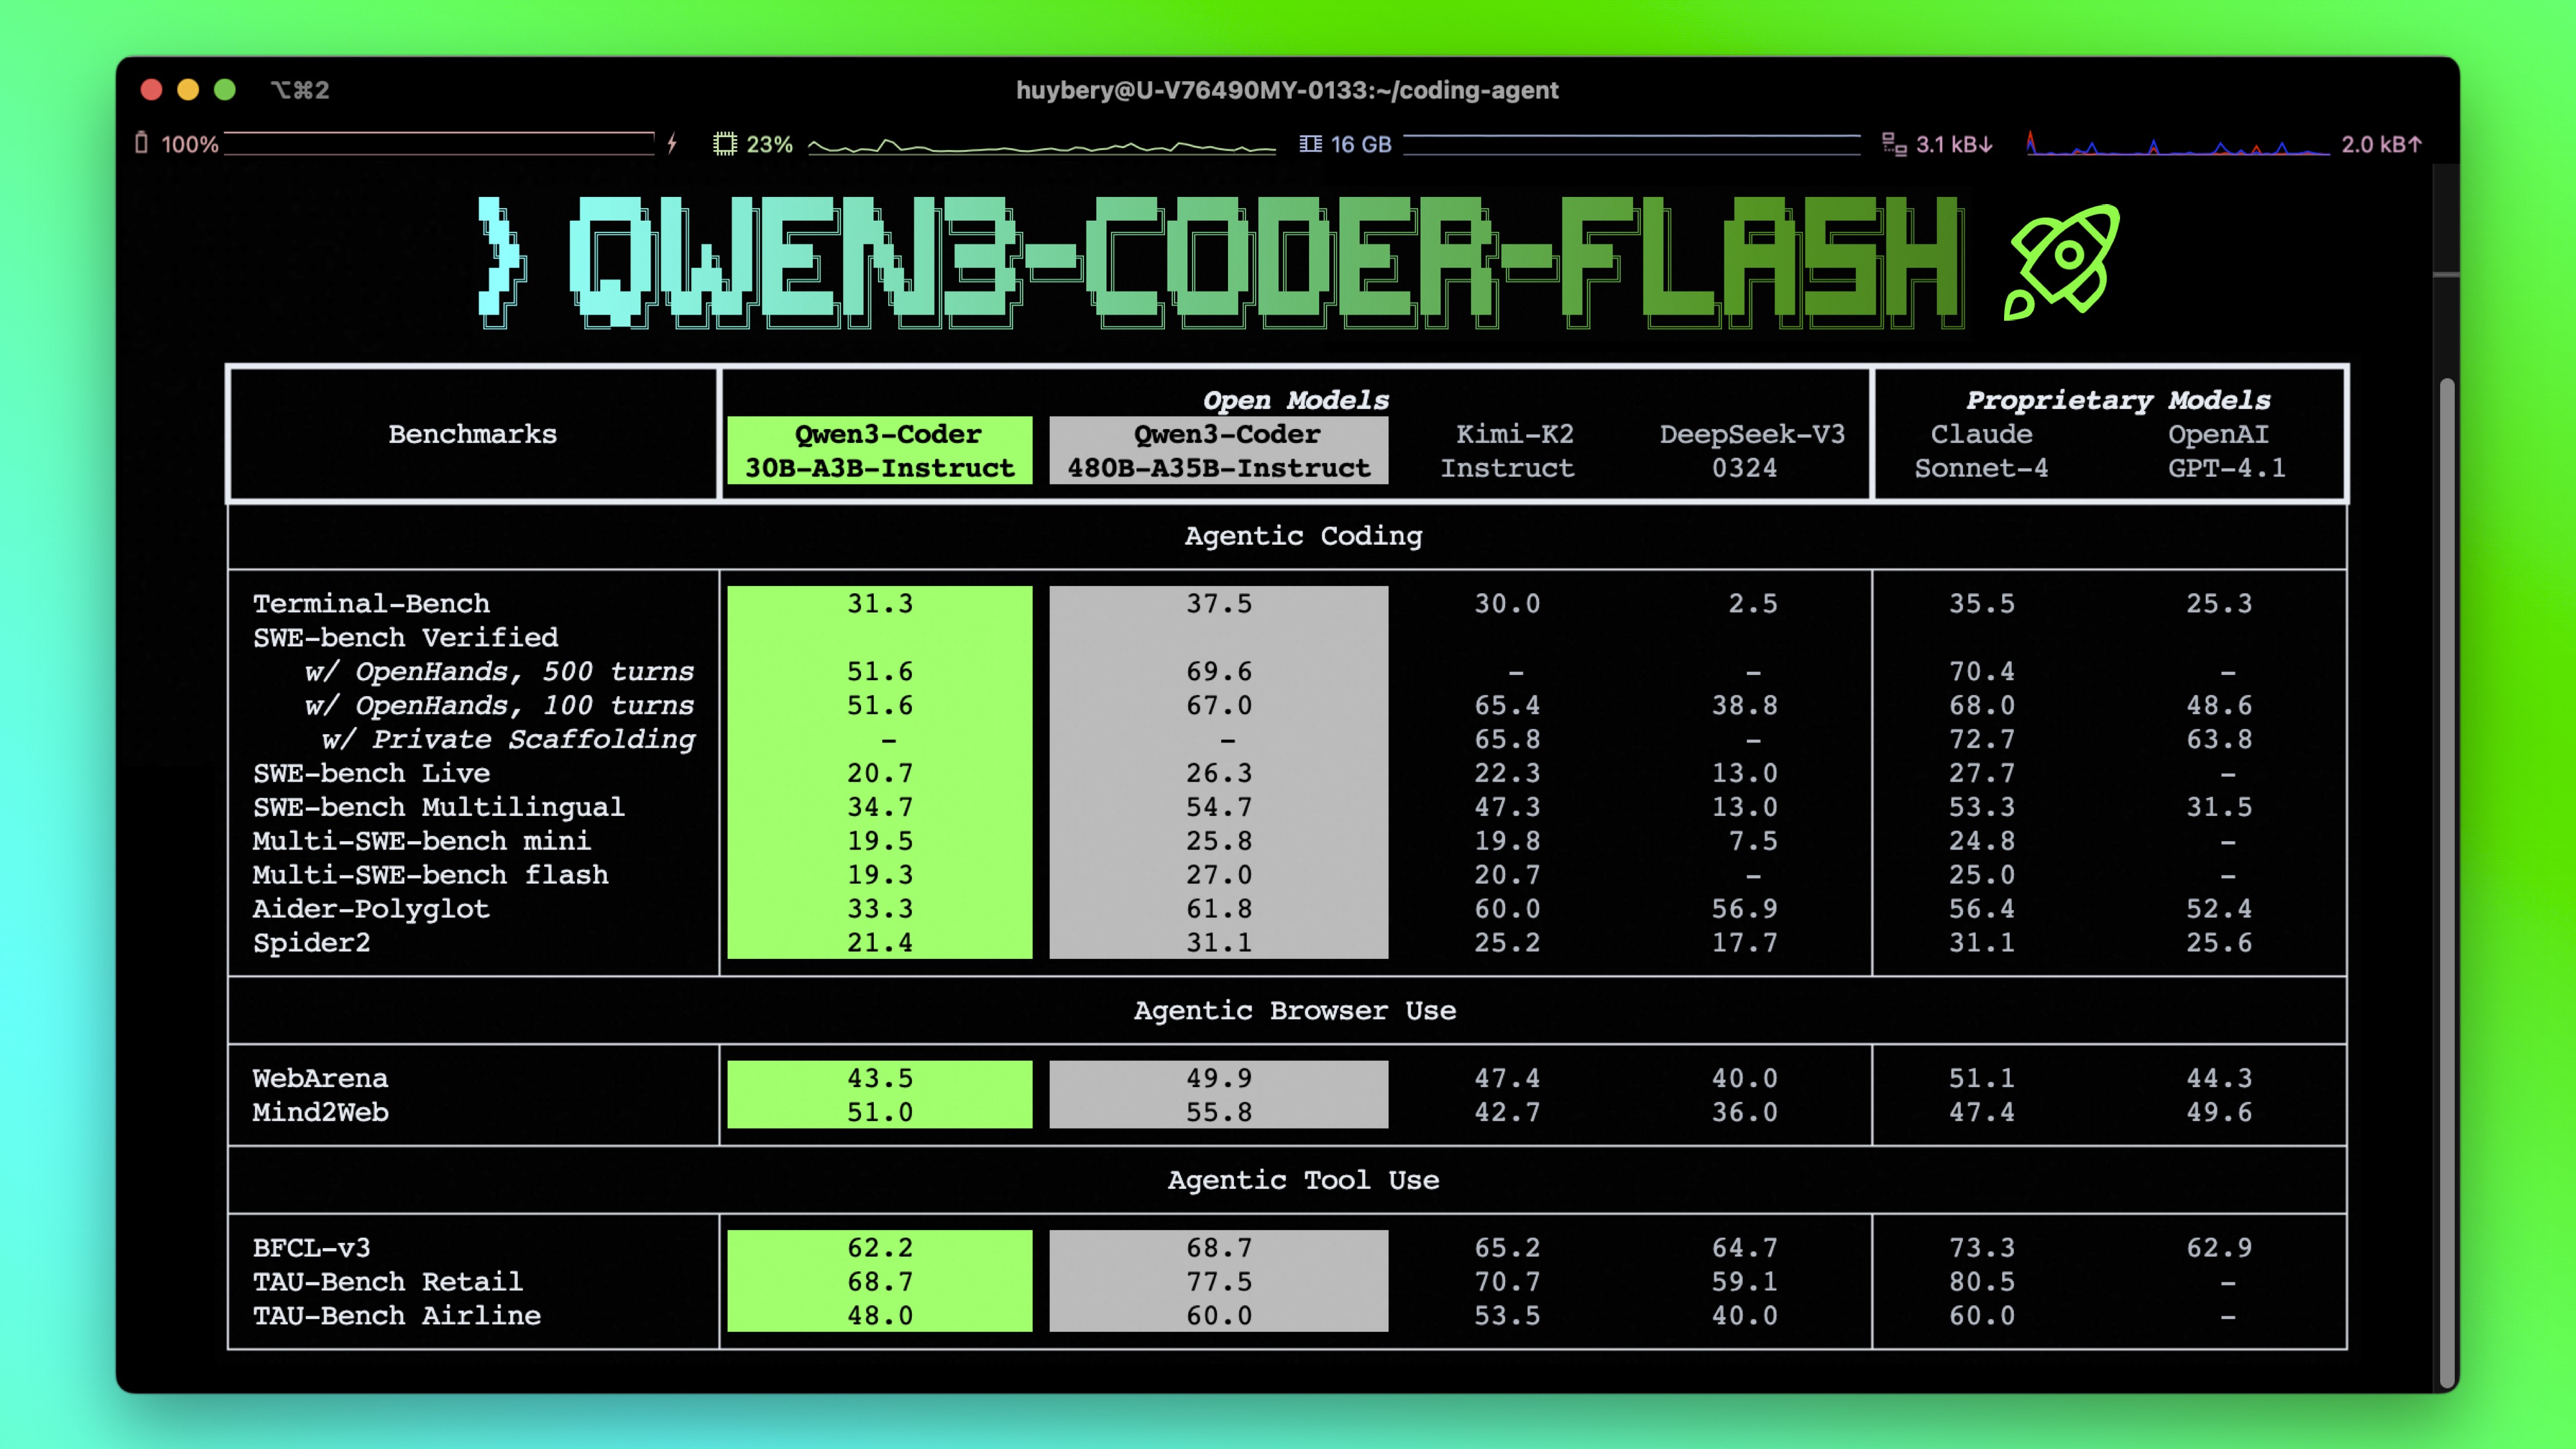
**Qwen3-Coder** is available in multiple sizes. Today, we're excited to introduce **Qwen3-Coder-30B-A3B-Instruct**. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
|
|||
|
|
|
|||
|
|
- **Significant Performance** among open models on **Agentic Coding**, **Agentic Browser-Use**, and other foundational coding tasks.
|
|||
|
|
- **Long-context Capabilities** with native support for **256K** tokens, extendable up to **1M** tokens using Yarn, optimized for repository-scale understanding.
|
|||
|
|
- **Agentic Coding** supporting for most platform such as **Qwen Code**, **CLINE**, featuring a specially designed function call format.
|
|||
|
|
|
|||
|
|
|
|||
|
|
|
|||
|
|
## Model Overview
|
|||
|
|
|
|||
|
|
**Qwen3-Coder-30B-A3B-Instruct** has the following features:
|
|||
|
|
- Type: Causal Language Models
|
|||
|
|
- Training Stage: Pretraining & Post-training
|
|||
|
|
- Number of Parameters: 30.5B in total and 3.3B activated
|
|||
|
|
- Number of Layers: 48
|
|||
|
|
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
|
|||
|
|
- Number of Experts: 128
|
|||
|
|
- Number of Activated Experts: 8
|
|||
|
|
- Context Length: **262,144 natively**.
|
|||
|
|
|
|||
|
|
**NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
|
|||
|
|
|
|||
|
|
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-coder/), [GitHub](https://github.com/QwenLM/Qwen3-Coder), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
|||
|
|
|
|||
|
|
|
|||
|
|
## Quickstart
|
|||
|
|
|
|||
|
|
We advise you to use the latest version of `transformers`.
|
|||
|
|
|
|||
|
|
With `transformers<4.51.0`, you will encounter the following error:
|
|||
|
|
```
|
|||
|
|
KeyError: 'qwen3_moe'
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
|||
|
|
```python
|
|||
|
|
from transformers import AutoModelForCausalLM, AutoTokenizer
|
|||
|
|
|
|||
|
|
model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct"
|
|||
|
|
|
|||
|
|
# load the tokenizer and the model
|
|||
|
|
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
|||
|
|
model = AutoModelForCausalLM.from_pretrained(
|
|||
|
|
model_name,
|
|||
|
|
torch_dtype="auto",
|
|||
|
|
device_map="auto"
|
|||
|
|
)
|
|||
|
|
|
|||
|
|
# prepare the model input
|
|||
|
|
prompt = "Write a quick sort algorithm."
|
|||
|
|
messages = [
|
|||
|
|
{"role": "user", "content": prompt}
|
|||
|
|
]
|
|||
|
|
text = tokenizer.apply_chat_template(
|
|||
|
|
messages,
|
|||
|
|
tokenize=False,
|
|||
|
|
add_generation_prompt=True,
|
|||
|
|
)
|
|||
|
|
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
|||
|
|
|
|||
|
|
# conduct text completion
|
|||
|
|
generated_ids = model.generate(
|
|||
|
|
**model_inputs,
|
|||
|
|
max_new_tokens=65536
|
|||
|
|
)
|
|||
|
|
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
|||
|
|
|
|||
|
|
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
|||
|
|
|
|||
|
|
print("content:", content)
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
|
|||
|
|
|
|||
|
|
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
|||
|
|
|
|||
|
|
## Agentic Coding
|
|||
|
|
|
|||
|
|
Qwen3-Coder excels in tool calling capabilities.
|
|||
|
|
|
|||
|
|
You can simply define or use any tools as following example.
|
|||
|
|
```python
|
|||
|
|
# Your tool implementation
|
|||
|
|
def square_the_number(num: float) -> dict:
|
|||
|
|
return num ** 2
|
|||
|
|
|
|||
|
|
# Define Tools
|
|||
|
|
tools=[
|
|||
|
|
{
|
|||
|
|
"type":"function",
|
|||
|
|
"function":{
|
|||
|
|
"name": "square_the_number",
|
|||
|
|
"description": "output the square of the number.",
|
|||
|
|
"parameters": {
|
|||
|
|
"type": "object",
|
|||
|
|
"required": ["input_num"],
|
|||
|
|
"properties": {
|
|||
|
|
'input_num': {
|
|||
|
|
'type': 'number',
|
|||
|
|
'description': 'input_num is a number that will be squared'
|
|||
|
|
}
|
|||
|
|
},
|
|||
|
|
}
|
|||
|
|
}
|
|||
|
|
}
|
|||
|
|
]
|
|||
|
|
|
|||
|
|
import OpenAI
|
|||
|
|
# Define LLM
|
|||
|
|
client = OpenAI(
|
|||
|
|
# Use a custom endpoint compatible with OpenAI API
|
|||
|
|
base_url='http://localhost:8000/v1', # api_base
|
|||
|
|
api_key="EMPTY"
|
|||
|
|
)
|
|||
|
|
|
|||
|
|
messages = [{'role': 'user', 'content': 'square the number 1024'}]
|
|||
|
|
|
|||
|
|
completion = client.chat.completions.create(
|
|||
|
|
messages=messages,
|
|||
|
|
model="Qwen3-Coder-30B-A3B-Instruct",
|
|||
|
|
max_tokens=65536,
|
|||
|
|
tools=tools,
|
|||
|
|
)
|
|||
|
|
|
|||
|
|
print(completion.choice[0])
|
|||
|
|
```
|
|||
|
|
|
|||
|
|
## Best Practices
|
|||
|
|
|
|||
|
|
To achieve optimal performance, we recommend the following settings:
|
|||
|
|
|
|||
|
|
1. **Sampling Parameters**:
|
|||
|
|
- We suggest using `temperature=0.7`, `top_p=0.8`, `top_k=20`, `repetition_penalty=1.05`.
|
|||
|
|
|
|||
|
|
2. **Adequate Output Length**: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
|
|||
|
|
|
|||
|
|
|
|||
|
|
### Citation
|
|||
|
|
|
|||
|
|
If you find our work helpful, feel free to give us a cite.
|
|||
|
|
|
|||
|
|
```
|
|||
|
|
@misc{qwen3technicalreport,
|
|||
|
|
title={Qwen3 Technical Report},
|
|||
|
|
author={Qwen Team},
|
|||
|
|
year={2025},
|
|||
|
|
eprint={2505.09388},
|
|||
|
|
archivePrefix={arXiv},
|
|||
|
|
primaryClass={cs.CL},
|
|||
|
|
url={https://arxiv.org/abs/2505.09388},
|
|||
|
|
}
|
|||
|
|
```
|