初始化项目,由ModelHub XC社区提供模型
Model: modelscope/zephyr-7b-beta
Source: Original Platform
This commit is contained in:
 ModelHub XC
34
.gitattributes
vendored
Normal file
34
.gitattributes
vendored
Normal file
@@ -0,0 +1,34 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
235
README.md
Normal file
235
README.md
Normal file
@@ -0,0 +1,235 @@
|
||||
---
|
||||
tags:
|
||||
- generated_from_trainer
|
||||
model-index:
|
||||
- name: zephyr-7b-beta
|
||||
results: []
|
||||
license: mit
|
||||
datasets:
|
||||
- HuggingFaceH4/ultrachat_200k
|
||||
- HuggingFaceH4/ultrafeedback_binarized
|
||||
language:
|
||||
- en
|
||||
base_model: mistralai/Mistral-7B-v0.1
|
||||
---
|
||||
|
||||
<!-- This model card has been generated automatically according to the information the Trainer had access to. You
|
||||
should probably proofread and complete it, then remove this comment. -->
|
||||
|
||||
<img src="https://huggingface.co/HuggingFaceH4/zephyr-7b-alpha/resolve/main/thumbnail.png" alt="Zephyr Logo" width="800" style="margin-left:'auto' margin-right:'auto' display:'block'"/>
|
||||
|
||||
|
||||
# Model Card for Zephyr 7B β
|
||||
|
||||
Zephyr is a series of language models that are trained to act as helpful assistants. Zephyr-7B-β is the second model in the series, and is a fine-tuned version of [mistralai/Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1) that was trained on on a mix of publicly available, synthetic datasets using [Direct Preference Optimization (DPO)](https://arxiv.org/abs/2305.18290). We found that removing the in-built alignment of these datasets boosted performance on [MT Bench](https://huggingface.co/spaces/lmsys/mt-bench) and made the model more helpful. However, this means that model is likely to generate problematic text when prompted to do so and should only be used for educational and research purposes. You can find more details in the [technical report](https://arxiv.org/abs/2310.16944).
|
||||
|
||||
|
||||
## Model description
|
||||
|
||||
- **Model type:** A 7B parameter GPT-like model fine-tuned on a mix of publicly available, synthetic datasets.
|
||||
- **Language(s) (NLP):** Primarily English
|
||||
- **License:** MIT
|
||||
- **Finetuned from model:** [mistralai/Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1)
|
||||
|
||||
### Model Sources
|
||||
|
||||
<!-- Provide the basic links for the model. -->
|
||||
|
||||
- **Repository:** https://github.com/huggingface/alignment-handbook
|
||||
- **Demo:** https://huggingface.co/spaces/HuggingFaceH4/zephyr-chat
|
||||
- **Chatbot Arena:** Evaluate Zephyr 7B against 10+ LLMs in the LMSYS arena: http://arena.lmsys.org
|
||||
|
||||
## Performance
|
||||
|
||||
At the time of release, Zephyr-7B-β is the highest ranked 7B chat model on the [MT-Bench](https://huggingface.co/spaces/lmsys/mt-bench) and [AlpacaEval](https://tatsu-lab.github.io/alpaca_eval/) benchmarks:
|
||||
|
||||
| Model | Size | Alignment | MT-Bench (score) | AlpacaEval (win rate %) |
|
||||
|-------------|-----|----|---------------|--------------|
|
||||
| StableLM-Tuned-α | 7B| dSFT |2.75| -|
|
||||
| MPT-Chat | 7B |dSFT |5.42| -|
|
||||
| Xwin-LMv0.1 | 7B| dPPO| 6.19| 87.83|
|
||||
| Mistral-Instructv0.1 | 7B| - | 6.84 |-|
|
||||
| Zephyr-7b-α |7B| dDPO| 6.88| -|
|
||||
| **Zephyr-7b-β** 🪁 | **7B** | **dDPO** | **7.34** | **90.60** |
|
||||
| Falcon-Instruct | 40B |dSFT |5.17 |45.71|
|
||||
| Guanaco | 65B | SFT |6.41| 71.80|
|
||||
| Llama2-Chat | 70B |RLHF |6.86| 92.66|
|
||||
| Vicuna v1.3 | 33B |dSFT |7.12 |88.99|
|
||||
| WizardLM v1.0 | 70B |dSFT |7.71 |-|
|
||||
| Xwin-LM v0.1 | 70B |dPPO |- |95.57|
|
||||
| GPT-3.5-turbo | - |RLHF |7.94 |89.37|
|
||||
| Claude 2 | - |RLHF |8.06| 91.36|
|
||||
| GPT-4 | -| RLHF |8.99| 95.28|
|
||||
|
||||
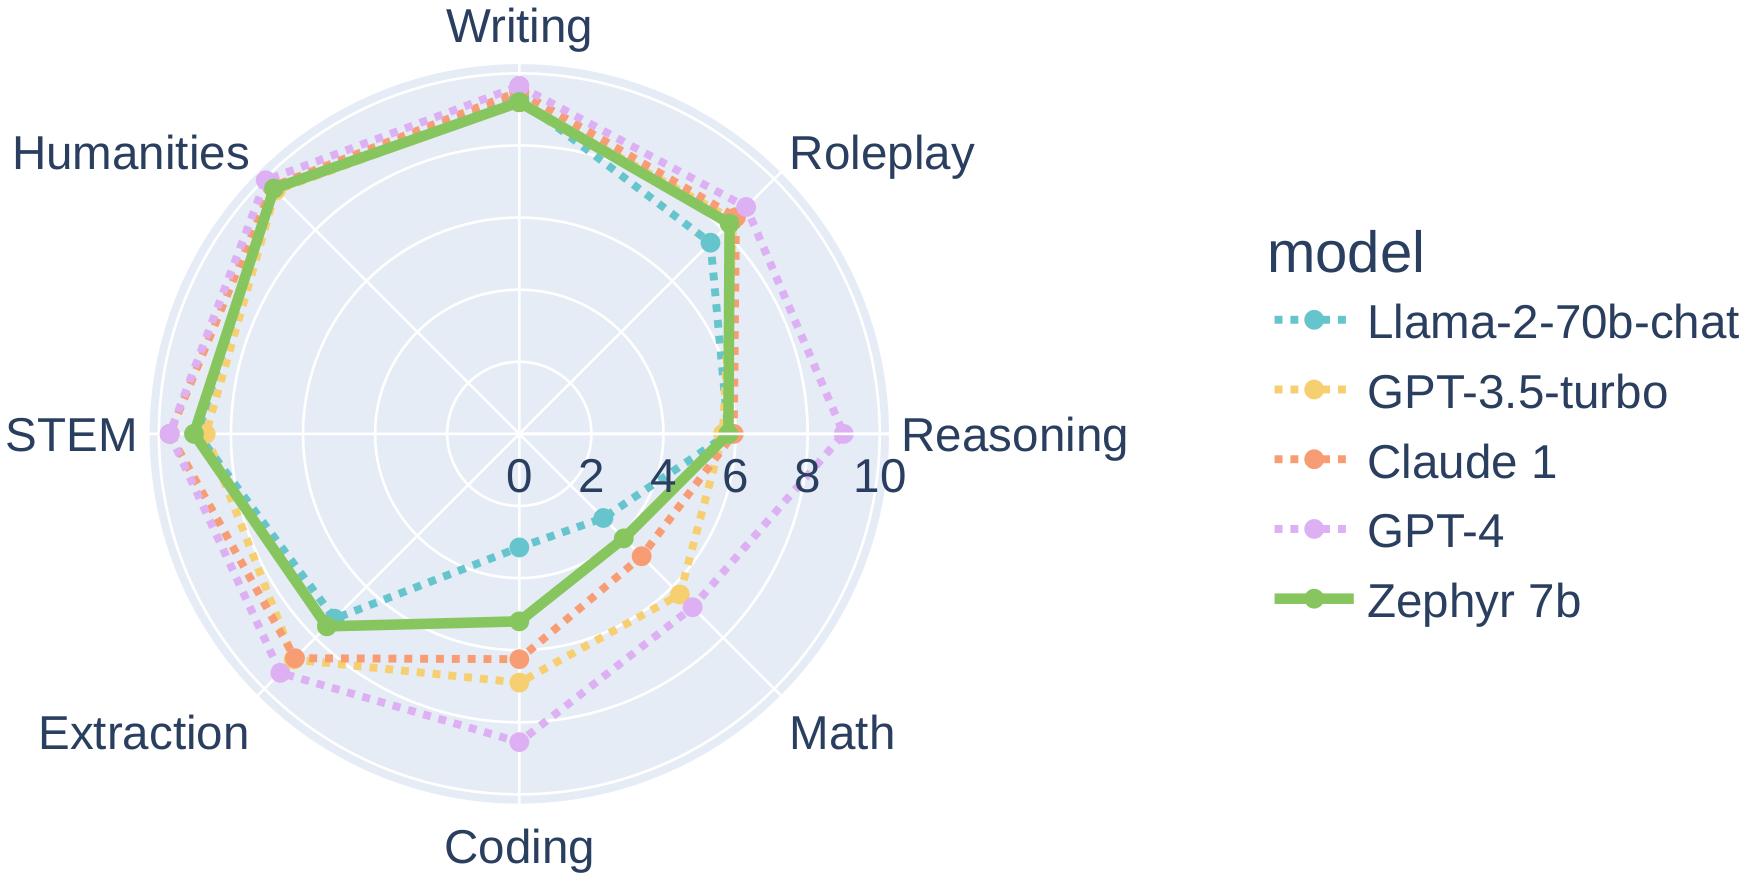
In particular, on several categories of MT-Bench, Zephyr-7B-β has strong performance compared to larger open models like Llama2-Chat-70B:
|
||||
|
||||
|
||||
|
||||
However, on more complex tasks like coding and mathematics, Zephyr-7B-β lags behind proprietary models and more research is needed to close the gap.
|
||||
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
The model was initially fine-tuned on a filtered and preprocessed of the [`UltraChat`](https://huggingface.co/datasets/stingning/ultrachat) dataset, which contains a diverse range of synthetic dialogues generated by ChatGPT.
|
||||
We then further aligned the model with [🤗 TRL's](https://github.com/huggingface/trl) `DPOTrainer` on the [openbmb/UltraFeedback](https://huggingface.co/datasets/openbmb/UltraFeedback) dataset, which contains 64k prompts and model completions that are ranked by GPT-4. As a result, the model can be used for chat and you can check out our [demo](https://huggingface.co/spaces/HuggingFaceH4/zephyr-chat) to test its capabilities.
|
||||
|
||||
You can find the datasets used for training Zephyr-7B-β [here](https://huggingface.co/collections/HuggingFaceH4/zephyr-7b-6538c6d6d5ddd1cbb1744a66)
|
||||
|
||||
Here's how you can run the model using the `pipeline()` function from 🤗 Transformers:
|
||||
|
||||
```python
|
||||
# Install transformers from source - only needed for versions <= v4.34
|
||||
# pip install git+https://github.com/huggingface/transformers.git
|
||||
# pip install accelerate
|
||||
|
||||
import torch
|
||||
from transformers import pipeline
|
||||
|
||||
pipe = pipeline("text-generation", model="HuggingFaceH4/zephyr-7b-beta", torch_dtype=torch.bfloat16, device_map="auto")
|
||||
|
||||
# We use the tokenizer's chat template to format each message - see https://huggingface.co/docs/transformers/main/en/chat_templating
|
||||
messages = [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a friendly chatbot who always responds in the style of a pirate",
|
||||
},
|
||||
{"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
|
||||
]
|
||||
prompt = pipe.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
|
||||
outputs = pipe(prompt, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
|
||||
print(outputs[0]["generated_text"])
|
||||
# <|system|>
|
||||
# You are a friendly chatbot who always responds in the style of a pirate.</s>
|
||||
# <|user|>
|
||||
# How many helicopters can a human eat in one sitting?</s>
|
||||
# <|assistant|>
|
||||
# Ah, me hearty matey! But yer question be a puzzler! A human cannot eat a helicopter in one sitting, as helicopters are not edible. They be made of metal, plastic, and other materials, not food!
|
||||
```
|
||||
|
||||
## Bias, Risks, and Limitations
|
||||
|
||||
<!-- This section is meant to convey both technical and sociotechnical limitations. -->
|
||||
|
||||
Zephyr-7B-β has not been aligned to human preferences with techniques like RLHF or deployed with in-the-loop filtering of responses like ChatGPT, so the model can produce problematic outputs (especially when prompted to do so).
|
||||
It is also unknown what the size and composition of the corpus was used to train the base model (`mistralai/Mistral-7B-v0.1`), however it is likely to have included a mix of Web data and technical sources like books and code. See the [Falcon 180B model card](https://huggingface.co/tiiuae/falcon-180B#training-data) for an example of this.
|
||||
|
||||
|
||||
## Training and evaluation data
|
||||
|
||||
During DPO training, this model achieves the following results on the evaluation set:
|
||||
|
||||
- Loss: 0.7496
|
||||
- Rewards/chosen: -4.5221
|
||||
- Rewards/rejected: -8.3184
|
||||
- Rewards/accuracies: 0.7812
|
||||
- Rewards/margins: 3.7963
|
||||
- Logps/rejected: -340.1541
|
||||
- Logps/chosen: -299.4561
|
||||
- Logits/rejected: -2.3081
|
||||
- Logits/chosen: -2.3531
|
||||
|
||||
|
||||
### Training hyperparameters
|
||||
|
||||
The following hyperparameters were used during training:
|
||||
- learning_rate: 5e-07
|
||||
- train_batch_size: 2
|
||||
- eval_batch_size: 4
|
||||
- seed: 42
|
||||
- distributed_type: multi-GPU
|
||||
- num_devices: 16
|
||||
- total_train_batch_size: 32
|
||||
- total_eval_batch_size: 64
|
||||
- optimizer: Adam with betas=(0.9,0.999) and epsilon=1e-08
|
||||
- lr_scheduler_type: linear
|
||||
- lr_scheduler_warmup_ratio: 0.1
|
||||
- num_epochs: 3.0
|
||||
|
||||
### Training results
|
||||
|
||||
The table below shows the full set of DPO training metrics:
|
||||
|
||||
|
||||
| Training Loss | Epoch | Step | Validation Loss | Rewards/chosen | Rewards/rejected | Rewards/accuracies | Rewards/margins | Logps/rejected | Logps/chosen | Logits/rejected | Logits/chosen |
|
||||
|:-------------:|:-----:|:----:|:---------------:|:--------------:|:----------------:|:------------------:|:---------------:|:--------------:|:------------:|:---------------:|:-------------:|
|
||||
| 0.6284 | 0.05 | 100 | 0.6098 | 0.0425 | -0.1872 | 0.7344 | 0.2297 | -258.8416 | -253.8099 | -2.7976 | -2.8234 |
|
||||
| 0.4908 | 0.1 | 200 | 0.5426 | -0.0279 | -0.6842 | 0.75 | 0.6563 | -263.8124 | -254.5145 | -2.7719 | -2.7960 |
|
||||
| 0.5264 | 0.15 | 300 | 0.5324 | 0.0414 | -0.9793 | 0.7656 | 1.0207 | -266.7627 | -253.8209 | -2.7892 | -2.8122 |
|
||||
| 0.5536 | 0.21 | 400 | 0.4957 | -0.0185 | -1.5276 | 0.7969 | 1.5091 | -272.2460 | -254.4203 | -2.8542 | -2.8764 |
|
||||
| 0.5362 | 0.26 | 500 | 0.5031 | -0.2630 | -1.5917 | 0.7812 | 1.3287 | -272.8869 | -256.8653 | -2.8702 | -2.8958 |
|
||||
| 0.5966 | 0.31 | 600 | 0.5963 | -0.2993 | -1.6491 | 0.7812 | 1.3499 | -273.4614 | -257.2279 | -2.8778 | -2.8986 |
|
||||
| 0.5014 | 0.36 | 700 | 0.5382 | -0.2859 | -1.4750 | 0.75 | 1.1891 | -271.7204 | -257.0942 | -2.7659 | -2.7869 |
|
||||
| 0.5334 | 0.41 | 800 | 0.5677 | -0.4289 | -1.8968 | 0.7969 | 1.4679 | -275.9378 | -258.5242 | -2.7053 | -2.7265 |
|
||||
| 0.5251 | 0.46 | 900 | 0.5772 | -0.2116 | -1.3107 | 0.7344 | 1.0991 | -270.0768 | -256.3507 | -2.8463 | -2.8662 |
|
||||
| 0.5205 | 0.52 | 1000 | 0.5262 | -0.3792 | -1.8585 | 0.7188 | 1.4793 | -275.5552 | -258.0276 | -2.7893 | -2.7979 |
|
||||
| 0.5094 | 0.57 | 1100 | 0.5433 | -0.6279 | -1.9368 | 0.7969 | 1.3089 | -276.3377 | -260.5136 | -2.7453 | -2.7536 |
|
||||
| 0.5837 | 0.62 | 1200 | 0.5349 | -0.3780 | -1.9584 | 0.7656 | 1.5804 | -276.5542 | -258.0154 | -2.7643 | -2.7756 |
|
||||
| 0.5214 | 0.67 | 1300 | 0.5732 | -1.0055 | -2.2306 | 0.7656 | 1.2251 | -279.2761 | -264.2903 | -2.6986 | -2.7113 |
|
||||
| 0.6914 | 0.72 | 1400 | 0.5137 | -0.6912 | -2.1775 | 0.7969 | 1.4863 | -278.7448 | -261.1467 | -2.7166 | -2.7275 |
|
||||
| 0.4655 | 0.77 | 1500 | 0.5090 | -0.7987 | -2.2930 | 0.7031 | 1.4943 | -279.8999 | -262.2220 | -2.6651 | -2.6838 |
|
||||
| 0.5731 | 0.83 | 1600 | 0.5312 | -0.8253 | -2.3520 | 0.7812 | 1.5268 | -280.4902 | -262.4876 | -2.6543 | -2.6728 |
|
||||
| 0.5233 | 0.88 | 1700 | 0.5206 | -0.4573 | -2.0951 | 0.7812 | 1.6377 | -277.9205 | -258.8084 | -2.6870 | -2.7097 |
|
||||
| 0.5593 | 0.93 | 1800 | 0.5231 | -0.5508 | -2.2000 | 0.7969 | 1.6492 | -278.9703 | -259.7433 | -2.6221 | -2.6519 |
|
||||
| 0.4967 | 0.98 | 1900 | 0.5290 | -0.5340 | -1.9570 | 0.8281 | 1.4230 | -276.5395 | -259.5749 | -2.6564 | -2.6878 |
|
||||
| 0.0921 | 1.03 | 2000 | 0.5368 | -1.1376 | -3.1615 | 0.7812 | 2.0239 | -288.5854 | -265.6111 | -2.6040 | -2.6345 |
|
||||
| 0.0733 | 1.08 | 2100 | 0.5453 | -1.1045 | -3.4451 | 0.7656 | 2.3406 | -291.4208 | -265.2799 | -2.6289 | -2.6595 |
|
||||
| 0.0972 | 1.14 | 2200 | 0.5571 | -1.6915 | -3.9823 | 0.8125 | 2.2908 | -296.7934 | -271.1505 | -2.6471 | -2.6709 |
|
||||
| 0.1058 | 1.19 | 2300 | 0.5789 | -1.0621 | -3.8941 | 0.7969 | 2.8319 | -295.9106 | -264.8563 | -2.5527 | -2.5798 |
|
||||
| 0.2423 | 1.24 | 2400 | 0.5455 | -1.1963 | -3.5590 | 0.7812 | 2.3627 | -292.5599 | -266.1981 | -2.5414 | -2.5784 |
|
||||
| 0.1177 | 1.29 | 2500 | 0.5889 | -1.8141 | -4.3942 | 0.7969 | 2.5801 | -300.9120 | -272.3761 | -2.4802 | -2.5189 |
|
||||
| 0.1213 | 1.34 | 2600 | 0.5683 | -1.4608 | -3.8420 | 0.8125 | 2.3812 | -295.3901 | -268.8436 | -2.4774 | -2.5207 |
|
||||
| 0.0889 | 1.39 | 2700 | 0.5890 | -1.6007 | -3.7337 | 0.7812 | 2.1330 | -294.3068 | -270.2423 | -2.4123 | -2.4522 |
|
||||
| 0.0995 | 1.45 | 2800 | 0.6073 | -1.5519 | -3.8362 | 0.8281 | 2.2843 | -295.3315 | -269.7538 | -2.4685 | -2.5050 |
|
||||
| 0.1145 | 1.5 | 2900 | 0.5790 | -1.7939 | -4.2876 | 0.8438 | 2.4937 | -299.8461 | -272.1744 | -2.4272 | -2.4674 |
|
||||
| 0.0644 | 1.55 | 3000 | 0.5735 | -1.7285 | -4.2051 | 0.8125 | 2.4766 | -299.0209 | -271.5201 | -2.4193 | -2.4574 |
|
||||
| 0.0798 | 1.6 | 3100 | 0.5537 | -1.7226 | -4.2850 | 0.8438 | 2.5624 | -299.8200 | -271.4610 | -2.5367 | -2.5696 |
|
||||
| 0.1013 | 1.65 | 3200 | 0.5575 | -1.5715 | -3.9813 | 0.875 | 2.4098 | -296.7825 | -269.9498 | -2.4926 | -2.5267 |
|
||||
| 0.1254 | 1.7 | 3300 | 0.5905 | -1.6412 | -4.4703 | 0.8594 | 2.8291 | -301.6730 | -270.6473 | -2.5017 | -2.5340 |
|
||||
| 0.085 | 1.76 | 3400 | 0.6133 | -1.9159 | -4.6760 | 0.8438 | 2.7601 | -303.7296 | -273.3941 | -2.4614 | -2.4960 |
|
||||
| 0.065 | 1.81 | 3500 | 0.6074 | -1.8237 | -4.3525 | 0.8594 | 2.5288 | -300.4951 | -272.4724 | -2.4597 | -2.5004 |
|
||||
| 0.0755 | 1.86 | 3600 | 0.5836 | -1.9252 | -4.4005 | 0.8125 | 2.4753 | -300.9748 | -273.4872 | -2.4327 | -2.4716 |
|
||||
| 0.0746 | 1.91 | 3700 | 0.5789 | -1.9280 | -4.4906 | 0.8125 | 2.5626 | -301.8762 | -273.5149 | -2.4686 | -2.5115 |
|
||||
| 0.1348 | 1.96 | 3800 | 0.6015 | -1.8658 | -4.2428 | 0.8281 | 2.3769 | -299.3976 | -272.8936 | -2.4943 | -2.5393 |
|
||||
| 0.0217 | 2.01 | 3900 | 0.6122 | -2.3335 | -4.9229 | 0.8281 | 2.5894 | -306.1988 | -277.5699 | -2.4841 | -2.5272 |
|
||||
| 0.0219 | 2.07 | 4000 | 0.6522 | -2.9890 | -6.0164 | 0.8281 | 3.0274 | -317.1334 | -284.1248 | -2.4105 | -2.4545 |
|
||||
| 0.0119 | 2.12 | 4100 | 0.6922 | -3.4777 | -6.6749 | 0.7969 | 3.1972 | -323.7187 | -289.0121 | -2.4272 | -2.4699 |
|
||||
| 0.0153 | 2.17 | 4200 | 0.6993 | -3.2406 | -6.6775 | 0.7969 | 3.4369 | -323.7453 | -286.6413 | -2.4047 | -2.4465 |
|
||||
| 0.011 | 2.22 | 4300 | 0.7178 | -3.7991 | -7.4397 | 0.7656 | 3.6406 | -331.3667 | -292.2260 | -2.3843 | -2.4290 |
|
||||
| 0.0072 | 2.27 | 4400 | 0.6840 | -3.3269 | -6.8021 | 0.8125 | 3.4752 | -324.9908 | -287.5042 | -2.4095 | -2.4536 |
|
||||
| 0.0197 | 2.32 | 4500 | 0.7013 | -3.6890 | -7.3014 | 0.8125 | 3.6124 | -329.9841 | -291.1250 | -2.4118 | -2.4543 |
|
||||
| 0.0182 | 2.37 | 4600 | 0.7476 | -3.8994 | -7.5366 | 0.8281 | 3.6372 | -332.3356 | -293.2291 | -2.4163 | -2.4565 |
|
||||
| 0.0125 | 2.43 | 4700 | 0.7199 | -4.0560 | -7.5765 | 0.8438 | 3.5204 | -332.7345 | -294.7952 | -2.3699 | -2.4100 |
|
||||
| 0.0082 | 2.48 | 4800 | 0.7048 | -3.6613 | -7.1356 | 0.875 | 3.4743 | -328.3255 | -290.8477 | -2.3925 | -2.4303 |
|
||||
| 0.0118 | 2.53 | 4900 | 0.6976 | -3.7908 | -7.3152 | 0.8125 | 3.5244 | -330.1224 | -292.1431 | -2.3633 | -2.4047 |
|
||||
| 0.0118 | 2.58 | 5000 | 0.7198 | -3.9049 | -7.5557 | 0.8281 | 3.6508 | -332.5271 | -293.2844 | -2.3764 | -2.4194 |
|
||||
| 0.006 | 2.63 | 5100 | 0.7506 | -4.2118 | -7.9149 | 0.8125 | 3.7032 | -336.1194 | -296.3530 | -2.3407 | -2.3860 |
|
||||
| 0.0143 | 2.68 | 5200 | 0.7408 | -4.2433 | -7.9802 | 0.8125 | 3.7369 | -336.7721 | -296.6682 | -2.3509 | -2.3946 |
|
||||
| 0.0057 | 2.74 | 5300 | 0.7552 | -4.3392 | -8.0831 | 0.7969 | 3.7439 | -337.8013 | -297.6275 | -2.3388 | -2.3842 |
|
||||
| 0.0138 | 2.79 | 5400 | 0.7404 | -4.2395 | -7.9762 | 0.8125 | 3.7367 | -336.7322 | -296.6304 | -2.3286 | -2.3737 |
|
||||
| 0.0079 | 2.84 | 5500 | 0.7525 | -4.4466 | -8.2196 | 0.7812 | 3.7731 | -339.1662 | -298.7007 | -2.3200 | -2.3641 |
|
||||
| 0.0077 | 2.89 | 5600 | 0.7520 | -4.5586 | -8.3485 | 0.7969 | 3.7899 | -340.4545 | -299.8206 | -2.3078 | -2.3517 |
|
||||
| 0.0094 | 2.94 | 5700 | 0.7527 | -4.5542 | -8.3509 | 0.7812 | 3.7967 | -340.4790 | -299.7773 | -2.3062 | -2.3510 |
|
||||
| 0.0054 | 2.99 | 5800 | 0.7520 | -4.5169 | -8.3079 | 0.7812 | 3.7911 | -340.0493 | -299.4038 | -2.3081 | -2.3530 |
|
||||
|
||||
|
||||
### Framework versions
|
||||
|
||||
- Transformers 4.35.0.dev0
|
||||
- Pytorch 2.0.1+cu118
|
||||
- Datasets 2.12.0
|
||||
- Tokenizers 0.14.0
|
||||
|
||||
## Citation
|
||||
|
||||
If you find Zephyr-7B-β is useful in your work, please cite it with:
|
||||
|
||||
```
|
||||
@misc{tunstall2023zephyr,
|
||||
title={Zephyr: Direct Distillation of LM Alignment},
|
||||
author={Lewis Tunstall and Edward Beeching and Nathan Lambert and Nazneen Rajani and Kashif Rasul and Younes Belkada and Shengyi Huang and Leandro von Werra and Clémentine Fourrier and Nathan Habib and Nathan Sarrazin and Omar Sanseviero and Alexander M. Rush and Thomas Wolf},
|
||||
year={2023},
|
||||
eprint={2310.16944},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.LG}
|
||||
}
|
||||
```
|
||||
5
added_tokens.json
Normal file
5
added_tokens.json
Normal file
@@ -0,0 +1,5 @@
|
||||
{
|
||||
"</s>": 2,
|
||||
"<s>": 1,
|
||||
"<unk>": 0
|
||||
}
|
||||
21
all_results.json
Normal file
21
all_results.json
Normal file
@@ -0,0 +1,21 @@
|
||||
{
|
||||
"epoch": 3.0,
|
||||
"eval_logits/chosen": -2.353081703186035,
|
||||
"eval_logits/rejected": -2.308103084564209,
|
||||
"eval_logps/chosen": -299.4560546875,
|
||||
"eval_logps/rejected": -340.154052734375,
|
||||
"eval_loss": 0.7496059536933899,
|
||||
"eval_rewards/accuracies": 0.78125,
|
||||
"eval_rewards/chosen": -4.522095203399658,
|
||||
"eval_rewards/margins": 3.7963125705718994,
|
||||
"eval_rewards/rejected": -8.318408012390137,
|
||||
"eval_runtime": 48.0152,
|
||||
"eval_samples": 1000,
|
||||
"eval_samples_per_second": 20.827,
|
||||
"eval_steps_per_second": 0.333,
|
||||
"train_loss": 0.2172969928600547,
|
||||
"train_runtime": 23865.9828,
|
||||
"train_samples": 61966,
|
||||
"train_samples_per_second": 7.789,
|
||||
"train_steps_per_second": 0.243
|
||||
}
|
||||
26
config.json
Normal file
26
config.json
Normal file
@@ -0,0 +1,26 @@
|
||||
{
|
||||
"_name_or_path": "HuggingFaceH4/zephyr-7b-beta",
|
||||
"architectures": [
|
||||
"MistralForCausalLM"
|
||||
],
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 4096,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 14336,
|
||||
"max_position_embeddings": 32768,
|
||||
"model_type": "mistral",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 32,
|
||||
"num_key_value_heads": 8,
|
||||
"pad_token_id": 2,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"rope_theta": 10000.0,
|
||||
"sliding_window": 4096,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.35.0.dev0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 32000
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework":"Pytorch","task":"text-generation"}
|
||||
16
eval_results.json
Normal file
16
eval_results.json
Normal file
@@ -0,0 +1,16 @@
|
||||
{
|
||||
"epoch": 3.0,
|
||||
"eval_logits/chosen": -2.353081703186035,
|
||||
"eval_logits/rejected": -2.308103084564209,
|
||||
"eval_logps/chosen": -299.4560546875,
|
||||
"eval_logps/rejected": -340.154052734375,
|
||||
"eval_loss": 0.7496059536933899,
|
||||
"eval_rewards/accuracies": 0.78125,
|
||||
"eval_rewards/chosen": -4.522095203399658,
|
||||
"eval_rewards/margins": 3.7963125705718994,
|
||||
"eval_rewards/rejected": -8.318408012390137,
|
||||
"eval_runtime": 48.0152,
|
||||
"eval_samples": 1000,
|
||||
"eval_samples_per_second": 20.827,
|
||||
"eval_steps_per_second": 0.333
|
||||
}
|
||||
6
generation_config.json
Normal file
6
generation_config.json
Normal file
@@ -0,0 +1,6 @@
|
||||
{
|
||||
"_from_model_config": true,
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"transformers_version": "4.35.0.dev0"
|
||||
}
|
||||
3
model-00001-of-00008.safetensors
Normal file
3
model-00001-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a6ec4a0398df9d56786afa9cce026423ec48a07ddc5ed5eba087614cae2dd746
|
||||
size 1889587040
|
||||
3
model-00002-of-00008.safetensors
Normal file
3
model-00002-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:1289796f16f33ef4c6b8a76b3d9e5169198a69daa0b5b660b5a3d5cae0dc1cf7
|
||||
size 1946243936
|
||||
3
model-00003-of-00008.safetensors
Normal file
3
model-00003-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6fc338de96c672840222ca19a12b44f09110048974bde8ab0f4c1da055d99c3f
|
||||
size 1979781432
|
||||
3
model-00004-of-00008.safetensors
Normal file
3
model-00004-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:92d948413fd7ac6c4fd5f6c36902bb7a72d2cddca19628c88e6f3b3e5482ab37
|
||||
size 1946243984
|
||||
3
model-00005-of-00008.safetensors
Normal file
3
model-00005-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d0ce3cc66d224a0e6014a1df6b7e56da29f5db52da1866ad0cc07d7583fb7c31
|
||||
size 1979781448
|
||||
3
model-00006-of-00008.safetensors
Normal file
3
model-00006-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:0b63ef55219d125eaeefabd2a33c358dced22b9c75d1d816bb7a871bd3773951
|
||||
size 1946243984
|
||||
3
model-00007-of-00008.safetensors
Normal file
3
model-00007-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b0e0a3c0b992925ff9a60f1234950af0bcc7ce3015c8a386a342489e76f5d09c
|
||||
size 1979781448
|
||||
3
model-00008-of-00008.safetensors
Normal file
3
model-00008-of-00008.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:667dd6958d5137dcba514db514c7970d18c9cd5d95fbb0c82490d558bd2a246c
|
||||
size 815834680
|
||||
298
model.safetensors.index.json
Normal file
298
model.safetensors.index.json
Normal file
@@ -0,0 +1,298 @@
|
||||
{
|
||||
"metadata": {
|
||||
"total_size": 14483464192
|
||||
},
|
||||
"weight_map": {
|
||||
"lm_head.weight": "model-00008-of-00008.safetensors",
|
||||
"model.embed_tokens.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.input_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.input_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.10.input_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.mlp.down_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.mlp.gate_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.mlp.up_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.post_attention_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.self_attn.k_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.self_attn.o_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.self_attn.q_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.10.self_attn.v_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.input_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.mlp.down_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.mlp.gate_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.mlp.up_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.post_attention_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.self_attn.k_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.self_attn.o_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.self_attn.q_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.11.self_attn.v_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.input_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.12.mlp.down_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.12.mlp.gate_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.mlp.up_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.post_attention_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.12.self_attn.k_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.self_attn.o_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.self_attn.q_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.12.self_attn.v_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.13.input_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.mlp.down_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.mlp.gate_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.mlp.up_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.post_attention_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.self_attn.k_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.self_attn.o_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.self_attn.q_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.13.self_attn.v_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.input_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.mlp.down_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.mlp.gate_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.mlp.up_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.post_attention_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.self_attn.k_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.self_attn.o_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.self_attn.q_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.14.self_attn.v_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.input_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.mlp.down_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.mlp.gate_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.mlp.up_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.post_attention_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.self_attn.k_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.self_attn.o_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.self_attn.q_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.15.self_attn.v_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.input_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.mlp.down_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.mlp.gate_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.mlp.up_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.post_attention_layernorm.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.self_attn.k_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.self_attn.o_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.self_attn.q_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.16.self_attn.v_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.17.input_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.17.mlp.down_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.17.mlp.gate_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.17.mlp.up_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.17.post_attention_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.17.self_attn.k_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.17.self_attn.o_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.17.self_attn.q_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.17.self_attn.v_proj.weight": "model-00004-of-00008.safetensors",
|
||||
"model.layers.18.input_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.mlp.down_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.mlp.gate_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.mlp.up_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.post_attention_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.self_attn.k_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.self_attn.o_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.self_attn.q_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.18.self_attn.v_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.input_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.mlp.down_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.mlp.gate_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.mlp.up_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.post_attention_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.self_attn.k_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.self_attn.o_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.self_attn.q_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.19.self_attn.v_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.2.input_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.20.input_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.mlp.down_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.mlp.gate_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.mlp.up_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.post_attention_layernorm.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.self_attn.k_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.self_attn.o_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.self_attn.q_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.20.self_attn.v_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.input_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.21.mlp.down_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.21.mlp.gate_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.mlp.up_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.post_attention_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.21.self_attn.k_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.self_attn.o_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.self_attn.q_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.21.self_attn.v_proj.weight": "model-00005-of-00008.safetensors",
|
||||
"model.layers.22.input_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.mlp.down_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.mlp.gate_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.mlp.up_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.post_attention_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.self_attn.k_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.self_attn.o_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.self_attn.q_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.22.self_attn.v_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.input_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.mlp.down_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.mlp.gate_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.mlp.up_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.post_attention_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.self_attn.k_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.self_attn.o_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.self_attn.q_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.23.self_attn.v_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.input_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.mlp.down_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.mlp.gate_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.mlp.up_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.post_attention_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.self_attn.k_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.self_attn.o_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.self_attn.q_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.24.self_attn.v_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.input_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.mlp.down_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.mlp.gate_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.mlp.up_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.post_attention_layernorm.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.self_attn.k_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.self_attn.o_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.self_attn.q_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.25.self_attn.v_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.26.input_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.26.mlp.down_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.26.mlp.gate_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.26.mlp.up_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.26.post_attention_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.26.self_attn.k_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.26.self_attn.o_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.26.self_attn.q_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.26.self_attn.v_proj.weight": "model-00006-of-00008.safetensors",
|
||||
"model.layers.27.input_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.mlp.down_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.mlp.gate_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.mlp.up_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.post_attention_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.self_attn.k_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.self_attn.o_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.self_attn.q_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.27.self_attn.v_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.input_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.mlp.down_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.mlp.gate_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.mlp.up_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.post_attention_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.self_attn.k_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.self_attn.o_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.self_attn.q_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.28.self_attn.v_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.input_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.mlp.down_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.mlp.gate_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.mlp.up_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.post_attention_layernorm.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.self_attn.k_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.self_attn.o_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.self_attn.q_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.29.self_attn.v_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.3.input_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.3.mlp.down_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.3.post_attention_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00008.safetensors",
|
||||
"model.layers.30.input_layernorm.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.30.mlp.down_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.30.mlp.gate_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.30.mlp.up_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.30.post_attention_layernorm.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.30.self_attn.k_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.30.self_attn.o_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.30.self_attn.q_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.30.self_attn.v_proj.weight": "model-00007-of-00008.safetensors",
|
||||
"model.layers.31.input_layernorm.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.mlp.down_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.mlp.gate_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.mlp.up_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.post_attention_layernorm.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.self_attn.k_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.self_attn.o_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.self_attn.q_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.31.self_attn.v_proj.weight": "model-00008-of-00008.safetensors",
|
||||
"model.layers.4.input_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.mlp.down_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.mlp.gate_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.mlp.up_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.post_attention_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.self_attn.k_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.self_attn.o_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.self_attn.q_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.4.self_attn.v_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.input_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.mlp.down_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.mlp.gate_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.mlp.up_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.post_attention_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.self_attn.k_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.self_attn.o_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.self_attn.q_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.5.self_attn.v_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.input_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.mlp.down_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.mlp.gate_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.mlp.up_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.post_attention_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.self_attn.k_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.self_attn.o_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.self_attn.q_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.6.self_attn.v_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.input_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.mlp.down_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.mlp.gate_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.mlp.up_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.post_attention_layernorm.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.self_attn.k_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.self_attn.o_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.self_attn.q_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.7.self_attn.v_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.8.input_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.8.mlp.down_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.8.mlp.gate_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.8.mlp.up_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.8.post_attention_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.8.self_attn.k_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.8.self_attn.o_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.8.self_attn.q_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.8.self_attn.v_proj.weight": "model-00002-of-00008.safetensors",
|
||||
"model.layers.9.input_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.mlp.down_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.mlp.gate_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.mlp.up_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.post_attention_layernorm.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.self_attn.k_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.self_attn.o_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.self_attn.q_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.layers.9.self_attn.v_proj.weight": "model-00003-of-00008.safetensors",
|
||||
"model.norm.weight": "model-00008-of-00008.safetensors"
|
||||
}
|
||||
}
|
||||
11
special_tokens_map.json
Normal file
11
special_tokens_map.json
Normal file
@@ -0,0 +1,11 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<unk>",
|
||||
"<s>",
|
||||
"</s>"
|
||||
],
|
||||
"bos_token": "<s>",
|
||||
"eos_token": "</s>",
|
||||
"pad_token": "</s>",
|
||||
"unk_token": "<unk>"
|
||||
}
|
||||
91122
tokenizer.json
Normal file
91122
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
46
tokenizer_config.json
Normal file
46
tokenizer_config.json
Normal file
@@ -0,0 +1,46 @@
|
||||
{
|
||||
"added_tokens_decoder": {
|
||||
"0": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"1": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"2": {
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
}
|
||||
},
|
||||
"additional_special_tokens": [
|
||||
"<unk>",
|
||||
"<s>",
|
||||
"</s>"
|
||||
],
|
||||
"bos_token": "<s>",
|
||||
"chat_template": "{% for message in messages %}\n{% if message['role'] == 'user' %}\n{{ '<|user|>\n' + message['content'] + eos_token }}\n{% elif message['role'] == 'system' %}\n{{ '<|system|>\n' + message['content'] + eos_token }}\n{% elif message['role'] == 'assistant' %}\n{{ '<|assistant|>\n' + message['content'] + eos_token }}\n{% endif %}\n{% if loop.last and add_generation_prompt %}\n{{ '<|assistant|>' }}\n{% endif %}\n{% endfor %}",
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "</s>",
|
||||
"legacy": true,
|
||||
"model_max_length": 1000000000000000019884624838656,
|
||||
"pad_token": "</s>",
|
||||
"sp_model_kwargs": {},
|
||||
"spaces_between_special_tokens": false,
|
||||
"tokenizer_class": "LlamaTokenizer",
|
||||
"truncation_side": "left",
|
||||
"unk_token": "<unk>",
|
||||
"use_default_system_prompt": true
|
||||
}
|
||||
8
train_results.json
Normal file
8
train_results.json
Normal file
@@ -0,0 +1,8 @@
|
||||
{
|
||||
"epoch": 3.0,
|
||||
"train_loss": 0.2172969928600547,
|
||||
"train_runtime": 23865.9828,
|
||||
"train_samples": 61966,
|
||||
"train_samples_per_second": 7.789,
|
||||
"train_steps_per_second": 0.243
|
||||
}
|
||||
9104
trainer_state.json
Normal file
9104
trainer_state.json
Normal file
File diff suppressed because it is too large
Load Diff
3
training_args.bin
Normal file
3
training_args.bin
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8484784a09e7deb9198e9aafc8f9654b6f8fed732a7f9e60d0b3c75aaedb94e4
|
||||
size 5435
|
||||
Reference in New Issue
Block a user