初始化项目,由ModelHub XC社区提供模型
Model: homebrewltd/AlphaMaze-v0.2-1.5B
Source: Original Platform
This commit is contained in:
 ModelHub XC
37
.gitattributes
vendored
Normal file
37
.gitattributes
vendored
Normal file
@@ -0,0 +1,37 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||
alphamaze.gif filter=lfs diff=lfs merge=lfs -text
|
||||
158
README.md
Normal file
158
README.md
Normal file
@@ -0,0 +1,158 @@
|
||||
---
|
||||
base_model: jan-hq/AlphaMaze-v0.2-1.5B
|
||||
tags:
|
||||
- text-generation-inference
|
||||
- transformers
|
||||
- unsloth
|
||||
- qwen2
|
||||
- trl
|
||||
license: apache-2.0
|
||||
language:
|
||||
- en
|
||||
---
|
||||
|
||||
[<img src="https://raw.githubusercontent.com/unslothai/unsloth/main/images/unsloth%20made%20with%20love.png" width="200"/>](https://github.com/unslothai/unsloth)
|
||||
|
||||
<div align="center">
|
||||
|
||||
# AlphaMaze: Teaching LLMs to Think Visually
|
||||
<!---
|
||||
<a href='https://homebrew.ltd/blog/alpha-maze'><img src='https://img.shields.io/badge/Project-Blog-Green'></a>
|
||||
<a href='https://huggingface.co/homebrewltd/AlphaMaze-v0.2-1.5B'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Models-blue'></a>
|
||||
<a href='https://huggingface.co/datasets/homebrewltd/Maze-Reasoning-v0.1'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Data-green'></a>
|
||||
<a href='https://alphamaze.menlo.ai/'><img src='https://img.shields.io/badge/Project-Demo-violet'></a>
|
||||
<a href=''><img src='https://img.shields.io/badge/Paper-Arxiv-red'></a>
|
||||
-->
|
||||
|
||||
[**About**](#About) | [**Demo**](#Demo) | [**Models and Datasets**](#Models-and-Dataset) | [**Benchmarks**](#Benchmarks) | [**How to Run Locally**](#Run-Locally) |
|
||||
|
||||
<img src="./alphamaze.gif" width="400"/>
|
||||
</div>
|
||||
|
||||
## About
|
||||
Developed by **Menlo Research**, **AlphaMaze** is a novel model for evaluating and enhancing visual reasoning in LLMs. AlphaMaze challenges models with a deceptively simple task: solving mazes presented entirely in text. We further enhance AlphaMaze's capabilities using the GRPO (Generalized Relative Policy Optimization) method.
|
||||
|
||||
Prior research, like [Microsoft's "Multimodal Visualization-of-Thought (MVoT)"](https://arxiv.org/abs/2501.07542), explored visual reasoning through image generation. But AlphaMaze takes a different, more focused path. We believe that if a model can internally reconstruct a maze from a text description and use that *mental map* to plan its moves, it demonstrates a genuine capacity for visual reasoning – even without generating a single image. AlphaMaze moves beyond the limitations of multiple-choice evaluations, providing a richer, more nuanced assessment of a model's spatial understanding. We're not just testing if a model *can* solve a maze; we're revealing *how* it thinks about space.
|
||||
|
||||
## Demo
|
||||
|
||||
AlphaMaze tackle a text-based maze! See how it interprets the maze, plans its moves, and strategically resets when it encounters a dead end.
|
||||
|
||||
[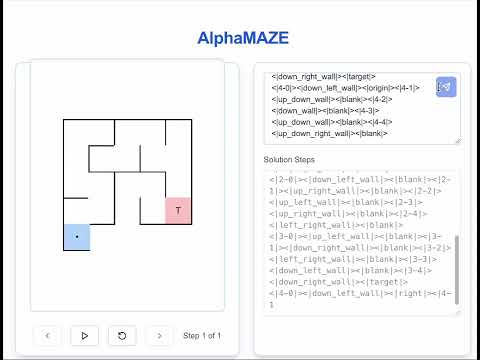](https://www.youtube.com/watch?v=dUS9wR03on8)
|
||||
|
||||
Alternatively, you can explore it on our [demo website](https://alphamaze.menlo.ai/).
|
||||
|
||||
## Models and Datasets
|
||||
|
||||
### Models
|
||||
|
||||
You can find our AlphaMaze models on Hugging Face 🤗! We're committed to open-source and easy access for the research community.
|
||||
|
||||
| Model | Backbone | Size | Link |
|
||||
|--------------|--------------------------------------------------------------------------|-------|----------------------------------------------------------------------------|
|
||||
| AlphaMaze-v0.1 | [DeepSeek-R1-Distill-Qwen-1.5B](https://huggingface.co/deepseek-ai/DeepSeek-R1-Distill-Qwen-1.5B) | 1.5B | [🤗 AlphaMaze-v0.1](https://huggingface.co/homebrewltd/AlphaMaze-v0.2-1.5B) |
|
||||
|
||||
### Datasets
|
||||
|
||||
We've released our datasets on Hugging Face 🤗 to support reproducibility and further research.
|
||||
|
||||
| Dataset | Description | Size | Link |
|
||||
|--------------------------------------|-----------------------------------------------------|-------|-----------------------------------------------------------------------------------------|
|
||||
| Maze-Reasoning-v0.1 | Training set used for Supervised Fine-Tuning (SFT) | 420k | [🤗 Maze-Reasoning-v0.1](https://huggingface.co/datasets/homebrewltd/Maze-Reasoning-v0.1) |
|
||||
| Maze-Reasoning-Reset-v0.1 | Training set for SFT, including reset actions | 50k | [🤗 Maze-Reasoning-Reset-v0.1](https://huggingface.co/datasets/homebrewltd/Maze-Reasoning-Reset-v0.1) |
|
||||
| Maze-Reasoning-GRPO-v0.1 | Training set used for GRPO model | 180k | [🤗 Maze-Reasoning-GRPO-v0.1](https://huggingface.co/datasets/homebrewltd/Maze-Reasoning-GRPO-v0.1) |
|
||||
|
||||
## Benchmarks
|
||||
|
||||
### Supervised Fine-Tuning (SFT)
|
||||
|
||||
We used [LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory) for Supervised Fine-Tuning (SFT) of our AlphaMaze model. Here's a summary of our key training runs:
|
||||
|
||||
| Run ID | Model Config | Dataset | Steps | Final Loss | Hardware | Key Findings |
|
||||
|--------|-------------------------------------------------------------------------------------------|--------------------------------------------------------------------------|-------|------------|-------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| exp-1 | [Full Finetune (Qwen-1.5B)](https://github.com/janhq/visual-thinker/blob/main/training/Llama-factory-config/Qwen2.5_1.5B_distil.yaml) | [Maze Reasoning](https://huggingface.co/datasets/jan-hq/Maze-Reasoning) | 3125 | 0.01 | ~1.5 hours on 6xA6000 | Initial run with new maze tokens. Observed lower performance. |
|
||||
| exp-2 | [Full Finetune (Qwen-1.5B)](https://github.com/janhq/visual-thinker/blob/main/training/Llama-factory-config/Qwen2.5_1.5B_distil.yaml) | [Maze Reasoning](https://huggingface.co/datasets/jan-hq/Maze-Reasoning) | 3125 | 0.01 | ~1.5 hours on 6xA6000 | Trained using pure text descriptions (no new tokens). Surprisingly strong performance. |
|
||||
| exp-3 | [Full Finetune (Qwen-7B)](https://github.com/janhq/visual-thinker/blob/main/training/Llama-factory-config/Qwen2.5_7B_distil.yaml) | [Maze Reasoning](https://huggingface.co/datasets/jan-hq/Maze-Reasoning) | 2344 | 0.0077 | ~12 hours on 6xA6000 | Extended training with pure text descriptions (larger model). |
|
||||
| exp-4 | [Full Finetune (Qwen-1.5B)](https://github.com/janhq/visual-thinker/blob/main/training/Llama-factory-config/Qwen2.5_1.5B_distil.yaml) | [Maze Reasoning](https://huggingface.co/datasets/jan-hq/Maze-Reasoning) | 2344 | ~0 | ~1.5 hours on 6xA6000 | Further extended training with pure text descriptions. Near-zero loss. |
|
||||
| exp-5 | [Full Finetune (Qwen-1.5B)](https://github.com/janhq/visual-thinker/blob/main/training/Llama-factory-config/Qwen2.5_1.5B_distil.yaml) | [Maze Reasoning](https://huggingface.co/datasets/jan-hq/Maze-Reasoning) | 3681 | ~0.02 | ~1 hours on 8xH200 | Experiment with new maze tokens and different hardware. |
|
||||
|
||||
**Key Observations from SFT:**
|
||||
|
||||
* Adding new maze-specific tokens did *not* improve performance, and in some cases, resulted in worse results.
|
||||
* Surprisingly, the model performed well even with *pure text descriptions*, suggesting a strong ability to learn spatial relationships from text alone.
|
||||
* Loss value equal to 0 is concerning.
|
||||
|
||||
**Note:** These results suggest that reducing token complexity can lead to improved performance in translating spatial information into language.
|
||||
|
||||
### Generalized Reward-based Policy Optimization (GRPO)
|
||||
|
||||
We employed [Unsloth](https://unsloth.ai/) for Generalized Reward-based Policy Optimization (GRPO) to further refine the model's maze-solving policy.
|
||||
|
||||
The plot below shows the MazeBench scores (blue crosses) achieved during GRPO training, along with a linear regression trendline (red dashed line). The upward trend demonstrates that GRPO effectively guides the model towards improved maze-solving strategies.
|
||||
|
||||

|
||||
_GRPO training progress, showing MazeBench scores over training steps._
|
||||
|
||||
|
||||
## Run Locally
|
||||
|
||||
For an example of using AlphaMaze with HuggingFace Transformers:
|
||||
|
||||
```python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
import flash_attn
|
||||
|
||||
model_path = "homebrewltd/AlphaMaze-v0.2-1.5B"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_path)
|
||||
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_path,
|
||||
torch_dtype=torch.float16,
|
||||
device_map="auto",
|
||||
attn_implementation="flash_attention_2",
|
||||
)
|
||||
|
||||
maze = """You are a helpful assistant that solves mazes. You will be given a maze represented by a series of tokens. The tokens represent: - Coordinates: <|row-col|> (e.g., <|0-0|>, <|2-4|>) - Walls: <|no_wall|>, <|up_wall|>, <|down_wall|>, <|left_wall|>, <|right_wall|>, <|up_down_wall|>, etc. - Origin: <|origin|> - Target: <|target|> - Movement: <|up|>, <|down|>, <|left|>, <|right|>, <|blank|> Your task is to output the sequence of movements (<|up|>, <|down|>, <|left|>, <|right|>) required to navigate from the origin to the target, based on the provided maze representation. Think step by step. At each step, predict only the next movement token. Output only the move tokens, separated by spaces. MAZE: <|0-0|><|up_left_wall|><|blank|><|0-1|><|up_down_wall|><|blank|><|0-2|><|up_down_wall|><|blank|><|0-3|><|up_right_wall|><|blank|><|0-4|><|up_left_right_wall|><|blank|> <|1-0|><|down_left_wall|><|blank|><|1-1|><|up_right_wall|><|blank|><|1-2|><|up_left_wall|><|blank|><|1-3|><|down_right_wall|><|blank|><|1-4|><|left_right_wall|><|blank|> <|2-0|><|up_left_wall|><|blank|><|2-1|><|down_right_wall|><|blank|><|2-2|><|down_left_wall|><|blank|><|2-3|><|up_down_wall|><|blank|><|2-4|><|down_right_wall|><|target|> <|3-0|><|left_right_wall|><|blank|><|3-1|><|up_left_wall|><|origin|><|3-2|><|up_right_wall|><|blank|><|3-3|><|up_down_left_wall|><|blank|><|3-4|><|up_right_wall|><|blank|> <|4-0|><|down_left_wall|><|blank|><|4-1|><|down_right_wall|><|blank|><|4-2|><|down_left_wall|><|blank|><|4-3|><|up_down_wall|><|blank|><|4-4|><|down_right_wall|><|blank|>"""
|
||||
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": maze
|
||||
}
|
||||
]
|
||||
|
||||
input_ids = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors='pt').to("cuda")
|
||||
generated_ids = model.generate(input_ids, max_new_tokens=2500, temperature=0.8, repetition_penalty=1.1, do_sample=True, eos_token_id=tokenizer.eos_token_id)
|
||||
response = tokenizer.decode(generated_ids[0], skip_special_tokens=True, clean_up_tokenization_space=True)
|
||||
print(f"Solving maze: {response}")
|
||||
```
|
||||
|
||||
## Next Steps
|
||||
We are exploring further GRPO enhancements to boost maze-solving capabilities. Stay tuned for more updates on how GRPO is paving the way for improved spatial reasoning in LLMs!
|
||||
|
||||
## Join Us
|
||||
|
||||
We're looking for collaborators and plan to expand the model's capabilities to include additional spatial tasks in the future.
|
||||
|
||||
## References
|
||||
|
||||
```bibtex
|
||||
@misc{dao2025alphamazeenhancinglargelanguage,
|
||||
title={AlphaMaze: Enhancing Large Language Models' Spatial Intelligence via GRPO},
|
||||
author={Alan Dao and Dinh Bach Vu},
|
||||
year={2025},
|
||||
eprint={2502.14669},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2502.14669},
|
||||
}
|
||||
```
|
||||
|
||||
## Acknowledgement
|
||||
|
||||
- [llama-factory](https://github.com/hiyouga/LLaMA-Factory)
|
||||
- [unsloth](https://unsloth.ai/)
|
||||
- [Deepseek](https://github.com/deepseek-ai/DeepSeek-R1)
|
||||
- [Multimodal Visualization-of-Thought (MVoT)](https://arxiv.org/abs/2501.07542)
|
||||
3
alphamaze.gif
Normal file
3
alphamaze.gif
Normal file

@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:32d67240d98334c7e09e0ff2ac92bc7fe3d287ca099831bc529e7b9c29a57362
|
||||
size 6954960
|
||||
32
config.json
Normal file
32
config.json
Normal file
@@ -0,0 +1,32 @@
|
||||
{
|
||||
"_name_or_path": "jan-hq/AlphaMaze-v0.2-1.5B",
|
||||
"architectures": [
|
||||
"Qwen2ForCausalLM"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 151643,
|
||||
"eos_token_id": 151643,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 1536,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 8960,
|
||||
"max_position_embeddings": 131072,
|
||||
"max_window_layers": 21,
|
||||
"model_type": "qwen2",
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 28,
|
||||
"num_key_value_heads": 2,
|
||||
"pad_token_id": 151654,
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_scaling": null,
|
||||
"rope_theta": 10000,
|
||||
"sliding_window": null,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.49.0",
|
||||
"unsloth_version": "2025.2.12",
|
||||
"use_cache": true,
|
||||
"use_mrope": false,
|
||||
"use_sliding_window": false,
|
||||
"vocab_size": 151936
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||
11
generation_config.json
Normal file
11
generation_config.json
Normal file
@@ -0,0 +1,11 @@
|
||||
{
|
||||
"_from_model_config": true,
|
||||
"bos_token_id": 151646,
|
||||
"do_sample": true,
|
||||
"eos_token_id": 151643,
|
||||
"max_length": 131072,
|
||||
"pad_token_id": 151654,
|
||||
"temperature": 0.6,
|
||||
"top_p": 0.95,
|
||||
"transformers_version": "4.49.0"
|
||||
}
|
||||
3
model.safetensors
Normal file
3
model.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:16264c9abd8f090b9d1518f3a8bef79c485666374f5356995cc7b2ed74fc4213
|
||||
size 3554214752
|
||||
23
special_tokens_map.json
Normal file
23
special_tokens_map.json
Normal file
@@ -0,0 +1,23 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|begin▁of▁sentence|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|end▁of▁sentence|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": {
|
||||
"content": "<|vision_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8730126b34dd527064a803e9311c9fa8264761937c503493b8c05599cf8edd3c
|
||||
size 11431945
|
||||
584
tokenizer_config.json
Normal file
584
tokenizer_config.json
Normal file
@@ -0,0 +1,584 @@
|
||||
{
|
||||
"add_bos_token": true,
|
||||
"add_eos_token": false,
|
||||
"add_prefix_space": null,
|
||||
"added_tokens_decoder": {
|
||||
"151643": {
|
||||
"content": "<|end▁of▁sentence|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151644": {
|
||||
"content": "<|User|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151645": {
|
||||
"content": "<|Assistant|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151646": {
|
||||
"content": "<|begin▁of▁sentence|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151647": {
|
||||
"content": "<|EOT|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151648": {
|
||||
"content": "<think>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151649": {
|
||||
"content": "</think>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151650": {
|
||||
"content": "<|quad_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151651": {
|
||||
"content": "<|quad_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151652": {
|
||||
"content": "<|vision_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151653": {
|
||||
"content": "<|vision_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151654": {
|
||||
"content": "<|vision_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151655": {
|
||||
"content": "<|image_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151656": {
|
||||
"content": "<|video_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151657": {
|
||||
"content": "<tool_call>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151658": {
|
||||
"content": "</tool_call>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151659": {
|
||||
"content": "<|fim_prefix|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151660": {
|
||||
"content": "<|fim_middle|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151661": {
|
||||
"content": "<|fim_suffix|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151662": {
|
||||
"content": "<|fim_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151663": {
|
||||
"content": "<|repo_name|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151664": {
|
||||
"content": "<|file_sep|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151665": {
|
||||
"content": "<|0-0|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151666": {
|
||||
"content": "<|0-1|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151667": {
|
||||
"content": "<|0-2|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151668": {
|
||||
"content": "<|0-3|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151669": {
|
||||
"content": "<|0-4|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151670": {
|
||||
"content": "<|1-0|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151671": {
|
||||
"content": "<|1-1|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151672": {
|
||||
"content": "<|1-2|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151673": {
|
||||
"content": "<|1-3|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151674": {
|
||||
"content": "<|1-4|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151675": {
|
||||
"content": "<|2-0|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151676": {
|
||||
"content": "<|2-1|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151677": {
|
||||
"content": "<|2-2|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151678": {
|
||||
"content": "<|2-3|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151679": {
|
||||
"content": "<|2-4|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151680": {
|
||||
"content": "<|3-0|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151681": {
|
||||
"content": "<|3-1|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151682": {
|
||||
"content": "<|3-2|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151683": {
|
||||
"content": "<|3-3|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151684": {
|
||||
"content": "<|3-4|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151685": {
|
||||
"content": "<|4-0|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151686": {
|
||||
"content": "<|4-1|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151687": {
|
||||
"content": "<|4-2|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151688": {
|
||||
"content": "<|4-3|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151689": {
|
||||
"content": "<|4-4|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151690": {
|
||||
"content": "<|up|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151691": {
|
||||
"content": "<|down|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151692": {
|
||||
"content": "<|left|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151693": {
|
||||
"content": "<|right|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151694": {
|
||||
"content": "<|blank|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151695": {
|
||||
"content": "<|origin|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151696": {
|
||||
"content": "<|target|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151697": {
|
||||
"content": "<|no_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151698": {
|
||||
"content": "<|up_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151699": {
|
||||
"content": "<|down_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151700": {
|
||||
"content": "<|left_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151701": {
|
||||
"content": "<|right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151702": {
|
||||
"content": "<|up_down_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151703": {
|
||||
"content": "<|up_left_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151704": {
|
||||
"content": "<|up_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151705": {
|
||||
"content": "<|down_left_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151706": {
|
||||
"content": "<|down_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151707": {
|
||||
"content": "<|left_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151708": {
|
||||
"content": "<|up_down_left_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151709": {
|
||||
"content": "<|up_down_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151710": {
|
||||
"content": "<|up_left_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151711": {
|
||||
"content": "<|down_left_right_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151712": {
|
||||
"content": "<|all_wall|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
}
|
||||
},
|
||||
"bos_token": "<|begin▁of▁sentence|>",
|
||||
"chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% set ns = namespace(is_first=false, is_tool=false, is_output_first=true, system_prompt='') %}{%- for message in messages %}{%- if message['role'] == 'system' %}{% set ns.system_prompt = message['content'] %}{%- endif %}{%- endfor %}{{bos_token}}{{ns.system_prompt}}{%- for message in messages %}{%- if message['role'] == 'user' %}{%- set ns.is_tool = false -%}{{'<|User|>' + message['content']}}{%- endif %}{%- if message['role'] == 'assistant' and message['content'] is none %}{%- set ns.is_tool = false -%}{%- for tool in message['tool_calls']%}{%- if not ns.is_first %}{{'<|Assistant|><|tool▁calls▁begin|><|tool▁call▁begin|>' + tool['type'] + '<|tool▁sep|>' + tool['function']['name'] + '\\n' + '```json' + '\\n' + tool['function']['arguments'] + '\\n' + '```' + '<|tool▁call▁end|>'}}{%- set ns.is_first = true -%}{%- else %}{{'\\n' + '<|tool▁call▁begin|>' + tool['type'] + '<|tool▁sep|>' + tool['function']['name'] + '\\n' + '```json' + '\\n' + tool['function']['arguments'] + '\\n' + '```' + '<|tool▁call▁end|>'}}{{'<|tool▁calls▁end|><|end▁of▁sentence|>'}}{%- endif %}{%- endfor %}{%- endif %}{%- if message['role'] == 'assistant' and message['content'] is not none %}{%- if ns.is_tool %}{{'<|tool▁outputs▁end|>' + message['content'] + '<|end▁of▁sentence|>'}}{%- set ns.is_tool = false -%}{%- else %}{% set content = message['content'] %}{% if '</think>' in content %}{% set content = content.split('</think>')[-1] %}{% endif %}{{'<|Assistant|>' + content + '<|end▁of▁sentence|>'}}{%- endif %}{%- endif %}{%- if message['role'] == 'tool' %}{%- set ns.is_tool = true -%}{%- if ns.is_output_first %}{{'<|tool▁outputs▁begin|><|tool▁output▁begin|>' + message['content'] + '<|tool▁output▁end|>'}}{%- set ns.is_output_first = false %}{%- else %}{{'\\n<|tool▁output▁begin|>' + message['content'] + '<|tool▁output▁end|>'}}{%- endif %}{%- endif %}{%- endfor -%}{% if ns.is_tool %}{{'<|tool▁outputs▁end|>'}}{% endif %}{% if add_generation_prompt and not ns.is_tool %}{{'<|Assistant|>'}}{% endif %}",
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "<|end▁of▁sentence|>",
|
||||
"extra_special_tokens": {},
|
||||
"legacy": true,
|
||||
"max_length": null,
|
||||
"model_max_length": 131072,
|
||||
"pad_to_multiple_of": null,
|
||||
"pad_token": "<|vision_pad|>",
|
||||
"pad_token_type_id": 0,
|
||||
"padding_side": "left",
|
||||
"sp_model_kwargs": {},
|
||||
"split_special_tokens": false,
|
||||
"tokenizer_class": "LlamaTokenizerFast",
|
||||
"unk_token": null,
|
||||
"use_default_system_prompt": false
|
||||
}
|
||||
Reference in New Issue
Block a user