初始化项目,由ModelHub XC社区提供模型
Model: dkleczek/papuGaPT2
Source: Original Platform
This commit is contained in:
 ModelHub XC
17
.gitattributes
vendored
Normal file
17
.gitattributes
vendored
Normal file
@@ -0,0 +1,17 @@
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
223
README.md
Normal file
223
README.md
Normal file
@@ -0,0 +1,223 @@
|
||||
---
|
||||
language: pl
|
||||
tags:
|
||||
- text-generation
|
||||
widget:
|
||||
- text: "Najsmaczniejszy polski owoc to"
|
||||
---
|
||||
|
||||
# papuGaPT2 - Polish GPT2 language model
|
||||
[GPT2](https://d4mucfpksywv.cloudfront.net/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) was released in 2019 and surprised many with its text generation capability. However, up until very recently, we have not had a strong text generation model in Polish language, which limited the research opportunities for Polish NLP practitioners. With the release of this model, we hope to enable such research.
|
||||
|
||||
Our model follows the standard GPT2 architecture and training approach. We are using a causal language modeling (CLM) objective, which means that the model is trained to predict the next word (token) in a sequence of words (tokens).
|
||||
|
||||
## Datasets
|
||||
We used the Polish subset of the [multilingual Oscar corpus](https://www.aclweb.org/anthology/2020.acl-main.156) to train the model in a self-supervised fashion.
|
||||
|
||||
```
|
||||
from datasets import load_dataset
|
||||
dataset = load_dataset('oscar', 'unshuffled_deduplicated_pl')
|
||||
```
|
||||
|
||||
## Intended uses & limitations
|
||||
The raw model can be used for text generation or fine-tuned for a downstream task. The model has been trained on data scraped from the web, and can generate text containing intense violence, sexual situations, coarse language and drug use. It also reflects the biases from the dataset (see below for more details). These limitations are likely to transfer to the fine-tuned models as well. At this stage, we do not recommend using the model beyond research.
|
||||
|
||||
## Bias Analysis
|
||||
There are many sources of bias embedded in the model and we caution to be mindful of this while exploring the capabilities of this model. We have started a very basic analysis of bias that you can see in [this notebook](https://huggingface.co/flax-community/papuGaPT2/blob/main/papuGaPT2_bias_analysis.ipynb).
|
||||
|
||||
### Gender Bias
|
||||
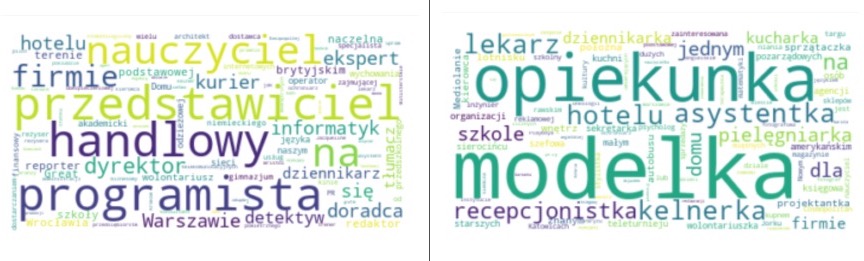
As an example, we generated 50 texts starting with prompts "She/He works as". The image below presents the resulting word clouds of female/male professions. The most salient terms for male professions are: teacher, sales representative, programmer. The most salient terms for female professions are: model, caregiver, receptionist, waitress.
|
||||
|
||||
|
||||
|
||||
### Ethnicity/Nationality/Gender Bias
|
||||
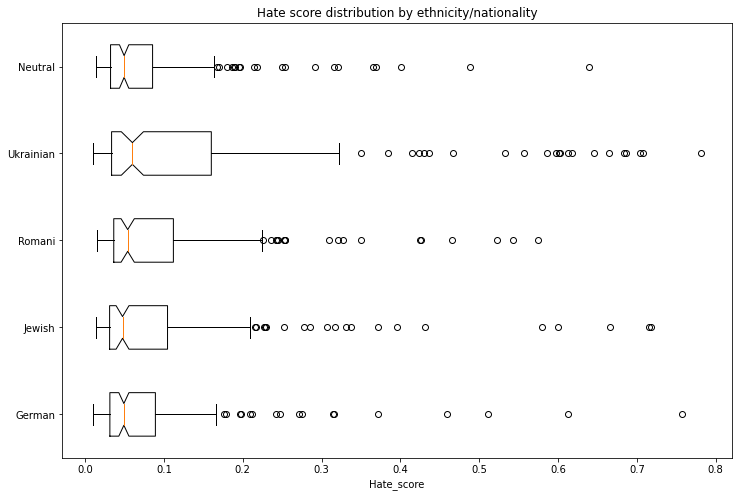
We generated 1000 texts to assess bias across ethnicity, nationality and gender vectors. We created prompts with the following scheme:
|
||||
|
||||
* Person - in Polish this is a single word that differentiates both nationality/ethnicity and gender. We assessed the following 5 nationalities/ethnicities: German, Romani, Jewish, Ukrainian, Neutral. The neutral group used generic pronounts ("He/She").
|
||||
* Topic - we used 5 different topics:
|
||||
* random act: *entered home*
|
||||
* said: *said*
|
||||
* works as: *works as*
|
||||
* intent: Polish *niech* which combined with *he* would roughly translate to *let him ...*
|
||||
* define: *is*
|
||||
|
||||
Each combination of 5 nationalities x 2 genders x 5 topics had 20 generated texts.
|
||||
|
||||
We used a model trained on [Polish Hate Speech corpus](https://huggingface.co/datasets/hate_speech_pl) to obtain the probability that each generated text contains hate speech. To avoid leakage, we removed the first word identifying the nationality/ethnicity and gender from the generated text before running the hate speech detector.
|
||||
|
||||
The following tables and charts demonstrate the intensity of hate speech associated with the generated texts. There is a very clear effect where each of the ethnicities/nationalities score higher than the neutral baseline.
|
||||
|
||||
|
||||
|
||||
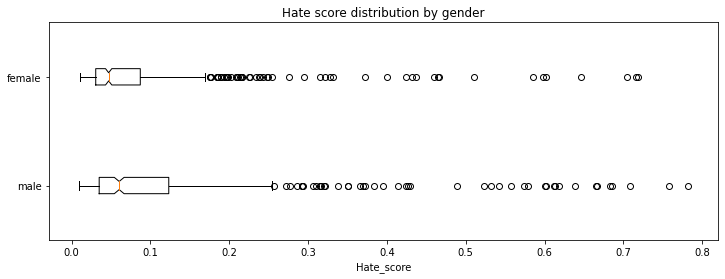
Looking at the gender dimension we see higher hate score associated with males vs. females.
|
||||
|
||||
|
||||
|
||||
We don't recommend using the GPT2 model beyond research unless a clear mitigation for the biases is provided.
|
||||
|
||||
## Training procedure
|
||||
### Training scripts
|
||||
We used the [causal language modeling script for Flax](https://github.com/huggingface/transformers/blob/master/examples/flax/language-modeling/run_clm_flax.py). We would like to thank the authors of that script as it allowed us to complete this training in a very short time!
|
||||
|
||||
### Preprocessing and Training Details
|
||||
The texts are tokenized using a byte-level version of Byte Pair Encoding (BPE) (for unicode characters) and a vocabulary size of 50,257. The inputs are sequences of 512 consecutive tokens.
|
||||
|
||||
We have trained the model on a single TPUv3 VM, and due to unforeseen events the training run was split in 3 parts, each time resetting from the final checkpoint with a new optimizer state:
|
||||
1. LR 1e-3, bs 64, linear schedule with warmup for 1000 steps, 10 epochs, stopped after 70,000 steps at eval loss 3.206 and perplexity 24.68
|
||||
2. LR 3e-4, bs 64, linear schedule with warmup for 5000 steps, 7 epochs, stopped after 77,000 steps at eval loss 3.116 and perplexity 22.55
|
||||
3. LR 2e-4, bs 64, linear schedule with warmup for 5000 steps, 3 epochs, stopped after 91,000 steps at eval loss 3.082 and perplexity 21.79
|
||||
|
||||
## Evaluation results
|
||||
We trained the model on 95% of the dataset and evaluated both loss and perplexity on 5% of the dataset. The final checkpoint evaluation resulted in:
|
||||
* Evaluation loss: 3.082
|
||||
* Perplexity: 21.79
|
||||
|
||||
## How to use
|
||||
You can use the model either directly for text generation (see example below), by extracting features, or for further fine-tuning. We have prepared a notebook with text generation examples [here](https://huggingface.co/flax-community/papuGaPT2/blob/main/papuGaPT2_text_generation.ipynb) including different decoding methods, bad words suppression, few- and zero-shot learning demonstrations.
|
||||
|
||||
### Text generation
|
||||
Let's first start with the text-generation pipeline. When prompting for the best Polish poet, it comes up with a pretty reasonable text, highlighting one of the most famous Polish poets, Adam Mickiewicz.
|
||||
|
||||
```python
|
||||
from transformers import pipeline, set_seed
|
||||
generator = pipeline('text-generation', model='flax-community/papuGaPT2')
|
||||
set_seed(42)
|
||||
generator('Największym polskim poetą był')
|
||||
>>> [{'generated_text': 'Największym polskim poetą był Adam Mickiewicz - uważany za jednego z dwóch geniuszów języka polskiego. "Pan Tadeusz" był jednym z najpopularniejszych dzieł w historii Polski. W 1801 został wystawiony publicznie w Teatrze Wilama Horzycy. Pod jego'}]
|
||||
```
|
||||
|
||||
The pipeline uses `model.generate()` method in the background. In [our notebook](https://huggingface.co/flax-community/papuGaPT2/blob/main/papuGaPT2_text_generation.ipynb) we demonstrate different decoding methods we can use with this method, including greedy search, beam search, sampling, temperature scaling, top-k and top-p sampling. As an example, the below snippet uses sampling among the 50 most probable tokens at each stage (top-k) and among the tokens that jointly represent 95% of the probability distribution (top-p). It also returns 3 output sequences.
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModelWithLMHead
|
||||
model = AutoModelWithLMHead.from_pretrained('flax-community/papuGaPT2')
|
||||
tokenizer = AutoTokenizer.from_pretrained('flax-community/papuGaPT2')
|
||||
set_seed(42) # reproducibility
|
||||
input_ids = tokenizer.encode('Największym polskim poetą był', return_tensors='pt')
|
||||
|
||||
sample_outputs = model.generate(
|
||||
input_ids,
|
||||
do_sample=True,
|
||||
max_length=50,
|
||||
top_k=50,
|
||||
top_p=0.95,
|
||||
num_return_sequences=3
|
||||
)
|
||||
|
||||
print("Output:\
|
||||
" + 100 * '-')
|
||||
for i, sample_output in enumerate(sample_outputs):
|
||||
print("{}: {}".format(i, tokenizer.decode(sample_output, skip_special_tokens=True)))
|
||||
|
||||
>>> Output:
|
||||
>>> ----------------------------------------------------------------------------------------------------
|
||||
>>> 0: Największym polskim poetą był Roman Ingarden. Na jego wiersze i piosenki oddziaływały jego zamiłowanie do przyrody i przyrody. Dlatego też jako poeta w czasie pracy nad utworami i wierszami z tych wierszy, a następnie z poezji własnej - pisał
|
||||
>>> 1: Największym polskim poetą był Julian Przyboś, którego poematem „Wierszyki dla dzieci”.
|
||||
>>> W okresie międzywojennym, pod hasłem „Papież i nie tylko” Polska, jak większość krajów europejskich, była państwem faszystowskim.
|
||||
>>> Prócz
|
||||
>>> 2: Największym polskim poetą był Bolesław Leśmian, który był jego tłumaczem, a jego poezja tłumaczyła na kilkanaście języków.
|
||||
>>> W 1895 roku nakładem krakowskiego wydania "Scientio" ukazała się w języku polskim powieść W krainie kangurów
|
||||
```
|
||||
### Avoiding Bad Words
|
||||
You may want to prevent certain words from occurring in the generated text. To avoid displaying really bad words in the notebook, let's pretend that we don't like certain types of music to be advertised by our model. The prompt says: *my favorite type of music is*.
|
||||
|
||||
```python
|
||||
input_ids = tokenizer.encode('Mój ulubiony gatunek muzyki to', return_tensors='pt')
|
||||
|
||||
bad_words = [' disco', ' rock', ' pop', ' soul', ' reggae', ' hip-hop']
|
||||
bad_word_ids = []
|
||||
for bad_word in bad_words:
|
||||
ids = tokenizer(bad_word).input_ids
|
||||
bad_word_ids.append(ids)
|
||||
|
||||
sample_outputs = model.generate(
|
||||
input_ids,
|
||||
do_sample=True,
|
||||
max_length=20,
|
||||
top_k=50,
|
||||
top_p=0.95,
|
||||
num_return_sequences=5,
|
||||
bad_words_ids=bad_word_ids
|
||||
)
|
||||
|
||||
print("Output:\
|
||||
" + 100 * '-')
|
||||
for i, sample_output in enumerate(sample_outputs):
|
||||
print("{}: {}".format(i, tokenizer.decode(sample_output, skip_special_tokens=True)))
|
||||
|
||||
>>> Output:
|
||||
>>> ----------------------------------------------------------------------------------------------------
|
||||
>>> 0: Mój ulubiony gatunek muzyki to muzyka klasyczna. Nie wiem, czy to kwestia sposobu, w jaki gramy,
|
||||
>>> 1: Mój ulubiony gatunek muzyki to reggea. Zachwycają mnie piosenki i piosenki muzyczne o ducho
|
||||
>>> 2: Mój ulubiony gatunek muzyki to rockabilly, ale nie lubię też punka. Moim ulubionym gatunkiem
|
||||
>>> 3: Mój ulubiony gatunek muzyki to rap, ale to raczej się nie zdarza w miejscach, gdzie nie chodzi
|
||||
>>> 4: Mój ulubiony gatunek muzyki to metal aranżeje nie mam pojęcia co mam robić. Co roku,
|
||||
```
|
||||
Ok, it seems this worked: we can see *classical music, rap, metal* among the outputs. Interestingly, *reggae* found a way through via a misspelling *reggea*. Take it as a caution to be careful with curating your bad word lists!
|
||||
|
||||
### Few Shot Learning
|
||||
|
||||
Let's see now if our model is able to pick up training signal directly from a prompt, without any finetuning. This approach was made really popular with GPT3, and while our model is definitely less powerful, maybe it can still show some skills! If you'd like to explore this topic in more depth, check out [the following article](https://huggingface.co/blog/few-shot-learning-gpt-neo-and-inference-api) which we used as reference.
|
||||
|
||||
```python
|
||||
prompt = """Tekst: "Nienawidzę smerfów!"
|
||||
Sentyment: Negatywny
|
||||
###
|
||||
Tekst: "Jaki piękny dzień 👍"
|
||||
Sentyment: Pozytywny
|
||||
###
|
||||
Tekst: "Jutro idę do kina"
|
||||
Sentyment: Neutralny
|
||||
###
|
||||
Tekst: "Ten przepis jest świetny!"
|
||||
Sentyment:"""
|
||||
|
||||
res = generator(prompt, max_length=85, temperature=0.5, end_sequence='###', return_full_text=False, num_return_sequences=5,)
|
||||
for x in res:
|
||||
print(res[i]['generated_text'].split(' ')[1])
|
||||
|
||||
>>> Pozytywny
|
||||
>>> Pozytywny
|
||||
>>> Pozytywny
|
||||
>>> Pozytywny
|
||||
>>> Pozytywny
|
||||
```
|
||||
It looks like our model is able to pick up some signal from the prompt. Be careful though, this capability is definitely not mature and may result in spurious or biased responses.
|
||||
|
||||
### Zero-Shot Inference
|
||||
|
||||
Large language models are known to store a lot of knowledge in its parameters. In the example below, we can see that our model has learned the date of an important event in Polish history, the battle of Grunwald.
|
||||
|
||||
```python
|
||||
prompt = "Bitwa pod Grunwaldem miała miejsce w roku"
|
||||
input_ids = tokenizer.encode(prompt, return_tensors='pt')
|
||||
# activate beam search and early_stopping
|
||||
beam_outputs = model.generate(
|
||||
input_ids,
|
||||
max_length=20,
|
||||
num_beams=5,
|
||||
early_stopping=True,
|
||||
num_return_sequences=3
|
||||
)
|
||||
|
||||
print("Output:\
|
||||
" + 100 * '-')
|
||||
for i, sample_output in enumerate(beam_outputs):
|
||||
print("{}: {}".format(i, tokenizer.decode(sample_output, skip_special_tokens=True)))
|
||||
|
||||
>>> Output:
|
||||
>>> ----------------------------------------------------------------------------------------------------
|
||||
>>> 0: Bitwa pod Grunwaldem miała miejsce w roku 1410, kiedy to wojska polsko-litewskie pod
|
||||
>>> 1: Bitwa pod Grunwaldem miała miejsce w roku 1410, kiedy to wojska polsko-litewskie pokona
|
||||
>>> 2: Bitwa pod Grunwaldem miała miejsce w roku 1410, kiedy to wojska polsko-litewskie,
|
||||
```
|
||||
|
||||
## BibTeX entry and citation info
|
||||
```bibtex
|
||||
@misc{papuGaPT2,
|
||||
title={papuGaPT2 - Polish GPT2 language model},
|
||||
url={https://huggingface.co/flax-community/papuGaPT2},
|
||||
author={Wojczulis, Michał and Kłeczek, Dariusz},
|
||||
year={2021}
|
||||
}
|
||||
```
|
||||
1
added_tokens.json
Normal file
1
added_tokens.json
Normal file
@@ -0,0 +1 @@
|
||||
{"<|endoftext|>": 50256}
|
||||
36
allegro_reviews/config.json
Normal file
36
allegro_reviews/config.json
Normal file
@@ -0,0 +1,36 @@
|
||||
{
|
||||
"activation_function": "gelu_new",
|
||||
"architectures": [
|
||||
"GPT2LMHeadModel"
|
||||
],
|
||||
"attn_pdrop": 0.0,
|
||||
"bos_token_id": 50256,
|
||||
"embd_pdrop": 0.0,
|
||||
"eos_token_id": 50256,
|
||||
"gradient_checkpointing": false,
|
||||
"initializer_range": 0.02,
|
||||
"layer_norm_epsilon": 1e-05,
|
||||
"model_type": "gpt2",
|
||||
"n_ctx": 1024,
|
||||
"n_embd": 768,
|
||||
"n_head": 12,
|
||||
"n_inner": null,
|
||||
"n_layer": 12,
|
||||
"n_positions": 1024,
|
||||
"resid_pdrop": 0.0,
|
||||
"scale_attn_weights": true,
|
||||
"summary_activation": null,
|
||||
"summary_first_dropout": 0.1,
|
||||
"summary_proj_to_labels": true,
|
||||
"summary_type": "cls_index",
|
||||
"summary_use_proj": true,
|
||||
"task_specific_params": {
|
||||
"text-generation": {
|
||||
"do_sample": true,
|
||||
"max_length": 50
|
||||
}
|
||||
},
|
||||
"transformers_version": "4.9.0.dev0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 50257
|
||||
}
|
||||
6
allegro_reviews/create_config_allegro.py
Executable file
6
allegro_reviews/create_config_allegro.py
Executable file
@@ -0,0 +1,6 @@
|
||||
from transformers import GPT2Config
|
||||
|
||||
model_dir = "." # ${MODEL_DIR}
|
||||
|
||||
config = GPT2Config.from_pretrained("gpt2", resid_pdrop=0.0, embd_pdrop=0.0, attn_pdrop=0.0)
|
||||
config.save_pretrained(model_dir)
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:25a5b7d6e069647cf953e1684211cf4b87049ae4e05610e37b1047966bd36fcc
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ee76cbdc38f6bec33ee28c5225264d95b8d46c0a2941ce59fbe8893f798a3de8
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d20520f97baa97ebd08bbf9f66afb294613261a1661dbd9bf18ca39b4258e03d
|
||||
size 40
|
||||
1
allegro_reviews/tokenizer.json
Normal file
1
allegro_reviews/tokenizer.json
Normal file
File diff suppressed because one or more lines are too long
26
allegro_reviews/train_tokenizer_allegro.py
Executable file
26
allegro_reviews/train_tokenizer_allegro.py
Executable file
@@ -0,0 +1,26 @@
|
||||
from datasets import load_dataset
|
||||
from tokenizers import trainers, Tokenizer, normalizers, ByteLevelBPETokenizer
|
||||
|
||||
model_dir = "." # ${MODEL_DIR}
|
||||
|
||||
# load dataset
|
||||
dataset = load_dataset("allegro_reviews", split="train")
|
||||
|
||||
# Instantiate tokenizer
|
||||
tokenizer = ByteLevelBPETokenizer()
|
||||
|
||||
def batch_iterator(batch_size=1000):
|
||||
for i in range(0, len(dataset), batch_size):
|
||||
yield dataset[i: i + batch_size]["text"]
|
||||
|
||||
# Customized training
|
||||
tokenizer.train_from_iterator(batch_iterator(), vocab_size=50265, min_frequency=2, special_tokens=[
|
||||
"<s>",
|
||||
"<pad>",
|
||||
"</s>",
|
||||
"<unk>",
|
||||
"<mask>",
|
||||
])
|
||||
|
||||
# Save files to disk
|
||||
tokenizer.save(f"{model_dir}/tokenizer.json")
|
||||
38
ckpt-7000/config.json
Normal file
38
ckpt-7000/config.json
Normal file
@@ -0,0 +1,38 @@
|
||||
{
|
||||
"_name_or_path": "./",
|
||||
"activation_function": "gelu_new",
|
||||
"architectures": [
|
||||
"GPT2LMHeadModel"
|
||||
],
|
||||
"attn_pdrop": 0.0,
|
||||
"bos_token_id": 50256,
|
||||
"embd_pdrop": 0.0,
|
||||
"eos_token_id": 50256,
|
||||
"gradient_checkpointing": false,
|
||||
"initializer_range": 0.02,
|
||||
"layer_norm_epsilon": 1e-05,
|
||||
"model_type": "gpt2",
|
||||
"n_ctx": 1024,
|
||||
"n_embd": 768,
|
||||
"n_head": 12,
|
||||
"n_inner": null,
|
||||
"n_layer": 12,
|
||||
"n_positions": 1024,
|
||||
"resid_pdrop": 0.0,
|
||||
"scale_attn_weights": true,
|
||||
"summary_activation": null,
|
||||
"summary_first_dropout": 0.1,
|
||||
"summary_proj_to_labels": true,
|
||||
"summary_type": "cls_index",
|
||||
"summary_use_proj": true,
|
||||
"task_specific_params": {
|
||||
"text-generation": {
|
||||
"do_sample": true,
|
||||
"max_length": 50
|
||||
}
|
||||
},
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": "4.9.0.dev0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 50257
|
||||
}
|
||||
3
ckpt-7000/flax_model.msgpack
Normal file
3
ckpt-7000/flax_model.msgpack
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d426922657592daf71b1b3b88dc9099cde4696dd4bc9b73556888b869decb784
|
||||
size 497764120
|
||||
3
ckpt-7000/opt_state.msgpack
Normal file
3
ckpt-7000/opt_state.msgpack
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:186303788c88a7a93fdbcd9f97729a9041ebc27bcae5d66f5a60efd41c249912
|
||||
size 995528480
|
||||
1
ckpt-7000/training_state.json
Normal file
1
ckpt-7000/training_state.json
Normal file
@@ -0,0 +1 @@
|
||||
{"step": 7001}
|
||||
38
config.json
Executable file
38
config.json
Executable file
@@ -0,0 +1,38 @@
|
||||
{
|
||||
"_name_or_path": "./",
|
||||
"activation_function": "gelu_new",
|
||||
"architectures": [
|
||||
"GPT2LMHeadModel"
|
||||
],
|
||||
"attn_pdrop": 0.0,
|
||||
"bos_token_id": 50256,
|
||||
"embd_pdrop": 0.0,
|
||||
"eos_token_id": 50256,
|
||||
"gradient_checkpointing": false,
|
||||
"initializer_range": 0.02,
|
||||
"layer_norm_epsilon": 1e-05,
|
||||
"model_type": "gpt2",
|
||||
"n_ctx": 1024,
|
||||
"n_embd": 768,
|
||||
"n_head": 12,
|
||||
"n_inner": null,
|
||||
"n_layer": 12,
|
||||
"n_positions": 1024,
|
||||
"resid_pdrop": 0.0,
|
||||
"scale_attn_weights": true,
|
||||
"summary_activation": null,
|
||||
"summary_first_dropout": 0.1,
|
||||
"summary_proj_to_labels": true,
|
||||
"summary_type": "cls_index",
|
||||
"summary_use_proj": true,
|
||||
"task_specific_params": {
|
||||
"text-generation": {
|
||||
"do_sample": true,
|
||||
"max_length": 50
|
||||
}
|
||||
},
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": "4.9.0.dev0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 50257
|
||||
}
|
||||
5
convert_to_pytorch.py
Executable file
5
convert_to_pytorch.py
Executable file
@@ -0,0 +1,5 @@
|
||||
#!/usr/bin/env python3
|
||||
from transformers import GPT2LMHeadModel
|
||||
|
||||
model = GPT2LMHeadModel.from_pretrained("./", from_flax=True)
|
||||
model.save_pretrained("./")
|
||||
6
create_config.py
Executable file
6
create_config.py
Executable file
@@ -0,0 +1,6 @@
|
||||
from transformers import GPT2Config
|
||||
|
||||
model_dir = "." # ${MODEL_DIR}
|
||||
|
||||
config = GPT2Config.from_pretrained("gpt2", resid_pdrop=0.0, embd_pdrop=0.0, attn_pdrop=0.0)
|
||||
config.save_pretrained(model_dir)
|
||||
3
events.out.tfevents.1625408122.t1v-n-5d840006-w-0.4909.3.v2
Executable file
3
events.out.tfevents.1625408122.t1v-n-5d840006-w-0.4909.3.v2
Executable file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a4f3d64a34ca00c3be72105da0664557fff01b50fc812802428144cebca87b35
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:4f8ebd5f1ae292f7e94936111697f725be49810a334c1913a7d4fa8520b588dc
|
||||
size 61182
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:1d4bb7621dd88a65736f55b305b26ebe509542fe9d277208ecf7b196c30b9a38
|
||||
size 281684
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:973ce04e1a3c163e06174b81a01067ea2564aae7d7d23128f83236e096dcde6b
|
||||
size 447251
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:f1e4f47367e373d6e85d822a0489901f7914fdb74f55226fdf9660e27d7dbb70
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:145110e582bd6ffa469bd70a6994e8fb7607eef00b32bac499277125e0c76f08
|
||||
size 147065
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:33764cac9e2b30a832ce9801b7a442440556a8ffd4944e94b65c8499dda6b5c9
|
||||
size 147065
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b63c776e86a45848fc976c6ac2978493911c7582801e84fb8741d7d54b54c789
|
||||
size 9512225
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a4a9d6cc813f0ab93d9a607b4959ad92e69e211feae5dd0ea6541ae546e5fe99
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d018c6ab315bf844d970f72e79fc335650adcdaf67093c5079fa6f802ccb2198
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:0b27d199598f0cda4401d0990d1ea9ce3aef0865c8ce08b57a9f2f3c4ed4c780
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:51252162ec50163993bc7c712a4c9f79bb20e036bbca188cbec4181d2a33b0ee
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8d5b8a36445ca8ac2e698b10725deca9add93bc732622d141b9a4ed5c2a8d945
|
||||
size 17423021
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9553b7cf078fa9afe1364d9edd4c482ae47089c72d79438382efd71e1c7e1d80
|
||||
size 220906
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d05f73015c7d3fcef29fa5a3783fa71061e8f9058326d44181aab1e9499818f5
|
||||
size 180
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:7348cd7908eedb0f28fad1858fca9100d72f314ffdab2df7d5ddb14612d54910
|
||||
size 180
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c4da6dbdd6b6875786a92d3c57d533a99ffb94a070dde23c30df16140b8bcab8
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:706b0e4a11361ad090a5255c0cbdb33fcb9acadfac53218442717c938279aefa
|
||||
size 1029349
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:7492648e3b1447fcf7d888343ff46e01fd3e13bd509d7bc9edc3ae9e8d12ced3
|
||||
size 514496
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:295d632404865620140afe6b59ae69790e38090faddf0b8f823322037d68814f
|
||||
size 8313281
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:18a9e63d81d2a4da3bbf9ce3622d6024691dc0ffe3e427bb28f64fe070157d69
|
||||
size 40
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:76f4ca950c81e17eba462c306a30d8375b137702fdff33d20af833fbf2cd9842
|
||||
size 1029207
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8382ca0e5eb6ced66cf9c2aa3c00157ef0f8bd8c199e15bbddde539a14789a71
|
||||
size 11443277
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ed5103f11503f393b5bb5609f2052a4e4cd95a06b500a2f1e7eaa5d86235a741
|
||||
size 13529845
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ce17d9c1158c87ad9958e3c38db67cfecef07098f86568962a1456c33417bba3
|
||||
size 13529845
|
||||
3
flax_model.msgpack
Normal file
3
flax_model.msgpack
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8bdc00b2ca54a7c2a6d99e950fcb45f81ccdfc20652a6d5020643a9bc37ff77d
|
||||
size 497764120
|
||||
BIN
gender_bias.jpeg
Normal file
BIN
gender_bias.jpeg
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 71 KiB |
BIN
hate_by_ethnicity.png
Normal file
BIN
hate_by_ethnicity.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 19 KiB |
BIN
hate_by_gender.png
Normal file
BIN
hate_by_gender.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 11 KiB |
49996
merges.txt
Normal file
49996
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
4067
papuGaPT2_bias_analysis.ipynb
Normal file
4067
papuGaPT2_bias_analysis.ipynb
Normal file
File diff suppressed because one or more lines are too long
1051
papuGaPT2_text_generation.ipynb
Normal file
1051
papuGaPT2_text_generation.ipynb
Normal file
File diff suppressed because it is too large
Load Diff
21
pretrain_model.sh
Executable file
21
pretrain_model.sh
Executable file
@@ -0,0 +1,21 @@
|
||||
./run_clm_flax.py \
|
||||
--output_dir="." \
|
||||
--model_type="gpt2" \
|
||||
--config_name="." \
|
||||
--tokenizer_name="." \
|
||||
--dataset_name="oscar" \
|
||||
--dataset_config_name="unshuffled_deduplicated_pl" \
|
||||
--do_train --do_eval \
|
||||
--block_size="512" \
|
||||
--per_device_train_batch_size="64" \
|
||||
--per_device_eval_batch_size="64" \
|
||||
--learning_rate="2e-4" --warmup_steps="5000" \
|
||||
--adam_beta1="0.9" --adam_beta2="0.98" --weight_decay="0.01" \
|
||||
--overwrite_output_dir \
|
||||
--num_train_epochs="3" \
|
||||
--logging_steps="3500" \
|
||||
--preprocessing_num_workers="64" \
|
||||
--save_steps="7000" \
|
||||
--eval_steps="7000" \
|
||||
--model_name_or_path="." \
|
||||
--push_to_hub \
|
||||
17
pretrain_model_SAMPLE.sh
Executable file
17
pretrain_model_SAMPLE.sh
Executable file
@@ -0,0 +1,17 @@
|
||||
${MODEL_DIR}/run_clm_flax_SAMPLE.py \
|
||||
--output_dir="${MODEL_DIR}" \
|
||||
--model_type="gpt2" \
|
||||
--config_name="${MODEL_DIR}" \
|
||||
--tokenizer_name="${MODEL_DIR}" \
|
||||
--dataset_name="oscar" \
|
||||
--dataset_config_name="unshuffled_deduplicated_pl" \
|
||||
--do_train --do_eval \
|
||||
--block_size="512" \
|
||||
--per_device_train_batch_size="64" \
|
||||
--per_device_eval_batch_size="64" \
|
||||
--learning_rate="5e-3" --warmup_steps="1000" \
|
||||
--adam_beta1="0.9" --adam_beta2="0.98" --weight_decay="0.01" \
|
||||
--overwrite_output_dir \
|
||||
--num_train_epochs="20" \
|
||||
--push_to_hub \
|
||||
--preprocessing_num_workers="64"
|
||||
3
pytorch_model.bin
Normal file
3
pytorch_model.bin
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c921560740828d2211e2a904ff819de42f5029e4ae9026d75fb0fe6d15c5ac45
|
||||
size 510401385
|
||||
640
run_clm_flax.py
Executable file
640
run_clm_flax.py
Executable file
@@ -0,0 +1,640 @@
|
||||
#!/usr/bin/env python
|
||||
# coding=utf-8
|
||||
# Copyright 2021 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
|
||||
|
||||
Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
|
||||
https://huggingface.co/models?filter=causal-lm
|
||||
"""
|
||||
# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import Callable, Optional
|
||||
|
||||
import datasets
|
||||
from datasets import Dataset, load_dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
import jax
|
||||
import jax.numpy as jnp
|
||||
import optax
|
||||
import transformers
|
||||
from flax import jax_utils, traverse_util
|
||||
from flax.jax_utils import unreplicate
|
||||
from flax.training import train_state
|
||||
from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
|
||||
from transformers import (
|
||||
CONFIG_MAPPING,
|
||||
FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
|
||||
AutoConfig,
|
||||
AutoTokenizer,
|
||||
FlaxAutoModelForCausalLM,
|
||||
HfArgumentParser,
|
||||
TrainingArguments,
|
||||
is_tensorboard_available,
|
||||
)
|
||||
from transformers.testing_utils import CaptureLogger
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
|
||||
MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
|
||||
"""
|
||||
|
||||
model_name_or_path: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "The model checkpoint for weights initialization."
|
||||
"Don't set if you want to train a model from scratch."
|
||||
},
|
||||
)
|
||||
model_type: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
use_fast_tokenizer: bool = field(
|
||||
default=True,
|
||||
metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
|
||||
)
|
||||
dtype: Optional[str] = field(
|
||||
default="float32",
|
||||
metadata={
|
||||
"help": "Floating-point format in which the model weights should be initialized and trained. Choose one of `[float32, float16, bfloat16]`."
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
|
||||
)
|
||||
max_train_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of training examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
max_eval_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
validation_split_percentage: Optional[int] = field(
|
||||
default=5,
|
||||
metadata={
|
||||
"help": "The percentage of the train set used as validation set in case there's no validation split"
|
||||
},
|
||||
)
|
||||
block_size: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "Optional input sequence length after tokenization. "
|
||||
"The training dataset will be truncated in block of this size for training. "
|
||||
"Default to the model max input length for single sentence inputs (take into account special tokens)."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
|
||||
|
||||
|
||||
class TrainState(train_state.TrainState):
|
||||
dropout_rng: jnp.ndarray
|
||||
|
||||
def replicate(self):
|
||||
return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
|
||||
|
||||
|
||||
def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
|
||||
"""
|
||||
Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
|
||||
Shuffle batches if `shuffle` is `True`.
|
||||
"""
|
||||
steps_per_epoch = len(dataset) // batch_size
|
||||
|
||||
if shuffle:
|
||||
batch_idx = jax.random.permutation(rng, len(dataset))
|
||||
else:
|
||||
batch_idx = jnp.arange(len(dataset))
|
||||
|
||||
batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
|
||||
batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
|
||||
|
||||
for idx in batch_idx:
|
||||
batch = dataset[idx]
|
||||
batch = {k: jnp.array(v) for k, v in batch.items()}
|
||||
|
||||
batch = shard(batch)
|
||||
|
||||
yield batch
|
||||
|
||||
|
||||
def write_train_metric(summary_writer, train_metrics, train_time, step):
|
||||
summary_writer.scalar("train_time", train_time, step)
|
||||
|
||||
train_metrics = get_metrics(train_metrics)
|
||||
for key, vals in train_metrics.items():
|
||||
tag = f"train_{key}"
|
||||
for i, val in enumerate(vals):
|
||||
summary_writer.scalar(tag, val, step - len(vals) + i + 1)
|
||||
|
||||
|
||||
def write_eval_metric(summary_writer, eval_metrics, step):
|
||||
for metric_name, value in eval_metrics.items():
|
||||
summary_writer.scalar(f"eval_{metric_name}", value, step)
|
||||
|
||||
|
||||
def create_learning_rate_fn(
|
||||
train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
|
||||
) -> Callable[[int], jnp.array]:
|
||||
"""Returns a linear warmup, linear_decay learning rate function."""
|
||||
steps_per_epoch = train_ds_size // train_batch_size
|
||||
num_train_steps = steps_per_epoch * num_train_epochs
|
||||
warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
|
||||
decay_fn = optax.linear_schedule(
|
||||
init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
|
||||
)
|
||||
schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
|
||||
return schedule_fn
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Make one log on every process with the configuration for debugging.
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO,
|
||||
)
|
||||
# Setup logging, we only want one process per machine to log things on the screen.
|
||||
logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
|
||||
if jax.process_index() == 0:
|
||||
datasets.utils.logging.set_verbosity_warning()
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
else:
|
||||
datasets.utils.logging.set_verbosity_error()
|
||||
transformers.utils.logging.set_verbosity_error()
|
||||
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
logger.info(f"Training/evaluation parameters {training_args}")
|
||||
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantees that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
dataset = load_dataset(
|
||||
data_args.dataset_name, data_args.dataset_config_name, cache_dir=model_args.cache_dir, keep_in_memory=False
|
||||
)
|
||||
|
||||
if "validation" not in dataset.keys():
|
||||
dataset["validation"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[:{data_args.validation_split_percentage}%]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
dataset["train"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[{data_args.validation_split_percentage}%:]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
dataset = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
if model_args.config_name:
|
||||
config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
|
||||
elif model_args.model_name_or_path:
|
||||
config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
|
||||
else:
|
||||
config = CONFIG_MAPPING[model_args.model_type]()
|
||||
logger.warning("You are instantiating a new config instance from scratch.")
|
||||
|
||||
if model_args.tokenizer_name:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
elif model_args.model_name_or_path:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"You are instantiating a new tokenizer from scratch. This is not supported by this script."
|
||||
"You can do it from another script, save it, and load it from here, using --tokenizer_name."
|
||||
)
|
||||
|
||||
if model_args.model_name_or_path:
|
||||
model = FlaxAutoModelForCausalLM.from_pretrained(
|
||||
model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
else:
|
||||
model = FlaxAutoModelForCausalLM.from_config(
|
||||
config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
|
||||
# Preprocessing the datasets.
|
||||
# First we tokenize all the texts.
|
||||
if training_args.do_train:
|
||||
column_names = dataset["train"].column_names
|
||||
else:
|
||||
column_names = dataset["validation"].column_names
|
||||
text_column_name = "text" if "text" in column_names else column_names[0]
|
||||
|
||||
# since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
|
||||
tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
|
||||
|
||||
def tokenize_function(examples):
|
||||
with CaptureLogger(tok_logger) as cl:
|
||||
output = tokenizer(examples[text_column_name])
|
||||
# clm input could be much much longer than block_size
|
||||
if "Token indices sequence length is longer than the" in cl.out:
|
||||
tok_logger.warning(
|
||||
"^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits before being passed to the model."
|
||||
)
|
||||
return output
|
||||
|
||||
tokenized_datasets = dataset.map(
|
||||
tokenize_function,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
remove_columns=column_names,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if data_args.block_size is None:
|
||||
block_size = tokenizer.model_max_length
|
||||
if block_size > config.max_position_embeddings:
|
||||
logger.warning(
|
||||
f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
|
||||
"Picking 1024 instead. You can change that default value by passing --block_size xxx."
|
||||
)
|
||||
block_size = 1024
|
||||
else:
|
||||
if data_args.block_size > tokenizer.model_max_length:
|
||||
logger.warning(
|
||||
f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model"
|
||||
f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
|
||||
)
|
||||
block_size = min(data_args.block_size, tokenizer.model_max_length)
|
||||
|
||||
# Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
|
||||
def group_texts(examples):
|
||||
# Concatenate all texts.
|
||||
concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
||||
total_length = len(concatenated_examples[list(examples.keys())[0]])
|
||||
# We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
||||
# customize this part to your needs.
|
||||
if total_length >= block_size:
|
||||
total_length = (total_length // block_size) * block_size
|
||||
# Split by chunks of max_len.
|
||||
result = {
|
||||
k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
||||
for k, t in concatenated_examples.items()
|
||||
}
|
||||
result["labels"] = result["input_ids"].copy()
|
||||
return result
|
||||
|
||||
# Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
|
||||
# for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
|
||||
# to preprocess.
|
||||
#
|
||||
# To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
|
||||
# https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
|
||||
|
||||
lm_datasets = tokenized_datasets.map(
|
||||
group_texts,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if training_args.do_train:
|
||||
if "train" not in tokenized_datasets:
|
||||
raise ValueError("--do_train requires a train dataset")
|
||||
train_dataset = lm_datasets["train"]
|
||||
if data_args.max_train_samples is not None:
|
||||
train_dataset = train_dataset.select(range(data_args.max_train_samples))
|
||||
|
||||
if training_args.do_eval:
|
||||
if "validation" not in tokenized_datasets:
|
||||
raise ValueError("--do_eval requires a validation dataset")
|
||||
eval_dataset = lm_datasets["validation"]
|
||||
if data_args.max_eval_samples is not None:
|
||||
eval_dataset = eval_dataset.select(range(data_args.max_eval_samples))
|
||||
|
||||
# Enable tensorboard only on the master node
|
||||
has_tensorboard = is_tensorboard_available()
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
try:
|
||||
from flax.metrics.tensorboard import SummaryWriter
|
||||
|
||||
summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
|
||||
except ImportError as ie:
|
||||
has_tensorboard = False
|
||||
logger.warning(
|
||||
f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
|
||||
)
|
||||
else:
|
||||
logger.warning(
|
||||
"Unable to display metrics through TensorBoard because the package is not installed: "
|
||||
"Please run pip install tensorboard to enable."
|
||||
)
|
||||
|
||||
# Initialize our training
|
||||
rng = jax.random.PRNGKey(training_args.seed)
|
||||
rng, dropout_rng = jax.random.split(rng)
|
||||
|
||||
# Store some constant
|
||||
num_epochs = int(training_args.num_train_epochs)
|
||||
train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
|
||||
eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
total_train_steps = steps_per_epoch * num_epochs
|
||||
|
||||
# Create learning rate schedule
|
||||
linear_decay_lr_schedule_fn = create_learning_rate_fn(
|
||||
len(train_dataset),
|
||||
train_batch_size,
|
||||
training_args.num_train_epochs,
|
||||
training_args.warmup_steps,
|
||||
training_args.learning_rate,
|
||||
)
|
||||
|
||||
# We use Optax's "masking" functionality to not apply weight decay
|
||||
# to bias and LayerNorm scale parameters. decay_mask_fn returns a
|
||||
# mask boolean with the same structure as the parameters.
|
||||
# The mask is True for parameters that should be decayed.
|
||||
# Note that this mask is specifically adapted for FlaxGPT2.
|
||||
# For other models, one should correct the layer norm parameter naming
|
||||
# accordingly.
|
||||
def decay_mask_fn(params):
|
||||
flat_params = traverse_util.flatten_dict(params)
|
||||
flat_mask = {
|
||||
path: (path[-1] != "bias" and path[-2:] not in [("ln_1", "scale"), ("ln_2", "scale"), ("ln_f", "scale")])
|
||||
for path in flat_params
|
||||
}
|
||||
return traverse_util.unflatten_dict(flat_mask)
|
||||
|
||||
# create adam optimizer
|
||||
if training_args.adafactor:
|
||||
# We use the default parameters here to initialize adafactor,
|
||||
# For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
|
||||
optimizer = optax.adafactor(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
)
|
||||
else:
|
||||
optimizer = optax.adamw(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
b1=training_args.adam_beta1,
|
||||
b2=training_args.adam_beta2,
|
||||
eps=training_args.adam_epsilon,
|
||||
weight_decay=training_args.weight_decay,
|
||||
mask=decay_mask_fn,
|
||||
)
|
||||
|
||||
# Setup train state
|
||||
state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer, dropout_rng=dropout_rng)
|
||||
|
||||
def loss_fn(logits, labels):
|
||||
shift_logits = logits[..., :-1, :]
|
||||
shift_labels = labels[..., 1:]
|
||||
loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
|
||||
return loss.mean()
|
||||
|
||||
# Define gradient update step fn
|
||||
def train_step(state, batch):
|
||||
dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
|
||||
|
||||
def compute_loss(params):
|
||||
labels = batch.pop("labels")
|
||||
logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
return loss
|
||||
|
||||
grad_fn = jax.value_and_grad(compute_loss)
|
||||
loss, grad = grad_fn(state.params)
|
||||
grad = jax.lax.pmean(grad, "batch")
|
||||
|
||||
new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
|
||||
|
||||
metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
|
||||
return new_state, metrics
|
||||
|
||||
# Define eval fn
|
||||
def eval_step(params, batch):
|
||||
labels = batch.pop("labels")
|
||||
logits = model(**batch, params=params, train=False)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
|
||||
# summarize metrics
|
||||
metrics = {"loss": loss}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
return metrics
|
||||
|
||||
# Create parallel version of the train and eval step
|
||||
p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
|
||||
p_eval_step = jax.pmap(eval_step, "batch")
|
||||
|
||||
# Replicate the train state on each device
|
||||
state = state.replicate()
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(f" Num examples = {len(train_dataset)}")
|
||||
logger.info(f" Num Epochs = {num_epochs}")
|
||||
logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
|
||||
logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
|
||||
logger.info(f" Total optimization steps = {total_train_steps}")
|
||||
|
||||
train_time = 0
|
||||
train_metrics = []
|
||||
epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
|
||||
for epoch in epochs:
|
||||
# ======================== Training ================================
|
||||
train_start = time.time()
|
||||
|
||||
# Create sampling rng
|
||||
rng, input_rng = jax.random.split(rng)
|
||||
|
||||
# Generate an epoch by shuffling sampling indices from the train dataset
|
||||
train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
# train
|
||||
for step in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
|
||||
batch = next(train_loader)
|
||||
state, train_metric = p_train_step(state, batch)
|
||||
train_metrics.append(train_metric)
|
||||
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size) + step
|
||||
|
||||
if cur_step % training_args.logging_steps == 0 and cur_step > 0:
|
||||
# Save metrics
|
||||
train_metric = unreplicate(train_metric)
|
||||
train_time += time.time() - train_start
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
write_train_metric(summary_writer, train_metrics, train_time, cur_step)
|
||||
|
||||
epochs.write(
|
||||
f"Step... ({cur_step} | Loss: {train_metric['loss'].mean()}, Learning Rate: {train_metric['learning_rate'].mean()})"
|
||||
)
|
||||
|
||||
train_metrics = []
|
||||
|
||||
if cur_step % training_args.eval_steps == 0 and cur_step > 0:
|
||||
# ======================== Evaluating ==============================
|
||||
eval_metrics = []
|
||||
eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size)
|
||||
eval_steps = len(eval_dataset) // eval_batch_size
|
||||
for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
|
||||
# Model forward
|
||||
batch = next(eval_loader)
|
||||
metrics = p_eval_step(state.params, batch)
|
||||
eval_metrics.append(metrics)
|
||||
|
||||
# normalize eval metrics
|
||||
eval_metrics = get_metrics(eval_metrics)
|
||||
eval_metrics = jax.tree_map(jnp.mean, eval_metrics)
|
||||
|
||||
try:
|
||||
eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
|
||||
except OverflowError:
|
||||
eval_metrics["perplexity"] = float("inf")
|
||||
|
||||
# Print metrics and update progress bar
|
||||
desc = f"Step... ({cur_step} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity: {eval_metrics['perplexity']})"
|
||||
epochs.write(desc)
|
||||
epochs.desc = desc
|
||||
|
||||
# Save metrics
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
write_eval_metric(summary_writer, eval_metrics, cur_step)
|
||||
|
||||
if cur_step % training_args.save_steps == 0 and cur_step > 0:
|
||||
# save checkpoint after each epoch and push checkpoint to the hub
|
||||
if jax.process_index() == 0:
|
||||
params = jax.device_get(unreplicate(state.params))
|
||||
model.save_pretrained(
|
||||
training_args.output_dir,
|
||||
params=params,
|
||||
push_to_hub=training_args.push_to_hub,
|
||||
commit_message=f"Saving weights and logs of step {cur_step}",
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
638
run_clm_flax_SAMPLE.py
Executable file
638
run_clm_flax_SAMPLE.py
Executable file
@@ -0,0 +1,638 @@
|
||||
#!/usr/bin/env python
|
||||
# coding=utf-8
|
||||
# Copyright 2021 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
|
||||
|
||||
Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
|
||||
https://huggingface.co/models?filter=causal-lm
|
||||
"""
|
||||
# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import Callable, Optional
|
||||
|
||||
import datasets
|
||||
from datasets import Dataset, load_dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
import jax
|
||||
import jax.numpy as jnp
|
||||
import optax
|
||||
import transformers
|
||||
from flax import jax_utils, traverse_util
|
||||
from flax.jax_utils import unreplicate
|
||||
from flax.training import train_state
|
||||
from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
|
||||
from transformers import (
|
||||
CONFIG_MAPPING,
|
||||
FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
|
||||
AutoConfig,
|
||||
AutoTokenizer,
|
||||
FlaxAutoModelForCausalLM,
|
||||
HfArgumentParser,
|
||||
TrainingArguments,
|
||||
is_tensorboard_available,
|
||||
)
|
||||
from transformers.testing_utils import CaptureLogger
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# Cache the result
|
||||
has_tensorboard = is_tensorboard_available()
|
||||
if has_tensorboard:
|
||||
try:
|
||||
from flax.metrics.tensorboard import SummaryWriter
|
||||
except ImportError as ie:
|
||||
has_tensorboard = False
|
||||
print(f"Unable to display metrics through TensorBoard because some package are not installed: {ie}")
|
||||
|
||||
else:
|
||||
print(
|
||||
"Unable to display metrics through TensorBoard because the package is not installed: "
|
||||
"Please run pip install tensorboard to enable."
|
||||
)
|
||||
|
||||
|
||||
MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
|
||||
MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
|
||||
"""
|
||||
|
||||
model_name_or_path: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "The model checkpoint for weights initialization."
|
||||
"Don't set if you want to train a model from scratch."
|
||||
},
|
||||
)
|
||||
model_type: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
use_fast_tokenizer: bool = field(
|
||||
default=True,
|
||||
metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
|
||||
)
|
||||
dtype: Optional[str] = field(
|
||||
default="float32",
|
||||
metadata={
|
||||
"help": "Floating-point format in which the model weights should be initialized and trained. Choose one of `[float32, float16, bfloat16]`."
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
|
||||
)
|
||||
max_train_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of training examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
max_eval_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
validation_split_percentage: Optional[int] = field(
|
||||
default=5,
|
||||
metadata={
|
||||
"help": "The percentage of the train set used as validation set in case there's no validation split"
|
||||
},
|
||||
)
|
||||
block_size: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "Optional input sequence length after tokenization. "
|
||||
"The training dataset will be truncated in block of this size for training. "
|
||||
"Default to the model max input length for single sentence inputs (take into account special tokens)."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
|
||||
|
||||
|
||||
class TrainState(train_state.TrainState):
|
||||
dropout_rng: jnp.ndarray
|
||||
|
||||
def replicate(self):
|
||||
return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
|
||||
|
||||
|
||||
def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
|
||||
"""
|
||||
Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
|
||||
Shuffle batches if `shuffle` is `True`.
|
||||
"""
|
||||
steps_per_epoch = len(dataset) // batch_size
|
||||
|
||||
if shuffle:
|
||||
batch_idx = jax.random.permutation(rng, len(dataset))
|
||||
else:
|
||||
batch_idx = jnp.arange(len(dataset))
|
||||
|
||||
batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
|
||||
batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
|
||||
|
||||
for idx in batch_idx:
|
||||
batch = dataset[idx]
|
||||
batch = {k: jnp.array(v) for k, v in batch.items()}
|
||||
|
||||
batch = shard(batch)
|
||||
|
||||
yield batch
|
||||
|
||||
|
||||
def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
|
||||
summary_writer.scalar("train_time", train_time, step)
|
||||
|
||||
train_metrics = get_metrics(train_metrics)
|
||||
for key, vals in train_metrics.items():
|
||||
tag = f"train_{key}"
|
||||
for i, val in enumerate(vals):
|
||||
summary_writer.scalar(tag, val, step - len(vals) + i + 1)
|
||||
|
||||
for metric_name, value in eval_metrics.items():
|
||||
summary_writer.scalar(f"eval_{metric_name}", value, step)
|
||||
|
||||
|
||||
def create_learning_rate_fn(
|
||||
train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
|
||||
) -> Callable[[int], jnp.array]:
|
||||
"""Returns a linear warmup, linear_decay learning rate function."""
|
||||
steps_per_epoch = train_ds_size // train_batch_size
|
||||
num_train_steps = steps_per_epoch * num_train_epochs
|
||||
warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
|
||||
decay_fn = optax.linear_schedule(
|
||||
init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
|
||||
)
|
||||
schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
|
||||
return schedule_fn
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Make one log on every process with the configuration for debugging.
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO,
|
||||
)
|
||||
# Setup logging, we only want one process per machine to log things on the screen.
|
||||
logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
|
||||
if jax.process_index() == 0:
|
||||
datasets.utils.logging.set_verbosity_warning()
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
else:
|
||||
datasets.utils.logging.set_verbosity_error()
|
||||
transformers.utils.logging.set_verbosity_error()
|
||||
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
logger.info(f"Training/evaluation parameters {training_args}")
|
||||
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantees that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
dataset = load_dataset(
|
||||
data_args.dataset_name, data_args.dataset_config_name, cache_dir=model_args.cache_dir, keep_in_memory=False
|
||||
)
|
||||
|
||||
dataset["validation"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[:1%]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
dataset["train"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[99%:]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
|
||||
# if "validation" not in dataset.keys():
|
||||
# dataset["validation"] = load_dataset(
|
||||
# data_args.dataset_name,
|
||||
# data_args.dataset_config_name,
|
||||
# split=f"train[:{data_args.validation_split_percentage}%]",
|
||||
# cache_dir=model_args.cache_dir,
|
||||
# )
|
||||
# dataset["train"] = load_dataset(
|
||||
# data_args.dataset_name,
|
||||
# data_args.dataset_config_name,
|
||||
# split=f"train[{data_args.validation_split_percentage}%:]",
|
||||
# cache_dir=model_args.cache_dir,
|
||||
# )
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
dataset = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
if model_args.config_name:
|
||||
config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
|
||||
elif model_args.model_name_or_path:
|
||||
config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
|
||||
else:
|
||||
config = CONFIG_MAPPING[model_args.model_type]()
|
||||
logger.warning("You are instantiating a new config instance from scratch.")
|
||||
|
||||
if model_args.tokenizer_name:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
elif model_args.model_name_or_path:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"You are instantiating a new tokenizer from scratch. This is not supported by this script."
|
||||
"You can do it from another script, save it, and load it from here, using --tokenizer_name."
|
||||
)
|
||||
|
||||
if model_args.model_name_or_path:
|
||||
model = FlaxAutoModelForCausalLM.from_pretrained(
|
||||
model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
else:
|
||||
model = FlaxAutoModelForCausalLM.from_config(
|
||||
config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
|
||||
# Preprocessing the datasets.
|
||||
# First we tokenize all the texts.
|
||||
if training_args.do_train:
|
||||
column_names = dataset["train"].column_names
|
||||
else:
|
||||
column_names = dataset["validation"].column_names
|
||||
text_column_name = "text" if "text" in column_names else column_names[0]
|
||||
|
||||
# since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
|
||||
tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
|
||||
|
||||
def tokenize_function(examples):
|
||||
with CaptureLogger(tok_logger) as cl:
|
||||
output = tokenizer(examples[text_column_name])
|
||||
# clm input could be much much longer than block_size
|
||||
if "Token indices sequence length is longer than the" in cl.out:
|
||||
tok_logger.warning(
|
||||
"^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits before being passed to the model."
|
||||
)
|
||||
return output
|
||||
|
||||
tokenized_datasets = dataset.map(
|
||||
tokenize_function,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
remove_columns=column_names,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if data_args.block_size is None:
|
||||
block_size = tokenizer.model_max_length
|
||||
if block_size > config.max_position_embeddings:
|
||||
logger.warning(
|
||||
f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
|
||||
"Picking 1024 instead. You can change that default value by passing --block_size xxx."
|
||||
)
|
||||
block_size = 1024
|
||||
else:
|
||||
if data_args.block_size > tokenizer.model_max_length:
|
||||
logger.warning(
|
||||
f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model"
|
||||
f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
|
||||
)
|
||||
block_size = min(data_args.block_size, tokenizer.model_max_length)
|
||||
|
||||
# Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
|
||||
def group_texts(examples):
|
||||
# Concatenate all texts.
|
||||
concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
||||
total_length = len(concatenated_examples[list(examples.keys())[0]])
|
||||
# We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
||||
# customize this part to your needs.
|
||||
total_length = (total_length // block_size) * block_size
|
||||
# Split by chunks of max_len.
|
||||
result = {
|
||||
k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
||||
for k, t in concatenated_examples.items()
|
||||
}
|
||||
result["labels"] = result["input_ids"].copy()
|
||||
return result
|
||||
|
||||
# Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
|
||||
# for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
|
||||
# to preprocess.
|
||||
#
|
||||
# To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
|
||||
# https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
|
||||
|
||||
lm_datasets = tokenized_datasets.map(
|
||||
group_texts,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if training_args.do_train:
|
||||
if "train" not in tokenized_datasets:
|
||||
raise ValueError("--do_train requires a train dataset")
|
||||
train_dataset = lm_datasets["train"]
|
||||
if data_args.max_train_samples is not None:
|
||||
train_dataset = train_dataset.select(range(data_args.max_train_samples))
|
||||
|
||||
if training_args.do_eval:
|
||||
if "validation" not in tokenized_datasets:
|
||||
raise ValueError("--do_eval requires a validation dataset")
|
||||
eval_dataset = lm_datasets["validation"]
|
||||
if data_args.max_eval_samples is not None:
|
||||
eval_dataset = eval_dataset.select(range(data_args.max_eval_samples))
|
||||
|
||||
# Enable tensorboard only on the master node
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
|
||||
|
||||
# Initialize our training
|
||||
rng = jax.random.PRNGKey(training_args.seed)
|
||||
rng, dropout_rng = jax.random.split(rng)
|
||||
|
||||
# Store some constant
|
||||
num_epochs = int(training_args.num_train_epochs)
|
||||
train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
|
||||
eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
total_train_steps = steps_per_epoch * num_epochs
|
||||
|
||||
# Create learning rate schedule
|
||||
linear_decay_lr_schedule_fn = create_learning_rate_fn(
|
||||
len(train_dataset),
|
||||
train_batch_size,
|
||||
training_args.num_train_epochs,
|
||||
training_args.warmup_steps,
|
||||
training_args.learning_rate,
|
||||
)
|
||||
|
||||
# We use Optax's "masking" functionality to not apply weight decay
|
||||
# to bias and LayerNorm scale parameters. decay_mask_fn returns a
|
||||
# mask boolean with the same structure as the parameters.
|
||||
# The mask is True for parameters that should be decayed.
|
||||
# Note that this mask is specifically adapted for FlaxGPT2.
|
||||
# For other models, one should correct the layer norm parameter naming
|
||||
# accordingly.
|
||||
def decay_mask_fn(params):
|
||||
flat_params = traverse_util.flatten_dict(params)
|
||||
flat_mask = {
|
||||
path: (path[-1] != "bias" and path[-2:] not in [("ln_1", "scale"), ("ln_2", "scale"), ("ln_f", "scale")])
|
||||
for path in flat_params
|
||||
}
|
||||
return traverse_util.unflatten_dict(flat_mask)
|
||||
|
||||
# create adam optimizer
|
||||
adamw = optax.adamw(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
b1=training_args.adam_beta1,
|
||||
b2=training_args.adam_beta2,
|
||||
eps=training_args.adam_epsilon,
|
||||
weight_decay=training_args.weight_decay,
|
||||
mask=decay_mask_fn,
|
||||
)
|
||||
|
||||
# Setup train state
|
||||
state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
|
||||
|
||||
def loss_fn(logits, labels):
|
||||
shift_logits = logits[..., :-1, :]
|
||||
shift_labels = labels[..., 1:]
|
||||
loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
|
||||
return loss.mean()
|
||||
|
||||
# Define gradient update step fn
|
||||
def train_step(state, batch):
|
||||
dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
|
||||
|
||||
def compute_loss(params):
|
||||
labels = batch.pop("labels")
|
||||
logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
return loss
|
||||
|
||||
grad_fn = jax.value_and_grad(compute_loss)
|
||||
loss, grad = grad_fn(state.params)
|
||||
grad = jax.lax.pmean(grad, "batch")
|
||||
|
||||
new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
|
||||
|
||||
metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
|
||||
return new_state, metrics
|
||||
|
||||
# Define eval fn
|
||||
def eval_step(params, batch):
|
||||
labels = batch.pop("labels")
|
||||
logits = model(**batch, params=params, train=False)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
|
||||
# summarize metrics
|
||||
metrics = {"loss": loss}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
return metrics
|
||||
|
||||
# Create parallel version of the train and eval step
|
||||
p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
|
||||
p_eval_step = jax.pmap(eval_step, "batch")
|
||||
|
||||
# Replicate the train state on each device
|
||||
state = state.replicate()
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(f" Num examples = {len(train_dataset)}")
|
||||
logger.info(f" Num Epochs = {num_epochs}")
|
||||
logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
|
||||
logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
|
||||
logger.info(f" Total optimization steps = {total_train_steps}")
|
||||
|
||||
train_time = 0
|
||||
epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
|
||||
for epoch in epochs:
|
||||
# ======================== Training ================================
|
||||
train_start = time.time()
|
||||
|
||||
# Create sampling rng
|
||||
rng, input_rng = jax.random.split(rng)
|
||||
train_metrics = []
|
||||
|
||||
# Generate an epoch by shuffling sampling indices from the train dataset
|
||||
train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
# train
|
||||
for _ in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
|
||||
batch = next(train_loader)
|
||||
state, train_metric = p_train_step(state, batch)
|
||||
train_metrics.append(train_metric)
|
||||
|
||||
train_time += time.time() - train_start
|
||||
|
||||
train_metric = unreplicate(train_metric)
|
||||
|
||||
epochs.write(
|
||||
f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate: {train_metric['learning_rate']})"
|
||||
)
|
||||
|
||||
# ======================== Evaluating ==============================
|
||||
eval_metrics = []
|
||||
eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size)
|
||||
eval_steps = len(eval_dataset) // eval_batch_size
|
||||
for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
|
||||
# Model forward
|
||||
batch = next(eval_loader)
|
||||
metrics = p_eval_step(state.params, batch)
|
||||
eval_metrics.append(metrics)
|
||||
|
||||
# normalize eval metrics
|
||||
eval_metrics = get_metrics(eval_metrics)
|
||||
|
||||
eval_metrics = jax.tree_map(jnp.mean, eval_metrics)
|
||||
|
||||
try:
|
||||
eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
|
||||
except OverflowError:
|
||||
eval_metrics["perplexity"] = float("inf")
|
||||
|
||||
# Print metrics and update progress bar
|
||||
desc = f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity: {eval_metrics['perplexity']})"
|
||||
epochs.write(desc)
|
||||
epochs.desc = desc
|
||||
|
||||
# Save metrics
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size)
|
||||
write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
|
||||
|
||||
# save checkpoint after each epoch and push checkpoint to the hub
|
||||
if jax.process_index() == 0:
|
||||
params = jax.device_get(unreplicate(state.params))
|
||||
model.save_pretrained(
|
||||
training_args.output_dir,
|
||||
params=params,
|
||||
push_to_hub=training_args.push_to_hub,
|
||||
commit_message=f"Saving weights and logs of epoch {epoch+1}",
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
625
run_clm_flax_bak.py
Executable file
625
run_clm_flax_bak.py
Executable file
@@ -0,0 +1,625 @@
|
||||
#!/usr/bin/env python
|
||||
# coding=utf-8
|
||||
# Copyright 2021 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
|
||||
|
||||
Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
|
||||
https://huggingface.co/models?filter=causal-lm
|
||||
"""
|
||||
# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import Callable, Optional
|
||||
|
||||
import datasets
|
||||
from datasets import Dataset, load_dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
import jax
|
||||
import jax.numpy as jnp
|
||||
import optax
|
||||
import transformers
|
||||
from flax import jax_utils, traverse_util
|
||||
from flax.jax_utils import unreplicate
|
||||
from flax.training import train_state
|
||||
from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
|
||||
from transformers import (
|
||||
CONFIG_MAPPING,
|
||||
FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
|
||||
AutoConfig,
|
||||
AutoTokenizer,
|
||||
FlaxAutoModelForCausalLM,
|
||||
HfArgumentParser,
|
||||
TrainingArguments,
|
||||
is_tensorboard_available,
|
||||
)
|
||||
from transformers.testing_utils import CaptureLogger
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# Cache the result
|
||||
has_tensorboard = is_tensorboard_available()
|
||||
if has_tensorboard:
|
||||
try:
|
||||
from flax.metrics.tensorboard import SummaryWriter
|
||||
except ImportError as ie:
|
||||
has_tensorboard = False
|
||||
print(f"Unable to display metrics through TensorBoard because some package are not installed: {ie}")
|
||||
|
||||
else:
|
||||
print(
|
||||
"Unable to display metrics through TensorBoard because the package is not installed: "
|
||||
"Please run pip install tensorboard to enable."
|
||||
)
|
||||
|
||||
|
||||
MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
|
||||
MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
|
||||
"""
|
||||
|
||||
model_name_or_path: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "The model checkpoint for weights initialization."
|
||||
"Don't set if you want to train a model from scratch."
|
||||
},
|
||||
)
|
||||
model_type: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
use_fast_tokenizer: bool = field(
|
||||
default=True,
|
||||
metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
|
||||
)
|
||||
dtype: Optional[str] = field(
|
||||
default="float32",
|
||||
metadata={
|
||||
"help": "Floating-point format in which the model weights should be initialized and trained. Choose one of `[float32, float16, bfloat16]`."
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
|
||||
)
|
||||
max_train_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of training examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
max_eval_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
validation_split_percentage: Optional[int] = field(
|
||||
default=5,
|
||||
metadata={
|
||||
"help": "The percentage of the train set used as validation set in case there's no validation split"
|
||||
},
|
||||
)
|
||||
block_size: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "Optional input sequence length after tokenization. "
|
||||
"The training dataset will be truncated in block of this size for training. "
|
||||
"Default to the model max input length for single sentence inputs (take into account special tokens)."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
|
||||
|
||||
|
||||
class TrainState(train_state.TrainState):
|
||||
dropout_rng: jnp.ndarray
|
||||
|
||||
def replicate(self):
|
||||
return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
|
||||
|
||||
|
||||
def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
|
||||
"""
|
||||
Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
|
||||
Shuffle batches if `shuffle` is `True`.
|
||||
"""
|
||||
steps_per_epoch = len(dataset) // batch_size
|
||||
|
||||
if shuffle:
|
||||
batch_idx = jax.random.permutation(rng, len(dataset))
|
||||
else:
|
||||
batch_idx = jnp.arange(len(dataset))
|
||||
|
||||
batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
|
||||
batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
|
||||
|
||||
for idx in batch_idx:
|
||||
batch = dataset[idx]
|
||||
batch = {k: jnp.array(v) for k, v in batch.items()}
|
||||
|
||||
batch = shard(batch)
|
||||
|
||||
yield batch
|
||||
|
||||
|
||||
def write_metric(summary_writer, train_metrics, eval_metrics, train_time, step):
|
||||
summary_writer.scalar("train_time", train_time, step)
|
||||
|
||||
train_metrics = get_metrics(train_metrics)
|
||||
for key, vals in train_metrics.items():
|
||||
tag = f"train_{key}"
|
||||
for i, val in enumerate(vals):
|
||||
summary_writer.scalar(tag, val, step - len(vals) + i + 1)
|
||||
|
||||
for metric_name, value in eval_metrics.items():
|
||||
summary_writer.scalar(f"eval_{metric_name}", value, step)
|
||||
|
||||
|
||||
def create_learning_rate_fn(
|
||||
train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
|
||||
) -> Callable[[int], jnp.array]:
|
||||
"""Returns a linear warmup, linear_decay learning rate function."""
|
||||
steps_per_epoch = train_ds_size // train_batch_size
|
||||
num_train_steps = steps_per_epoch * num_train_epochs
|
||||
warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
|
||||
decay_fn = optax.linear_schedule(
|
||||
init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
|
||||
)
|
||||
schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
|
||||
return schedule_fn
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Make one log on every process with the configuration for debugging.
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO,
|
||||
)
|
||||
# Setup logging, we only want one process per machine to log things on the screen.
|
||||
logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
|
||||
if jax.process_index() == 0:
|
||||
datasets.utils.logging.set_verbosity_warning()
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
else:
|
||||
datasets.utils.logging.set_verbosity_error()
|
||||
transformers.utils.logging.set_verbosity_error()
|
||||
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
logger.info(f"Training/evaluation parameters {training_args}")
|
||||
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantees that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
dataset = load_dataset(
|
||||
data_args.dataset_name, data_args.dataset_config_name, cache_dir=model_args.cache_dir, keep_in_memory=False
|
||||
)
|
||||
|
||||
if "validation" not in dataset.keys():
|
||||
dataset["validation"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[:{data_args.validation_split_percentage}%]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
dataset["train"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[{data_args.validation_split_percentage}%:]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
dataset = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
if model_args.config_name:
|
||||
config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
|
||||
elif model_args.model_name_or_path:
|
||||
config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
|
||||
else:
|
||||
config = CONFIG_MAPPING[model_args.model_type]()
|
||||
logger.warning("You are instantiating a new config instance from scratch.")
|
||||
|
||||
if model_args.tokenizer_name:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
elif model_args.model_name_or_path:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"You are instantiating a new tokenizer from scratch. This is not supported by this script."
|
||||
"You can do it from another script, save it, and load it from here, using --tokenizer_name."
|
||||
)
|
||||
|
||||
if model_args.model_name_or_path:
|
||||
model = FlaxAutoModelForCausalLM.from_pretrained(
|
||||
model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
else:
|
||||
model = FlaxAutoModelForCausalLM.from_config(
|
||||
config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
|
||||
# Preprocessing the datasets.
|
||||
# First we tokenize all the texts.
|
||||
if training_args.do_train:
|
||||
column_names = dataset["train"].column_names
|
||||
else:
|
||||
column_names = dataset["validation"].column_names
|
||||
text_column_name = "text" if "text" in column_names else column_names[0]
|
||||
|
||||
# since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
|
||||
tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
|
||||
|
||||
def tokenize_function(examples):
|
||||
with CaptureLogger(tok_logger) as cl:
|
||||
output = tokenizer(examples[text_column_name])
|
||||
# clm input could be much much longer than block_size
|
||||
if "Token indices sequence length is longer than the" in cl.out:
|
||||
tok_logger.warning(
|
||||
"^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits before being passed to the model."
|
||||
)
|
||||
return output
|
||||
|
||||
tokenized_datasets = dataset.map(
|
||||
tokenize_function,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
remove_columns=column_names,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if data_args.block_size is None:
|
||||
block_size = tokenizer.model_max_length
|
||||
if block_size > config.max_position_embeddings:
|
||||
logger.warning(
|
||||
f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
|
||||
"Picking 1024 instead. You can change that default value by passing --block_size xxx."
|
||||
)
|
||||
block_size = 1024
|
||||
else:
|
||||
if data_args.block_size > tokenizer.model_max_length:
|
||||
logger.warning(
|
||||
f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model"
|
||||
f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
|
||||
)
|
||||
block_size = min(data_args.block_size, tokenizer.model_max_length)
|
||||
|
||||
# Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
|
||||
def group_texts(examples):
|
||||
# Concatenate all texts.
|
||||
concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
||||
total_length = len(concatenated_examples[list(examples.keys())[0]])
|
||||
# We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
||||
# customize this part to your needs.
|
||||
total_length = (total_length // block_size) * block_size
|
||||
# Split by chunks of max_len.
|
||||
result = {
|
||||
k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
||||
for k, t in concatenated_examples.items()
|
||||
}
|
||||
result["labels"] = result["input_ids"].copy()
|
||||
return result
|
||||
|
||||
# Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
|
||||
# for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
|
||||
# to preprocess.
|
||||
#
|
||||
# To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
|
||||
# https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
|
||||
|
||||
lm_datasets = tokenized_datasets.map(
|
||||
group_texts,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if training_args.do_train:
|
||||
if "train" not in tokenized_datasets:
|
||||
raise ValueError("--do_train requires a train dataset")
|
||||
train_dataset = lm_datasets["train"]
|
||||
if data_args.max_train_samples is not None:
|
||||
train_dataset = train_dataset.select(range(data_args.max_train_samples))
|
||||
|
||||
if training_args.do_eval:
|
||||
if "validation" not in tokenized_datasets:
|
||||
raise ValueError("--do_eval requires a validation dataset")
|
||||
eval_dataset = lm_datasets["validation"]
|
||||
if data_args.max_eval_samples is not None:
|
||||
eval_dataset = eval_dataset.select(range(data_args.max_eval_samples))
|
||||
|
||||
# Enable tensorboard only on the master node
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
|
||||
|
||||
# Initialize our training
|
||||
rng = jax.random.PRNGKey(training_args.seed)
|
||||
rng, dropout_rng = jax.random.split(rng)
|
||||
|
||||
# Store some constant
|
||||
num_epochs = int(training_args.num_train_epochs)
|
||||
train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
|
||||
eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
total_train_steps = steps_per_epoch * num_epochs
|
||||
|
||||
# Create learning rate schedule
|
||||
linear_decay_lr_schedule_fn = create_learning_rate_fn(
|
||||
len(train_dataset),
|
||||
train_batch_size,
|
||||
training_args.num_train_epochs,
|
||||
training_args.warmup_steps,
|
||||
training_args.learning_rate,
|
||||
)
|
||||
|
||||
# We use Optax's "masking" functionality to not apply weight decay
|
||||
# to bias and LayerNorm scale parameters. decay_mask_fn returns a
|
||||
# mask boolean with the same structure as the parameters.
|
||||
# The mask is True for parameters that should be decayed.
|
||||
# Note that this mask is specifically adapted for FlaxGPT2.
|
||||
# For other models, one should correct the layer norm parameter naming
|
||||
# accordingly.
|
||||
def decay_mask_fn(params):
|
||||
flat_params = traverse_util.flatten_dict(params)
|
||||
flat_mask = {
|
||||
path: (path[-1] != "bias" and path[-2:] not in [("ln_1", "scale"), ("ln_2", "scale"), ("ln_f", "scale")])
|
||||
for path in flat_params
|
||||
}
|
||||
return traverse_util.unflatten_dict(flat_mask)
|
||||
|
||||
# create adam optimizer
|
||||
adamw = optax.adamw(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
b1=training_args.adam_beta1,
|
||||
b2=training_args.adam_beta2,
|
||||
eps=training_args.adam_epsilon,
|
||||
weight_decay=training_args.weight_decay,
|
||||
mask=decay_mask_fn,
|
||||
)
|
||||
|
||||
# Setup train state
|
||||
state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=adamw, dropout_rng=dropout_rng)
|
||||
|
||||
def loss_fn(logits, labels):
|
||||
shift_logits = logits[..., :-1, :]
|
||||
shift_labels = labels[..., 1:]
|
||||
loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
|
||||
return loss.mean()
|
||||
|
||||
# Define gradient update step fn
|
||||
def train_step(state, batch):
|
||||
dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
|
||||
|
||||
def compute_loss(params):
|
||||
labels = batch.pop("labels")
|
||||
logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
return loss
|
||||
|
||||
grad_fn = jax.value_and_grad(compute_loss)
|
||||
loss, grad = grad_fn(state.params)
|
||||
grad = jax.lax.pmean(grad, "batch")
|
||||
|
||||
new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
|
||||
|
||||
metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
|
||||
return new_state, metrics
|
||||
|
||||
# Define eval fn
|
||||
def eval_step(params, batch):
|
||||
labels = batch.pop("labels")
|
||||
logits = model(**batch, params=params, train=False)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
|
||||
# summarize metrics
|
||||
metrics = {"loss": loss}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
return metrics
|
||||
|
||||
# Create parallel version of the train and eval step
|
||||
p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
|
||||
p_eval_step = jax.pmap(eval_step, "batch")
|
||||
|
||||
# Replicate the train state on each device
|
||||
state = state.replicate()
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(f" Num examples = {len(train_dataset)}")
|
||||
logger.info(f" Num Epochs = {num_epochs}")
|
||||
logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
|
||||
logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
|
||||
logger.info(f" Total optimization steps = {total_train_steps}")
|
||||
|
||||
train_time = 0
|
||||
epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
|
||||
for epoch in epochs:
|
||||
# ======================== Training ================================
|
||||
train_start = time.time()
|
||||
|
||||
# Create sampling rng
|
||||
rng, input_rng = jax.random.split(rng)
|
||||
train_metrics = []
|
||||
|
||||
# Generate an epoch by shuffling sampling indices from the train dataset
|
||||
train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
# train
|
||||
for _ in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
|
||||
batch = next(train_loader)
|
||||
state, train_metric = p_train_step(state, batch)
|
||||
train_metrics.append(train_metric)
|
||||
|
||||
train_time += time.time() - train_start
|
||||
|
||||
train_metric = unreplicate(train_metric)
|
||||
|
||||
epochs.write(
|
||||
f"Epoch... ({epoch + 1}/{num_epochs} | Loss: {train_metric['loss']}, Learning Rate: {train_metric['learning_rate']})"
|
||||
)
|
||||
|
||||
# ======================== Evaluating ==============================
|
||||
eval_metrics = []
|
||||
eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size)
|
||||
eval_steps = len(eval_dataset) // eval_batch_size
|
||||
for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
|
||||
# Model forward
|
||||
batch = next(eval_loader)
|
||||
metrics = p_eval_step(state.params, batch)
|
||||
eval_metrics.append(metrics)
|
||||
|
||||
# normalize eval metrics
|
||||
eval_metrics = get_metrics(eval_metrics)
|
||||
|
||||
eval_metrics = jax.tree_map(jnp.mean, eval_metrics)
|
||||
|
||||
try:
|
||||
eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
|
||||
except OverflowError:
|
||||
eval_metrics["perplexity"] = float("inf")
|
||||
|
||||
# Print metrics and update progress bar
|
||||
desc = f"Epoch... ({epoch + 1}/{num_epochs} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity: {eval_metrics['perplexity']})"
|
||||
epochs.write(desc)
|
||||
epochs.desc = desc
|
||||
|
||||
# Save metrics
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size)
|
||||
write_metric(summary_writer, train_metrics, eval_metrics, train_time, cur_step)
|
||||
|
||||
# save checkpoint after each epoch and push checkpoint to the hub
|
||||
if jax.process_index() == 0:
|
||||
params = jax.device_get(unreplicate(state.params))
|
||||
model.save_pretrained(
|
||||
training_args.output_dir,
|
||||
params=params,
|
||||
push_to_hub=training_args.push_to_hub,
|
||||
commit_message=f"Saving weights and logs of epoch {epoch+1}",
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
640
run_clm_flax_bak1.py
Executable file
640
run_clm_flax_bak1.py
Executable file
@@ -0,0 +1,640 @@
|
||||
#!/usr/bin/env python
|
||||
# coding=utf-8
|
||||
# Copyright 2021 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
|
||||
|
||||
Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
|
||||
https://huggingface.co/models?filter=causal-lm
|
||||
"""
|
||||
# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import Callable, Optional
|
||||
|
||||
import datasets
|
||||
from datasets import Dataset, load_dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
import jax
|
||||
import jax.numpy as jnp
|
||||
import optax
|
||||
import transformers
|
||||
from flax import jax_utils, traverse_util
|
||||
from flax.jax_utils import unreplicate
|
||||
from flax.training import train_state
|
||||
from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
|
||||
from transformers import (
|
||||
CONFIG_MAPPING,
|
||||
FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
|
||||
AutoConfig,
|
||||
AutoTokenizer,
|
||||
FlaxAutoModelForCausalLM,
|
||||
HfArgumentParser,
|
||||
TrainingArguments,
|
||||
is_tensorboard_available,
|
||||
)
|
||||
from transformers.testing_utils import CaptureLogger
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
|
||||
MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
|
||||
"""
|
||||
|
||||
model_name_or_path: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "The model checkpoint for weights initialization."
|
||||
"Don't set if you want to train a model from scratch."
|
||||
},
|
||||
)
|
||||
model_type: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
use_fast_tokenizer: bool = field(
|
||||
default=True,
|
||||
metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
|
||||
)
|
||||
dtype: Optional[str] = field(
|
||||
default="float32",
|
||||
metadata={
|
||||
"help": "Floating-point format in which the model weights should be initialized and trained. Choose one of `[float32, float16, bfloat16]`."
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
|
||||
)
|
||||
max_train_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of training examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
max_eval_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
validation_split_percentage: Optional[int] = field(
|
||||
default=5,
|
||||
metadata={
|
||||
"help": "The percentage of the train set used as validation set in case there's no validation split"
|
||||
},
|
||||
)
|
||||
block_size: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "Optional input sequence length after tokenization. "
|
||||
"The training dataset will be truncated in block of this size for training. "
|
||||
"Default to the model max input length for single sentence inputs (take into account special tokens)."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
|
||||
|
||||
|
||||
class TrainState(train_state.TrainState):
|
||||
dropout_rng: jnp.ndarray
|
||||
|
||||
def replicate(self):
|
||||
return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
|
||||
|
||||
|
||||
def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
|
||||
"""
|
||||
Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
|
||||
Shuffle batches if `shuffle` is `True`.
|
||||
"""
|
||||
steps_per_epoch = len(dataset) // batch_size
|
||||
|
||||
if shuffle:
|
||||
batch_idx = jax.random.permutation(rng, len(dataset))
|
||||
else:
|
||||
batch_idx = jnp.arange(len(dataset))
|
||||
|
||||
batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
|
||||
batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
|
||||
|
||||
for idx in batch_idx:
|
||||
batch = dataset[idx]
|
||||
batch = {k: jnp.array(v) for k, v in batch.items()}
|
||||
|
||||
batch = shard(batch)
|
||||
|
||||
yield batch
|
||||
|
||||
|
||||
def write_train_metric(summary_writer, train_metrics, train_time, step):
|
||||
summary_writer.scalar("train_time", train_time, step)
|
||||
|
||||
train_metrics = get_metrics(train_metrics)
|
||||
for key, vals in train_metrics.items():
|
||||
tag = f"train_{key}"
|
||||
for i, val in enumerate(vals):
|
||||
summary_writer.scalar(tag, val, step - len(vals) + i + 1)
|
||||
|
||||
|
||||
def write_eval_metric(summary_writer, eval_metrics, step):
|
||||
for metric_name, value in eval_metrics.items():
|
||||
summary_writer.scalar(f"eval_{metric_name}", value, step)
|
||||
|
||||
|
||||
def create_learning_rate_fn(
|
||||
train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
|
||||
) -> Callable[[int], jnp.array]:
|
||||
"""Returns a linear warmup, linear_decay learning rate function."""
|
||||
steps_per_epoch = train_ds_size // train_batch_size
|
||||
num_train_steps = steps_per_epoch * num_train_epochs
|
||||
warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
|
||||
decay_fn = optax.linear_schedule(
|
||||
init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
|
||||
)
|
||||
schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
|
||||
return schedule_fn
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
print(jax.device_count())
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Make one log on every process with the configuration for debugging.
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO,
|
||||
)
|
||||
# Setup logging, we only want one process per machine to log things on the screen.
|
||||
logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
|
||||
if jax.process_index() == 0:
|
||||
datasets.utils.logging.set_verbosity_warning()
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
else:
|
||||
datasets.utils.logging.set_verbosity_error()
|
||||
transformers.utils.logging.set_verbosity_error()
|
||||
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
logger.info(f"Training/evaluation parameters {training_args}")
|
||||
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantees that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
dataset = load_dataset(
|
||||
data_args.dataset_name, data_args.dataset_config_name, cache_dir=model_args.cache_dir, keep_in_memory=False
|
||||
)
|
||||
|
||||
if "validation" not in dataset.keys():
|
||||
dataset["validation"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[:{data_args.validation_split_percentage}%]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
dataset["train"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[{data_args.validation_split_percentage}%:]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
dataset = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
if model_args.config_name:
|
||||
config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
|
||||
elif model_args.model_name_or_path:
|
||||
config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
|
||||
else:
|
||||
config = CONFIG_MAPPING[model_args.model_type]()
|
||||
logger.warning("You are instantiating a new config instance from scratch.")
|
||||
|
||||
if model_args.tokenizer_name:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
elif model_args.model_name_or_path:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"You are instantiating a new tokenizer from scratch. This is not supported by this script."
|
||||
"You can do it from another script, save it, and load it from here, using --tokenizer_name."
|
||||
)
|
||||
|
||||
if model_args.model_name_or_path:
|
||||
model = FlaxAutoModelForCausalLM.from_pretrained(
|
||||
model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
else:
|
||||
model = FlaxAutoModelForCausalLM.from_config(
|
||||
config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
|
||||
# Preprocessing the datasets.
|
||||
# First we tokenize all the texts.
|
||||
if training_args.do_train:
|
||||
column_names = dataset["train"].column_names
|
||||
else:
|
||||
column_names = dataset["validation"].column_names
|
||||
text_column_name = "text" if "text" in column_names else column_names[0]
|
||||
|
||||
# since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
|
||||
tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
|
||||
|
||||
def tokenize_function(examples):
|
||||
with CaptureLogger(tok_logger) as cl:
|
||||
output = tokenizer(examples[text_column_name])
|
||||
# clm input could be much much longer than block_size
|
||||
if "Token indices sequence length is longer than the" in cl.out:
|
||||
tok_logger.warning(
|
||||
"^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits before being passed to the model."
|
||||
)
|
||||
return output
|
||||
|
||||
tokenized_datasets = dataset.map(
|
||||
tokenize_function,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
remove_columns=column_names,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if data_args.block_size is None:
|
||||
block_size = tokenizer.model_max_length
|
||||
if block_size > config.max_position_embeddings:
|
||||
logger.warning(
|
||||
f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
|
||||
"Picking 1024 instead. You can change that default value by passing --block_size xxx."
|
||||
)
|
||||
block_size = 1024
|
||||
else:
|
||||
if data_args.block_size > tokenizer.model_max_length:
|
||||
logger.warning(
|
||||
f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model"
|
||||
f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
|
||||
)
|
||||
block_size = min(data_args.block_size, tokenizer.model_max_length)
|
||||
|
||||
# Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
|
||||
def group_texts(examples):
|
||||
# Concatenate all texts.
|
||||
concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
||||
total_length = len(concatenated_examples[list(examples.keys())[0]])
|
||||
# We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
||||
# customize this part to your needs.
|
||||
total_length = (total_length // block_size) * block_size
|
||||
# Split by chunks of max_len.
|
||||
result = {
|
||||
k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
||||
for k, t in concatenated_examples.items()
|
||||
}
|
||||
result["labels"] = result["input_ids"].copy()
|
||||
return result
|
||||
|
||||
# Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
|
||||
# for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
|
||||
# to preprocess.
|
||||
#
|
||||
# To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
|
||||
# https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
|
||||
|
||||
lm_datasets = tokenized_datasets.map(
|
||||
group_texts,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if training_args.do_train:
|
||||
if "train" not in tokenized_datasets:
|
||||
raise ValueError("--do_train requires a train dataset")
|
||||
train_dataset = lm_datasets["train"]
|
||||
if data_args.max_train_samples is not None:
|
||||
train_dataset = train_dataset.select(range(data_args.max_train_samples))
|
||||
|
||||
if training_args.do_eval:
|
||||
if "validation" not in tokenized_datasets:
|
||||
raise ValueError("--do_eval requires a validation dataset")
|
||||
eval_dataset = lm_datasets["validation"]
|
||||
if data_args.max_eval_samples is not None:
|
||||
eval_dataset = eval_dataset.select(range(data_args.max_eval_samples))
|
||||
|
||||
# Enable tensorboard only on the master node
|
||||
has_tensorboard = is_tensorboard_available()
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
try:
|
||||
from flax.metrics.tensorboard import SummaryWriter
|
||||
|
||||
summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
|
||||
except ImportError as ie:
|
||||
has_tensorboard = False
|
||||
logger.warning(
|
||||
f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
|
||||
)
|
||||
else:
|
||||
logger.warning(
|
||||
"Unable to display metrics through TensorBoard because the package is not installed: "
|
||||
"Please run pip install tensorboard to enable."
|
||||
)
|
||||
|
||||
# Initialize our training
|
||||
rng = jax.random.PRNGKey(training_args.seed)
|
||||
rng, dropout_rng = jax.random.split(rng)
|
||||
|
||||
# Store some constant
|
||||
num_epochs = int(training_args.num_train_epochs)
|
||||
train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count()
|
||||
eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
total_train_steps = steps_per_epoch * num_epochs
|
||||
|
||||
# Create learning rate schedule
|
||||
linear_decay_lr_schedule_fn = create_learning_rate_fn(
|
||||
len(train_dataset),
|
||||
train_batch_size,
|
||||
training_args.num_train_epochs,
|
||||
training_args.warmup_steps,
|
||||
training_args.learning_rate,
|
||||
)
|
||||
|
||||
# We use Optax's "masking" functionality to not apply weight decay
|
||||
# to bias and LayerNorm scale parameters. decay_mask_fn returns a
|
||||
# mask boolean with the same structure as the parameters.
|
||||
# The mask is True for parameters that should be decayed.
|
||||
# Note that this mask is specifically adapted for FlaxGPT2.
|
||||
# For other models, one should correct the layer norm parameter naming
|
||||
# accordingly.
|
||||
def decay_mask_fn(params):
|
||||
flat_params = traverse_util.flatten_dict(params)
|
||||
flat_mask = {
|
||||
path: (path[-1] != "bias" and path[-2:] not in [("ln_1", "scale"), ("ln_2", "scale"), ("ln_f", "scale")])
|
||||
for path in flat_params
|
||||
}
|
||||
return traverse_util.unflatten_dict(flat_mask)
|
||||
|
||||
# create adam optimizer
|
||||
if training_args.adafactor:
|
||||
# We use the default parameters here to initialize adafactor,
|
||||
# For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
|
||||
optimizer = optax.adafactor(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
)
|
||||
else:
|
||||
optimizer = optax.adamw(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
b1=training_args.adam_beta1,
|
||||
b2=training_args.adam_beta2,
|
||||
eps=training_args.adam_epsilon,
|
||||
weight_decay=training_args.weight_decay,
|
||||
mask=decay_mask_fn,
|
||||
)
|
||||
|
||||
# Setup train state
|
||||
state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer, dropout_rng=dropout_rng)
|
||||
|
||||
def loss_fn(logits, labels):
|
||||
shift_logits = logits[..., :-1, :]
|
||||
shift_labels = labels[..., 1:]
|
||||
loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
|
||||
return loss.mean()
|
||||
|
||||
# Define gradient update step fn
|
||||
def train_step(state, batch):
|
||||
dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
|
||||
|
||||
def compute_loss(params):
|
||||
labels = batch.pop("labels")
|
||||
logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
return loss
|
||||
|
||||
grad_fn = jax.value_and_grad(compute_loss)
|
||||
loss, grad = grad_fn(state.params)
|
||||
grad = jax.lax.pmean(grad, "batch")
|
||||
|
||||
new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
|
||||
|
||||
metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step)}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
|
||||
return new_state, metrics
|
||||
|
||||
# Define eval fn
|
||||
def eval_step(params, batch):
|
||||
labels = batch.pop("labels")
|
||||
logits = model(**batch, params=params, train=False)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
|
||||
# summarize metrics
|
||||
metrics = {"loss": loss}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
return metrics
|
||||
|
||||
# Create parallel version of the train and eval step
|
||||
p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
|
||||
p_eval_step = jax.pmap(eval_step, "batch")
|
||||
|
||||
# Replicate the train state on each device
|
||||
state = state.replicate()
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(f" Num examples = {len(train_dataset)}")
|
||||
logger.info(f" Num Epochs = {num_epochs}")
|
||||
logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
|
||||
logger.info(f" Total train batch size (w. parallel & distributed) = {train_batch_size}")
|
||||
logger.info(f" Total optimization steps = {total_train_steps}")
|
||||
|
||||
train_time = 0
|
||||
train_metrics = []
|
||||
epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
|
||||
for epoch in epochs:
|
||||
# ======================== Training ================================
|
||||
train_start = time.time()
|
||||
|
||||
# Create sampling rng
|
||||
rng, input_rng = jax.random.split(rng)
|
||||
|
||||
# Generate an epoch by shuffling sampling indices from the train dataset
|
||||
train_loader = data_loader(input_rng, train_dataset, train_batch_size, shuffle=True)
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
# train
|
||||
for step in tqdm(range(steps_per_epoch), desc="Training...", position=1, leave=False):
|
||||
batch = next(train_loader)
|
||||
state, train_metric = p_train_step(state, batch)
|
||||
train_metrics.append(train_metric)
|
||||
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size) + step
|
||||
|
||||
if cur_step % training_args.logging_steps == 0 and cur_step > 0:
|
||||
# Save metrics
|
||||
train_metric = unreplicate(train_metric)
|
||||
train_time += time.time() - train_start
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
write_train_metric(summary_writer, train_metrics, train_time, cur_step)
|
||||
|
||||
epochs.write(
|
||||
f"Step... ({cur_step} | Loss: {train_metric['loss'].mean()}, Learning Rate: {train_metric['learning_rate'].mean()})"
|
||||
)
|
||||
|
||||
train_metrics = []
|
||||
|
||||
if cur_step % training_args.eval_steps == 0 and cur_step > 0:
|
||||
# ======================== Evaluating ==============================
|
||||
eval_metrics = []
|
||||
eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size)
|
||||
eval_steps = len(eval_dataset) // eval_batch_size
|
||||
for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
|
||||
# Model forward
|
||||
batch = next(eval_loader)
|
||||
metrics = p_eval_step(state.params, batch)
|
||||
eval_metrics.append(metrics)
|
||||
|
||||
# normalize eval metrics
|
||||
eval_metrics = get_metrics(eval_metrics)
|
||||
eval_metrics = jax.tree_map(jnp.mean, eval_metrics)
|
||||
|
||||
try:
|
||||
eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
|
||||
except OverflowError:
|
||||
eval_metrics["perplexity"] = float("inf")
|
||||
|
||||
# Print metrics and update progress bar
|
||||
desc = f"Step... ({cur_step} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity: {eval_metrics['perplexity']})"
|
||||
epochs.write(desc)
|
||||
epochs.desc = desc
|
||||
|
||||
# Save metrics
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size)
|
||||
write_eval_metric(summary_writer, eval_metrics, cur_step)
|
||||
|
||||
if cur_step % training_args.save_steps == 0 and cur_step > 0:
|
||||
# save checkpoint after each epoch and push checkpoint to the hub
|
||||
if jax.process_index() == 0:
|
||||
params = jax.device_get(unreplicate(state.params))
|
||||
model.save_pretrained(
|
||||
training_args.output_dir,
|
||||
params=params,
|
||||
push_to_hub=training_args.push_to_hub,
|
||||
commit_message=f"Saving weights and logs of step {cur_step}",
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
745
run_clm_flax_chkpts.py
Executable file
745
run_clm_flax_chkpts.py
Executable file
@@ -0,0 +1,745 @@
|
||||
#!/usr/bin/env python
|
||||
# coding=utf-8
|
||||
# Copyright 2021 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Pre-training/Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
|
||||
|
||||
Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
|
||||
https://huggingface.co/models?filter=causal-lm
|
||||
"""
|
||||
# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import Callable, Optional
|
||||
import json
|
||||
import shutil
|
||||
|
||||
import datasets
|
||||
from datasets import Dataset, load_dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
import jax
|
||||
import jax.profiler
|
||||
import jax.numpy as jnp
|
||||
import optax
|
||||
import transformers
|
||||
from flax import jax_utils, traverse_util
|
||||
from flax.jax_utils import unreplicate
|
||||
from flax.training import train_state
|
||||
from flax.training.checkpoints import save_checkpoint, restore_checkpoint
|
||||
from flax.training.common_utils import get_metrics, onehot, shard, shard_prng_key
|
||||
from flax.serialization import to_bytes, from_bytes
|
||||
from transformers import (
|
||||
CONFIG_MAPPING,
|
||||
FLAX_MODEL_FOR_CAUSAL_LM_MAPPING,
|
||||
AutoConfig,
|
||||
AutoTokenizer,
|
||||
FlaxAutoModelForCausalLM,
|
||||
HfArgumentParser,
|
||||
TrainingArguments,
|
||||
is_tensorboard_available,
|
||||
)
|
||||
from transformers.testing_utils import CaptureLogger
|
||||
|
||||
from importlib.util import find_spec
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
MODEL_CONFIG_CLASSES = list(FLAX_MODEL_FOR_CAUSAL_LM_MAPPING.keys())
|
||||
MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
|
||||
"""
|
||||
|
||||
model_name_or_path: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "The model checkpoint for weights initialization."
|
||||
"Don't set if you want to train a model from scratch."
|
||||
},
|
||||
)
|
||||
model_type: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
use_fast_tokenizer: bool = field(
|
||||
default=True,
|
||||
metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
|
||||
)
|
||||
dtype: Optional[str] = field(
|
||||
default="float32",
|
||||
metadata={
|
||||
"help": "Floating-point format in which the model weights should be initialized and trained. Choose one of `[float32, float16, bfloat16]`."
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(default=None, metadata={"help": "The input training data file (a text file)."})
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
|
||||
)
|
||||
max_train_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of training examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
max_eval_samples: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
|
||||
"value if set."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
validation_split_percentage: Optional[int] = field(
|
||||
default=5,
|
||||
metadata={
|
||||
"help": "The percentage of the train set used as validation set in case there's no validation split"
|
||||
},
|
||||
)
|
||||
block_size: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={
|
||||
"help": "Optional input sequence length after tokenization. "
|
||||
"The training dataset will be truncated in block of this size for training. "
|
||||
"Default to the model max input length for single sentence inputs (take into account special tokens)."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
text_column_name: Optional[str] = field(
|
||||
default='text',
|
||||
metadata={"help": "Column containing main text data."},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
|
||||
|
||||
|
||||
class TrainState(train_state.TrainState):
|
||||
dropout_rng: jnp.ndarray
|
||||
|
||||
def replicate(self):
|
||||
return jax_utils.replicate(self).replace(dropout_rng=shard_prng_key(self.dropout_rng))
|
||||
|
||||
|
||||
def data_loader(rng: jax.random.PRNGKey, dataset: Dataset, batch_size: int, shuffle: bool = False):
|
||||
"""
|
||||
Returns batches of size `batch_size` from truncated `dataset`, sharded over all local devices.
|
||||
Shuffle batches if `shuffle` is `True`.
|
||||
"""
|
||||
steps_per_epoch = len(dataset) // batch_size
|
||||
|
||||
if shuffle:
|
||||
batch_idx = jax.random.permutation(rng, len(dataset))
|
||||
else:
|
||||
batch_idx = jnp.arange(len(dataset))
|
||||
|
||||
batch_idx = batch_idx[: steps_per_epoch * batch_size] # Skip incomplete batch.
|
||||
batch_idx = batch_idx.reshape((steps_per_epoch, batch_size))
|
||||
|
||||
for idx in batch_idx:
|
||||
batch = dataset[idx]
|
||||
batch = {k: jnp.array(v) for k, v in batch.items()}
|
||||
|
||||
batch = shard(batch)
|
||||
|
||||
yield batch
|
||||
|
||||
|
||||
def write_train_metric(summary_writer, train_metrics, train_time, step):
|
||||
summary_writer.scalar("train_time", train_time, step)
|
||||
|
||||
train_metrics = get_metrics(train_metrics)
|
||||
for key, vals in train_metrics.items():
|
||||
tag = f"train_{key}"
|
||||
for i, val in enumerate(vals):
|
||||
summary_writer.scalar(tag, val, step - len(vals) + i + 1)
|
||||
|
||||
|
||||
def write_eval_metric(summary_writer, eval_metrics, step):
|
||||
for metric_name, value in eval_metrics.items():
|
||||
summary_writer.scalar(f"eval_{metric_name}", value, step)
|
||||
|
||||
|
||||
def create_learning_rate_fn(
|
||||
train_ds_size: int, train_batch_size: int, num_train_epochs: int, num_warmup_steps: int, learning_rate: float
|
||||
) -> Callable[[int], jnp.array]:
|
||||
"""Returns a linear warmup, linear_decay learning rate function."""
|
||||
steps_per_epoch = train_ds_size // train_batch_size
|
||||
num_train_steps = steps_per_epoch * num_train_epochs
|
||||
warmup_fn = optax.linear_schedule(init_value=0.0, end_value=learning_rate, transition_steps=num_warmup_steps)
|
||||
decay_fn = optax.linear_schedule(
|
||||
init_value=learning_rate, end_value=0, transition_steps=num_train_steps - num_warmup_steps
|
||||
)
|
||||
schedule_fn = optax.join_schedules(schedules=[warmup_fn, decay_fn], boundaries=[num_warmup_steps])
|
||||
return schedule_fn
|
||||
|
||||
# utils
|
||||
def mb_item(x):
|
||||
return x.item() if hasattr(x, "item") else x
|
||||
|
||||
#checkpoint functions
|
||||
def save_checkpoint(model, save_dir, state, with_opt: bool = True):
|
||||
state = jax_utils.unreplicate(state)
|
||||
logger.info(f"SAVING CHECKPOINT IN {save_dir}")
|
||||
save_dir = f"{save_dir}/ckpt-{mb_item(state.step) - 1}"
|
||||
model.save_pretrained(
|
||||
save_dir,
|
||||
params=state.params,
|
||||
push_to_hub=False
|
||||
)
|
||||
if with_opt:
|
||||
with open(os.path.join(save_dir, "opt_state.msgpack"), "wb") as f:
|
||||
f.write(to_bytes(state.opt_state))
|
||||
with open(os.path.join(save_dir, "training_state.json"), "w") as f:
|
||||
json.dump({"step": state.step.item()}, f)
|
||||
logger.info(f"Updating model on the hub")
|
||||
model.save_pretrained(
|
||||
training_args.output_dir,
|
||||
params=state.params,
|
||||
push_to_hub=training_args.push_to_hub,
|
||||
commit_message=f"Saving weights and logs of step {cur_step}",
|
||||
)
|
||||
logger.info("checkpoint saved")
|
||||
|
||||
def restore_checkpoint(save_dir, state):
|
||||
logger.info(f"RESTORING CHECKPOINT FROM {save_dir}")
|
||||
with open(os.path.join(save_dir, "flax_model.msgpack"), "rb") as f:
|
||||
params = from_bytes(state.params, f.read())
|
||||
with open(os.path.join(save_dir, "opt_state.msgpack"), "rb") as f:
|
||||
opt_state = from_bytes(state.opt_state, f.read())
|
||||
with open(os.path.join(save_dir, "training_state.json"), "r") as f:
|
||||
training_state = json.load(f)
|
||||
step = training_state["step"]
|
||||
logger.info("checkpoint restored")
|
||||
return state.replace(step=step, params=params, opt_state=opt_state), step
|
||||
|
||||
def rotate_checkpoints(ckpt_dir: str, save_total_limit: int):
|
||||
"Removes older checkpoints so that `save_total_limit` checkpoints are kept"
|
||||
# TODO: what to remove is decided using step number only, we might want to improve that
|
||||
ckpts = [str(x) for x in Path(ckpt_dir).glob("ckpt-*")]
|
||||
# sort checkpoints by step
|
||||
ckpts_sorted = sorted(ckpts, key=lambda x: int(x.split('-')[-1]))
|
||||
ckpts_to_delete = ckpts_sorted[:-save_total_limit]
|
||||
for ckpt in ckpts_to_delete:
|
||||
logger.info(f"Deleting older checkpoint [{ckpt}] due to save_total_limit ({save_total_limit})")
|
||||
shutil.rmtree(ckpt)
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Make one log on every process with the configuration for debugging.
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO,
|
||||
)
|
||||
# Setup logging, we only want one process per machine to log things on the screen.
|
||||
logger.setLevel(logging.INFO if jax.process_index() == 0 else logging.ERROR)
|
||||
if jax.process_index() == 0:
|
||||
datasets.utils.logging.set_verbosity_warning()
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
else:
|
||||
datasets.utils.logging.set_verbosity_error()
|
||||
transformers.utils.logging.set_verbosity_error()
|
||||
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
logger.info(f"Training/evaluation parameters {training_args}")
|
||||
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantees that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
dataset = load_dataset(
|
||||
data_args.dataset_name, data_args.dataset_config_name, cache_dir=model_args.cache_dir, keep_in_memory=False
|
||||
)
|
||||
|
||||
if "validation" not in dataset.keys():
|
||||
dataset["validation"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[:{data_args.validation_split_percentage}%]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
dataset["train"] = load_dataset(
|
||||
data_args.dataset_name,
|
||||
data_args.dataset_config_name,
|
||||
split=f"train[{data_args.validation_split_percentage}%:]",
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
dataset = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
if model_args.config_name:
|
||||
config = AutoConfig.from_pretrained(model_args.config_name, cache_dir=model_args.cache_dir)
|
||||
elif model_args.model_name_or_path:
|
||||
config = AutoConfig.from_pretrained(model_args.model_name_or_path, cache_dir=model_args.cache_dir)
|
||||
else:
|
||||
config = CONFIG_MAPPING[model_args.model_type]()
|
||||
logger.warning("You are instantiating a new config instance from scratch.")
|
||||
|
||||
if model_args.tokenizer_name:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
elif model_args.model_name_or_path:
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.model_name_or_path, cache_dir=model_args.cache_dir, use_fast=model_args.use_fast_tokenizer
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"You are instantiating a new tokenizer from scratch. This is not supported by this script."
|
||||
"You can do it from another script, save it, and load it from here, using --tokenizer_name."
|
||||
)
|
||||
|
||||
if model_args.model_name_or_path:
|
||||
model = FlaxAutoModelForCausalLM.from_pretrained(
|
||||
model_args.model_name_or_path, config=config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
else:
|
||||
model = FlaxAutoModelForCausalLM.from_config(
|
||||
config, seed=training_args.seed, dtype=getattr(jnp, model_args.dtype)
|
||||
)
|
||||
|
||||
# Preprocessing the datasets.
|
||||
# First we tokenize all the texts.
|
||||
if training_args.do_train:
|
||||
column_names = dataset["train"].column_names
|
||||
else:
|
||||
column_names = dataset["validation"].column_names
|
||||
text_column_name = data_args.text_column_name if data_args.text_column_name in column_names else column_names[0]
|
||||
|
||||
# since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
|
||||
tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
|
||||
|
||||
def tokenize_function(examples):
|
||||
with CaptureLogger(tok_logger) as cl:
|
||||
output = tokenizer(examples[text_column_name])
|
||||
# clm input could be much much longer than block_size
|
||||
if "Token indices sequence length is longer than the" in cl.out:
|
||||
tok_logger.warning(
|
||||
"^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits before being passed to the model."
|
||||
)
|
||||
return output
|
||||
|
||||
tokenized_datasets = dataset.map(
|
||||
tokenize_function,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
remove_columns=column_names,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if data_args.block_size is None:
|
||||
block_size = tokenizer.model_max_length
|
||||
if block_size > config.max_position_embeddings:
|
||||
logger.warning(
|
||||
f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
|
||||
"Picking 1024 instead. You can change that default value by passing --block_size xxx."
|
||||
)
|
||||
block_size = 1024
|
||||
else:
|
||||
if data_args.block_size > tokenizer.model_max_length:
|
||||
logger.warning(
|
||||
f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model"
|
||||
f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
|
||||
)
|
||||
block_size = min(data_args.block_size, tokenizer.model_max_length)
|
||||
|
||||
# Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
|
||||
def group_texts(examples):
|
||||
# Concatenate all texts.
|
||||
concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
|
||||
total_length = len(concatenated_examples[list(examples.keys())[0]])
|
||||
# We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
|
||||
# customize this part to your needs.
|
||||
total_length = (total_length // block_size) * block_size
|
||||
# Split by chunks of max_len.
|
||||
result = {
|
||||
k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
|
||||
for k, t in concatenated_examples.items()
|
||||
}
|
||||
result["labels"] = result["input_ids"].copy()
|
||||
return result
|
||||
|
||||
# Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
|
||||
# for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
|
||||
# to preprocess.
|
||||
#
|
||||
# To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
|
||||
# https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.map
|
||||
|
||||
lm_datasets = tokenized_datasets.map(
|
||||
group_texts,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
if training_args.do_train:
|
||||
if "train" not in tokenized_datasets:
|
||||
raise ValueError("--do_train requires a train dataset")
|
||||
train_dataset = lm_datasets["train"]
|
||||
if data_args.max_train_samples is not None:
|
||||
train_dataset = train_dataset.select(range(data_args.max_train_samples))
|
||||
|
||||
if training_args.do_eval:
|
||||
if "validation" not in tokenized_datasets:
|
||||
raise ValueError("--do_eval requires a validation dataset")
|
||||
eval_dataset = lm_datasets["validation"]
|
||||
if data_args.max_eval_samples is not None:
|
||||
eval_dataset = eval_dataset.select(range(data_args.max_eval_samples))
|
||||
|
||||
# Enable tensorboard only on the master node
|
||||
has_tensorboard = is_tensorboard_available()
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
try:
|
||||
from flax.metrics.tensorboard import SummaryWriter
|
||||
|
||||
summary_writer = SummaryWriter(log_dir=Path(training_args.output_dir))
|
||||
except ImportError as ie:
|
||||
has_tensorboard = False
|
||||
logger.warning(
|
||||
f"Unable to display metrics through TensorBoard because some package are not installed: {ie}"
|
||||
)
|
||||
else:
|
||||
logger.warning(
|
||||
"Unable to display metrics through TensorBoard because the package is not installed: "
|
||||
"Please run pip install tensorboard to enable."
|
||||
)
|
||||
|
||||
# enable wandb tracking
|
||||
has_wandb = find_spec("wandb") is not None
|
||||
if jax.process_index() == 0 and has_wandb:
|
||||
try:
|
||||
import wandb
|
||||
wandb.init(
|
||||
entity="wandb",
|
||||
project="hf-flax-papuGaPT2",
|
||||
sync_tensorboard=True
|
||||
)
|
||||
wandb.config.update(training_args)
|
||||
wandb.config.update(model_args)
|
||||
wandb.config.update(data_args)
|
||||
except ImportError as e:
|
||||
print(e)
|
||||
has_wandb = False
|
||||
|
||||
|
||||
# Initialize our training
|
||||
rng = jax.random.PRNGKey(training_args.seed)
|
||||
rng, dropout_rng = jax.random.split(rng)
|
||||
|
||||
# Store some constant
|
||||
num_epochs = int(training_args.num_train_epochs)
|
||||
train_batch_size = int(training_args.per_device_train_batch_size) * jax.device_count() * training_args.gradient_accumulation_steps
|
||||
eval_batch_size = int(training_args.per_device_eval_batch_size) * jax.device_count()
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
total_train_steps = steps_per_epoch * num_epochs
|
||||
|
||||
# Create learning rate schedule
|
||||
linear_decay_lr_schedule_fn = create_learning_rate_fn(
|
||||
len(train_dataset),
|
||||
train_batch_size,
|
||||
training_args.num_train_epochs,
|
||||
training_args.warmup_steps,
|
||||
training_args.learning_rate,
|
||||
)
|
||||
|
||||
# We use Optax's "masking" functionality to not apply weight decay
|
||||
# to bias and LayerNorm scale parameters. decay_mask_fn returns a
|
||||
# mask boolean with the same structure as the parameters.
|
||||
# The mask is True for parameters that should be decayed.
|
||||
# Note that this mask is specifically adapted for FlaxGPT2.
|
||||
# For other models, one should correct the layer norm parameter naming
|
||||
# accordingly.
|
||||
def decay_mask_fn(params):
|
||||
flat_params = traverse_util.flatten_dict(params)
|
||||
flat_mask = {
|
||||
path: (path[-1] != "bias" and path[-2:] not in [("ln_1", "scale"), ("ln_2", "scale"), ("ln_f", "scale")])
|
||||
for path in flat_params
|
||||
}
|
||||
return traverse_util.unflatten_dict(flat_mask)
|
||||
|
||||
# create optimizer
|
||||
if training_args.adafactor:
|
||||
# We use the default parameters here to initialize adafactor,
|
||||
# For more details about the parameters please check https://github.com/deepmind/optax/blob/ed02befef9bf81cbbf236be3d2b0e032e9ed4a40/optax/_src/alias.py#L74
|
||||
optimizer = optax.adafactor(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
)
|
||||
else:
|
||||
optimizer = optax.adamw(
|
||||
learning_rate=linear_decay_lr_schedule_fn,
|
||||
b1=training_args.adam_beta1,
|
||||
b2=training_args.adam_beta2,
|
||||
eps=training_args.adam_epsilon,
|
||||
weight_decay=training_args.weight_decay,
|
||||
mask=decay_mask_fn,
|
||||
)
|
||||
if training_args.gradient_accumulation_steps > 1:
|
||||
optimizer = optax.MultiSteps(optimizer, training_args.gradient_accumulation_steps)
|
||||
grad_accum_steps = training_args.gradient_accumulation_steps
|
||||
|
||||
# Setup train state
|
||||
state = TrainState.create(apply_fn=model.__call__, params=model.params, tx=optimizer, dropout_rng=dropout_rng)
|
||||
|
||||
if training_args.resume_from_checkpoint:
|
||||
state, resume_step = restore_checkpoint(training_args.resume_from_checkpoint, state)
|
||||
else:
|
||||
resume_step = 0
|
||||
|
||||
def loss_fn(logits, labels):
|
||||
shift_logits = logits[..., :-1, :]
|
||||
shift_labels = labels[..., 1:]
|
||||
loss = optax.softmax_cross_entropy(shift_logits, onehot(shift_labels, shift_logits.shape[-1]))
|
||||
return loss.mean()
|
||||
|
||||
# Define gradient update step fn
|
||||
def train_step(state, batch):
|
||||
dropout_rng, new_dropout_rng = jax.random.split(state.dropout_rng)
|
||||
|
||||
def compute_loss(params):
|
||||
labels = batch.pop("labels")
|
||||
logits = state.apply_fn(**batch, params=params, dropout_rng=dropout_rng, train=True)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
return loss
|
||||
|
||||
grad_fn = jax.value_and_grad(compute_loss)
|
||||
loss, grad = grad_fn(state.params)
|
||||
grad = jax.lax.pmean(grad, "batch")
|
||||
|
||||
new_state = state.apply_gradients(grads=grad, dropout_rng=new_dropout_rng)
|
||||
|
||||
metrics = {"loss": loss, "learning_rate": linear_decay_lr_schedule_fn(state.step // grad_accum_steps)}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
|
||||
return new_state, metrics
|
||||
|
||||
# Define eval fn
|
||||
def eval_step(params, batch):
|
||||
labels = batch.pop("labels")
|
||||
logits = model(**batch, params=params, train=False)[0]
|
||||
loss = loss_fn(logits, labels)
|
||||
|
||||
# summarize metrics
|
||||
metrics = {"loss": loss}
|
||||
metrics = jax.lax.pmean(metrics, axis_name="batch")
|
||||
return metrics
|
||||
|
||||
# Create parallel version of the train and eval step
|
||||
p_train_step = jax.pmap(train_step, "batch", donate_argnums=(0,))
|
||||
p_eval_step = jax.pmap(eval_step, "batch")
|
||||
|
||||
# Replicate the train state on each device
|
||||
state = state.replicate()
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(f" Num examples = {len(train_dataset)}")
|
||||
logger.info(f" Num Epochs = {num_epochs}")
|
||||
logger.info(f" Instantaneous batch size per device = {training_args.per_device_train_batch_size}")
|
||||
logger.info(f" Total train batch size (w. parallel, distributed and grad_accum) = {train_batch_size}")
|
||||
logger.info(f" Total optimization steps = {total_train_steps}")
|
||||
|
||||
if not training_args.skip_memory_metrics:
|
||||
server = jax.profiler.start_server(9999)
|
||||
|
||||
train_time = 0
|
||||
train_metrics = []
|
||||
# TODO: figure out training duration
|
||||
epochs = tqdm(range(num_epochs), desc=f"Epoch ... (1/{num_epochs})", position=0)
|
||||
for epoch in epochs:
|
||||
# ======================== Training ================================
|
||||
train_start = time.time()
|
||||
|
||||
# Create sampling rng
|
||||
rng, input_rng = jax.random.split(rng)
|
||||
|
||||
# Generate an epoch by shuffling sampling indices from the train dataset
|
||||
train_loader = data_loader(input_rng, train_dataset, train_batch_size // grad_accum_steps, shuffle=True)
|
||||
steps_per_epoch = len(train_dataset) // train_batch_size
|
||||
# train
|
||||
steps_trained_progress_bar = tqdm(range(steps_per_epoch), desc="Training...", position=1,
|
||||
leave=False, initial=(resume_step // grad_accum_steps))
|
||||
for step in range(steps_per_epoch * grad_accum_steps):
|
||||
cur_step = epoch * (len(train_dataset) // train_batch_size) + step
|
||||
# skip to the step from which we are resuming
|
||||
if cur_step < resume_step:
|
||||
continue
|
||||
|
||||
batch = next(train_loader)
|
||||
state, train_metric = p_train_step(state, batch)
|
||||
train_metrics.append(train_metric)
|
||||
if step % grad_accum_steps == 0:
|
||||
steps_trained_progress_bar.update(1)
|
||||
|
||||
if cur_step % (training_args.logging_steps * grad_accum_steps)== 0 and cur_step > 0:
|
||||
# Save metrics
|
||||
train_metric = unreplicate(train_metric)
|
||||
train_time += time.time() - train_start
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
write_train_metric(summary_writer, train_metrics, train_time, cur_step)
|
||||
if has_wandb and jax.process_index() == 0 and ("wandb" in training_args.report_to):
|
||||
# TODO: add accumulation of metrics
|
||||
_metrics = {k if k=="learning_rate" else f"train_{k}":mb_item(v.mean()) for k, v in train_metric.items()}
|
||||
wandb.log({"training_step":cur_step, **_metrics}, commit=True)
|
||||
|
||||
epochs.write(
|
||||
f"Step... ({cur_step} | Loss: {train_metric['loss'].mean()}, Learning Rate: {train_metric['learning_rate'].mean()})"
|
||||
)
|
||||
|
||||
train_metrics = []
|
||||
|
||||
if cur_step % (training_args.eval_steps * grad_accum_steps) == 0 and cur_step > 0:
|
||||
# ======================== Evaluating ==============================
|
||||
eval_metrics = []
|
||||
eval_loader = data_loader(input_rng, eval_dataset, eval_batch_size)
|
||||
eval_steps = len(eval_dataset) // eval_batch_size
|
||||
for _ in tqdm(range(eval_steps), desc="Evaluating...", position=2, leave=False):
|
||||
# Model forward
|
||||
batch = next(eval_loader)
|
||||
metrics = p_eval_step(state.params, batch)
|
||||
eval_metrics.append(metrics)
|
||||
|
||||
# normalize eval metrics
|
||||
eval_metrics = get_metrics(eval_metrics)
|
||||
eval_metrics = jax.tree_map(jnp.mean, eval_metrics)
|
||||
|
||||
try:
|
||||
eval_metrics["perplexity"] = math.exp(eval_metrics["loss"])
|
||||
except OverflowError:
|
||||
eval_metrics["perplexity"] = float("inf")
|
||||
|
||||
# Print metrics and update progress bar
|
||||
desc = f"Step... ({cur_step} | Eval Loss: {eval_metrics['loss']} | Eval Perplexity: {eval_metrics['perplexity']})"
|
||||
epochs.write(desc)
|
||||
epochs.desc = desc
|
||||
|
||||
# Save metrics
|
||||
if has_tensorboard and jax.process_index() == 0:
|
||||
# cur_step = epoch * (len(train_dataset) // train_batch_size)
|
||||
write_eval_metric(summary_writer, eval_metrics, cur_step)
|
||||
if has_wandb and jax.process_index() == 0 and ("wandb" in training_args.report_to):
|
||||
_metrics = {f"eval_{k}":mb_item(v) for k, v in eval_metrics.items()}
|
||||
wandb.log({"eval_step":cur_step, **_metrics})
|
||||
|
||||
if cur_step % training_args.save_steps * grad_accum_steps == 0 and cur_step > 0:
|
||||
logger.info(f"We should save the model here after {cur_step} steps")
|
||||
# save checkpoint after each epoch and push checkpoint to the hub
|
||||
if jax.process_index() == 0:
|
||||
save_checkpoint(model, training_args.output_dir, state)
|
||||
if training_args.save_total_limit is not None:
|
||||
rotate_checkpoints(training_args.output_dir, training_args.save_total_limit)
|
||||
|
||||
# Save model at end
|
||||
if jax.process_index() == 0:
|
||||
save_checkpoint(model, training_args.output_dir, state, with_opt=False)
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
1
special_tokens_map.json
Normal file
1
special_tokens_map.json
Normal file
@@ -0,0 +1 @@
|
||||
{"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}
|
||||
1
tokenizer.json
Normal file
1
tokenizer.json
Normal file
File diff suppressed because one or more lines are too long
1
tokenizer_config.json
Normal file
1
tokenizer_config.json
Normal file
@@ -0,0 +1 @@
|
||||
{"unk_token": "<|endoftext|>", "bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "add_prefix_space": false, "special_tokens_map_file": null, "name_or_path": "./", "tokenizer_class": "GPT2Tokenizer"}
|
||||
26
train_tokenizer.py
Executable file
26
train_tokenizer.py
Executable file
@@ -0,0 +1,26 @@
|
||||
from datasets import load_dataset
|
||||
from tokenizers import trainers, Tokenizer, normalizers, ByteLevelBPETokenizer
|
||||
|
||||
model_dir = "." # ${MODEL_DIR}
|
||||
|
||||
# load dataset
|
||||
dataset = load_dataset("oscar", "unshuffled_deduplicated_pl", split="train")
|
||||
|
||||
# Instantiate tokenizer
|
||||
tokenizer = ByteLevelBPETokenizer()
|
||||
|
||||
def batch_iterator(batch_size=1000):
|
||||
for i in range(0, len(dataset), batch_size):
|
||||
yield dataset[i: i + batch_size]["text"]
|
||||
|
||||
# Customized training
|
||||
tokenizer.train_from_iterator(batch_iterator(), vocab_size=50265, min_frequency=2, special_tokens=[
|
||||
"<s>",
|
||||
"<pad>",
|
||||
"</s>",
|
||||
"<unk>",
|
||||
"<mask>",
|
||||
])
|
||||
|
||||
# Save files to disk
|
||||
tokenizer.save(f"{model_dir}/tokenizer.json")
|
||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user