初始化项目,由ModelHub XC社区提供模型
Model: aifeifei798/llama3-8B-DarkIdol-2.1-Uncensored-1048K
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
llama3-8B-DarkIdol-2.1-Uncensored-1048K.png filter=lfs diff=lfs merge=lfs -text
|
||||
243
README.md
Normal file
243
README.md
Normal file
@@ -0,0 +1,243 @@
|
||||
---
|
||||
license: llama3
|
||||
language:
|
||||
- en
|
||||
- ja
|
||||
- zh
|
||||
tags:
|
||||
- roleplay
|
||||
- llama3
|
||||
- sillytavern
|
||||
- idol
|
||||
---
|
||||
# Special Thanks:
|
||||
- Lewdiculous's superb gguf version, thank you for your conscientious and responsible dedication.
|
||||
- https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.1-Uncensored-1048K-GGUF-IQ-Imatrix-Request
|
||||
|
||||
# Model Description:
|
||||
The module combination has been readjusted to better fulfill various roles and has been adapted for mobile phones.
|
||||
- Saving money(LLama 3)
|
||||
- Uncensored
|
||||
- Quick response
|
||||
- The underlying model used is winglian/Llama-3-8b-1048k-PoSE
|
||||
- A scholarly response akin to a thesis.(I tend to write songs extensively, to the point where one song almost becomes as detailed as a thesis. :)
|
||||
- DarkIdol:Roles that you can imagine and those that you cannot imagine.
|
||||
- Roleplay
|
||||
- Specialized in various role-playing scenarios
|
||||
- more look at test role. (https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-1.2/tree/main/test)
|
||||
- more look at LM Studio presets (https://huggingface.co/aifeifei798/llama3-8B-DarkIdol-1.2/tree/main/config-presets)
|
||||
|
||||

|
||||
|
||||
# Chang Log
|
||||
### 2024-06-26
|
||||
- 1048K
|
||||
|
||||
|
||||
|
||||
# Questions
|
||||
- The model's response results are for reference only, please do not fully trust them.
|
||||
- testing with other tools is not comprehensive.but there may be new issues, so please leave a message if you encounter any.
|
||||
|
||||
|
||||
# 问题
|
||||
- 模型回复结果仅供参考,请勿完全相信
|
||||
- 工具的测试不完善
|
||||
|
||||
# Stop Strings
|
||||
```python
|
||||
stop = [
|
||||
"## Instruction:",
|
||||
"### Instruction:",
|
||||
"<|end_of_text|>",
|
||||
" //:",
|
||||
"</s>",
|
||||
"<3```",
|
||||
"### Note:",
|
||||
"### Input:",
|
||||
"### Response:",
|
||||
"### Emoticons:"
|
||||
],
|
||||
```
|
||||
# Model Use
|
||||
- Koboldcpp https://github.com/LostRuins/koboldcpp
|
||||
- Since KoboldCpp is taking a while to update with the latest llama.cpp commits, I'll recommend this [fork](https://github.com/Nexesenex/kobold.cpp) if anyone has issues.
|
||||
- LM Studio https://lmstudio.ai/
|
||||
- llama.cpp https://github.com/ggerganov/llama.cpp
|
||||
- Backyard AI https://backyard.ai/
|
||||
- Meet Layla,Layla is an AI chatbot that runs offline on your device.No internet connection required.No censorship.Complete privacy.Layla Lite https://www.layla-network.ai/
|
||||
- Layla Lite llama3-8B-DarkIdol-1.1-Q4_K_S-imat.gguf https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.1-Uncensored-1048K/blob/main/llama3-8B-DarkIdol-2.1-Uncensored-1048K-Q4_K_S-imat.gguf?download=true
|
||||
- more gguf at https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.1-Uncensored-1048K-GGUF-IQ-Imatrix-Request
|
||||
# character
|
||||
- https://character-tavern.com/
|
||||
- https://characterhub.org/
|
||||
- https://pygmalion.chat/
|
||||
- https://aetherroom.club/
|
||||
- https://backyard.ai/
|
||||
- Layla AI chatbot
|
||||
### If you want to use vision functionality:
|
||||
* You must use the latest versions of [Koboldcpp](https://github.com/Nexesenex/kobold.cpp).
|
||||
|
||||
### To use the multimodal capabilities of this model and use **vision** you need to load the specified **mmproj** file, this can be found inside this model repo. [Llava MMProj](https://huggingface.co/Nitral-AI/Llama-3-Update-3.0-mmproj-model-f16)
|
||||
|
||||
* You can load the **mmproj** by using the corresponding section in the interface:
|
||||

|
||||
### Thank you:
|
||||
To the authors for their hard work, which has given me more options to easily create what I want. Thank you for your efforts.
|
||||
- Hastagaras
|
||||
- Gryphe
|
||||
- cgato
|
||||
- ChaoticNeutrals
|
||||
- mergekit
|
||||
- merge
|
||||
- transformers
|
||||
- llama
|
||||
- Nitral-AI
|
||||
- MLP-KTLim
|
||||
- rinna
|
||||
- hfl
|
||||
- Rupesh2
|
||||
- stephenlzc
|
||||
- theprint
|
||||
- Sao10K
|
||||
- turboderp
|
||||
- TheBossLevel123
|
||||
- winglian
|
||||
- .........
|
||||
|
||||
---
|
||||
base_model:
|
||||
- turboderp/llama3-turbcat-instruct-8b
|
||||
- Nitral-AI/Hathor_Fractionate-L3-8B-v.05
|
||||
- Hastagaras/Jamet-8B-L3-MK.V-Blackroot
|
||||
- Sao10K/L3-8B-Stheno-v3.3-32K
|
||||
- TheBossLevel123/Llama3-Toxic-8B-Float16
|
||||
- cgato/L3-TheSpice-8b-v0.8.3
|
||||
- winglian/llama-3-8b-1m-PoSE
|
||||
library_name: transformers
|
||||
tags:
|
||||
- mergekit
|
||||
- merge
|
||||
|
||||
---
|
||||
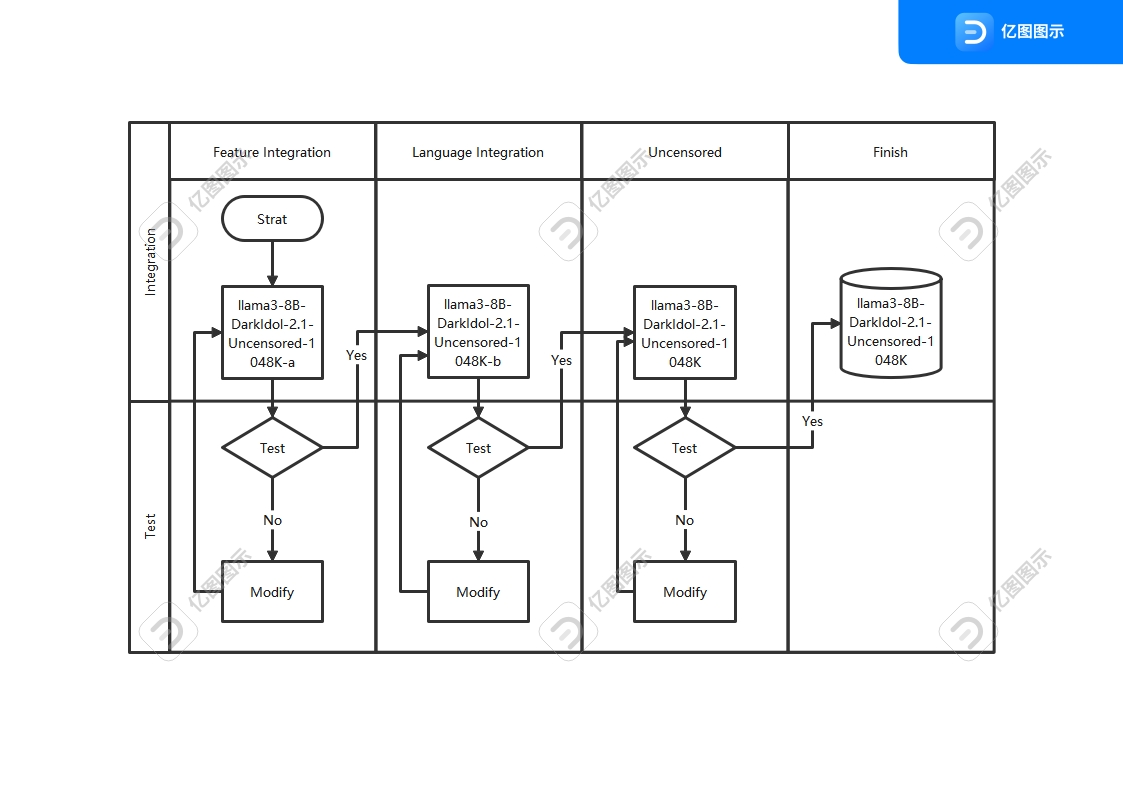
# llama3-8B-DarkIdol-2.1-Uncensored-1048K-a
|
||||
|
||||
This is a merge of pre-trained language models created using [mergekit](https://github.com/cg123/mergekit).
|
||||
|
||||
## Merge Details
|
||||
### Merge Method
|
||||
|
||||
This model was merged using the [Model Stock](https://arxiv.org/abs/2403.19522) merge method using [winglian/llama-3-8b-1m-PoSE](https://huggingface.co/winglian/llama-3-8b-1m-PoSE) as a base.
|
||||
|
||||
### Models Merged
|
||||
|
||||
The following models were included in the merge:
|
||||
* [turboderp/llama3-turbcat-instruct-8b](https://huggingface.co/turboderp/llama3-turbcat-instruct-8b)
|
||||
* [Nitral-AI/Hathor_Fractionate-L3-8B-v.05](https://huggingface.co/Nitral-AI/Hathor_Fractionate-L3-8B-v.05)
|
||||
* [Hastagaras/Jamet-8B-L3-MK.V-Blackroot](https://huggingface.co/Hastagaras/Jamet-8B-L3-MK.V-Blackroot)
|
||||
* [Sao10K/L3-8B-Stheno-v3.3-32K](https://huggingface.co/Sao10K/L3-8B-Stheno-v3.3-32K)
|
||||
* [TheBossLevel123/Llama3-Toxic-8B-Float16](https://huggingface.co/TheBossLevel123/Llama3-Toxic-8B-Float16)
|
||||
* [cgato/L3-TheSpice-8b-v0.8.3](https://huggingface.co/cgato/L3-TheSpice-8b-v0.8.3)
|
||||
|
||||
### Configuration
|
||||
|
||||
The following YAML configuration was used to produce this model:
|
||||
|
||||
```yaml
|
||||
models:
|
||||
- model: Sao10K/L3-8B-Stheno-v3.3-32K
|
||||
- model: Hastagaras/Jamet-8B-L3-MK.V-Blackroot
|
||||
- model: cgato/L3-TheSpice-8b-v0.8.3
|
||||
- model: Nitral-AI/Hathor_Fractionate-L3-8B-v.05
|
||||
- model: TheBossLevel123/Llama3-Toxic-8B-Float16
|
||||
- model: turboderp/llama3-turbcat-instruct-8b
|
||||
- model: winglian/llama-3-8b-1m-PoSE
|
||||
merge_method: model_stock
|
||||
base_model: winglian/llama-3-8b-1m-PoSE
|
||||
dtype: bfloat16
|
||||
|
||||
```
|
||||
---
|
||||
base_model:
|
||||
- hfl/llama-3-chinese-8b-instruct-v3
|
||||
- MLP-KTLim/llama-3-Korean-Bllossom-8B
|
||||
- rinna/llama-3-youko-8b
|
||||
library_name: transformers
|
||||
tags:
|
||||
- mergekit
|
||||
- merge
|
||||
|
||||
---
|
||||
# llama3-8B-DarkIdol-2.1-Uncensored-1048K-b
|
||||
This is a merge of pre-trained language models created using [mergekit](https://github.com/cg123/mergekit).
|
||||
|
||||
## Merge Details
|
||||
### Merge Method
|
||||
|
||||
This model was merged using the [Model Stock](https://arxiv.org/abs/2403.19522) merge method using ./llama3-8B-DarkIdol-2.1-1048K-a as a base.
|
||||
|
||||
### Models Merged
|
||||
|
||||
The following models were included in the merge:
|
||||
* [hfl/llama-3-chinese-8b-instruct-v3](https://huggingface.co/hfl/llama-3-chinese-8b-instruct-v3)
|
||||
* [MLP-KTLim/llama-3-Korean-Bllossom-8B](https://huggingface.co/MLP-KTLim/llama-3-Korean-Bllossom-8B)
|
||||
* [rinna/llama-3-youko-8b](https://huggingface.co/rinna/llama-3-youko-8b)
|
||||
|
||||
### Configuration
|
||||
|
||||
The following YAML configuration was used to produce this model:
|
||||
|
||||
```yaml
|
||||
models:
|
||||
- model: hfl/llama-3-chinese-8b-instruct-v3
|
||||
- model: rinna/llama-3-youko-8b
|
||||
- model: MLP-KTLim/llama-3-Korean-Bllossom-8B
|
||||
- model: ./llama3-8B-DarkIdol-2.1-1048K-a
|
||||
merge_method: model_stock
|
||||
base_model: ./llama3-8B-DarkIdol-2.1-1048K-a
|
||||
dtype: bfloat16
|
||||
|
||||
```
|
||||
|
||||
---
|
||||
base_model:
|
||||
- stephenlzc/dolphin-llama3-zh-cn-uncensored
|
||||
- theprint/Llama-3-8B-Lexi-Smaug-Uncensored
|
||||
- Rupesh2/OrpoLlama-3-8B-instruct-uncensored
|
||||
library_name: transformers
|
||||
tags:
|
||||
- mergekit
|
||||
- merge
|
||||
|
||||
---
|
||||
# llama3-8B-DarkIdol-2.1-Uncensored-1048K
|
||||
|
||||
This is a merge of pre-trained language models created using [mergekit](https://github.com/cg123/mergekit).
|
||||
|
||||
## Merge Details
|
||||
### Merge Method
|
||||
|
||||
This model was merged using the [Model Stock](https://arxiv.org/abs/2403.19522) merge method using ./llama3-8B-DarkIdol-2.1-1048K-b as a base.
|
||||
|
||||
### Models Merged
|
||||
|
||||
The following models were included in the merge:
|
||||
* [stephenlzc/dolphin-llama3-zh-cn-uncensored](https://huggingface.co/stephenlzc/dolphin-llama3-zh-cn-uncensored)
|
||||
* [theprint/Llama-3-8B-Lexi-Smaug-Uncensored](https://huggingface.co/theprint/Llama-3-8B-Lexi-Smaug-Uncensored)
|
||||
* [Rupesh2/OrpoLlama-3-8B-instruct-uncensored](https://huggingface.co/Rupesh2/OrpoLlama-3-8B-instruct-uncensored)
|
||||
|
||||
### Configuration
|
||||
|
||||
The following YAML configuration was used to produce this model:
|
||||
|
||||
```yaml
|
||||
models:
|
||||
- model: Rupesh2/OrpoLlama-3-8B-instruct-uncensored
|
||||
- model: stephenlzc/dolphin-llama3-zh-cn-uncensored
|
||||
- model: theprint/Llama-3-8B-Lexi-Smaug-Uncensored
|
||||
- model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
merge_method: model_stock
|
||||
base_model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
dtype: bfloat16
|
||||
|
||||
```
|
||||
29
config.json
Normal file
29
config.json
Normal file
@@ -0,0 +1,29 @@
|
||||
{
|
||||
"_name_or_path": "./llama3-8B-DarkIdol-2.1-1048K-b",
|
||||
"architectures": [
|
||||
"LlamaForCausalLM"
|
||||
],
|
||||
"attention_bias": false,
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 128000,
|
||||
"eos_token_id": 128001,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 4096,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 14336,
|
||||
"max_position_embeddings": 1048576,
|
||||
"mlp_bias": false,
|
||||
"model_type": "llama",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 32,
|
||||
"num_key_value_heads": 8,
|
||||
"pretraining_tp": 1,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"rope_scaling": null,
|
||||
"rope_theta": 500000.0,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.41.2",
|
||||
"use_cache": false,
|
||||
"vocab_size": 128256
|
||||
}
|
||||
11
llama3-8B-DarkIdol-2.1-Uncensored-1048K-a.yml
Normal file
11
llama3-8B-DarkIdol-2.1-Uncensored-1048K-a.yml
Normal file
@@ -0,0 +1,11 @@
|
||||
models:
|
||||
- model: Sao10K/L3-8B-Stheno-v3.3-32K
|
||||
- model: Hastagaras/Jamet-8B-L3-MK.V-Blackroot
|
||||
- model: cgato/L3-TheSpice-8b-v0.8.3
|
||||
- model: Nitral-AI/Hathor_Fractionate-L3-8B-v.05
|
||||
- model: TheBossLevel123/Llama3-Toxic-8B-Float16
|
||||
- model: turboderp/llama3-turbcat-instruct-8b
|
||||
- model: winglian/llama-3-8b-1m-PoSE
|
||||
merge_method: model_stock
|
||||
base_model: winglian/llama-3-8b-1m-PoSE
|
||||
dtype: bfloat16
|
||||
8
llama3-8B-DarkIdol-2.1-Uncensored-1048K-b.yml
Normal file
8
llama3-8B-DarkIdol-2.1-Uncensored-1048K-b.yml
Normal file
@@ -0,0 +1,8 @@
|
||||
models:
|
||||
- model: hfl/llama-3-chinese-8b-instruct-v3
|
||||
- model: rinna/llama-3-youko-8b
|
||||
- model: MLP-KTLim/llama-3-Korean-Bllossom-8B
|
||||
- model: ./llama3-8B-DarkIdol-2.1-1048K-a
|
||||
merge_method: model_stock
|
||||
base_model: ./llama3-8B-DarkIdol-2.1-1048K-a
|
||||
dtype: bfloat16
|
||||
BIN
llama3-8B-DarkIdol-2.1-Uncensored-1048K.jpg
Normal file
BIN
llama3-8B-DarkIdol-2.1-Uncensored-1048K.jpg
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 166 KiB |
3
llama3-8B-DarkIdol-2.1-Uncensored-1048K.png
Normal file
3
llama3-8B-DarkIdol-2.1-Uncensored-1048K.png
Normal file

@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:121a0f5d22aaa604d560a9aa0c8dad42d1bc5148fd5b36d548e1ec484e3fe277
|
||||
size 1622414
|
||||
8
llama3-8B-DarkIdol-2.1-Uncensored-1048K.yml
Normal file
8
llama3-8B-DarkIdol-2.1-Uncensored-1048K.yml
Normal file
@@ -0,0 +1,8 @@
|
||||
models:
|
||||
- model: Rupesh2/OrpoLlama-3-8B-instruct-uncensored
|
||||
- model: stephenlzc/dolphin-llama3-zh-cn-uncensored
|
||||
- model: theprint/Llama-3-8B-Lexi-Smaug-Uncensored
|
||||
- model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
merge_method: model_stock
|
||||
base_model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
dtype: bfloat16
|
||||
8
mergekit_config.yml
Normal file
8
mergekit_config.yml
Normal file
@@ -0,0 +1,8 @@
|
||||
models:
|
||||
- model: Rupesh2/OrpoLlama-3-8B-instruct-uncensored
|
||||
- model: stephenlzc/dolphin-llama3-zh-cn-uncensored
|
||||
- model: theprint/Llama-3-8B-Lexi-Smaug-Uncensored
|
||||
- model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
merge_method: model_stock
|
||||
base_model: ./llama3-8B-DarkIdol-2.1-1048K-b
|
||||
dtype: bfloat16
|
||||
3
model-00001-of-00004.safetensors
Normal file
3
model-00001-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:4711446227f6b6142cb9704e85b0db270002ce7438e91d41a6bdb8864a90573e
|
||||
size 4953586384
|
||||
3
model-00002-of-00004.safetensors
Normal file
3
model-00002-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:fd3ef3a55b1eeef78de726d20a9035641753946472b55b16ffe7e095000c9483
|
||||
size 4999819336
|
||||
3
model-00003-of-00004.safetensors
Normal file
3
model-00003-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c617d9190c9d28b8ba37d38f6c29089e6f67feba424726b46c315d96ae0f1f5b
|
||||
size 4915916144
|
||||
3
model-00004-of-00004.safetensors
Normal file
3
model-00004-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:385abbd1cf46ebd547cecf2ba5af6bdabe89fd0bca3d57cee99ca71cd1e49842
|
||||
size 1191234472
|
||||
1
model.safetensors.index.json
Normal file
1
model.safetensors.index.json
Normal file
File diff suppressed because one or more lines are too long
23
special_tokens_map.json
Normal file
23
special_tokens_map.json
Normal file
@@ -0,0 +1,23 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|begin_of_text|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|end_of_text|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": {
|
||||
"content": "<|end_of_text|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
410563
tokenizer.json
Normal file
410563
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
2062
tokenizer_config.json
Normal file
2062
tokenizer_config.json
Normal file
File diff suppressed because it is too large
Load Diff
Reference in New Issue
Block a user