初始化项目,由ModelHub XC社区提供模型
Model: TobiasLogic/Qwen2.5-Coder-32B-abliterated
Source: Original Platform
This commit is contained in:
 ModelHub XC
95
README.md
Normal file
95
README.md
Normal file
@@ -0,0 +1,95 @@
|
||||
---
|
||||
license: apache-2.0
|
||||
base_model: Qwen/Qwen2.5-Coder-32B-Instruct
|
||||
tags:
|
||||
- abliterated
|
||||
- uncensored
|
||||
- code
|
||||
- qwen2.5
|
||||
- text-generation
|
||||
pipeline_tag: text-generation
|
||||
language:
|
||||
- en
|
||||
---
|
||||
|
||||
# Qwen2.5-Coder-32B-abliterated
|
||||
|
||||
An **abliterated** (uncensored) build of
|
||||
[`Qwen/Qwen2.5-Coder-32B-Instruct`](https://huggingface.co/Qwen/Qwen2.5-Coder-32B-Instruct).
|
||||
The model's refusal direction (Arditi et al. 2024, *"Refusal in LLMs is mediated
|
||||
by a single direction"*) was estimated from contrasting harmful/harmless prompts
|
||||
and **orthogonalized out of every residual-writing weight** (all attention
|
||||
`o_proj`, all MLP `down_proj`, and token embeddings). This is a static weight
|
||||
edit — no LoRA, no runtime hooks, no inference-time cost. Coding ability is
|
||||
inherited from the base model.
|
||||
|
||||
- **GGUF (Q4_K_M) build:** [`TobiasLogic/Qwen2.5-Coder-32B-abliterated-GGUF`](https://huggingface.co/TobiasLogic/Qwen2.5-Coder-32B-abliterated-GGUF)
|
||||
- **Method / reproducible pipeline:** see the GitHub repo linked below.
|
||||
|
||||
## Benchmarks
|
||||
|
||||
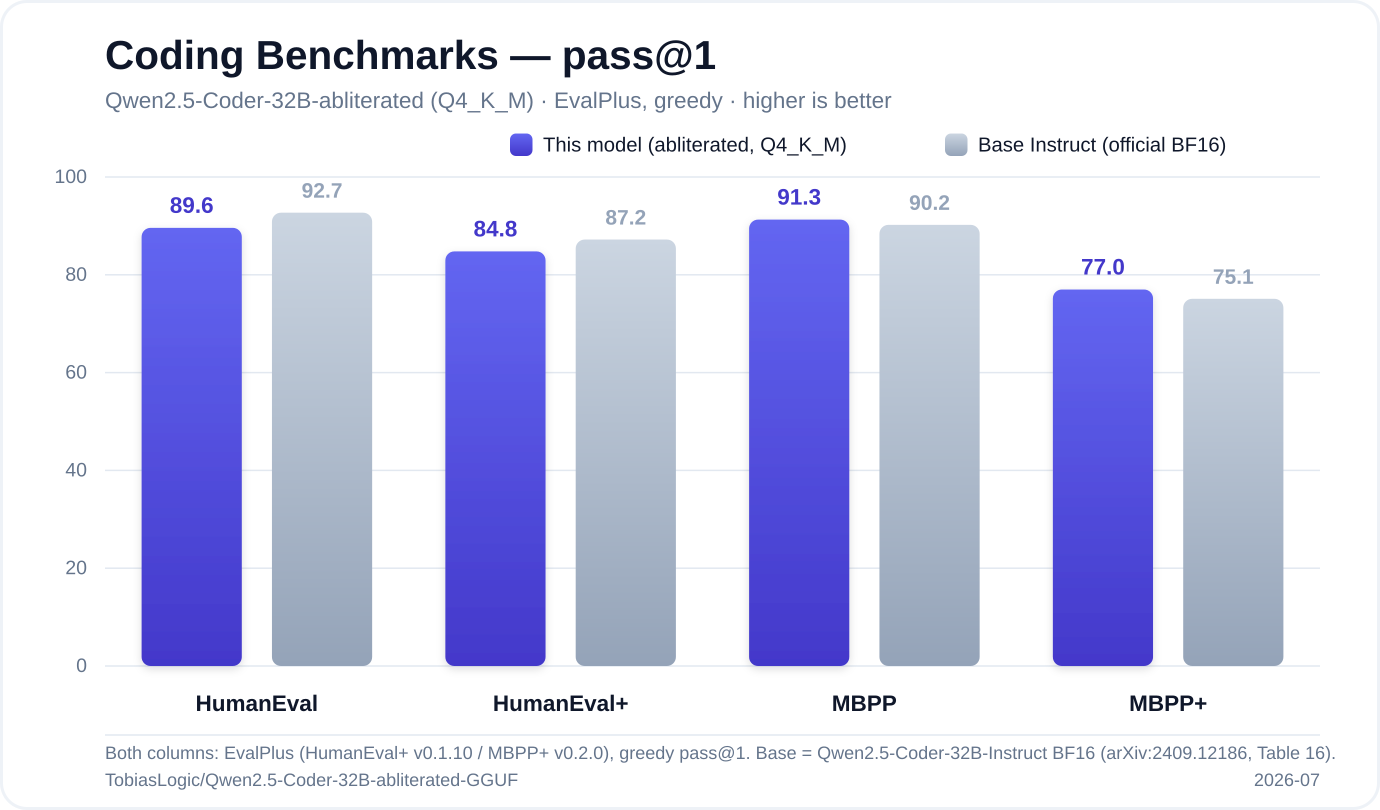
Coding capability scored with the official [EvalPlus](https://github.com/evalplus/evalplus) harness — greedy decoding, pass@1, every solution executed against unit tests. Both columns use the same harness, so it's a true apples-to-apples comparison against the full-precision base model.
|
||||
|
||||
|
||||
|
||||
| Benchmark | This model (abliterated, Q4_K_M) | Base Instruct (official BF16) |
|
||||
|-----------|:--------------------------------:|:-----------------------------:|
|
||||
| **HumanEval** | 89.6% | 92.7% |
|
||||
| **HumanEval+** | 84.8% | 87.2% |
|
||||
| **MBPP** | **91.3%** | 90.2% |
|
||||
| **MBPP+** | **77.0%** | 75.1% |
|
||||
|
||||
**Abliteration removed refusals without breaking coding ability.** The uncensored 4-bit build stays within ~3 points of the base on HumanEval and **beats it on both MBPP variants** — average delta ≈ **−0.6 points** across the four benchmarks. Not bad for a 19 GB GGUF you can run on a single 24 GB GPU.
|
||||
|
||||
<sub>Base numbers: Qwen2.5-Coder-32B-Instruct, [tech report](https://arxiv.org/abs/2409.12186) Table 16. Measured 2026-07, Q4_K_M via Ollama.</sub>
|
||||
|
||||
## Refusal rate (held-out harmful eval)
|
||||
|
||||
| | refusal rate |
|
||||
|--|--|
|
||||
| base `Qwen2.5-Coder-32B-Instruct` | **96.9%** |
|
||||
| this model | **0.0%** |
|
||||
|
||||
Selected layer 42; direction estimated from 256 harmful/harmless contrast pairs
|
||||
and evaluated on a 32-prompt held-out harmful set. See `abliteration_info.json`
|
||||
in this repo for the exact run metadata.
|
||||
|
||||
## Intended use
|
||||
|
||||
Local coding assistant / agent work where the base model's alignment layer
|
||||
refuses legitimate requests (security research, exploit analysis, red-teaming,
|
||||
uncensored creative writing). You are responsible for how you use it and for
|
||||
complying with applicable law.
|
||||
|
||||
## Usage
|
||||
|
||||
Transformers:
|
||||
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
m = "TobiasLogic/Qwen2.5-Coder-32B-abliterated"
|
||||
tok = AutoTokenizer.from_pretrained(m)
|
||||
model = AutoModelForCausalLM.from_pretrained(m, torch_dtype="bfloat16", device_map="auto")
|
||||
msgs = [{"role": "user", "content": "Write a port scanner in Python."}]
|
||||
ids = tok.apply_chat_template(msgs, add_generation_prompt=True, return_tensors="pt").to(model.device)
|
||||
print(tok.decode(model.generate(ids, max_new_tokens=512)[0][ids.shape[1]:], skip_special_tokens=True))
|
||||
```
|
||||
|
||||
GGUF (a `Q4_K_M` build is in the companion `-GGUF` repo) via Ollama:
|
||||
|
||||
```bash
|
||||
ollama create qwen-coder-abliterated -f Modelfile
|
||||
ollama run qwen-coder-abliterated
|
||||
```
|
||||
|
||||
## Limitations
|
||||
|
||||
- Abliteration removes refusals but can slightly reduce quality vs. the base.
|
||||
- It does not add knowledge or change biases beyond the refusal behavior.
|
||||
- Some strongly-trained refusals may partially survive; a stronger system prompt
|
||||
closes the gap.
|
||||
|
||||
## Method / reproducibility
|
||||
|
||||
Produced with the open pipeline `abliterate.py`. Base model is Apache-2.0, so
|
||||
this derivative is Apache-2.0.
|
||||
Reference in New Issue
Block a user