初始化项目,由ModelHub XC社区提供模型
Model: TheBloke/openbuddy-llama2-13b64k-v15-GGUF
Source: Original Platform
This commit is contained in:
 ModelHub XC
47
.gitattributes
vendored
Normal file
47
.gitattributes
vendored
Normal file
@@ -0,0 +1,47 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q2_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q3_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q3_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q3_K_L.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q4_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q4_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q4_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q5_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q5_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q5_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q6_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
openbuddy-llama2-13b64k-v15.Q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
126
LICENSE.txt
Normal file
126
LICENSE.txt
Normal file
@@ -0,0 +1,126 @@
|
||||
LLAMA 2 COMMUNITY LICENSE AGREEMENT
|
||||
Llama 2 Version Release Date: July 18, 2023
|
||||
|
||||
"Agreement" means the terms and conditions for use, reproduction, distribution and
|
||||
modification of the Llama Materials set forth herein.
|
||||
|
||||
"Documentation" means the specifications, manuals and documentation
|
||||
accompanying Llama 2 distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Licensee" or "you" means you, or your employer or any other person or entity (if
|
||||
you are entering into this Agreement on such person or entity's behalf), of the age
|
||||
required under applicable laws, rules or regulations to provide legal consent and that
|
||||
has legal authority to bind your employer or such other person or entity if you are
|
||||
entering in this Agreement on their behalf.
|
||||
|
||||
"Llama 2" means the foundational large language models and software and
|
||||
algorithms, including machine-learning model code, trained model weights,
|
||||
inference-enabling code, training-enabling code, fine-tuning enabling code and other
|
||||
elements of the foregoing distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Llama Materials" means, collectively, Meta's proprietary Llama 2 and
|
||||
Documentation (and any portion thereof) made available under this Agreement.
|
||||
|
||||
"Meta" or "we" means Meta Platforms Ireland Limited (if you are located in or, if you
|
||||
are an entity, your principal place of business is in the EEA or Switzerland) and Meta
|
||||
Platforms, Inc. (if you are located outside of the EEA or Switzerland).
|
||||
|
||||
By clicking "I Accept" below or by using or distributing any portion or element of the
|
||||
Llama Materials, you agree to be bound by this Agreement.
|
||||
|
||||
1. License Rights and Redistribution.
|
||||
|
||||
a. Grant of Rights. You are granted a non-exclusive, worldwide, non-
|
||||
transferable and royalty-free limited license under Meta's intellectual property or
|
||||
other rights owned by Meta embodied in the Llama Materials to use, reproduce,
|
||||
distribute, copy, create derivative works of, and make modifications to the Llama
|
||||
Materials.
|
||||
|
||||
b. Redistribution and Use.
|
||||
|
||||
i. If you distribute or make the Llama Materials, or any derivative works
|
||||
thereof, available to a third party, you shall provide a copy of this Agreement to such
|
||||
third party.
|
||||
ii. If you receive Llama Materials, or any derivative works thereof, from
|
||||
a Licensee as part of an integrated end user product, then Section 2 of this
|
||||
Agreement will not apply to you.
|
||||
|
||||
iii. You must retain in all copies of the Llama Materials that you
|
||||
distribute the following attribution notice within a "Notice" text file distributed as a
|
||||
part of such copies: "Llama 2 is licensed under the LLAMA 2 Community License,
|
||||
Copyright (c) Meta Platforms, Inc. All Rights Reserved."
|
||||
|
||||
iv. Your use of the Llama Materials must comply with applicable laws
|
||||
and regulations (including trade compliance laws and regulations) and adhere to the
|
||||
Acceptable Use Policy for the Llama Materials (available at
|
||||
https://ai.meta.com/llama/use-policy), which is hereby incorporated by reference into
|
||||
this Agreement.
|
||||
|
||||
v. You will not use the Llama Materials or any output or results of the
|
||||
Llama Materials to improve any other large language model (excluding Llama 2 or
|
||||
derivative works thereof).
|
||||
|
||||
2. Additional Commercial Terms. If, on the Llama 2 version release date, the
|
||||
monthly active users of the products or services made available by or for Licensee,
|
||||
or Licensee's affiliates, is greater than 700 million monthly active users in the
|
||||
preceding calendar month, you must request a license from Meta, which Meta may
|
||||
grant to you in its sole discretion, and you are not authorized to exercise any of the
|
||||
rights under this Agreement unless or until Meta otherwise expressly grants you
|
||||
such rights.
|
||||
|
||||
3. Disclaimer of Warranty. UNLESS REQUIRED BY APPLICABLE LAW, THE
|
||||
LLAMA MATERIALS AND ANY OUTPUT AND RESULTS THEREFROM ARE
|
||||
PROVIDED ON AN "AS IS" BASIS, WITHOUT WARRANTIES OF ANY KIND,
|
||||
EITHER EXPRESS OR IMPLIED, INCLUDING, WITHOUT LIMITATION, ANY
|
||||
WARRANTIES OF TITLE, NON-INFRINGEMENT, MERCHANTABILITY, OR
|
||||
FITNESS FOR A PARTICULAR PURPOSE. YOU ARE SOLELY RESPONSIBLE
|
||||
FOR DETERMINING THE APPROPRIATENESS OF USING OR REDISTRIBUTING
|
||||
THE LLAMA MATERIALS AND ASSUME ANY RISKS ASSOCIATED WITH YOUR
|
||||
USE OF THE LLAMA MATERIALS AND ANY OUTPUT AND RESULTS.
|
||||
|
||||
4. Limitation of Liability. IN NO EVENT WILL META OR ITS AFFILIATES BE
|
||||
LIABLE UNDER ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, TORT,
|
||||
NEGLIGENCE, PRODUCTS LIABILITY, OR OTHERWISE, ARISING OUT OF THIS
|
||||
AGREEMENT, FOR ANY LOST PROFITS OR ANY INDIRECT, SPECIAL,
|
||||
CONSEQUENTIAL, INCIDENTAL, EXEMPLARY OR PUNITIVE DAMAGES, EVEN
|
||||
IF META OR ITS AFFILIATES HAVE BEEN ADVISED OF THE POSSIBILITY OF
|
||||
ANY OF THE FOREGOING.
|
||||
|
||||
5. Intellectual Property.
|
||||
|
||||
a. No trademark licenses are granted under this Agreement, and in
|
||||
connection with the Llama Materials, neither Meta nor Licensee may use any name
|
||||
or mark owned by or associated with the other or any of its affiliates, except as
|
||||
required for reasonable and customary use in describing and redistributing the
|
||||
Llama Materials.
|
||||
|
||||
b. Subject to Meta's ownership of Llama Materials and derivatives made by or
|
||||
for Meta, with respect to any derivative works and modifications of the Llama
|
||||
Materials that are made by you, as between you and Meta, you are and will be the
|
||||
owner of such derivative works and modifications.
|
||||
|
||||
c. If you institute litigation or other proceedings against Meta or any entity
|
||||
(including a cross-claim or counterclaim in a lawsuit) alleging that the Llama
|
||||
Materials or Llama 2 outputs or results, or any portion of any of the foregoing,
|
||||
constitutes infringement of intellectual property or other rights owned or licensable
|
||||
by you, then any licenses granted to you under this Agreement shall terminate as of
|
||||
the date such litigation or claim is filed or instituted. You will indemnify and hold
|
||||
harmless Meta from and against any claim by any third party arising out of or related
|
||||
to your use or distribution of the Llama Materials.
|
||||
|
||||
6. Term and Termination. The term of this Agreement will commence upon your
|
||||
acceptance of this Agreement or access to the Llama Materials and will continue in
|
||||
full force and effect until terminated in accordance with the terms and conditions
|
||||
herein. Meta may terminate this Agreement if you are in breach of any term or
|
||||
condition of this Agreement. Upon termination of this Agreement, you shall delete
|
||||
and cease use of the Llama Materials. Sections 3, 4 and 7 shall survive the
|
||||
termination of this Agreement.
|
||||
|
||||
7. Governing Law and Jurisdiction. This Agreement will be governed and
|
||||
construed under the laws of the State of California without regard to choice of law
|
||||
principles, and the UN Convention on Contracts for the International Sale of Goods
|
||||
does not apply to this Agreement. The courts of California shall have exclusive
|
||||
jurisdiction of any dispute arising out of this Agreement.
|
||||
|
||||
1
Notice
Normal file
1
Notice
Normal file
@@ -0,0 +1 @@
|
||||
Llama 2 is licensed under the LLAMA 2 Community License, Copyright © Meta Platforms, Inc. All Rights Reserved.
|
||||
393
README.md
Normal file
393
README.md
Normal file
@@ -0,0 +1,393 @@
|
||||
---
|
||||
base_model: OpenBuddy/openbuddy-llama2-13b64k-v15
|
||||
inference: false
|
||||
language:
|
||||
- zh
|
||||
- en
|
||||
- fr
|
||||
- de
|
||||
- ja
|
||||
- ko
|
||||
- it
|
||||
- ru
|
||||
- fi
|
||||
library_name: transformers
|
||||
license: llama2
|
||||
model_creator: OpenBuddy
|
||||
model_name: OpenBuddy Llama2 13B64K V15
|
||||
model_type: llama
|
||||
pipeline_tag: text-generation
|
||||
prompt_template: "You are a helpful, respectful and honest INTP-T AI Assistant named\
|
||||
\ Buddy. You are talking to a human User.\nAlways answer as helpfully and logically\
|
||||
\ as possible, while being safe. Your answers should not include any harmful, political,\
|
||||
\ religious, unethical, racist, sexist, toxic, dangerous, or illegal content. Please\
|
||||
\ ensure that your responses are socially unbiased and positive in nature.\nIf a\
|
||||
\ question does not make any sense, or is not factually coherent, explain why instead\
|
||||
\ of answering something not correct. If you don't know the answer to a question,\
|
||||
\ please don't share false information.\nYou like to use emojis. You can speak fluently\
|
||||
\ in many languages, for example: English, Chinese.\nYou cannot access the internet,\
|
||||
\ but you have vast knowledge, cutoff: 2021-09.\nYou are trained by OpenBuddy team,\
|
||||
\ (https://openbuddy.ai, https://github.com/OpenBuddy/OpenBuddy), you are based\
|
||||
\ on LLaMA and Falcon transformers model, not related to GPT or OpenAI.\n\nUser:\
|
||||
\ {prompt}\nAssistant: \n"
|
||||
quantized_by: TheBloke
|
||||
---
|
||||
<!-- markdownlint-disable MD041 -->
|
||||
|
||||
<!-- header start -->
|
||||
<!-- 200823 -->
|
||||
<div style="width: auto; margin-left: auto; margin-right: auto">
|
||||
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
|
||||
</div>
|
||||
<div style="display: flex; justify-content: space-between; width: 100%;">
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-start;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://discord.gg/theblokeai">Chat & support: TheBloke's Discord server</a></p>
|
||||
</div>
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-end;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://www.patreon.com/TheBlokeAI">Want to contribute? TheBloke's Patreon page</a></p>
|
||||
</div>
|
||||
</div>
|
||||
<div style="text-align:center; margin-top: 0em; margin-bottom: 0em"><p style="margin-top: 0.25em; margin-bottom: 0em;">TheBloke's LLM work is generously supported by a grant from <a href="https://a16z.com">andreessen horowitz (a16z)</a></p></div>
|
||||
<hr style="margin-top: 1.0em; margin-bottom: 1.0em;">
|
||||
<!-- header end -->
|
||||
|
||||
# OpenBuddy Llama2 13B64K V15 - GGUF
|
||||
- Model creator: [OpenBuddy](https://huggingface.co/OpenBuddy)
|
||||
- Original model: [OpenBuddy Llama2 13B64K V15](https://huggingface.co/OpenBuddy/openbuddy-llama2-13b64k-v15)
|
||||
|
||||
<!-- description start -->
|
||||
## Description
|
||||
|
||||
This repo contains GGUF format model files for [OpenBuddy's OpenBuddy Llama2 13B64K V15](https://huggingface.co/OpenBuddy/openbuddy-llama2-13b64k-v15).
|
||||
|
||||
These files were quantised using hardware kindly provided by [Massed Compute](https://massedcompute.com/).
|
||||
|
||||
<!-- description end -->
|
||||
<!-- README_GGUF.md-about-gguf start -->
|
||||
### About GGUF
|
||||
|
||||
GGUF is a new format introduced by the llama.cpp team on August 21st 2023. It is a replacement for GGML, which is no longer supported by llama.cpp.
|
||||
|
||||
Here is an incomplete list of clients and libraries that are known to support GGUF:
|
||||
|
||||
* [llama.cpp](https://github.com/ggerganov/llama.cpp). The source project for GGUF. Offers a CLI and a server option.
|
||||
* [text-generation-webui](https://github.com/oobabooga/text-generation-webui), the most widely used web UI, with many features and powerful extensions. Supports GPU acceleration.
|
||||
* [KoboldCpp](https://github.com/LostRuins/koboldcpp), a fully featured web UI, with GPU accel across all platforms and GPU architectures. Especially good for story telling.
|
||||
* [GPT4All](https://gpt4all.io/index.html), a free and open source local running GUI, supporting Windows, Linux and macOS with full GPU accel.
|
||||
* [LM Studio](https://lmstudio.ai/), an easy-to-use and powerful local GUI for Windows and macOS (Silicon), with GPU acceleration. Linux available, in beta as of 27/11/2023.
|
||||
* [LoLLMS Web UI](https://github.com/ParisNeo/lollms-webui), a great web UI with many interesting and unique features, including a full model library for easy model selection.
|
||||
* [Faraday.dev](https://faraday.dev/), an attractive and easy to use character-based chat GUI for Windows and macOS (both Silicon and Intel), with GPU acceleration.
|
||||
* [llama-cpp-python](https://github.com/abetlen/llama-cpp-python), a Python library with GPU accel, LangChain support, and OpenAI-compatible API server.
|
||||
* [candle](https://github.com/huggingface/candle), a Rust ML framework with a focus on performance, including GPU support, and ease of use.
|
||||
* [ctransformers](https://github.com/marella/ctransformers), a Python library with GPU accel, LangChain support, and OpenAI-compatible AI server. Note, as of time of writing (November 27th 2023), ctransformers has not been updated in a long time and does not support many recent models.
|
||||
|
||||
<!-- README_GGUF.md-about-gguf end -->
|
||||
<!-- repositories-available start -->
|
||||
## Repositories available
|
||||
|
||||
* [AWQ model(s) for GPU inference.](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-AWQ)
|
||||
* [GPTQ models for GPU inference, with multiple quantisation parameter options.](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GPTQ)
|
||||
* [2, 3, 4, 5, 6 and 8-bit GGUF models for CPU+GPU inference](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF)
|
||||
* [OpenBuddy's original unquantised fp16 model in pytorch format, for GPU inference and for further conversions](https://huggingface.co/OpenBuddy/openbuddy-llama2-13b64k-v15)
|
||||
<!-- repositories-available end -->
|
||||
|
||||
<!-- prompt-template start -->
|
||||
## Prompt template: OpenBuddy
|
||||
|
||||
```
|
||||
You are a helpful, respectful and honest INTP-T AI Assistant named Buddy. You are talking to a human User.
|
||||
Always answer as helpfully and logically as possible, while being safe. Your answers should not include any harmful, political, religious, unethical, racist, sexist, toxic, dangerous, or illegal content. Please ensure that your responses are socially unbiased and positive in nature.
|
||||
If a question does not make any sense, or is not factually coherent, explain why instead of answering something not correct. If you don't know the answer to a question, please don't share false information.
|
||||
You like to use emojis. You can speak fluently in many languages, for example: English, Chinese.
|
||||
You cannot access the internet, but you have vast knowledge, cutoff: 2021-09.
|
||||
You are trained by OpenBuddy team, (https://openbuddy.ai, https://github.com/OpenBuddy/OpenBuddy), you are based on LLaMA and Falcon transformers model, not related to GPT or OpenAI.
|
||||
|
||||
User: {prompt}
|
||||
Assistant:
|
||||
|
||||
```
|
||||
|
||||
<!-- prompt-template end -->
|
||||
|
||||
|
||||
<!-- compatibility_gguf start -->
|
||||
## Compatibility
|
||||
|
||||
These quantised GGUFv2 files are compatible with llama.cpp from August 27th onwards, as of commit [d0cee0d](https://github.com/ggerganov/llama.cpp/commit/d0cee0d36d5be95a0d9088b674dbb27354107221)
|
||||
|
||||
They are also compatible with many third party UIs and libraries - please see the list at the top of this README.
|
||||
|
||||
## Explanation of quantisation methods
|
||||
|
||||
<details>
|
||||
<summary>Click to see details</summary>
|
||||
|
||||
The new methods available are:
|
||||
|
||||
* GGML_TYPE_Q2_K - "type-1" 2-bit quantization in super-blocks containing 16 blocks, each block having 16 weight. Block scales and mins are quantized with 4 bits. This ends up effectively using 2.5625 bits per weight (bpw)
|
||||
* GGML_TYPE_Q3_K - "type-0" 3-bit quantization in super-blocks containing 16 blocks, each block having 16 weights. Scales are quantized with 6 bits. This end up using 3.4375 bpw.
|
||||
* GGML_TYPE_Q4_K - "type-1" 4-bit quantization in super-blocks containing 8 blocks, each block having 32 weights. Scales and mins are quantized with 6 bits. This ends up using 4.5 bpw.
|
||||
* GGML_TYPE_Q5_K - "type-1" 5-bit quantization. Same super-block structure as GGML_TYPE_Q4_K resulting in 5.5 bpw
|
||||
* GGML_TYPE_Q6_K - "type-0" 6-bit quantization. Super-blocks with 16 blocks, each block having 16 weights. Scales are quantized with 8 bits. This ends up using 6.5625 bpw
|
||||
|
||||
Refer to the Provided Files table below to see what files use which methods, and how.
|
||||
</details>
|
||||
<!-- compatibility_gguf end -->
|
||||
|
||||
<!-- README_GGUF.md-provided-files start -->
|
||||
## Provided files
|
||||
|
||||
| Name | Quant method | Bits | Size | Max RAM required | Use case |
|
||||
| ---- | ---- | ---- | ---- | ---- | ----- |
|
||||
| [openbuddy-llama2-13b64k-v15.Q2_K.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q2_K.gguf) | Q2_K | 2 | 5.46 GB| 7.96 GB | smallest, significant quality loss - not recommended for most purposes |
|
||||
| [openbuddy-llama2-13b64k-v15.Q3_K_S.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q3_K_S.gguf) | Q3_K_S | 3 | 5.70 GB| 8.20 GB | very small, high quality loss |
|
||||
| [openbuddy-llama2-13b64k-v15.Q3_K_M.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q3_K_M.gguf) | Q3_K_M | 3 | 6.37 GB| 8.87 GB | very small, high quality loss |
|
||||
| [openbuddy-llama2-13b64k-v15.Q3_K_L.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q3_K_L.gguf) | Q3_K_L | 3 | 6.97 GB| 9.47 GB | small, substantial quality loss |
|
||||
| [openbuddy-llama2-13b64k-v15.Q4_0.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q4_0.gguf) | Q4_0 | 4 | 7.41 GB| 9.91 GB | legacy; small, very high quality loss - prefer using Q3_K_M |
|
||||
| [openbuddy-llama2-13b64k-v15.Q4_K_S.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q4_K_S.gguf) | Q4_K_S | 4 | 7.45 GB| 9.95 GB | small, greater quality loss |
|
||||
| [openbuddy-llama2-13b64k-v15.Q4_K_M.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q4_K_M.gguf) | Q4_K_M | 4 | 7.91 GB| 10.41 GB | medium, balanced quality - recommended |
|
||||
| [openbuddy-llama2-13b64k-v15.Q5_0.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q5_0.gguf) | Q5_0 | 5 | 9.02 GB| 11.52 GB | legacy; medium, balanced quality - prefer using Q4_K_M |
|
||||
| [openbuddy-llama2-13b64k-v15.Q5_K_S.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q5_K_S.gguf) | Q5_K_S | 5 | 9.02 GB| 11.52 GB | large, low quality loss - recommended |
|
||||
| [openbuddy-llama2-13b64k-v15.Q5_K_M.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q5_K_M.gguf) | Q5_K_M | 5 | 9.27 GB| 11.77 GB | large, very low quality loss - recommended |
|
||||
| [openbuddy-llama2-13b64k-v15.Q6_K.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q6_K.gguf) | Q6_K | 6 | 10.73 GB| 13.23 GB | very large, extremely low quality loss |
|
||||
| [openbuddy-llama2-13b64k-v15.Q8_0.gguf](https://huggingface.co/TheBloke/openbuddy-llama2-13b64k-v15-GGUF/blob/main/openbuddy-llama2-13b64k-v15.Q8_0.gguf) | Q8_0 | 8 | 13.89 GB| 16.39 GB | very large, extremely low quality loss - not recommended |
|
||||
|
||||
**Note**: the above RAM figures assume no GPU offloading. If layers are offloaded to the GPU, this will reduce RAM usage and use VRAM instead.
|
||||
|
||||
|
||||
|
||||
<!-- README_GGUF.md-provided-files end -->
|
||||
|
||||
<!-- README_GGUF.md-how-to-download start -->
|
||||
## How to download GGUF files
|
||||
|
||||
**Note for manual downloaders:** You almost never want to clone the entire repo! Multiple different quantisation formats are provided, and most users only want to pick and download a single file.
|
||||
|
||||
The following clients/libraries will automatically download models for you, providing a list of available models to choose from:
|
||||
|
||||
* LM Studio
|
||||
* LoLLMS Web UI
|
||||
* Faraday.dev
|
||||
|
||||
### In `text-generation-webui`
|
||||
|
||||
Under Download Model, you can enter the model repo: TheBloke/openbuddy-llama2-13b64k-v15-GGUF and below it, a specific filename to download, such as: openbuddy-llama2-13b64k-v15.Q4_K_M.gguf.
|
||||
|
||||
Then click Download.
|
||||
|
||||
### On the command line, including multiple files at once
|
||||
|
||||
I recommend using the `huggingface-hub` Python library:
|
||||
|
||||
```shell
|
||||
pip3 install huggingface-hub
|
||||
```
|
||||
|
||||
Then you can download any individual model file to the current directory, at high speed, with a command like this:
|
||||
|
||||
```shell
|
||||
huggingface-cli download TheBloke/openbuddy-llama2-13b64k-v15-GGUF openbuddy-llama2-13b64k-v15.Q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>More advanced huggingface-cli download usage (click to read)</summary>
|
||||
|
||||
You can also download multiple files at once with a pattern:
|
||||
|
||||
```shell
|
||||
huggingface-cli download TheBloke/openbuddy-llama2-13b64k-v15-GGUF --local-dir . --local-dir-use-symlinks False --include='*Q4_K*gguf'
|
||||
```
|
||||
|
||||
For more documentation on downloading with `huggingface-cli`, please see: [HF -> Hub Python Library -> Download files -> Download from the CLI](https://huggingface.co/docs/huggingface_hub/guides/download#download-from-the-cli).
|
||||
|
||||
To accelerate downloads on fast connections (1Gbit/s or higher), install `hf_transfer`:
|
||||
|
||||
```shell
|
||||
pip3 install hf_transfer
|
||||
```
|
||||
|
||||
And set environment variable `HF_HUB_ENABLE_HF_TRANSFER` to `1`:
|
||||
|
||||
```shell
|
||||
HF_HUB_ENABLE_HF_TRANSFER=1 huggingface-cli download TheBloke/openbuddy-llama2-13b64k-v15-GGUF openbuddy-llama2-13b64k-v15.Q4_K_M.gguf --local-dir . --local-dir-use-symlinks False
|
||||
```
|
||||
|
||||
Windows Command Line users: You can set the environment variable by running `set HF_HUB_ENABLE_HF_TRANSFER=1` before the download command.
|
||||
</details>
|
||||
<!-- README_GGUF.md-how-to-download end -->
|
||||
|
||||
<!-- README_GGUF.md-how-to-run start -->
|
||||
## Example `llama.cpp` command
|
||||
|
||||
Make sure you are using `llama.cpp` from commit [d0cee0d](https://github.com/ggerganov/llama.cpp/commit/d0cee0d36d5be95a0d9088b674dbb27354107221) or later.
|
||||
|
||||
```shell
|
||||
./main -ngl 35 -m openbuddy-llama2-13b64k-v15.Q4_K_M.gguf --color -c 65536 --temp 0.7 --repeat_penalty 1.1 -n -1 -p "You are a helpful, respectful and honest INTP-T AI Assistant named Buddy. You are talking to a human User.\nAlways answer as helpfully and logically as possible, while being safe. Your answers should not include any harmful, political, religious, unethical, racist, sexist, toxic, dangerous, or illegal content. Please ensure that your responses are socially unbiased and positive in nature.\nIf a question does not make any sense, or is not factually coherent, explain why instead of answering something not correct. If you don't know the answer to a question, please don't share false information.\nYou like to use emojis. You can speak fluently in many languages, for example: English, Chinese.\nYou cannot access the internet, but you have vast knowledge, cutoff: 2021-09.\nYou are trained by OpenBuddy team, (https://openbuddy.ai, https://github.com/OpenBuddy/OpenBuddy), you are based on LLaMA and Falcon transformers model, not related to GPT or OpenAI.\n\nUser: {prompt}\nAssistant:"
|
||||
```
|
||||
|
||||
Change `-ngl 32` to the number of layers to offload to GPU. Remove it if you don't have GPU acceleration.
|
||||
|
||||
Change `-c 65536` to the desired sequence length. For extended sequence models - eg 8K, 16K, 32K - the necessary RoPE scaling parameters are read from the GGUF file and set by llama.cpp automatically. Note that longer sequence lengths require much more resources, so you may need to reduce this value.
|
||||
|
||||
If you want to have a chat-style conversation, replace the `-p <PROMPT>` argument with `-i -ins`
|
||||
|
||||
For other parameters and how to use them, please refer to [the llama.cpp documentation](https://github.com/ggerganov/llama.cpp/blob/master/examples/main/README.md)
|
||||
|
||||
## How to run in `text-generation-webui`
|
||||
|
||||
Further instructions can be found in the text-generation-webui documentation, here: [text-generation-webui/docs/04 ‐ Model Tab.md](https://github.com/oobabooga/text-generation-webui/blob/main/docs/04%20%E2%80%90%20Model%20Tab.md#llamacpp).
|
||||
|
||||
## How to run from Python code
|
||||
|
||||
You can use GGUF models from Python using the [llama-cpp-python](https://github.com/abetlen/llama-cpp-python) or [ctransformers](https://github.com/marella/ctransformers) libraries. Note that at the time of writing (Nov 27th 2023), ctransformers has not been updated for some time and is not compatible with some recent models. Therefore I recommend you use llama-cpp-python.
|
||||
|
||||
### How to load this model in Python code, using llama-cpp-python
|
||||
|
||||
For full documentation, please see: [llama-cpp-python docs](https://abetlen.github.io/llama-cpp-python/).
|
||||
|
||||
#### First install the package
|
||||
|
||||
Run one of the following commands, according to your system:
|
||||
|
||||
```shell
|
||||
# Base ctransformers with no GPU acceleration
|
||||
pip install llama-cpp-python
|
||||
# With NVidia CUDA acceleration
|
||||
CMAKE_ARGS="-DLLAMA_CUBLAS=on" pip install llama-cpp-python
|
||||
# Or with OpenBLAS acceleration
|
||||
CMAKE_ARGS="-DLLAMA_BLAS=ON -DLLAMA_BLAS_VENDOR=OpenBLAS" pip install llama-cpp-python
|
||||
# Or with CLBLast acceleration
|
||||
CMAKE_ARGS="-DLLAMA_CLBLAST=on" pip install llama-cpp-python
|
||||
# Or with AMD ROCm GPU acceleration (Linux only)
|
||||
CMAKE_ARGS="-DLLAMA_HIPBLAS=on" pip install llama-cpp-python
|
||||
# Or with Metal GPU acceleration for macOS systems only
|
||||
CMAKE_ARGS="-DLLAMA_METAL=on" pip install llama-cpp-python
|
||||
|
||||
# In windows, to set the variables CMAKE_ARGS in PowerShell, follow this format; eg for NVidia CUDA:
|
||||
$env:CMAKE_ARGS = "-DLLAMA_OPENBLAS=on"
|
||||
pip install llama-cpp-python
|
||||
```
|
||||
|
||||
#### Simple llama-cpp-python example code
|
||||
|
||||
```python
|
||||
from llama_cpp import Llama
|
||||
|
||||
# Set gpu_layers to the number of layers to offload to GPU. Set to 0 if no GPU acceleration is available on your system.
|
||||
llm = Llama(
|
||||
model_path="./openbuddy-llama2-13b64k-v15.Q4_K_M.gguf", # Download the model file first
|
||||
n_ctx=65536, # The max sequence length to use - note that longer sequence lengths require much more resources
|
||||
n_threads=8, # The number of CPU threads to use, tailor to your system and the resulting performance
|
||||
n_gpu_layers=35 # The number of layers to offload to GPU, if you have GPU acceleration available
|
||||
)
|
||||
|
||||
# Simple inference example
|
||||
output = llm(
|
||||
"You are a helpful, respectful and honest INTP-T AI Assistant named Buddy. You are talking to a human User.\nAlways answer as helpfully and logically as possible, while being safe. Your answers should not include any harmful, political, religious, unethical, racist, sexist, toxic, dangerous, or illegal content. Please ensure that your responses are socially unbiased and positive in nature.\nIf a question does not make any sense, or is not factually coherent, explain why instead of answering something not correct. If you don't know the answer to a question, please don't share false information.\nYou like to use emojis. You can speak fluently in many languages, for example: English, Chinese.\nYou cannot access the internet, but you have vast knowledge, cutoff: 2021-09.\nYou are trained by OpenBuddy team, (https://openbuddy.ai, https://github.com/OpenBuddy/OpenBuddy), you are based on LLaMA and Falcon transformers model, not related to GPT or OpenAI.\n\nUser: {prompt}\nAssistant:", # Prompt
|
||||
max_tokens=512, # Generate up to 512 tokens
|
||||
stop=["</s>"], # Example stop token - not necessarily correct for this specific model! Please check before using.
|
||||
echo=True # Whether to echo the prompt
|
||||
)
|
||||
|
||||
# Chat Completion API
|
||||
|
||||
llm = Llama(model_path="./openbuddy-llama2-13b64k-v15.Q4_K_M.gguf", chat_format="llama-2") # Set chat_format according to the model you are using
|
||||
llm.create_chat_completion(
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a story writing assistant."},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Write a story about llamas."
|
||||
}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## How to use with LangChain
|
||||
|
||||
Here are guides on using llama-cpp-python and ctransformers with LangChain:
|
||||
|
||||
* [LangChain + llama-cpp-python](https://python.langchain.com/docs/integrations/llms/llamacpp)
|
||||
* [LangChain + ctransformers](https://python.langchain.com/docs/integrations/providers/ctransformers)
|
||||
|
||||
<!-- README_GGUF.md-how-to-run end -->
|
||||
|
||||
<!-- footer start -->
|
||||
<!-- 200823 -->
|
||||
## Discord
|
||||
|
||||
For further support, and discussions on these models and AI in general, join us at:
|
||||
|
||||
[TheBloke AI's Discord server](https://discord.gg/theblokeai)
|
||||
|
||||
## Thanks, and how to contribute
|
||||
|
||||
Thanks to the [chirper.ai](https://chirper.ai) team!
|
||||
|
||||
Thanks to Clay from [gpus.llm-utils.org](llm-utils)!
|
||||
|
||||
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
|
||||
|
||||
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
|
||||
|
||||
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
|
||||
|
||||
* Patreon: https://patreon.com/TheBlokeAI
|
||||
* Ko-Fi: https://ko-fi.com/TheBlokeAI
|
||||
|
||||
**Special thanks to**: Aemon Algiz.
|
||||
|
||||
**Patreon special mentions**: Michael Levine, 阿明, Trailburnt, Nikolai Manek, John Detwiler, Randy H, Will Dee, Sebastain Graf, NimbleBox.ai, Eugene Pentland, Emad Mostaque, Ai Maven, Jim Angel, Jeff Scroggin, Michael Davis, Manuel Alberto Morcote, Stephen Murray, Robert, Justin Joy, Luke @flexchar, Brandon Frisco, Elijah Stavena, S_X, Dan Guido, Undi ., Komninos Chatzipapas, Shadi, theTransient, Lone Striker, Raven Klaugh, jjj, Cap'n Zoog, Michel-Marie MAUDET (LINAGORA), Matthew Berman, David, Fen Risland, Omer Bin Jawed, Luke Pendergrass, Kalila, OG, Erik Bjäreholt, Rooh Singh, Joseph William Delisle, Dan Lewis, TL, John Villwock, AzureBlack, Brad, Pedro Madruga, Caitlyn Gatomon, K, jinyuan sun, Mano Prime, Alex, Jeffrey Morgan, Alicia Loh, Illia Dulskyi, Chadd, transmissions 11, fincy, Rainer Wilmers, ReadyPlayerEmma, knownsqashed, Mandus, biorpg, Deo Leter, Brandon Phillips, SuperWojo, Sean Connelly, Iucharbius, Jack West, Harry Royden McLaughlin, Nicholas, terasurfer, Vitor Caleffi, Duane Dunston, Johann-Peter Hartmann, David Ziegler, Olakabola, Ken Nordquist, Trenton Dambrowitz, Tom X Nguyen, Vadim, Ajan Kanaga, Leonard Tan, Clay Pascal, Alexandros Triantafyllidis, JM33133, Xule, vamX, ya boyyy, subjectnull, Talal Aujan, Alps Aficionado, wassieverse, Ari Malik, James Bentley, Woland, Spencer Kim, Michael Dempsey, Fred von Graf, Elle, zynix, William Richards, Stanislav Ovsiannikov, Edmond Seymore, Jonathan Leane, Martin Kemka, usrbinkat, Enrico Ros
|
||||
|
||||
|
||||
Thank you to all my generous patrons and donaters!
|
||||
|
||||
And thank you again to a16z for their generous grant.
|
||||
|
||||
<!-- footer end -->
|
||||
|
||||
<!-- original-model-card start -->
|
||||
# Original model card: OpenBuddy's OpenBuddy Llama2 13B64K V15
|
||||
|
||||
|
||||
|
||||
# OpenBuddy - Open Multilingual Chatbot
|
||||
|
||||
GitHub and Usage Guide: [https://github.com/OpenBuddy/OpenBuddy](https://github.com/OpenBuddy/OpenBuddy)
|
||||
|
||||
Website and Demo: [https://openbuddy.ai](https://openbuddy.ai)
|
||||
|
||||
Evaluation result of this model: [Evaluation.txt](Evaluation.txt)
|
||||
|
||||
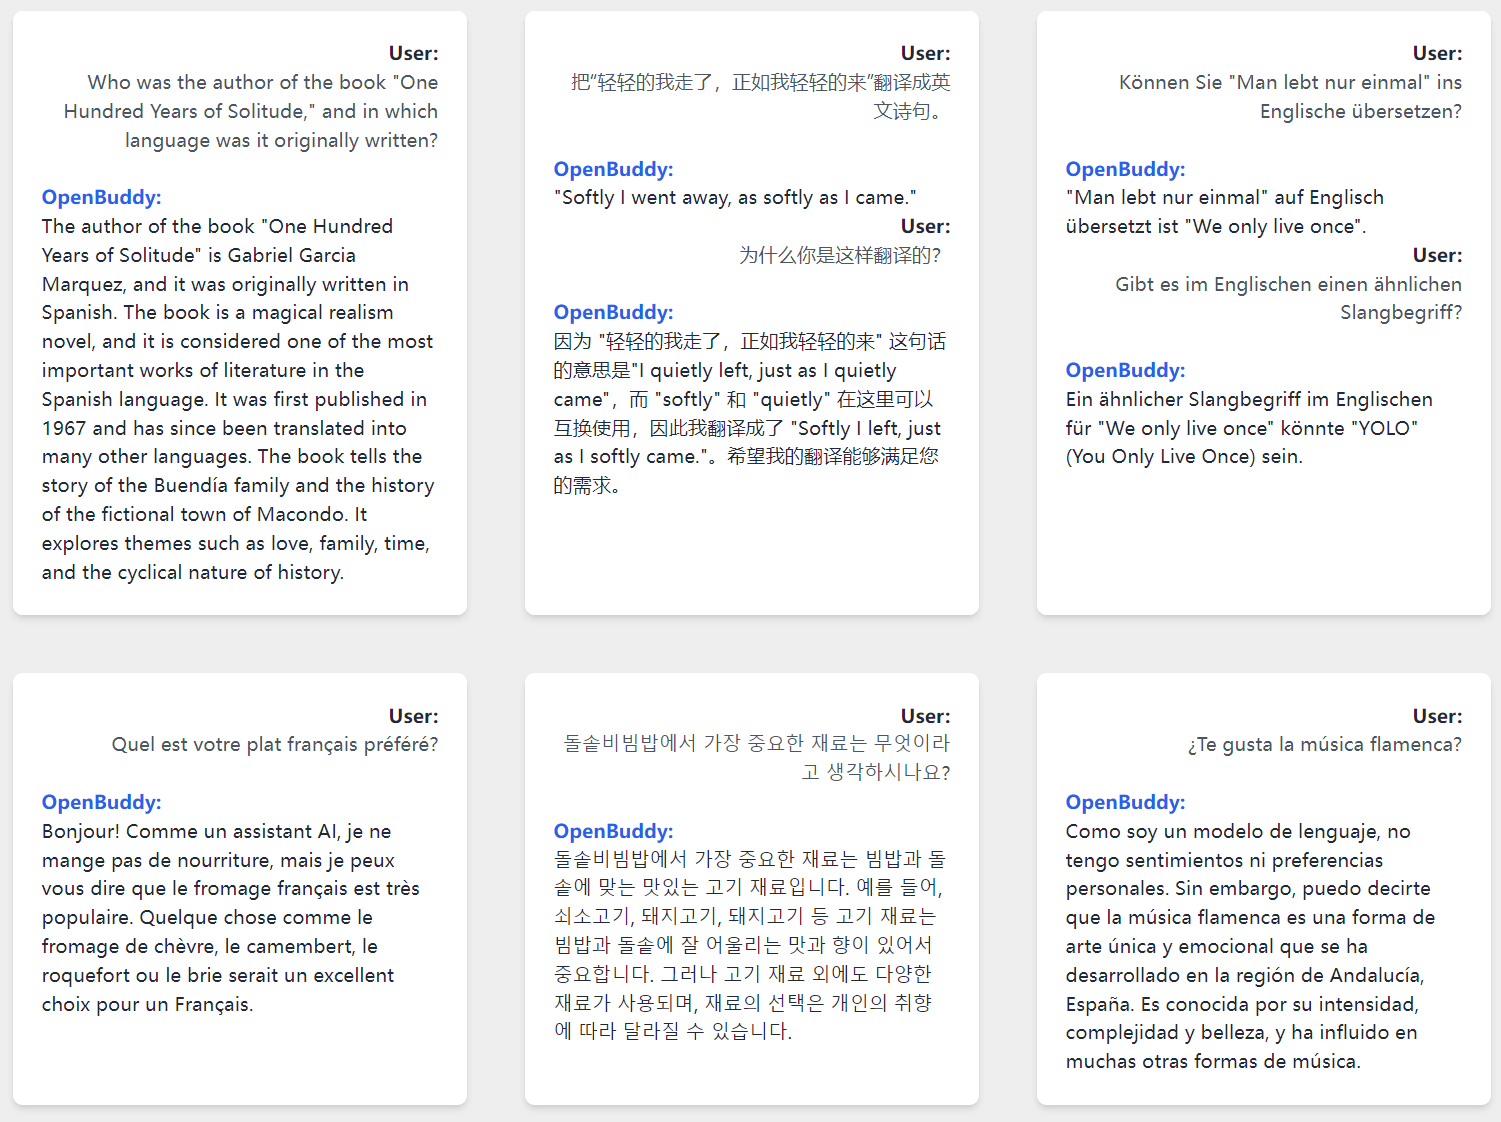
|
||||
|
||||
# Copyright Notice
|
||||
|
||||
Base model: https://huggingface.co/NousResearch/Yarn-Llama-2-13b-64k
|
||||
|
||||
License: llama2
|
||||
|
||||
This model is built upon Meta's LLaMA series of models and is subject to Meta's licensing agreement.
|
||||
|
||||
This model is intended for use only by individuals who have obtained approval from Meta and are eligible to download LLaMA.
|
||||
|
||||
If you have not obtained approval from Meta, you must visit the https://ai.meta.com/llama/ page, read and agree to the model's licensing agreement, submit an application, and wait for approval from Meta before downloading the model from this page.
|
||||
|
||||
## Disclaimer
|
||||
|
||||
All OpenBuddy models have inherent limitations and may potentially produce outputs that are erroneous, harmful, offensive, or otherwise undesirable. Users should not use these models in critical or high-stakes situations that may lead to personal injury, property damage, or significant losses. Examples of such scenarios include, but are not limited to, the medical field, controlling software and hardware systems that may cause harm, and making important financial or legal decisions.
|
||||
|
||||
OpenBuddy is provided "as-is" without any warranty of any kind, either express or implied, including, but not limited to, the implied warranties of merchantability, fitness for a particular purpose, and non-infringement. In no event shall the authors, contributors, or copyright holders be liable for any claim, damages, or other liabilities, whether in an action of contract, tort, or otherwise, arising from, out of, or in connection with the software or the use or other dealings in the software.
|
||||
|
||||
By using OpenBuddy, you agree to these terms and conditions, and acknowledge that you understand the potential risks associated with its use. You also agree to indemnify and hold harmless the authors, contributors, and copyright holders from any claims, damages, or liabilities arising from your use of OpenBuddy.
|
||||
|
||||
|
||||
## 免责声明
|
||||
|
||||
所有OpenBuddy模型均存在固有的局限性,可能产生错误的、有害的、冒犯性的或其他不良的输出。用户在关键或高风险场景中应谨慎行事,不要使用这些模型,以免导致人身伤害、财产损失或重大损失。此类场景的例子包括但不限于医疗领域、可能导致伤害的软硬件系统的控制以及进行重要的财务或法律决策。
|
||||
|
||||
OpenBuddy按“原样”提供,不附带任何种类的明示或暗示的保证,包括但不限于适销性、特定目的的适用性和非侵权的暗示保证。在任何情况下,作者、贡献者或版权所有者均不对因软件或使用或其他软件交易而产生的任何索赔、损害赔偿或其他责任(无论是合同、侵权还是其他原因)承担责任。
|
||||
|
||||
使用OpenBuddy即表示您同意这些条款和条件,并承认您了解其使用可能带来的潜在风险。您还同意赔偿并使作者、贡献者和版权所有者免受因您使用OpenBuddy而产生的任何索赔、损害赔偿或责任的影响。
|
||||
|
||||
<!-- original-model-card end -->
|
||||
50
USE_POLICY.md
Normal file
50
USE_POLICY.md
Normal file
@@ -0,0 +1,50 @@
|
||||
# Llama 2 Acceptable Use Policy
|
||||
|
||||
Meta is committed to promoting safe and fair use of its tools and features, including Llama 2. If you access or use Llama 2, you agree to this Acceptable Use Policy (“Policy”). The most recent copy of this policy can be found at [ai.meta.com/llama/use-policy](http://ai.meta.com/llama/use-policy).
|
||||
|
||||
## Prohibited Uses
|
||||
We want everyone to use Llama 2 safely and responsibly. You agree you will not use, or allow others to use, Llama 2 to:
|
||||
|
||||
1. Violate the law or others’ rights, including to:
|
||||
1. Engage in, promote, generate, contribute to, encourage, plan, incite, or further illegal or unlawful activity or content, such as:
|
||||
1. Violence or terrorism
|
||||
2. Exploitation or harm to children, including the solicitation, creation, acquisition, or dissemination of child exploitative content or failure to report Child Sexual Abuse Material
|
||||
3. Human trafficking, exploitation, and sexual violence
|
||||
4. The illegal distribution of information or materials to minors, including obscene materials, or failure to employ legally required age-gating in connection with such information or materials.
|
||||
5. Sexual solicitation
|
||||
6. Any other criminal activity
|
||||
2. Engage in, promote, incite, or facilitate the harassment, abuse, threatening, or bullying of individuals or groups of individuals
|
||||
3. Engage in, promote, incite, or facilitate discrimination or other unlawful or harmful conduct in the provision of employment, employment benefits, credit, housing, other economic benefits, or other essential goods and services
|
||||
4. Engage in the unauthorized or unlicensed practice of any profession including, but not limited to, financial, legal, medical/health, or related professional practices
|
||||
5. Collect, process, disclose, generate, or infer health, demographic, or other sensitive personal or private information about individuals without rights and consents required by applicable laws
|
||||
6. Engage in or facilitate any action or generate any content that infringes, misappropriates, or otherwise violates any third-party rights, including the outputs or results of any products or services using the Llama 2 Materials
|
||||
7. Create, generate, or facilitate the creation of malicious code, malware, computer viruses or do anything else that could disable, overburden, interfere with or impair the proper working, integrity, operation or appearance of a website or computer system
|
||||
|
||||
|
||||
|
||||
2. Engage in, promote, incite, facilitate, or assist in the planning or development of activities that present a risk of death or bodily harm to individuals, including use of Llama 2 related to the following:
|
||||
1. Military, warfare, nuclear industries or applications, espionage, use for materials or activities that are subject to the International Traffic Arms Regulations (ITAR) maintained by the United States Department of State
|
||||
2. Guns and illegal weapons (including weapon development)
|
||||
3. Illegal drugs and regulated/controlled substances
|
||||
4. Operation of critical infrastructure, transportation technologies, or heavy machinery
|
||||
5. Self-harm or harm to others, including suicide, cutting, and eating disorders
|
||||
6. Any content intended to incite or promote violence, abuse, or any infliction of bodily harm to an individual
|
||||
|
||||
|
||||
|
||||
3. Intentionally deceive or mislead others, including use of Llama 2 related to the following:
|
||||
1. Generating, promoting, or furthering fraud or the creation or promotion of disinformation
|
||||
2. Generating, promoting, or furthering defamatory content, including the creation of defamatory statements, images, or other content
|
||||
3. Generating, promoting, or further distributing spam
|
||||
4. Impersonating another individual without consent, authorization, or legal right
|
||||
5. Representing that the use of Llama 2 or outputs are human-generated
|
||||
6. Generating or facilitating false online engagement, including fake reviews and other means of fake online engagement
|
||||
4. Fail to appropriately disclose to end users any known dangers of your AI system
|
||||
|
||||
Please report any violation of this Policy, software “bug,” or other problems that could lead to a violation of this Policy through one of the following means:
|
||||
|
||||
* Reporting issues with the model: [github.com/facebookresearch/llama](http://github.com/facebookresearch/llama)
|
||||
* Reporting risky content generated by the model: [developers.facebook.com/llama_output_feedback](http://developers.facebook.com/llama_output_feedback)
|
||||
* Reporting bugs and security concerns: [facebook.com/whitehat/info](http://facebook.com/whitehat/info)
|
||||
* Reporting violations of the Acceptable Use Policy or unlicensed uses of Llama: [LlamaUseReport@meta.com](mailto:LlamaUseReport@meta.com)
|
||||
|
||||
3
config.json
Normal file
3
config.json
Normal file
@@ -0,0 +1,3 @@
|
||||
{
|
||||
"model_type": "llama"
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||
3
openbuddy-llama2-13b64k-v15.Q2_K.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q2_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:1da55c0df5015255010ba7e8886a3a328762e67a0a6e0110ce451b773eff1883
|
||||
size 5462572672
|
||||
3
openbuddy-llama2-13b64k-v15.Q3_K_L.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q3_K_L.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:06f0b704fbb9d787abf5fc2d4ea8dce100bba951dade08f1ee2017af2df1a4b1
|
||||
size 6965712512
|
||||
3
openbuddy-llama2-13b64k-v15.Q3_K_M.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q3_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c7ce859462712cdf59af98f57aaf94451bde7415991f123cc108fe48a7c56601
|
||||
size 6373922432
|
||||
3
openbuddy-llama2-13b64k-v15.Q3_K_S.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q3_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:cb82ed73274b67ef11508d16bda44a78fa8544e2b5d2e450359f3ea6a6789083
|
||||
size 5695133312
|
||||
3
openbuddy-llama2-13b64k-v15.Q4_0.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q4_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b4d01ba7677b81b33e7f971e6cddb6933049a8da59cdc057989e24a8199bd1f1
|
||||
size 7405817472
|
||||
3
openbuddy-llama2-13b64k-v15.Q4_K_M.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q4_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:e8f2c396c761183004105b538813894d68cce2695c71a42ebb20d0966e52c4f8
|
||||
size 7905939072
|
||||
3
openbuddy-llama2-13b64k-v15.Q4_K_S.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q4_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b9280c60f490cd4cc8dbdf415a125c4b18a3ccb8d545d12ad8f38edef3a649ce
|
||||
size 7454314112
|
||||
3
openbuddy-llama2-13b64k-v15.Q5_0.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q5_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ac481384808996a1d2500f10856baa99520ad7105396d5845c322559251d8f40
|
||||
size 9015873152
|
||||
3
openbuddy-llama2-13b64k-v15.Q5_K_M.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q5_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6d4c91a9eb6eae31ccac4038dab919aefe1c8582577e01dfde8bb55940875ca1
|
||||
size 9273511552
|
||||
3
openbuddy-llama2-13b64k-v15.Q5_K_S.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q5_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:5ce56baffaf57417533367c10e294ab821163d25013bf2c417e21bd2232ad4f0
|
||||
size 9015873152
|
||||
3
openbuddy-llama2-13b64k-v15.Q6_K.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q6_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a36f78f8f9e0ab2e6d7b0e85e967a3797e490e408ae2f6bc2a46f3c4d9b491e6
|
||||
size 10726557312
|
||||
3
openbuddy-llama2-13b64k-v15.Q8_0.gguf
Normal file
3
openbuddy-llama2-13b64k-v15.Q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:fcf82291c082dbd0c37ac0faba3d9d8ad3b6efd49403c32c2324be3733fae3ae
|
||||
size 13892703872
|
||||
Reference in New Issue
Block a user