初始化项目,由ModelHub XC社区提供模型
Model: TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
model.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
126
LICENSE.txt
Normal file
126
LICENSE.txt
Normal file
@@ -0,0 +1,126 @@
|
||||
LLAMA 2 COMMUNITY LICENSE AGREEMENT
|
||||
Llama 2 Version Release Date: July 18, 2023
|
||||
|
||||
"Agreement" means the terms and conditions for use, reproduction, distribution and
|
||||
modification of the Llama Materials set forth herein.
|
||||
|
||||
"Documentation" means the specifications, manuals and documentation
|
||||
accompanying Llama 2 distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Licensee" or "you" means you, or your employer or any other person or entity (if
|
||||
you are entering into this Agreement on such person or entity's behalf), of the age
|
||||
required under applicable laws, rules or regulations to provide legal consent and that
|
||||
has legal authority to bind your employer or such other person or entity if you are
|
||||
entering in this Agreement on their behalf.
|
||||
|
||||
"Llama 2" means the foundational large language models and software and
|
||||
algorithms, including machine-learning model code, trained model weights,
|
||||
inference-enabling code, training-enabling code, fine-tuning enabling code and other
|
||||
elements of the foregoing distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Llama Materials" means, collectively, Meta's proprietary Llama 2 and
|
||||
Documentation (and any portion thereof) made available under this Agreement.
|
||||
|
||||
"Meta" or "we" means Meta Platforms Ireland Limited (if you are located in or, if you
|
||||
are an entity, your principal place of business is in the EEA or Switzerland) and Meta
|
||||
Platforms, Inc. (if you are located outside of the EEA or Switzerland).
|
||||
|
||||
By clicking "I Accept" below or by using or distributing any portion or element of the
|
||||
Llama Materials, you agree to be bound by this Agreement.
|
||||
|
||||
1. License Rights and Redistribution.
|
||||
|
||||
a. Grant of Rights. You are granted a non-exclusive, worldwide, non-
|
||||
transferable and royalty-free limited license under Meta's intellectual property or
|
||||
other rights owned by Meta embodied in the Llama Materials to use, reproduce,
|
||||
distribute, copy, create derivative works of, and make modifications to the Llama
|
||||
Materials.
|
||||
|
||||
b. Redistribution and Use.
|
||||
|
||||
i. If you distribute or make the Llama Materials, or any derivative works
|
||||
thereof, available to a third party, you shall provide a copy of this Agreement to such
|
||||
third party.
|
||||
ii. If you receive Llama Materials, or any derivative works thereof, from
|
||||
a Licensee as part of an integrated end user product, then Section 2 of this
|
||||
Agreement will not apply to you.
|
||||
|
||||
iii. You must retain in all copies of the Llama Materials that you
|
||||
distribute the following attribution notice within a "Notice" text file distributed as a
|
||||
part of such copies: "Llama 2 is licensed under the LLAMA 2 Community License,
|
||||
Copyright (c) Meta Platforms, Inc. All Rights Reserved."
|
||||
|
||||
iv. Your use of the Llama Materials must comply with applicable laws
|
||||
and regulations (including trade compliance laws and regulations) and adhere to the
|
||||
Acceptable Use Policy for the Llama Materials (available at
|
||||
https://ai.meta.com/llama/use-policy), which is hereby incorporated by reference into
|
||||
this Agreement.
|
||||
|
||||
v. You will not use the Llama Materials or any output or results of the
|
||||
Llama Materials to improve any other large language model (excluding Llama 2 or
|
||||
derivative works thereof).
|
||||
|
||||
2. Additional Commercial Terms. If, on the Llama 2 version release date, the
|
||||
monthly active users of the products or services made available by or for Licensee,
|
||||
or Licensee's affiliates, is greater than 700 million monthly active users in the
|
||||
preceding calendar month, you must request a license from Meta, which Meta may
|
||||
grant to you in its sole discretion, and you are not authorized to exercise any of the
|
||||
rights under this Agreement unless or until Meta otherwise expressly grants you
|
||||
such rights.
|
||||
|
||||
3. Disclaimer of Warranty. UNLESS REQUIRED BY APPLICABLE LAW, THE
|
||||
LLAMA MATERIALS AND ANY OUTPUT AND RESULTS THEREFROM ARE
|
||||
PROVIDED ON AN "AS IS" BASIS, WITHOUT WARRANTIES OF ANY KIND,
|
||||
EITHER EXPRESS OR IMPLIED, INCLUDING, WITHOUT LIMITATION, ANY
|
||||
WARRANTIES OF TITLE, NON-INFRINGEMENT, MERCHANTABILITY, OR
|
||||
FITNESS FOR A PARTICULAR PURPOSE. YOU ARE SOLELY RESPONSIBLE
|
||||
FOR DETERMINING THE APPROPRIATENESS OF USING OR REDISTRIBUTING
|
||||
THE LLAMA MATERIALS AND ASSUME ANY RISKS ASSOCIATED WITH YOUR
|
||||
USE OF THE LLAMA MATERIALS AND ANY OUTPUT AND RESULTS.
|
||||
|
||||
4. Limitation of Liability. IN NO EVENT WILL META OR ITS AFFILIATES BE
|
||||
LIABLE UNDER ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, TORT,
|
||||
NEGLIGENCE, PRODUCTS LIABILITY, OR OTHERWISE, ARISING OUT OF THIS
|
||||
AGREEMENT, FOR ANY LOST PROFITS OR ANY INDIRECT, SPECIAL,
|
||||
CONSEQUENTIAL, INCIDENTAL, EXEMPLARY OR PUNITIVE DAMAGES, EVEN
|
||||
IF META OR ITS AFFILIATES HAVE BEEN ADVISED OF THE POSSIBILITY OF
|
||||
ANY OF THE FOREGOING.
|
||||
|
||||
5. Intellectual Property.
|
||||
|
||||
a. No trademark licenses are granted under this Agreement, and in
|
||||
connection with the Llama Materials, neither Meta nor Licensee may use any name
|
||||
or mark owned by or associated with the other or any of its affiliates, except as
|
||||
required for reasonable and customary use in describing and redistributing the
|
||||
Llama Materials.
|
||||
|
||||
b. Subject to Meta's ownership of Llama Materials and derivatives made by or
|
||||
for Meta, with respect to any derivative works and modifications of the Llama
|
||||
Materials that are made by you, as between you and Meta, you are and will be the
|
||||
owner of such derivative works and modifications.
|
||||
|
||||
c. If you institute litigation or other proceedings against Meta or any entity
|
||||
(including a cross-claim or counterclaim in a lawsuit) alleging that the Llama
|
||||
Materials or Llama 2 outputs or results, or any portion of any of the foregoing,
|
||||
constitutes infringement of intellectual property or other rights owned or licensable
|
||||
by you, then any licenses granted to you under this Agreement shall terminate as of
|
||||
the date such litigation or claim is filed or instituted. You will indemnify and hold
|
||||
harmless Meta from and against any claim by any third party arising out of or related
|
||||
to your use or distribution of the Llama Materials.
|
||||
|
||||
6. Term and Termination. The term of this Agreement will commence upon your
|
||||
acceptance of this Agreement or access to the Llama Materials and will continue in
|
||||
full force and effect until terminated in accordance with the terms and conditions
|
||||
herein. Meta may terminate this Agreement if you are in breach of any term or
|
||||
condition of this Agreement. Upon termination of this Agreement, you shall delete
|
||||
and cease use of the Llama Materials. Sections 3, 4 and 7 shall survive the
|
||||
termination of this Agreement.
|
||||
|
||||
7. Governing Law and Jurisdiction. This Agreement will be governed and
|
||||
construed under the laws of the State of California without regard to choice of law
|
||||
principles, and the UN Convention on Contracts for the International Sale of Goods
|
||||
does not apply to this Agreement. The courts of California shall have exclusive
|
||||
jurisdiction of any dispute arising out of this Agreement.
|
||||
|
||||
1
Notice
Normal file
1
Notice
Normal file
@@ -0,0 +1 @@
|
||||
Llama 2 is licensed under the LLAMA 2 Community License, Copyright © Meta Platforms, Inc. All Rights Reserved.
|
||||
530
README.md
Normal file
530
README.md
Normal file
@@ -0,0 +1,530 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
license: llama2
|
||||
library_name: transformers
|
||||
datasets:
|
||||
- Open-Orca/OpenOrca
|
||||
model_name: OpenOrca x OpenChat - Preview2 - 13B
|
||||
base_model: Open-Orca/OpenOrcaxOpenChat-Preview2-13B
|
||||
inference: false
|
||||
model_creator: Open-Orca
|
||||
model_type: llama
|
||||
pipeline_tag: text-generation
|
||||
prompt_template: 'GPT4 User: {prompt}<|end_of_turn|>GPT4 Assistant:
|
||||
|
||||
'
|
||||
quantized_by: TheBloke
|
||||
---
|
||||
|
||||
<!-- header start -->
|
||||
<!-- 200823 -->
|
||||
<div style="width: auto; margin-left: auto; margin-right: auto">
|
||||
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
|
||||
</div>
|
||||
<div style="display: flex; justify-content: space-between; width: 100%;">
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-start;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://discord.gg/theblokeai">Chat & support: TheBloke's Discord server</a></p>
|
||||
</div>
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-end;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://www.patreon.com/TheBlokeAI">Want to contribute? TheBloke's Patreon page</a></p>
|
||||
</div>
|
||||
</div>
|
||||
<div style="text-align:center; margin-top: 0em; margin-bottom: 0em"><p style="margin-top: 0.25em; margin-bottom: 0em;">TheBloke's LLM work is generously supported by a grant from <a href="https://a16z.com">andreessen horowitz (a16z)</a></p></div>
|
||||
<hr style="margin-top: 1.0em; margin-bottom: 1.0em;">
|
||||
<!-- header end -->
|
||||
|
||||
# OpenOrca x OpenChat - Preview2 - 13B - GPTQ
|
||||
- Model creator: [Open-Orca](https://huggingface.co/Open-Orca)
|
||||
- Original model: [OpenOrca x OpenChat - Preview2 - 13B](https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B)
|
||||
|
||||
<!-- description start -->
|
||||
## Description
|
||||
|
||||
This repo contains GPTQ model files for [Open-Orca's OpenOrca x OpenChat - Preview2 - 13B](https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B).
|
||||
|
||||
Multiple GPTQ parameter permutations are provided; see Provided Files below for details of the options provided, their parameters, and the software used to create them.
|
||||
|
||||
<!-- description end -->
|
||||
<!-- repositories-available start -->
|
||||
## Repositories available
|
||||
|
||||
* [AWQ model(s) for GPU inference.](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-AWQ)
|
||||
* [GPTQ models for GPU inference, with multiple quantisation parameter options.](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ)
|
||||
* [Open-Orca's original unquantised fp16 model in pytorch format, for GPU inference and for further conversions](https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B)
|
||||
<!-- repositories-available end -->
|
||||
|
||||
<!-- prompt-template start -->
|
||||
## Prompt template: OpenChat
|
||||
|
||||
```
|
||||
GPT4 User: {prompt}<|end_of_turn|>GPT4 Assistant:
|
||||
|
||||
```
|
||||
|
||||
<!-- prompt-template end -->
|
||||
|
||||
|
||||
<!-- README_GPTQ.md-provided-files start -->
|
||||
## Provided files and GPTQ parameters
|
||||
|
||||
Multiple quantisation parameters are provided, to allow you to choose the best one for your hardware and requirements.
|
||||
|
||||
Each separate quant is in a different branch. See below for instructions on fetching from different branches.
|
||||
|
||||
All recent GPTQ files are made with AutoGPTQ, and all files in non-main branches are made with AutoGPTQ. Files in the `main` branch which were uploaded before August 2023 were made with GPTQ-for-LLaMa.
|
||||
|
||||
<details>
|
||||
<summary>Explanation of GPTQ parameters</summary>
|
||||
|
||||
- Bits: The bit size of the quantised model.
|
||||
- GS: GPTQ group size. Higher numbers use less VRAM, but have lower quantisation accuracy. "None" is the lowest possible value.
|
||||
- Act Order: True or False. Also known as `desc_act`. True results in better quantisation accuracy. Some GPTQ clients have had issues with models that use Act Order plus Group Size, but this is generally resolved now.
|
||||
- Damp %: A GPTQ parameter that affects how samples are processed for quantisation. 0.01 is default, but 0.1 results in slightly better accuracy.
|
||||
- GPTQ dataset: The dataset used for quantisation. Using a dataset more appropriate to the model's training can improve quantisation accuracy. Note that the GPTQ dataset is not the same as the dataset used to train the model - please refer to the original model repo for details of the training dataset(s).
|
||||
- Sequence Length: The length of the dataset sequences used for quantisation. Ideally this is the same as the model sequence length. For some very long sequence models (16+K), a lower sequence length may have to be used. Note that a lower sequence length does not limit the sequence length of the quantised model. It only impacts the quantisation accuracy on longer inference sequences.
|
||||
- ExLlama Compatibility: Whether this file can be loaded with ExLlama, which currently only supports Llama models in 4-bit.
|
||||
|
||||
</details>
|
||||
|
||||
| Branch | Bits | GS | Act Order | Damp % | GPTQ Dataset | Seq Len | Size | ExLlama | Desc |
|
||||
| ------ | ---- | -- | --------- | ------ | ------------ | ------- | ---- | ------- | ---- |
|
||||
| [main](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/main) | 4 | 128 | No | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 7.26 GB | Yes | 4-bit, without Act Order and group size 128g. |
|
||||
| [gptq-4bit-32g-actorder_True](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/gptq-4bit-32g-actorder_True) | 4 | 32 | Yes | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 8.00 GB | Yes | 4-bit, with Act Order and group size 32g. Gives highest possible inference quality, with maximum VRAM usage. |
|
||||
| [gptq-4bit-64g-actorder_True](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/gptq-4bit-64g-actorder_True) | 4 | 64 | Yes | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 7.51 GB | Yes | 4-bit, with Act Order and group size 64g. Uses less VRAM than 32g, but with slightly lower accuracy. |
|
||||
| [gptq-4bit-128g-actorder_True](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/gptq-4bit-128g-actorder_True) | 4 | 128 | Yes | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 7.26 GB | Yes | 4-bit, with Act Order and group size 128g. Uses even less VRAM than 64g, but with slightly lower accuracy. |
|
||||
| [gptq-8bit--1g-actorder_True](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/gptq-8bit--1g-actorder_True) | 8 | None | Yes | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 13.36 GB | No | 8-bit, with Act Order. No group size, to lower VRAM requirements. |
|
||||
| [gptq-8bit-128g-actorder_True](https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ/tree/gptq-8bit-128g-actorder_True) | 8 | 128 | Yes | 0.1 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 13.65 GB | No | 8-bit, with group size 128g for higher inference quality and with Act Order for even higher accuracy. |
|
||||
|
||||
<!-- README_GPTQ.md-provided-files end -->
|
||||
|
||||
<!-- README_GPTQ.md-download-from-branches start -->
|
||||
## How to download from branches
|
||||
|
||||
- In text-generation-webui, you can add `:branch` to the end of the download name, eg `TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ:main`
|
||||
- With Git, you can clone a branch with:
|
||||
```
|
||||
git clone --single-branch --branch main https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ
|
||||
```
|
||||
- In Python Transformers code, the branch is the `revision` parameter; see below.
|
||||
<!-- README_GPTQ.md-download-from-branches end -->
|
||||
<!-- README_GPTQ.md-text-generation-webui start -->
|
||||
## How to easily download and use this model in [text-generation-webui](https://github.com/oobabooga/text-generation-webui).
|
||||
|
||||
Please make sure you're using the latest version of [text-generation-webui](https://github.com/oobabooga/text-generation-webui).
|
||||
|
||||
It is strongly recommended to use the text-generation-webui one-click-installers unless you're sure you know how to make a manual install.
|
||||
|
||||
1. Click the **Model tab**.
|
||||
2. Under **Download custom model or LoRA**, enter `TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ`.
|
||||
- To download from a specific branch, enter for example `TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ:main`
|
||||
- see Provided Files above for the list of branches for each option.
|
||||
3. Click **Download**.
|
||||
4. The model will start downloading. Once it's finished it will say "Done".
|
||||
5. In the top left, click the refresh icon next to **Model**.
|
||||
6. In the **Model** dropdown, choose the model you just downloaded: `OpenOrcaxOpenChat-Preview2-13B-GPTQ`
|
||||
7. The model will automatically load, and is now ready for use!
|
||||
8. If you want any custom settings, set them and then click **Save settings for this model** followed by **Reload the Model** in the top right.
|
||||
* Note that you do not need to and should not set manual GPTQ parameters any more. These are set automatically from the file `quantize_config.json`.
|
||||
9. Once you're ready, click the **Text Generation tab** and enter a prompt to get started!
|
||||
<!-- README_GPTQ.md-text-generation-webui end -->
|
||||
|
||||
<!-- README_GPTQ.md-use-from-python start -->
|
||||
## How to use this GPTQ model from Python code
|
||||
|
||||
### Install the necessary packages
|
||||
|
||||
Requires: Transformers 4.32.0 or later, Optimum 1.12.0 or later, and AutoGPTQ 0.4.2 or later.
|
||||
|
||||
```shell
|
||||
pip3 install transformers>=4.32.0 optimum>=1.12.0
|
||||
pip3 install auto-gptq --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu118/ # Use cu117 if on CUDA 11.7
|
||||
```
|
||||
|
||||
If you have problems installing AutoGPTQ using the pre-built wheels, install it from source instead:
|
||||
|
||||
```shell
|
||||
pip3 uninstall -y auto-gptq
|
||||
git clone https://github.com/PanQiWei/AutoGPTQ
|
||||
cd AutoGPTQ
|
||||
pip3 install .
|
||||
```
|
||||
|
||||
### For CodeLlama models only: you must use Transformers 4.33.0 or later.
|
||||
|
||||
If 4.33.0 is not yet released when you read this, you will need to install Transformers from source:
|
||||
```shell
|
||||
pip3 uninstall -y transformers
|
||||
pip3 install git+https://github.com/huggingface/transformers.git
|
||||
```
|
||||
|
||||
### You can then use the following code
|
||||
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline
|
||||
|
||||
model_name_or_path = "TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ"
|
||||
# To use a different branch, change revision
|
||||
# For example: revision="main"
|
||||
model = AutoModelForCausalLM.from_pretrained(model_name_or_path,
|
||||
device_map="auto",
|
||||
trust_remote_code=False,
|
||||
revision="main")
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, use_fast=True)
|
||||
|
||||
prompt = "Tell me about AI"
|
||||
prompt_template=f'''GPT4 User: {prompt}<|end_of_turn|>GPT4 Assistant:
|
||||
|
||||
'''
|
||||
|
||||
print("\n\n*** Generate:")
|
||||
|
||||
input_ids = tokenizer(prompt_template, return_tensors='pt').input_ids.cuda()
|
||||
output = model.generate(inputs=input_ids, temperature=0.7, do_sample=True, top_p=0.95, top_k=40, max_new_tokens=512)
|
||||
print(tokenizer.decode(output[0]))
|
||||
|
||||
# Inference can also be done using transformers' pipeline
|
||||
|
||||
print("*** Pipeline:")
|
||||
pipe = pipeline(
|
||||
"text-generation",
|
||||
model=model,
|
||||
tokenizer=tokenizer,
|
||||
max_new_tokens=512,
|
||||
do_sample=True,
|
||||
temperature=0.7,
|
||||
top_p=0.95,
|
||||
top_k=40,
|
||||
repetition_penalty=1.1
|
||||
)
|
||||
|
||||
print(pipe(prompt_template)[0]['generated_text'])
|
||||
```
|
||||
<!-- README_GPTQ.md-use-from-python end -->
|
||||
|
||||
<!-- README_GPTQ.md-compatibility start -->
|
||||
## Compatibility
|
||||
|
||||
The files provided are tested to work with AutoGPTQ, both via Transformers and using AutoGPTQ directly. They should also work with [Occ4m's GPTQ-for-LLaMa fork](https://github.com/0cc4m/KoboldAI).
|
||||
|
||||
[ExLlama](https://github.com/turboderp/exllama) is compatible with Llama models in 4-bit. Please see the Provided Files table above for per-file compatibility.
|
||||
|
||||
[Huggingface Text Generation Inference (TGI)](https://github.com/huggingface/text-generation-inference) is compatible with all GPTQ models.
|
||||
<!-- README_GPTQ.md-compatibility end -->
|
||||
|
||||
<!-- footer start -->
|
||||
<!-- 200823 -->
|
||||
## Discord
|
||||
|
||||
For further support, and discussions on these models and AI in general, join us at:
|
||||
|
||||
[TheBloke AI's Discord server](https://discord.gg/theblokeai)
|
||||
|
||||
## Thanks, and how to contribute
|
||||
|
||||
Thanks to the [chirper.ai](https://chirper.ai) team!
|
||||
|
||||
Thanks to Clay from [gpus.llm-utils.org](llm-utils)!
|
||||
|
||||
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
|
||||
|
||||
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
|
||||
|
||||
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
|
||||
|
||||
* Patreon: https://patreon.com/TheBlokeAI
|
||||
* Ko-Fi: https://ko-fi.com/TheBlokeAI
|
||||
|
||||
**Special thanks to**: Aemon Algiz.
|
||||
|
||||
**Patreon special mentions**: Alicia Loh, Stephen Murray, K, Ajan Kanaga, RoA, Magnesian, Deo Leter, Olakabola, Eugene Pentland, zynix, Deep Realms, Raymond Fosdick, Elijah Stavena, Iucharbius, Erik Bjäreholt, Luis Javier Navarrete Lozano, Nicholas, theTransient, John Detwiler, alfie_i, knownsqashed, Mano Prime, Willem Michiel, Enrico Ros, LangChain4j, OG, Michael Dempsey, Pierre Kircher, Pedro Madruga, James Bentley, Thomas Belote, Luke @flexchar, Leonard Tan, Johann-Peter Hartmann, Illia Dulskyi, Fen Risland, Chadd, S_X, Jeff Scroggin, Ken Nordquist, Sean Connelly, Artur Olbinski, Swaroop Kallakuri, Jack West, Ai Maven, David Ziegler, Russ Johnson, transmissions 11, John Villwock, Alps Aficionado, Clay Pascal, Viktor Bowallius, Subspace Studios, Rainer Wilmers, Trenton Dambrowitz, vamX, Michael Levine, 준교 김, Brandon Frisco, Kalila, Trailburnt, Randy H, Talal Aujan, Nathan Dryer, Vadim, 阿明, ReadyPlayerEmma, Tiffany J. Kim, George Stoitzev, Spencer Kim, Jerry Meng, Gabriel Tamborski, Cory Kujawski, Jeffrey Morgan, Spiking Neurons AB, Edmond Seymore, Alexandros Triantafyllidis, Lone Striker, Cap'n Zoog, Nikolai Manek, danny, ya boyyy, Derek Yates, usrbinkat, Mandus, TL, Nathan LeClaire, subjectnull, Imad Khwaja, webtim, Raven Klaugh, Asp the Wyvern, Gabriel Puliatti, Caitlyn Gatomon, Joseph William Delisle, Jonathan Leane, Luke Pendergrass, SuperWojo, Sebastain Graf, Will Dee, Fred von Graf, Andrey, Dan Guido, Daniel P. Andersen, Nitin Borwankar, Elle, Vitor Caleffi, biorpg, jjj, NimbleBox.ai, Pieter, Matthew Berman, terasurfer, Michael Davis, Alex, Stanislav Ovsiannikov
|
||||
|
||||
|
||||
Thank you to all my generous patrons and donaters!
|
||||
|
||||
And thank you again to a16z for their generous grant.
|
||||
|
||||
<!-- footer end -->
|
||||
|
||||
# Original model card: Open-Orca's OpenOrca x OpenChat - Preview2 - 13B
|
||||
|
||||
|
||||
<p><h1>🐋 The Second OpenOrca Model Preview! 🐋</h1></p>
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
# OpenOrca x OpenChat - Preview2 - 13B
|
||||
|
||||
We have used our own [OpenOrca dataset](https://huggingface.co/datasets/Open-Orca/OpenOrca) to fine-tune Llama2-13B using [OpenChat](https://huggingface.co/openchat) packing.
|
||||
This dataset is our attempt to reproduce the dataset generated for Microsoft Research's [Orca Paper](https://arxiv.org/abs/2306.02707).
|
||||
|
||||
This second preview release is trained on a curated filtered subset of most of our GPT-4 augmented data.
|
||||
|
||||
This release highlights that our dataset and training methods have surpassed performance parity with the Orca paper.
|
||||
We measured this with BigBench-Hard and AGIEval results with the same methods as used in the Orca paper, finding **~103%** of original Orca's performance on average.
|
||||
As well, this is done with <1/10th the compute requirement and using <20% of the dataset size from the original Orca paper.
|
||||
|
||||
We have run extensive evaluations internally and expect this model to **place number 1** on both the HuggingFaceH4 Open LLM Leaderboard and the GPT4ALL Leaderboard for 13B models.
|
||||
|
||||
"One" of [OpenChat](https://huggingface.co/openchat) has joined our team, and we'd like to provide special thanks for their training of this model!
|
||||
We have utilized OpenChat [MultiPack algorithm](https://github.com/imoneoi/multipack_sampler) which achieves 99.85% bin-packing efficiency on our dataset.
|
||||
This has significantly reduced training time, with efficiency improvement of 3-10X over traditional methods.
|
||||
|
||||
|
||||
<img src="https://raw.githubusercontent.com/imoneoi/openchat/master/assets/logo_new.png" style="width: 40%">
|
||||
|
||||
|
||||
Want to visualize our full (pre-filtering) dataset? Check out our [Nomic Atlas Map](https://atlas.nomic.ai/map/c1b88b47-2d9b-47e0-9002-b80766792582/2560fd25-52fe-42f1-a58f-ff5eccc890d2).
|
||||
|
||||
|
||||
[<img src="https://huggingface.co/Open-Orca/OpenOrca-Preview1-13B/resolve/main/OpenOrca%20Nomic%20Atlas.png" alt="Atlas Nomic Dataset Map" width="400" height="400" />](https://atlas.nomic.ai/map/c1b88b47-2d9b-47e0-9002-b80766792582/2560fd25-52fe-42f1-a58f-ff5eccc890d2)
|
||||
|
||||
|
||||
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
|
||||
|
||||
We will also give sneak-peak announcements on our Discord, which you can find here:
|
||||
|
||||
https://AlignmentLab.ai
|
||||
|
||||
# Prompt Template
|
||||
|
||||
We use our own prompt template which we call "`OpenChat Llama2 V1`".
|
||||
|
||||
The model is heavily conditioned to work using this format only and will likely encounter issues such as run-on output which emulates a chat between a user and assistant if this format is not properly followed.
|
||||
|
||||
|
||||
Examples:
|
||||
```
|
||||
# Single-turn `OpenChat Llama2 V1`
|
||||
tokenize("You are OpenOrcaChat.<|end_of_turn|>User: Hello<|end_of_turn|>Assistant:")
|
||||
# [1, 887, 526, 4673, 2816, 1113, 1451, 271, 29889, 32000, 4911, 29901, 15043, 32000, 4007, 22137, 29901]
|
||||
|
||||
# Multi-turn `OpenChat Llama2 V1`
|
||||
tokenize("You are OpenOrcaChat.<|end_of_turn|>User: Hello<|end_of_turn|>Assistant: Hi<|end_of_turn|>User: How are you today?<|end_of_turn|>Assistant:")
|
||||
# [1, 887, 526, 4673, 2816, 1113, 1451, 271, 29889, 32000, 4911, 29901, 15043, 32000, 4007, 22137, 29901, 6324, 32000, 4911, 29901, 1128, 526, 366, 9826, 29973, 32000, 4007, 22137, 29901]
|
||||
```
|
||||
|
||||
For UIs with Prefix and Suffix fields, these will likely work:
|
||||
|
||||
Prefix (include a space after colon):
|
||||
```
|
||||
User:
|
||||
```
|
||||
|
||||
Suffix (space after colon):
|
||||
```
|
||||
<|end_of_turn|>\nAssistant:
|
||||
```
|
||||
|
||||
**Oobabooga's text-generation-webui instructions can be found [further down the page](https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B#serving-with-oobabooga--text-generation-webui).**
|
||||
|
||||
|
||||
# Evaluation
|
||||
|
||||
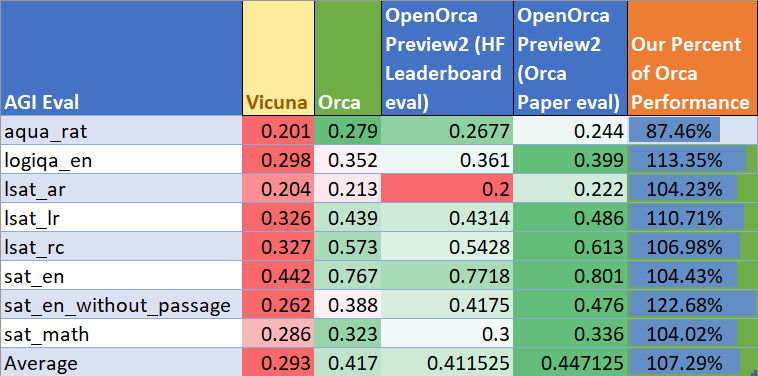
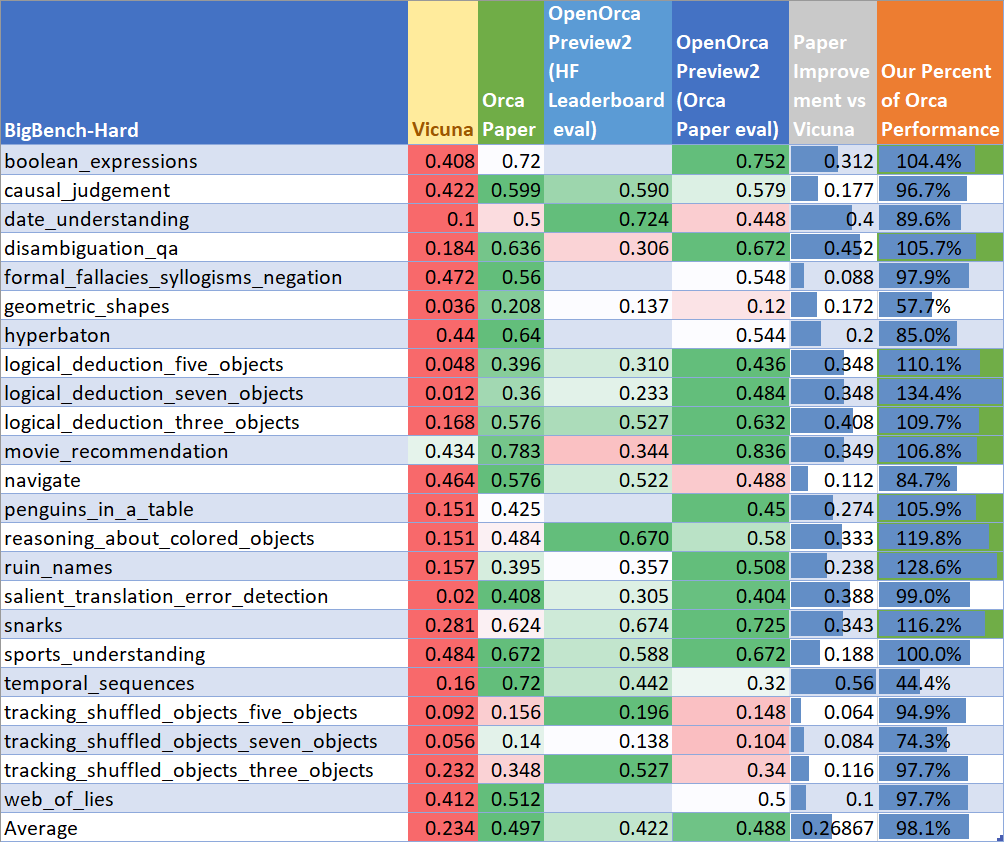
We have evaluated **OpenOrcaxOpenChat-Preview2-13B** on hard reasoning tasks from BigBench-Hard and AGIEval as outlined in the Orca paper.
|
||||
|
||||
Our average performance for BigBench-Hard: 0.488
|
||||
|
||||
Average for AGIEval: 0.447
|
||||
|
||||
We find our score averages to **~103%** of the total performance that was shown in the Orca paper, using the same evaluation methods as outlined in the paper.
|
||||
|
||||
So we are surpassing Orca performance with <20% of the dataset size and <1/10th the training budget!
|
||||
|
||||
As well, we have evaluated using the methodology and tools for the HuggingFace Leaderboard and GPT4ALL Leaderboard, and find that we place #1 on both for all 13B models at release time!
|
||||
|
||||
## AGIEval Performance
|
||||
|
||||
We present our results in two columns.
|
||||
The column for "`(Orca Paper eval)`" uses the methods outlined in the Orca paper, so as to be a direct apples-to-apples comparison with the results from the paper.
|
||||
The column for "`(HF Leaderboard eval)`" uses EleutherAI's LM Evaluation Harness with settings outlined by HuggingFace. These results are not comparable to the other columns, as the methods are different.
|
||||
|
||||
|
||||
|
||||
## BigBench-Hard Performance
|
||||
|
||||
We present our results in two columns.
|
||||
The column for "`(Orca Paper eval)`" uses the methods outlined in the Orca paper, so as to be a direct apples-to-apples comparison with the results from the paper.
|
||||
The column for "`(HF Leaderboard eval)`" uses EleutherAI's LM Evaluation Harness with settings outlined by HuggingFace. These results are not comparable to the other columns, as the methods are different.
|
||||
|
||||
|
||||
|
||||
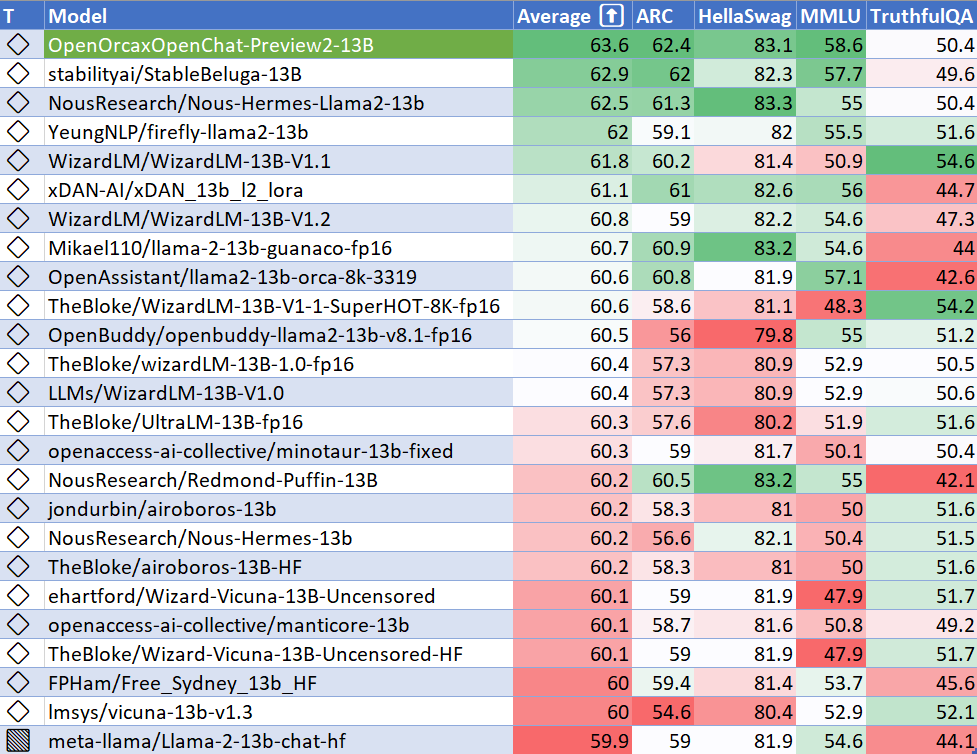
## HuggingFaceH4 Open LLM Leaderboard Performance
|
||||
|
||||
We have run our own tests using parameters matching the [HuggingFaceH4 Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard) evals.
|
||||
|
||||
We place #1 for all 13B models at release time!
|
||||
|
||||
|
||||
|
||||
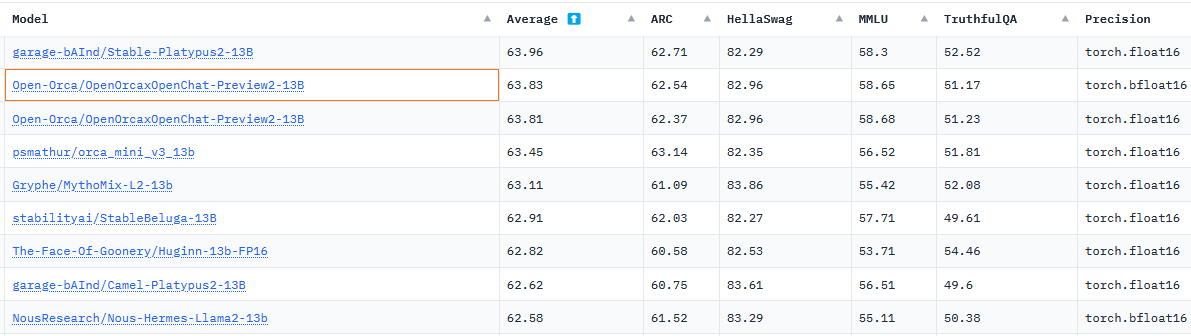
**Update Aug 10th:** The official results on the leaderboard are below.
|
||||
|
||||
|
||||
|
||||
Since our release, a new model which merges an Orca-style model with a Platypus (trained on STEM and logic) model places narrowly above ours, but we were #1 at release time.
|
||||
|
||||
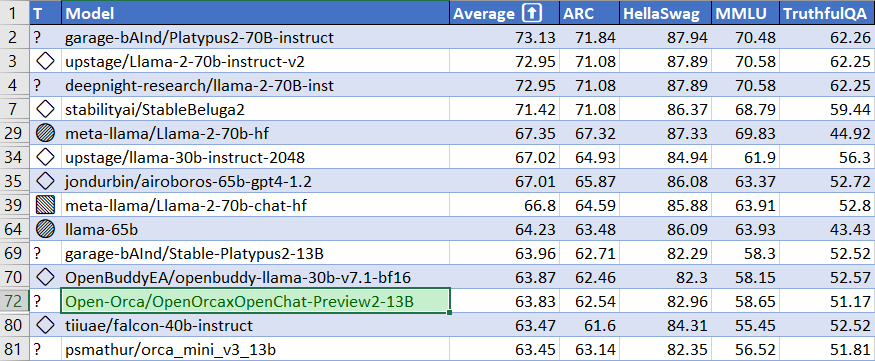
Below we also highlight how our model fits relative to models of all sizes on the current (as of Aug 10th, 2023) leaderboard.
|
||||
|
||||
|
||||
|
||||
Notably, performance is beyond falcon-40b-instruct, and close to LLaMA1-65B base.
|
||||
|
||||
## GPT4ALL Leaderboard Performance
|
||||
|
||||
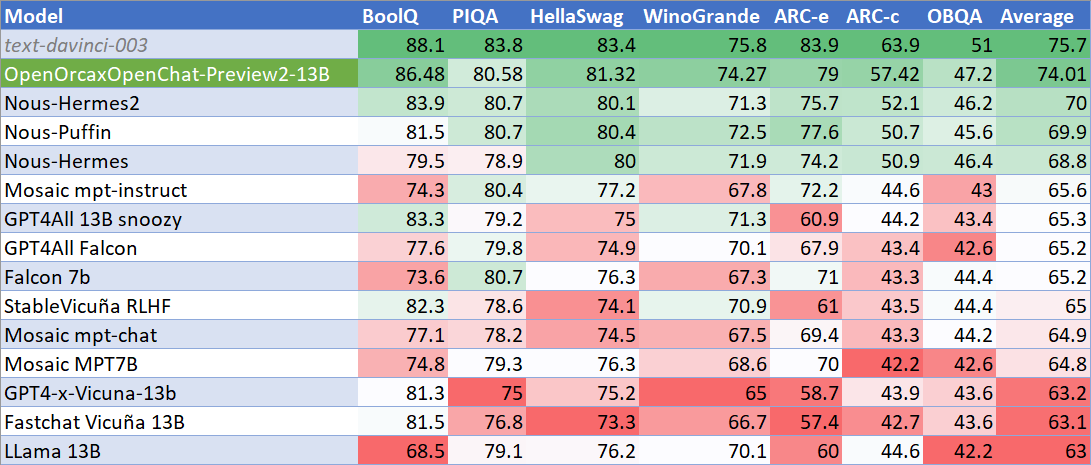
We have tested using parameters matching the GPT4ALL Benchmark Suite and report our results and placement vs their official reporting below.
|
||||
|
||||
We place #1 for all open models and come within comparison of `text-davinci-003`, a proprietary OpenAI model an order of magnitude larger.
|
||||
|
||||
|
||||
|
||||
|
||||
# Dataset
|
||||
|
||||
We used a curated, filtered selection of most of the GPT-4 augmented data from our OpenOrca dataset, which aims to reproduce the Orca Research Paper dataset.
|
||||
Further details of our curation practices will be forthcoming with our full model releases.
|
||||
|
||||
|
||||
# Training
|
||||
|
||||
We trained with 8x A100-80G GPUs for 46 hours, completing 5 epochs of full fine tuning on our dataset in one training run.
|
||||
This contrasts with the 20x A100-80G GPUs for 200 hours used in the Orca paper, for only 3 epochs, and requiring stacked training (which is known to suffer catastrophic forgetting).
|
||||
Our compute requirement was <1/10th that of the original Orca.
|
||||
Commodity cost was ~$600.
|
||||
|
||||
Please await our full releases for further training details.
|
||||
|
||||
|
||||
# Serving
|
||||
|
||||
This model is most easily served with [OpenChat's](https://github.com/imoneoi/openchat) customized vLLM OpenAI-compatible API server.
|
||||
This is highly recommended as it is by far the fastest in terms of inference speed and is a quick and easy option for setup.
|
||||
We also illustrate setup of Oobabooga/text-generation-webui below. The settings outlined there will also apply to other uses of `Transformers`.
|
||||
|
||||
## Serving Quantized
|
||||
|
||||
Pre-quantized models are now available courtesy of our friend TheBloke:
|
||||
|
||||
* **GGML**: https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GGML
|
||||
* **GPTQ**: https://huggingface.co/TheBloke/OpenOrcaxOpenChat-Preview2-13B-GPTQ
|
||||
|
||||
The serving instructions below only apply to the unquantized model being presented in the repository you are viewing here.
|
||||
There are some notes, such as on use of the prompt format, that will still apply to the quantized models though.
|
||||
|
||||
## Serving with OpenChat
|
||||
|
||||
[Install OpenChat](https://github.com/imoneoi/openchat/#installation)
|
||||
|
||||
After installation, run:
|
||||
|
||||
```bash
|
||||
python -m ochat.serving.openai_api_server \
|
||||
--model-type openchat_llama2 \
|
||||
--model Open-Orca/OpenOrcaxOpenChat-Preview2-13B \
|
||||
--engine-use-ray --worker-use-ray --max-num-batched-tokens 5120
|
||||
```
|
||||
|
||||
Follow the OpenChat documentation to use features such as tensor parallelism on consumer GPUs, API keys, and logging.
|
||||
You may then connect to the OpenAI-compatible API endpoint with tools such as [BetterGPT.chat](https://bettergpt.chat).
|
||||
|
||||
## Serving with Oobabooga / text-generation-webui
|
||||
|
||||
The model may also be loaded via [oobabooga/text-generation-webui](https://github.com/oobabooga/text-generation-webui/) in a similar manner to other models.
|
||||
See the requirements below. Note that inference with just the Transformers library is significantly slower than using the recommended OpenChat vLLM server.
|
||||
|
||||
### Oobabooga Key Requirements
|
||||
|
||||
* You will first need to download the model as you normally do to the "`models/`" folder of your `text-generation-webui` installation.
|
||||
* To use the unquantized model presented here, select "`Transformers`"" in the webui's "`Model`" tab "`Model loader`" dropdown.
|
||||
* You will likely want to tick "`auto-devices`". The model will require >40GB VRAM after loading in context for inference.
|
||||
* The model was trained in bf16, so tick the "`bf16`" box for best performance.
|
||||
* It will run safely on single GPUs with VRAM >=48GB (e.g. A6000)
|
||||
* If using consumer GPUs, e.g. 2x RTX3090 24GB, you will likely want to enter "18,17" under "`tensor_split`" to split the model across both GPUs
|
||||
* The model will perform significantly better if you use the appropriate prompting template
|
||||
* We will submit a PR to include our prompting template into text-generation-webui soon
|
||||
* For now, manually enter the settings described in the following sections:
|
||||
|
||||
### Oobabooga Chat Settings
|
||||
|
||||
In the "`Chat settings`" tab, select the following settings:
|
||||
|
||||
For "`User String`" ...
|
||||
```
|
||||
User:
|
||||
```
|
||||
For "`Bot string`" ...
|
||||
```
|
||||
Assistant:
|
||||
```
|
||||
For "`Context`", this is analogous to system prompt.
|
||||
It is not necessary, but we have found good results with the below example.
|
||||
System prompts used in the Orca training also work well. ...
|
||||
```
|
||||
You are a helpful assistant. Please answer truthfully and write out your thinking step by step to be sure you get the right answer. If you make a mistake or encounter an error in your thinking, say so out loud and attempt to correct it. If you don't know or aren't sure about something, say so clearly. You will act as a professional logician, mathematician, and physicist. You will also act as the most appropriate type of expert to answer any particular question or solve the relevant problem; state which expert type your are, if so. Also think of any particular named expert that would be ideal to answer the relevant question or solve the relevant problem; name and act as them, if appropriate.
|
||||
```
|
||||
For "`Turn template`", this is absolutely essential to have. You will get poor, mixed up output without this template ...
|
||||
```
|
||||
<|user|> <|user-message|><|end_of_turn|>\n<|bot|> <|bot-message|>\n
|
||||
```
|
||||
|
||||
When done, it should look as below:
|
||||
<img src="https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B/resolve/main/Images/OpenOrcaLlama2OobaboogaChatInstructionTemplate.png" style="width: 40%">
|
||||
|
||||
You may then save this as a named template preset by clicking the "Floppy" icon and giving it an appropriate name in the popup, e.g. "`OpenOrcaxOpenChat Llama2`".
|
||||
|
||||
### Oobabooga Text Generation Mode
|
||||
|
||||
In the "`Text generation`" tab, select "`instruct`" as the mode:
|
||||
|
||||
#### Mode Illustration
|
||||
It should look as below:
|
||||
<img src="https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B/resolve/main/Images/OpenOrcaLlama2OobaboogaInstructMode.png" style="width: 40%">
|
||||
|
||||
Then you should be ready to generate!
|
||||
|
||||
# Citation
|
||||
|
||||
```bibtex
|
||||
@software{OpenOrcaxOpenChatPreview2,
|
||||
title = {OpenOrcaxOpenChatPreview2: Llama2-13B Model Instruct-tuned on Filtered OpenOrcaV1 GPT-4 Dataset},
|
||||
author = {Guan Wang and Bleys Goodson and Wing Lian and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
|
||||
year = {2023},
|
||||
publisher = {HuggingFace},
|
||||
journal = {HuggingFace repository},
|
||||
howpublished = {\url{https://https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B},
|
||||
}
|
||||
@software{openchat,
|
||||
title = {{OpenChat: Advancing Open-source Language Models with Imperfect Data}},
|
||||
author = {Wang, Guan and Cheng, Sijie and Yu, Qiying and Liu, Changling},
|
||||
doi = {10.5281/zenodo.8105775},
|
||||
url = {https://github.com/imoneoi/openchat},
|
||||
version = {pre-release},
|
||||
year = {2023},
|
||||
month = {7},
|
||||
}
|
||||
@misc{mukherjee2023orca,
|
||||
title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
|
||||
author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
|
||||
year={2023},
|
||||
eprint={2306.02707},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL}
|
||||
}
|
||||
@misc{longpre2023flan,
|
||||
title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
|
||||
author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
|
||||
year={2023},
|
||||
eprint={2301.13688},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.AI}
|
||||
}
|
||||
@misc{touvron2023llama,
|
||||
title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
|
||||
author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
|
||||
year={2023},
|
||||
eprint={2307.09288},
|
||||
archivePrefix={arXiv},
|
||||
}
|
||||
```
|
||||
50
USE_POLICY.md
Normal file
50
USE_POLICY.md
Normal file
@@ -0,0 +1,50 @@
|
||||
# Llama 2 Acceptable Use Policy
|
||||
|
||||
Meta is committed to promoting safe and fair use of its tools and features, including Llama 2. If you access or use Llama 2, you agree to this Acceptable Use Policy (“Policy”). The most recent copy of this policy can be found at [ai.meta.com/llama/use-policy](http://ai.meta.com/llama/use-policy).
|
||||
|
||||
## Prohibited Uses
|
||||
We want everyone to use Llama 2 safely and responsibly. You agree you will not use, or allow others to use, Llama 2 to:
|
||||
|
||||
1. Violate the law or others’ rights, including to:
|
||||
1. Engage in, promote, generate, contribute to, encourage, plan, incite, or further illegal or unlawful activity or content, such as:
|
||||
1. Violence or terrorism
|
||||
2. Exploitation or harm to children, including the solicitation, creation, acquisition, or dissemination of child exploitative content or failure to report Child Sexual Abuse Material
|
||||
3. Human trafficking, exploitation, and sexual violence
|
||||
4. The illegal distribution of information or materials to minors, including obscene materials, or failure to employ legally required age-gating in connection with such information or materials.
|
||||
5. Sexual solicitation
|
||||
6. Any other criminal activity
|
||||
2. Engage in, promote, incite, or facilitate the harassment, abuse, threatening, or bullying of individuals or groups of individuals
|
||||
3. Engage in, promote, incite, or facilitate discrimination or other unlawful or harmful conduct in the provision of employment, employment benefits, credit, housing, other economic benefits, or other essential goods and services
|
||||
4. Engage in the unauthorized or unlicensed practice of any profession including, but not limited to, financial, legal, medical/health, or related professional practices
|
||||
5. Collect, process, disclose, generate, or infer health, demographic, or other sensitive personal or private information about individuals without rights and consents required by applicable laws
|
||||
6. Engage in or facilitate any action or generate any content that infringes, misappropriates, or otherwise violates any third-party rights, including the outputs or results of any products or services using the Llama 2 Materials
|
||||
7. Create, generate, or facilitate the creation of malicious code, malware, computer viruses or do anything else that could disable, overburden, interfere with or impair the proper working, integrity, operation or appearance of a website or computer system
|
||||
|
||||
|
||||
|
||||
2. Engage in, promote, incite, facilitate, or assist in the planning or development of activities that present a risk of death or bodily harm to individuals, including use of Llama 2 related to the following:
|
||||
1. Military, warfare, nuclear industries or applications, espionage, use for materials or activities that are subject to the International Traffic Arms Regulations (ITAR) maintained by the United States Department of State
|
||||
2. Guns and illegal weapons (including weapon development)
|
||||
3. Illegal drugs and regulated/controlled substances
|
||||
4. Operation of critical infrastructure, transportation technologies, or heavy machinery
|
||||
5. Self-harm or harm to others, including suicide, cutting, and eating disorders
|
||||
6. Any content intended to incite or promote violence, abuse, or any infliction of bodily harm to an individual
|
||||
|
||||
|
||||
|
||||
3. Intentionally deceive or mislead others, including use of Llama 2 related to the following:
|
||||
1. Generating, promoting, or furthering fraud or the creation or promotion of disinformation
|
||||
2. Generating, promoting, or furthering defamatory content, including the creation of defamatory statements, images, or other content
|
||||
3. Generating, promoting, or further distributing spam
|
||||
4. Impersonating another individual without consent, authorization, or legal right
|
||||
5. Representing that the use of Llama 2 or outputs are human-generated
|
||||
6. Generating or facilitating false online engagement, including fake reviews and other means of fake online engagement
|
||||
4. Fail to appropriately disclose to end users any known dangers of your AI system
|
||||
|
||||
Please report any violation of this Policy, software “bug,” or other problems that could lead to a violation of this Policy through one of the following means:
|
||||
|
||||
* Reporting issues with the model: [github.com/facebookresearch/llama](http://github.com/facebookresearch/llama)
|
||||
* Reporting risky content generated by the model: [developers.facebook.com/llama_output_feedback](http://developers.facebook.com/llama_output_feedback)
|
||||
* Reporting bugs and security concerns: [facebook.com/whitehat/info](http://facebook.com/whitehat/info)
|
||||
* Reporting violations of the Acceptable Use Policy or unlicensed uses of Llama: [LlamaUseReport@meta.com](mailto:LlamaUseReport@meta.com)
|
||||
|
||||
4
added_tokens.json
Normal file
4
added_tokens.json
Normal file
@@ -0,0 +1,4 @@
|
||||
{
|
||||
"<|PAD|>": 32001,
|
||||
"<|end_of_turn|>": 32000
|
||||
}
|
||||
35
config.json
Normal file
35
config.json
Normal file
@@ -0,0 +1,35 @@
|
||||
{
|
||||
"_name_or_path": "imone/LLaMA2_13B_with_EOT_token",
|
||||
"architectures": [
|
||||
"LlamaForCausalLM"
|
||||
],
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 5120,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 13824,
|
||||
"max_position_embeddings": 4096,
|
||||
"model_type": "llama",
|
||||
"num_attention_heads": 40,
|
||||
"num_hidden_layers": 40,
|
||||
"pad_token_id": 0,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.28.1",
|
||||
"use_cache": true,
|
||||
"vocab_size": 32002,
|
||||
"pretraining_tp": 1,
|
||||
"quantization_config": {
|
||||
"bits": 4,
|
||||
"group_size": 128,
|
||||
"damp_percent": 0.1,
|
||||
"desc_act": false,
|
||||
"sym": true,
|
||||
"true_sequential": true,
|
||||
"model_name_or_path": null,
|
||||
"model_file_base_name": "model",
|
||||
"quant_method": "gptq"
|
||||
}
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||
3
model.safetensors
Normal file
3
model.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ed044b829ce0c794b1a764335a1b35883967bc406ec00e540e946e6fe02f8aef
|
||||
size 7259490616
|
||||
10
quantize_config.json
Normal file
10
quantize_config.json
Normal file
@@ -0,0 +1,10 @@
|
||||
{
|
||||
"bits": 4,
|
||||
"group_size": 128,
|
||||
"damp_percent": 0.1,
|
||||
"desc_act": false,
|
||||
"sym": true,
|
||||
"true_sequential": true,
|
||||
"model_name_or_path": null,
|
||||
"model_file_base_name": "model"
|
||||
}
|
||||
21
special_tokens_map.json
Normal file
21
special_tokens_map.json
Normal file
@@ -0,0 +1,21 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<|end_of_turn|>",
|
||||
"<|PAD|>"
|
||||
],
|
||||
"bos_token": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": "<|end_of_turn|>",
|
||||
"unk_token": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
93409
tokenizer.json
Normal file
93409
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
34
tokenizer_config.json
Normal file
34
tokenizer_config.json
Normal file
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"add_bos_token": true,
|
||||
"add_eos_token": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"legacy": true,
|
||||
"model_max_length": 1000000000000000019884624838656,
|
||||
"pad_token": null,
|
||||
"sp_model_kwargs": {},
|
||||
"tokenizer_class": "LlamaTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
Reference in New Issue
Block a user