初始化项目,由ModelHub XC社区提供模型
Model: TheBloke/LlongOrca-7B-16K-AWQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
model.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
126
LICENSE.txt
Normal file
126
LICENSE.txt
Normal file
@@ -0,0 +1,126 @@
|
||||
LLAMA 2 COMMUNITY LICENSE AGREEMENT
|
||||
Llama 2 Version Release Date: July 18, 2023
|
||||
|
||||
"Agreement" means the terms and conditions for use, reproduction, distribution and
|
||||
modification of the Llama Materials set forth herein.
|
||||
|
||||
"Documentation" means the specifications, manuals and documentation
|
||||
accompanying Llama 2 distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Licensee" or "you" means you, or your employer or any other person or entity (if
|
||||
you are entering into this Agreement on such person or entity's behalf), of the age
|
||||
required under applicable laws, rules or regulations to provide legal consent and that
|
||||
has legal authority to bind your employer or such other person or entity if you are
|
||||
entering in this Agreement on their behalf.
|
||||
|
||||
"Llama 2" means the foundational large language models and software and
|
||||
algorithms, including machine-learning model code, trained model weights,
|
||||
inference-enabling code, training-enabling code, fine-tuning enabling code and other
|
||||
elements of the foregoing distributed by Meta at ai.meta.com/resources/models-and-
|
||||
libraries/llama-downloads/.
|
||||
|
||||
"Llama Materials" means, collectively, Meta's proprietary Llama 2 and
|
||||
Documentation (and any portion thereof) made available under this Agreement.
|
||||
|
||||
"Meta" or "we" means Meta Platforms Ireland Limited (if you are located in or, if you
|
||||
are an entity, your principal place of business is in the EEA or Switzerland) and Meta
|
||||
Platforms, Inc. (if you are located outside of the EEA or Switzerland).
|
||||
|
||||
By clicking "I Accept" below or by using or distributing any portion or element of the
|
||||
Llama Materials, you agree to be bound by this Agreement.
|
||||
|
||||
1. License Rights and Redistribution.
|
||||
|
||||
a. Grant of Rights. You are granted a non-exclusive, worldwide, non-
|
||||
transferable and royalty-free limited license under Meta's intellectual property or
|
||||
other rights owned by Meta embodied in the Llama Materials to use, reproduce,
|
||||
distribute, copy, create derivative works of, and make modifications to the Llama
|
||||
Materials.
|
||||
|
||||
b. Redistribution and Use.
|
||||
|
||||
i. If you distribute or make the Llama Materials, or any derivative works
|
||||
thereof, available to a third party, you shall provide a copy of this Agreement to such
|
||||
third party.
|
||||
ii. If you receive Llama Materials, or any derivative works thereof, from
|
||||
a Licensee as part of an integrated end user product, then Section 2 of this
|
||||
Agreement will not apply to you.
|
||||
|
||||
iii. You must retain in all copies of the Llama Materials that you
|
||||
distribute the following attribution notice within a "Notice" text file distributed as a
|
||||
part of such copies: "Llama 2 is licensed under the LLAMA 2 Community License,
|
||||
Copyright (c) Meta Platforms, Inc. All Rights Reserved."
|
||||
|
||||
iv. Your use of the Llama Materials must comply with applicable laws
|
||||
and regulations (including trade compliance laws and regulations) and adhere to the
|
||||
Acceptable Use Policy for the Llama Materials (available at
|
||||
https://ai.meta.com/llama/use-policy), which is hereby incorporated by reference into
|
||||
this Agreement.
|
||||
|
||||
v. You will not use the Llama Materials or any output or results of the
|
||||
Llama Materials to improve any other large language model (excluding Llama 2 or
|
||||
derivative works thereof).
|
||||
|
||||
2. Additional Commercial Terms. If, on the Llama 2 version release date, the
|
||||
monthly active users of the products or services made available by or for Licensee,
|
||||
or Licensee's affiliates, is greater than 700 million monthly active users in the
|
||||
preceding calendar month, you must request a license from Meta, which Meta may
|
||||
grant to you in its sole discretion, and you are not authorized to exercise any of the
|
||||
rights under this Agreement unless or until Meta otherwise expressly grants you
|
||||
such rights.
|
||||
|
||||
3. Disclaimer of Warranty. UNLESS REQUIRED BY APPLICABLE LAW, THE
|
||||
LLAMA MATERIALS AND ANY OUTPUT AND RESULTS THEREFROM ARE
|
||||
PROVIDED ON AN "AS IS" BASIS, WITHOUT WARRANTIES OF ANY KIND,
|
||||
EITHER EXPRESS OR IMPLIED, INCLUDING, WITHOUT LIMITATION, ANY
|
||||
WARRANTIES OF TITLE, NON-INFRINGEMENT, MERCHANTABILITY, OR
|
||||
FITNESS FOR A PARTICULAR PURPOSE. YOU ARE SOLELY RESPONSIBLE
|
||||
FOR DETERMINING THE APPROPRIATENESS OF USING OR REDISTRIBUTING
|
||||
THE LLAMA MATERIALS AND ASSUME ANY RISKS ASSOCIATED WITH YOUR
|
||||
USE OF THE LLAMA MATERIALS AND ANY OUTPUT AND RESULTS.
|
||||
|
||||
4. Limitation of Liability. IN NO EVENT WILL META OR ITS AFFILIATES BE
|
||||
LIABLE UNDER ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, TORT,
|
||||
NEGLIGENCE, PRODUCTS LIABILITY, OR OTHERWISE, ARISING OUT OF THIS
|
||||
AGREEMENT, FOR ANY LOST PROFITS OR ANY INDIRECT, SPECIAL,
|
||||
CONSEQUENTIAL, INCIDENTAL, EXEMPLARY OR PUNITIVE DAMAGES, EVEN
|
||||
IF META OR ITS AFFILIATES HAVE BEEN ADVISED OF THE POSSIBILITY OF
|
||||
ANY OF THE FOREGOING.
|
||||
|
||||
5. Intellectual Property.
|
||||
|
||||
a. No trademark licenses are granted under this Agreement, and in
|
||||
connection with the Llama Materials, neither Meta nor Licensee may use any name
|
||||
or mark owned by or associated with the other or any of its affiliates, except as
|
||||
required for reasonable and customary use in describing and redistributing the
|
||||
Llama Materials.
|
||||
|
||||
b. Subject to Meta's ownership of Llama Materials and derivatives made by or
|
||||
for Meta, with respect to any derivative works and modifications of the Llama
|
||||
Materials that are made by you, as between you and Meta, you are and will be the
|
||||
owner of such derivative works and modifications.
|
||||
|
||||
c. If you institute litigation or other proceedings against Meta or any entity
|
||||
(including a cross-claim or counterclaim in a lawsuit) alleging that the Llama
|
||||
Materials or Llama 2 outputs or results, or any portion of any of the foregoing,
|
||||
constitutes infringement of intellectual property or other rights owned or licensable
|
||||
by you, then any licenses granted to you under this Agreement shall terminate as of
|
||||
the date such litigation or claim is filed or instituted. You will indemnify and hold
|
||||
harmless Meta from and against any claim by any third party arising out of or related
|
||||
to your use or distribution of the Llama Materials.
|
||||
|
||||
6. Term and Termination. The term of this Agreement will commence upon your
|
||||
acceptance of this Agreement or access to the Llama Materials and will continue in
|
||||
full force and effect until terminated in accordance with the terms and conditions
|
||||
herein. Meta may terminate this Agreement if you are in breach of any term or
|
||||
condition of this Agreement. Upon termination of this Agreement, you shall delete
|
||||
and cease use of the Llama Materials. Sections 3, 4 and 7 shall survive the
|
||||
termination of this Agreement.
|
||||
|
||||
7. Governing Law and Jurisdiction. This Agreement will be governed and
|
||||
construed under the laws of the State of California without regard to choice of law
|
||||
principles, and the UN Convention on Contracts for the International Sale of Goods
|
||||
does not apply to this Agreement. The courts of California shall have exclusive
|
||||
jurisdiction of any dispute arising out of this Agreement.
|
||||
|
||||
1
Notice
Normal file
1
Notice
Normal file
@@ -0,0 +1 @@
|
||||
Llama 2 is licensed under the LLAMA 2 Community License, Copyright © Meta Platforms, Inc. All Rights Reserved.
|
||||
408
README.md
Normal file
408
README.md
Normal file
@@ -0,0 +1,408 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
license: llama2
|
||||
library_name: transformers
|
||||
datasets:
|
||||
- Open-Orca/OpenOrca
|
||||
model_name: LlongOrca 7B 16K
|
||||
base_model: Open-Orca/LlongOrca-7B-16k
|
||||
inference: false
|
||||
model_creator: Open-Orca
|
||||
model_type: llama
|
||||
pipeline_tag: text-generation
|
||||
prompt_template: '<|im_start|>system
|
||||
|
||||
{system_message}<|im_end|>
|
||||
|
||||
<|im_start|>user
|
||||
|
||||
{prompt}<|im_end|>
|
||||
|
||||
<|im_start|>assistant
|
||||
|
||||
'
|
||||
quantized_by: TheBloke
|
||||
---
|
||||
|
||||
<!-- header start -->
|
||||
<!-- 200823 -->
|
||||
<div style="width: auto; margin-left: auto; margin-right: auto">
|
||||
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
|
||||
</div>
|
||||
<div style="display: flex; justify-content: space-between; width: 100%;">
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-start;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://discord.gg/theblokeai">Chat & support: TheBloke's Discord server</a></p>
|
||||
</div>
|
||||
<div style="display: flex; flex-direction: column; align-items: flex-end;">
|
||||
<p style="margin-top: 0.5em; margin-bottom: 0em;"><a href="https://www.patreon.com/TheBlokeAI">Want to contribute? TheBloke's Patreon page</a></p>
|
||||
</div>
|
||||
</div>
|
||||
<div style="text-align:center; margin-top: 0em; margin-bottom: 0em"><p style="margin-top: 0.25em; margin-bottom: 0em;">TheBloke's LLM work is generously supported by a grant from <a href="https://a16z.com">andreessen horowitz (a16z)</a></p></div>
|
||||
<hr style="margin-top: 1.0em; margin-bottom: 1.0em;">
|
||||
<!-- header end -->
|
||||
|
||||
# LlongOrca 7B 16K - AWQ
|
||||
- Model creator: [Open-Orca](https://huggingface.co/Open-Orca)
|
||||
- Original model: [LlongOrca 7B 16K](https://huggingface.co/Open-Orca/LlongOrca-7B-16k)
|
||||
|
||||
<!-- description start -->
|
||||
## Description
|
||||
|
||||
This repo contains AWQ model files for [Open-Orca's LlongOrca 7B 16K](https://huggingface.co/Open-Orca/LlongOrca-7B-16k).
|
||||
|
||||
|
||||
### About AWQ
|
||||
|
||||
AWQ is an efficient, accurate and blazing-fast low-bit weight quantization method, currently supporting 4-bit quantization. Compared to GPTQ, it offers faster Transformers-based inference.
|
||||
|
||||
It is also now supported by continuous batching server [vLLM](https://github.com/vllm-project/vllm), allowing use of AWQ models for high-throughput concurrent inference in multi-user server scenarios. Note that, at the time of writing, overall throughput is still lower than running vLLM with unquantised models, however using AWQ enables using much smaller GPUs which can lead to easier deployment and overall cost savings. For example, a 70B model can be run on 1 x 48GB GPU instead of 2 x 80GB.
|
||||
<!-- description end -->
|
||||
<!-- repositories-available start -->
|
||||
## Repositories available
|
||||
|
||||
* [AWQ model(s) for GPU inference.](https://huggingface.co/TheBloke/LlongOrca-7B-16K-AWQ)
|
||||
* [GPTQ models for GPU inference, with multiple quantisation parameter options.](https://huggingface.co/TheBloke/LlongOrca-7B-16K-GPTQ)
|
||||
* [2, 3, 4, 5, 6 and 8-bit GGUF models for CPU+GPU inference](https://huggingface.co/TheBloke/LlongOrca-7B-16K-GGUF)
|
||||
* [Open-Orca's original unquantised fp16 model in pytorch format, for GPU inference and for further conversions](https://huggingface.co/Open-Orca/LlongOrca-7B-16k)
|
||||
<!-- repositories-available end -->
|
||||
|
||||
<!-- prompt-template start -->
|
||||
## Prompt template: ChatML
|
||||
|
||||
```
|
||||
<|im_start|>system
|
||||
{system_message}<|im_end|>
|
||||
<|im_start|>user
|
||||
{prompt}<|im_end|>
|
||||
<|im_start|>assistant
|
||||
|
||||
```
|
||||
|
||||
<!-- prompt-template end -->
|
||||
|
||||
|
||||
<!-- README_AWQ.md-provided-files start -->
|
||||
## Provided files and AWQ parameters
|
||||
|
||||
For my first release of AWQ models, I am releasing 128g models only. I will consider adding 32g as well if there is interest, and once I have done perplexity and evaluation comparisons, but at this time 32g models are still not fully tested with AutoAWQ and vLLM.
|
||||
|
||||
Models are released as sharded safetensors files.
|
||||
|
||||
| Branch | Bits | GS | AWQ Dataset | Seq Len | Size |
|
||||
| ------ | ---- | -- | ----------- | ------- | ---- |
|
||||
| [main](https://huggingface.co/TheBloke/LlongOrca-7B-16K-AWQ/tree/main) | 4 | 128 | [wikitext](https://huggingface.co/datasets/wikitext/viewer/wikitext-2-v1/test) | 4096 | 3.89 GB
|
||||
|
||||
<!-- README_AWQ.md-provided-files end -->
|
||||
|
||||
<!-- README_AWQ.md-use-from-vllm start -->
|
||||
## Serving this model from vLLM
|
||||
|
||||
Documentation on installing and using vLLM [can be found here](https://vllm.readthedocs.io/en/latest/).
|
||||
|
||||
- When using vLLM as a server, pass the `--quantization awq` parameter, for example:
|
||||
|
||||
```shell
|
||||
python3 python -m vllm.entrypoints.api_server --model TheBloke/LlongOrca-7B-16K-AWQ --quantization awq
|
||||
```
|
||||
|
||||
When using vLLM from Python code, pass the `quantization=awq` parameter, for example:
|
||||
|
||||
```python
|
||||
from vllm import LLM, SamplingParams
|
||||
|
||||
prompts = [
|
||||
"Hello, my name is",
|
||||
"The president of the United States is",
|
||||
"The capital of France is",
|
||||
"The future of AI is",
|
||||
]
|
||||
sampling_params = SamplingParams(temperature=0.8, top_p=0.95)
|
||||
|
||||
llm = LLM(model="TheBloke/LlongOrca-7B-16K-AWQ", quantization="awq")
|
||||
|
||||
outputs = llm.generate(prompts, sampling_params)
|
||||
|
||||
# Print the outputs.
|
||||
for output in outputs:
|
||||
prompt = output.prompt
|
||||
generated_text = output.outputs[0].text
|
||||
print(f"Prompt: {prompt!r}, Generated text: {generated_text!r}")
|
||||
```
|
||||
<!-- README_AWQ.md-use-from-vllm start -->
|
||||
|
||||
<!-- README_AWQ.md-use-from-python start -->
|
||||
## How to use this AWQ model from Python code
|
||||
|
||||
### Install the necessary packages
|
||||
|
||||
Requires: [AutoAWQ](https://github.com/casper-hansen/AutoAWQ) 0.0.2 or later
|
||||
|
||||
```shell
|
||||
pip3 install autoawq
|
||||
```
|
||||
|
||||
If you have problems installing [AutoAWQ](https://github.com/casper-hansen/AutoAWQ) using the pre-built wheels, install it from source instead:
|
||||
|
||||
```shell
|
||||
pip3 uninstall -y autoawq
|
||||
git clone https://github.com/casper-hansen/AutoAWQ
|
||||
cd AutoAWQ
|
||||
pip3 install .
|
||||
```
|
||||
|
||||
### You can then try the following example code
|
||||
|
||||
```python
|
||||
from awq import AutoAWQForCausalLM
|
||||
from transformers import AutoTokenizer
|
||||
|
||||
model_name_or_path = "TheBloke/LlongOrca-7B-16K-AWQ"
|
||||
|
||||
# Load model
|
||||
model = AutoAWQForCausalLM.from_quantized(model_name_or_path, fuse_layers=True,
|
||||
trust_remote_code=False, safetensors=True)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, trust_remote_code=False)
|
||||
|
||||
prompt = "Tell me about AI"
|
||||
prompt_template=f'''<|im_start|>system
|
||||
{system_message}<|im_end|>
|
||||
<|im_start|>user
|
||||
{prompt}<|im_end|>
|
||||
<|im_start|>assistant
|
||||
|
||||
'''
|
||||
|
||||
print("\n\n*** Generate:")
|
||||
|
||||
tokens = tokenizer(
|
||||
prompt_template,
|
||||
return_tensors='pt'
|
||||
).input_ids.cuda()
|
||||
|
||||
# Generate output
|
||||
generation_output = model.generate(
|
||||
tokens,
|
||||
do_sample=True,
|
||||
temperature=0.7,
|
||||
top_p=0.95,
|
||||
top_k=40,
|
||||
max_new_tokens=512
|
||||
)
|
||||
|
||||
print("Output: ", tokenizer.decode(generation_output[0]))
|
||||
|
||||
# Inference can also be done using transformers' pipeline
|
||||
from transformers import pipeline
|
||||
|
||||
print("*** Pipeline:")
|
||||
pipe = pipeline(
|
||||
"text-generation",
|
||||
model=model,
|
||||
tokenizer=tokenizer,
|
||||
max_new_tokens=512,
|
||||
do_sample=True,
|
||||
temperature=0.7,
|
||||
top_p=0.95,
|
||||
top_k=40,
|
||||
repetition_penalty=1.1
|
||||
)
|
||||
|
||||
print(pipe(prompt_template)[0]['generated_text'])
|
||||
```
|
||||
<!-- README_AWQ.md-use-from-python end -->
|
||||
|
||||
<!-- README_AWQ.md-compatibility start -->
|
||||
## Compatibility
|
||||
|
||||
The files provided are tested to work with [AutoAWQ](https://github.com/casper-hansen/AutoAWQ), and [vLLM](https://github.com/vllm-project/vllm).
|
||||
|
||||
[Huggingface Text Generation Inference (TGI)](https://github.com/huggingface/text-generation-inference) is not yet compatible with AWQ, but a PR is open which should bring support soon: [TGI PR #781](https://github.com/huggingface/text-generation-inference/issues/781).
|
||||
<!-- README_AWQ.md-compatibility end -->
|
||||
|
||||
<!-- footer start -->
|
||||
<!-- 200823 -->
|
||||
## Discord
|
||||
|
||||
For further support, and discussions on these models and AI in general, join us at:
|
||||
|
||||
[TheBloke AI's Discord server](https://discord.gg/theblokeai)
|
||||
|
||||
## Thanks, and how to contribute
|
||||
|
||||
Thanks to the [chirper.ai](https://chirper.ai) team!
|
||||
|
||||
Thanks to Clay from [gpus.llm-utils.org](llm-utils)!
|
||||
|
||||
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
|
||||
|
||||
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
|
||||
|
||||
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
|
||||
|
||||
* Patreon: https://patreon.com/TheBlokeAI
|
||||
* Ko-Fi: https://ko-fi.com/TheBlokeAI
|
||||
|
||||
**Special thanks to**: Aemon Algiz.
|
||||
|
||||
**Patreon special mentions**: Alicia Loh, Stephen Murray, K, Ajan Kanaga, RoA, Magnesian, Deo Leter, Olakabola, Eugene Pentland, zynix, Deep Realms, Raymond Fosdick, Elijah Stavena, Iucharbius, Erik Bjäreholt, Luis Javier Navarrete Lozano, Nicholas, theTransient, John Detwiler, alfie_i, knownsqashed, Mano Prime, Willem Michiel, Enrico Ros, LangChain4j, OG, Michael Dempsey, Pierre Kircher, Pedro Madruga, James Bentley, Thomas Belote, Luke @flexchar, Leonard Tan, Johann-Peter Hartmann, Illia Dulskyi, Fen Risland, Chadd, S_X, Jeff Scroggin, Ken Nordquist, Sean Connelly, Artur Olbinski, Swaroop Kallakuri, Jack West, Ai Maven, David Ziegler, Russ Johnson, transmissions 11, John Villwock, Alps Aficionado, Clay Pascal, Viktor Bowallius, Subspace Studios, Rainer Wilmers, Trenton Dambrowitz, vamX, Michael Levine, 준교 김, Brandon Frisco, Kalila, Trailburnt, Randy H, Talal Aujan, Nathan Dryer, Vadim, 阿明, ReadyPlayerEmma, Tiffany J. Kim, George Stoitzev, Spencer Kim, Jerry Meng, Gabriel Tamborski, Cory Kujawski, Jeffrey Morgan, Spiking Neurons AB, Edmond Seymore, Alexandros Triantafyllidis, Lone Striker, Cap'n Zoog, Nikolai Manek, danny, ya boyyy, Derek Yates, usrbinkat, Mandus, TL, Nathan LeClaire, subjectnull, Imad Khwaja, webtim, Raven Klaugh, Asp the Wyvern, Gabriel Puliatti, Caitlyn Gatomon, Joseph William Delisle, Jonathan Leane, Luke Pendergrass, SuperWojo, Sebastain Graf, Will Dee, Fred von Graf, Andrey, Dan Guido, Daniel P. Andersen, Nitin Borwankar, Elle, Vitor Caleffi, biorpg, jjj, NimbleBox.ai, Pieter, Matthew Berman, terasurfer, Michael Davis, Alex, Stanislav Ovsiannikov
|
||||
|
||||
|
||||
Thank you to all my generous patrons and donaters!
|
||||
|
||||
And thank you again to a16z for their generous grant.
|
||||
|
||||
<!-- footer end -->
|
||||
|
||||
# Original model card: Open-Orca's LlongOrca 7B 16K
|
||||
|
||||
|
||||
<p><h1>🐋 The First Llong Context Orca! 🐋</h1></p>
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
# OpenOrca - LlongOrca - 7B - 16k
|
||||
|
||||
We have used our own [OpenOrca dataset](https://huggingface.co/datasets/Open-Orca/OpenOrca) to fine-tune on top of [LLongMA-2-7b-16k](https://huggingface.co/conceptofmind/LLongMA-2-7b-16k).
|
||||
This dataset is our attempt to reproduce the dataset generated for Microsoft Research's [Orca Paper](https://arxiv.org/abs/2306.02707).
|
||||
We use [OpenChat](https://huggingface.co/openchat) packing, trained with [Axolotl](https://github.com/OpenAccess-AI-Collective/axolotl).
|
||||
|
||||
This release is trained on a curated filtered subset of most of our GPT-4 augmented data.
|
||||
It is the same subset of our data as was used in our [OpenOrcaxOpenChat-Preview2-13B model](https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B).
|
||||
|
||||
This release reveals that stacking our training on an existing long context fine-tuned model yields significant improvements to model performance.
|
||||
We measured this with BigBench-Hard and AGIEval results, finding **~134%** of the base Llongma2-16k model's performance on average.
|
||||
|
||||
We have run extensive evaluations internally and expect this model to place number 4 on the HuggingFaceH4 Open LLM Leaderboard for 7B models, but with >99% performance of the first place and **place number 1** for longer context 7B models.
|
||||
|
||||
We did this training as part of testing integration of OpenChat's [MultiPack algorithm](https://github.com/imoneoi/multipack_sampler) into the Axolotl trainer.
|
||||
MultiPack achieves 99.85% bin-packing efficiency on our dataset.
|
||||
This has significantly reduced training time, with efficiency improvement of 3-10X over traditional methods.
|
||||
|
||||
|
||||
<img src="https://raw.githubusercontent.com/imoneoi/openchat/master/assets/logo_new.png" style="width: 300px">
|
||||
|
||||
|
||||
Want to visualize our full (pre-filtering) dataset? Check out our [Nomic Atlas Map](https://atlas.nomic.ai/map/c1b88b47-2d9b-47e0-9002-b80766792582/2560fd25-52fe-42f1-a58f-ff5eccc890d2).
|
||||
|
||||
|
||||
[<img src="https://huggingface.co/Open-Orca/OpenOrca-Preview1-13B/resolve/main/OpenOrca%20Nomic%20Atlas.png" alt="Atlas Nomic Dataset Map" width="400" height="400" />](https://atlas.nomic.ai/map/c1b88b47-2d9b-47e0-9002-b80766792582/2560fd25-52fe-42f1-a58f-ff5eccc890d2)
|
||||
|
||||
|
||||
Many thanks to @EnricoShippole, @theemozilla, and @kaiokendev1 for the fine work on creating the LlongMA-2-7b-16k model this was trained on top of!
|
||||
|
||||
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
|
||||
|
||||
We will also give sneak-peak announcements on our Discord, which you can find here:
|
||||
|
||||
https://AlignmentLab.ai
|
||||
|
||||
# Prompt Template
|
||||
|
||||
We used [OpenAI's Chat Markup Language (ChatML)](https://github.com/openai/openai-python/blob/main/chatml.md) format, with `<|im_start|>` and `<|im_end|>` tokens added to support this.
|
||||
|
||||
## Example Prompt Exchange
|
||||
|
||||
```
|
||||
<|im_start|>system
|
||||
You are LlongOrca, a large language model trained by Alignment Lab AI. Write out your reasoning step-by-step to be sure you get the right answers!
|
||||
<|im_end|>
|
||||
<|im_start|>user
|
||||
How are you<|im_end|>
|
||||
<|im_start|>assistant
|
||||
I am doing well!<|im_end|>
|
||||
<|im_start|>user
|
||||
How are you now?<|im_end|>
|
||||
```
|
||||
|
||||
|
||||
# Evaluation
|
||||
|
||||
We have evaluated using the methodology and tools for the HuggingFace Leaderboard, and find that we have significantly improved upon the base long context model.
|
||||
As well, we should place #4 among all 7B models (and #1 for a model with long context) at release time!
|
||||
|
||||
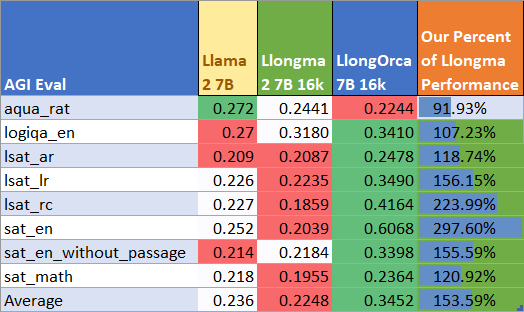
## AGIEval Performance
|
||||
|
||||
We present our performance on AGI Eval in comparison to base Llama2-7B and to [Llongma2-7b-16k](https://huggingface.co/conceptofmind/LLongMA-2-7b-16k), which we trained on top of.
|
||||
This demonstrates the benefits of stacking OpenOrca dataset training on existing models.
|
||||
Most notably, there is a very dramatic improvement of nearly 3X in the English writing performance.
|
||||
|
||||
|
||||
|
||||
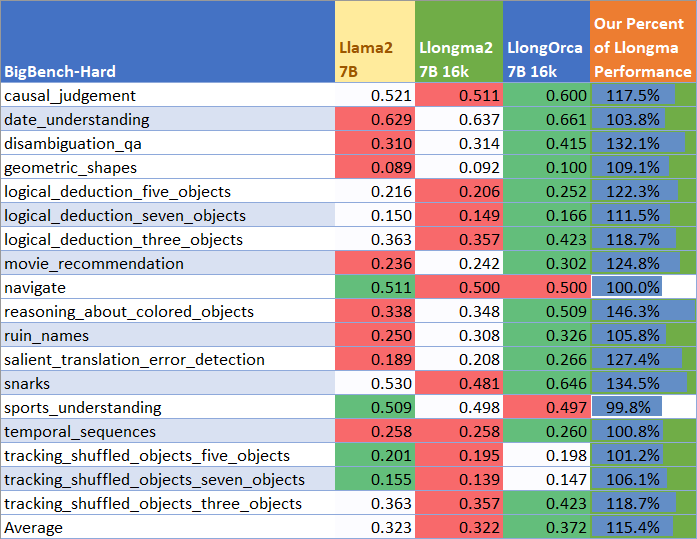
## BigBench-Hard Performance
|
||||
|
||||
We present our performance on BigBench-Hard in comparison to base Llama2-7B and to [Llongma2-7b-16k](https://huggingface.co/conceptofmind/LLongMA-2-7b-16k), which we trained on top of.
|
||||
This demonstrates the benefits of stacking OpenOrca dataset training on existing models.
|
||||
|
||||
|
||||
|
||||
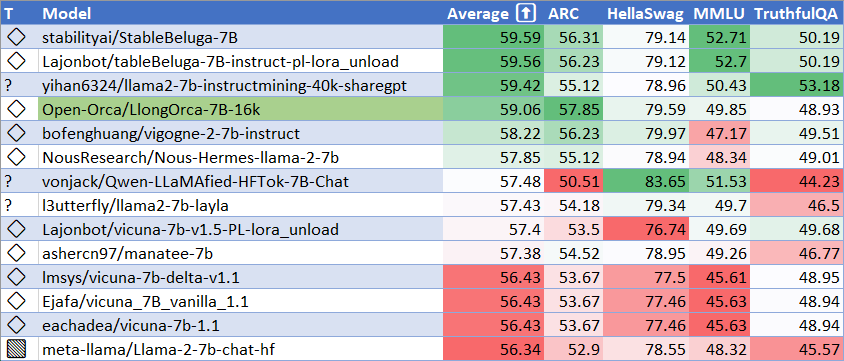
## HuggingFaceH4 Open LLM Leaderboard Performance
|
||||
|
||||
We have run our own tests using parameters matching the [HuggingFaceH4 Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard) evals.
|
||||
|
||||
We place #4 for all 7B models at release time, and #1 for long context models.
|
||||
|
||||
|
||||
|
||||
|
||||
# Dataset
|
||||
|
||||
We used a curated, filtered selection of most of the GPT-4 augmented data from our OpenOrca dataset, which aims to reproduce the Orca Research Paper dataset.
|
||||
Further details of our curation practices will be forthcoming with our full model releases.
|
||||
|
||||
|
||||
# Training
|
||||
|
||||
[<img src="https://raw.githubusercontent.com/OpenAccess-AI-Collective/axolotl/main/image/axolotl-badge-web.png" alt="Built with Axolotl"/>](https://github.com/OpenAccess-AI-Collective/axolotl)
|
||||
|
||||
We trained with 8x A6000-48GB (first-gen) GPUs for 37 hours, completing 4 epochs of full fine tuning on our dataset in one training run.
|
||||
Commodity cost was ~$200.
|
||||
Axolotl training parameters can be found in [configs/oo7b.yml](https://huggingface.co/Open-Orca/LlongOrca-7B-16k/blob/main/configs/oo-7b.yml).
|
||||
We used the `packing-attn` branch of Axolotl during training.
|
||||
|
||||
# Citation
|
||||
|
||||
```bibtex
|
||||
@software{lian2023llongorca7b,
|
||||
title = {LlongOrca7B: Llama2-7B Model Instruct-tuned for Long Context on Filtered OpenOrcaV1 GPT-4 Dataset},
|
||||
author = {Wing Lian and Bleys Goodson and Guan Wang and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
|
||||
year = {2023},
|
||||
publisher = {HuggingFace},
|
||||
journal = {HuggingFace repository},
|
||||
howpublished = {\url{https://https://huggingface.co/Open-Orca/LlongOrca-7B-16k},
|
||||
}
|
||||
@software{openchat,
|
||||
title = {{OpenChat: Advancing Open-source Language Models with Imperfect Data}},
|
||||
author = {Wang, Guan and Cheng, Sijie and Yu, Qiying and Liu, Changling},
|
||||
doi = {10.5281/zenodo.8105775},
|
||||
url = {https://github.com/imoneoi/openchat},
|
||||
version = {pre-release},
|
||||
year = {2023},
|
||||
month = {7},
|
||||
}
|
||||
@misc{mukherjee2023orca,
|
||||
title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
|
||||
author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
|
||||
year={2023},
|
||||
eprint={2306.02707},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL}
|
||||
}
|
||||
@misc{longpre2023flan,
|
||||
title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
|
||||
author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
|
||||
year={2023},
|
||||
eprint={2301.13688},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.AI}
|
||||
}
|
||||
@misc{touvron2023llama,
|
||||
title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
|
||||
author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
|
||||
year={2023},
|
||||
eprint={2307.09288},
|
||||
archivePrefix={arXiv},
|
||||
}
|
||||
```
|
||||
50
USE_POLICY.md
Normal file
50
USE_POLICY.md
Normal file
@@ -0,0 +1,50 @@
|
||||
# Llama 2 Acceptable Use Policy
|
||||
|
||||
Meta is committed to promoting safe and fair use of its tools and features, including Llama 2. If you access or use Llama 2, you agree to this Acceptable Use Policy (“Policy”). The most recent copy of this policy can be found at [ai.meta.com/llama/use-policy](http://ai.meta.com/llama/use-policy).
|
||||
|
||||
## Prohibited Uses
|
||||
We want everyone to use Llama 2 safely and responsibly. You agree you will not use, or allow others to use, Llama 2 to:
|
||||
|
||||
1. Violate the law or others’ rights, including to:
|
||||
1. Engage in, promote, generate, contribute to, encourage, plan, incite, or further illegal or unlawful activity or content, such as:
|
||||
1. Violence or terrorism
|
||||
2. Exploitation or harm to children, including the solicitation, creation, acquisition, or dissemination of child exploitative content or failure to report Child Sexual Abuse Material
|
||||
3. Human trafficking, exploitation, and sexual violence
|
||||
4. The illegal distribution of information or materials to minors, including obscene materials, or failure to employ legally required age-gating in connection with such information or materials.
|
||||
5. Sexual solicitation
|
||||
6. Any other criminal activity
|
||||
2. Engage in, promote, incite, or facilitate the harassment, abuse, threatening, or bullying of individuals or groups of individuals
|
||||
3. Engage in, promote, incite, or facilitate discrimination or other unlawful or harmful conduct in the provision of employment, employment benefits, credit, housing, other economic benefits, or other essential goods and services
|
||||
4. Engage in the unauthorized or unlicensed practice of any profession including, but not limited to, financial, legal, medical/health, or related professional practices
|
||||
5. Collect, process, disclose, generate, or infer health, demographic, or other sensitive personal or private information about individuals without rights and consents required by applicable laws
|
||||
6. Engage in or facilitate any action or generate any content that infringes, misappropriates, or otherwise violates any third-party rights, including the outputs or results of any products or services using the Llama 2 Materials
|
||||
7. Create, generate, or facilitate the creation of malicious code, malware, computer viruses or do anything else that could disable, overburden, interfere with or impair the proper working, integrity, operation or appearance of a website or computer system
|
||||
|
||||
|
||||
|
||||
2. Engage in, promote, incite, facilitate, or assist in the planning or development of activities that present a risk of death or bodily harm to individuals, including use of Llama 2 related to the following:
|
||||
1. Military, warfare, nuclear industries or applications, espionage, use for materials or activities that are subject to the International Traffic Arms Regulations (ITAR) maintained by the United States Department of State
|
||||
2. Guns and illegal weapons (including weapon development)
|
||||
3. Illegal drugs and regulated/controlled substances
|
||||
4. Operation of critical infrastructure, transportation technologies, or heavy machinery
|
||||
5. Self-harm or harm to others, including suicide, cutting, and eating disorders
|
||||
6. Any content intended to incite or promote violence, abuse, or any infliction of bodily harm to an individual
|
||||
|
||||
|
||||
|
||||
3. Intentionally deceive or mislead others, including use of Llama 2 related to the following:
|
||||
1. Generating, promoting, or furthering fraud or the creation or promotion of disinformation
|
||||
2. Generating, promoting, or furthering defamatory content, including the creation of defamatory statements, images, or other content
|
||||
3. Generating, promoting, or further distributing spam
|
||||
4. Impersonating another individual without consent, authorization, or legal right
|
||||
5. Representing that the use of Llama 2 or outputs are human-generated
|
||||
6. Generating or facilitating false online engagement, including fake reviews and other means of fake online engagement
|
||||
4. Fail to appropriately disclose to end users any known dangers of your AI system
|
||||
|
||||
Please report any violation of this Policy, software “bug,” or other problems that could lead to a violation of this Policy through one of the following means:
|
||||
|
||||
* Reporting issues with the model: [github.com/facebookresearch/llama](http://github.com/facebookresearch/llama)
|
||||
* Reporting risky content generated by the model: [developers.facebook.com/llama_output_feedback](http://developers.facebook.com/llama_output_feedback)
|
||||
* Reporting bugs and security concerns: [facebook.com/whitehat/info](http://facebook.com/whitehat/info)
|
||||
* Reporting violations of the Acceptable Use Policy or unlicensed uses of Llama: [LlamaUseReport@meta.com](mailto:LlamaUseReport@meta.com)
|
||||
|
||||
5
added_tokens.json
Normal file
5
added_tokens.json
Normal file
@@ -0,0 +1,5 @@
|
||||
{
|
||||
"<pad>": 32000,
|
||||
"<|im_end|>": 32002,
|
||||
"<|im_start|>": 32001
|
||||
}
|
||||
37
config.json
Normal file
37
config.json
Normal file
@@ -0,0 +1,37 @@
|
||||
{
|
||||
"_name_or_path": "conceptofmind/LLongMA-2-7b-16k",
|
||||
"architectures": [
|
||||
"LlamaForCausalLM"
|
||||
],
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 4096,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 11008,
|
||||
"max_position_embeddings": 16384,
|
||||
"model_type": "llama",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 32,
|
||||
"num_key_value_heads": 32,
|
||||
"pad_token_id": 0,
|
||||
"pretraining_tp": 1,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"rope_scaling": {
|
||||
"factor": 4.0,
|
||||
"type": "linear"
|
||||
},
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.32.0.dev0",
|
||||
"use_cache": true,
|
||||
"use_flash_attention": false,
|
||||
"vocab_size": 32003,
|
||||
"quantization_config": {
|
||||
"quant_method": "awq",
|
||||
"zero_point": true,
|
||||
"group_size": 128,
|
||||
"bits": 4,
|
||||
"version": "gemm"
|
||||
}
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||
9
generation_config.json
Normal file
9
generation_config.json
Normal file
@@ -0,0 +1,9 @@
|
||||
{
|
||||
"_from_model_config": true,
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"pad_token_id": 32000,
|
||||
"temperature": 0.9,
|
||||
"top_p": 0.6,
|
||||
"transformers_version": "4.32.0.dev0"
|
||||
}
|
||||
3
model.safetensors
Normal file
3
model.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:f205b154750dba0f4acfa79b1227b310a6cf0cc5c3223d2dde16009368e5638d
|
||||
size 3889440728
|
||||
6
quant_config.json
Normal file
6
quant_config.json
Normal file
@@ -0,0 +1,6 @@
|
||||
{
|
||||
"zero_point": true,
|
||||
"q_group_size": 128,
|
||||
"w_bit": 4,
|
||||
"version": "GEMM"
|
||||
}
|
||||
18
special_tokens_map.json
Normal file
18
special_tokens_map.json
Normal file
@@ -0,0 +1,18 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": "<|im_end|>",
|
||||
"pad_token": "<unk>",
|
||||
"unk_token": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
93418
tokenizer.json
Normal file
93418
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
36
tokenizer_config.json
Normal file
36
tokenizer_config.json
Normal file
@@ -0,0 +1,36 @@
|
||||
{
|
||||
"add_bos_token": true,
|
||||
"add_eos_token": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"legacy": false,
|
||||
"model_max_length": 16384,
|
||||
"pad_token": null,
|
||||
"sp_model_kwargs": {},
|
||||
"spaces_between_special_tokens": false,
|
||||
"tokenizer_class": "LlamaTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"use_default_system_prompt": true
|
||||
}
|
||||
Reference in New Issue
Block a user