初始化项目,由ModelHub XC社区提供模型
Model: RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf
Source: Original Platform
This commit is contained in:
 ModelHub XC
54
.gitattributes
vendored
Normal file
54
.gitattributes
vendored
Normal file
@@ -0,0 +1,54 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q2_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q3_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q3_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q3_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q3_K_L.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.IQ4_XS.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q4_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.IQ4_NL.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q4_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q4_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q4_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q4_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q5_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q5_K_S.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q5_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q5_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q5_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q6_K.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
CursorCore-QW2.5-1.5B.Q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
3
CursorCore-QW2.5-1.5B.IQ4_NL.gguf
Normal file
3
CursorCore-QW2.5-1.5B.IQ4_NL.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b4b2366738e6cf6a581bd6f2c658e4806c848b9afe09bf5dd48e384bdb0a7524
|
||||
size 941162720
|
||||
3
CursorCore-QW2.5-1.5B.IQ4_XS.gguf
Normal file
3
CursorCore-QW2.5-1.5B.IQ4_XS.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:0e95278de2b4265462e6eb88d5bcab5f8c6f946fd8469195fc7c0238cf2b7aa1
|
||||
size 901853408
|
||||
3
CursorCore-QW2.5-1.5B.Q2_K.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q2_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6c68e7c1c07a55645484d297760394c7bd19e87b01f8ad7f9f351b053d1602ea
|
||||
size 675975392
|
||||
3
CursorCore-QW2.5-1.5B.Q3_K.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q3_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b0cf407721825a2f2912883223763d5db37462c6fbe8d9e58385b4221d30b12e
|
||||
size 823849184
|
||||
3
CursorCore-QW2.5-1.5B.Q3_K_L.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q3_K_L.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d15910d67c14d120aea99fdb579ad5a51c1c46e87cb3d7ae3f2e4f76af4f32f8
|
||||
size 879833312
|
||||
3
CursorCore-QW2.5-1.5B.Q3_K_M.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q3_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b0cf407721825a2f2912883223763d5db37462c6fbe8d9e58385b4221d30b12e
|
||||
size 823849184
|
||||
3
CursorCore-QW2.5-1.5B.Q3_K_S.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q3_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:0f358b2bc55c21ee00d8b46c1d93a72fbf661b775deece4d9ca003418dab6174
|
||||
size 760615136
|
||||
3
CursorCore-QW2.5-1.5B.Q4_0.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q4_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:54ad2e8fb0c58ac8d853eaeff82b35b068c2853ed952b5ac658c60417d963240
|
||||
size 934625504
|
||||
3
CursorCore-QW2.5-1.5B.Q4_1.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q4_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b953829ea82bb26ae4aa47a283ce7ccfc529757c78a92f188707afe9d682bff8
|
||||
size 1016512736
|
||||
3
CursorCore-QW2.5-1.5B.Q4_K.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q4_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:658d5d7d1dbae26f88df6d7180607ce0b77a49a85e882991c6e494793e9e19cb
|
||||
size 985719008
|
||||
3
CursorCore-QW2.5-1.5B.Q4_K_M.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q4_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:658d5d7d1dbae26f88df6d7180607ce0b77a49a85e882991c6e494793e9e19cb
|
||||
size 985719008
|
||||
3
CursorCore-QW2.5-1.5B.Q4_K_S.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q4_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8f8333abc25d97af1ae3b583e89f66f0828f6a51faa9f61521f89cdeff797a4b
|
||||
size 939983072
|
||||
3
CursorCore-QW2.5-1.5B.Q5_0.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q5_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:2cf7dd8d5a98e9866e599d25b702eaaa569b85536021060c117aef7e2af8c283
|
||||
size 1098399968
|
||||
3
CursorCore-QW2.5-1.5B.Q5_1.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q5_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a84a857788f18c69f9442a03b9d3e56ad6b3196143b1e56dd12fe675c2ee941b
|
||||
size 1180287200
|
||||
3
CursorCore-QW2.5-1.5B.Q5_K.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q5_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:aaf5a5c7ac0699329cfda01e7147615d95939b72871933a960afc2c1449b8ae2
|
||||
size 1124720864
|
||||
3
CursorCore-QW2.5-1.5B.Q5_K_M.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q5_K_M.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:aaf5a5c7ac0699329cfda01e7147615d95939b72871933a960afc2c1449b8ae2
|
||||
size 1124720864
|
||||
3
CursorCore-QW2.5-1.5B.Q5_K_S.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q5_K_S.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:1fe81635580dc5ce6aea5b6aade0b09f1e1c497314bcc61c41438295b4111193
|
||||
size 1098399968
|
||||
3
CursorCore-QW2.5-1.5B.Q6_K.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q6_K.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dbb12cbbad930178e13c211c6731e5502cf2b613b839b14a346ee6c6fefd10fe
|
||||
size 1272410336
|
||||
3
CursorCore-QW2.5-1.5B.Q8_0.gguf
Normal file
3
CursorCore-QW2.5-1.5B.Q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9d57057be22351535f543111ba11f777eaab7931248c9d016e414568954cbccb
|
||||
size 1646148320
|
||||
455
README.md
Normal file
455
README.md
Normal file
@@ -0,0 +1,455 @@
|
||||
---
|
||||
tags:
|
||||
- code
|
||||
base_model:
|
||||
- Qwen/Qwen2.5-Coder-1.5B
|
||||
library_name: transformers
|
||||
pipeline_tag: text-generation
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
Quantization made by Richard Erkhov.
|
||||
|
||||
[Github](https://github.com/RichardErkhov)
|
||||
|
||||
[Discord](https://discord.gg/pvy7H8DZMG)
|
||||
|
||||
[Request more models](https://github.com/RichardErkhov/quant_request)
|
||||
|
||||
|
||||
CursorCore-QW2.5-1.5B - GGUF
|
||||
- Model creator: https://huggingface.co/TechxGenus/
|
||||
- Original model: https://huggingface.co/TechxGenus/CursorCore-QW2.5-1.5B/
|
||||
|
||||
|
||||
| Name | Quant method | Size |
|
||||
| ---- | ---- | ---- |
|
||||
| [CursorCore-QW2.5-1.5B.Q2_K.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q2_K.gguf) | Q2_K | 0.63GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q3_K_S.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q3_K_S.gguf) | Q3_K_S | 0.71GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q3_K.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q3_K.gguf) | Q3_K | 0.77GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q3_K_M.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q3_K_M.gguf) | Q3_K_M | 0.77GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q3_K_L.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q3_K_L.gguf) | Q3_K_L | 0.82GB |
|
||||
| [CursorCore-QW2.5-1.5B.IQ4_XS.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.IQ4_XS.gguf) | IQ4_XS | 0.84GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q4_0.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q4_0.gguf) | Q4_0 | 0.87GB |
|
||||
| [CursorCore-QW2.5-1.5B.IQ4_NL.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.IQ4_NL.gguf) | IQ4_NL | 0.88GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q4_K_S.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q4_K_S.gguf) | Q4_K_S | 0.88GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q4_K.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q4_K.gguf) | Q4_K | 0.92GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q4_K_M.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q4_K_M.gguf) | Q4_K_M | 0.92GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q4_1.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q4_1.gguf) | Q4_1 | 0.95GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q5_0.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q5_0.gguf) | Q5_0 | 1.02GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q5_K_S.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q5_K_S.gguf) | Q5_K_S | 1.02GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q5_K.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q5_K.gguf) | Q5_K | 1.05GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q5_K_M.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q5_K_M.gguf) | Q5_K_M | 1.05GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q5_1.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q5_1.gguf) | Q5_1 | 1.1GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q6_K.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q6_K.gguf) | Q6_K | 1.19GB |
|
||||
| [CursorCore-QW2.5-1.5B.Q8_0.gguf](https://huggingface.co/RichardErkhov/TechxGenus_-_CursorCore-QW2.5-1.5B-gguf/blob/main/CursorCore-QW2.5-1.5B.Q8_0.gguf) | Q8_0 | 1.53GB |
|
||||
|
||||
# CursorCore: Assist Programming through Aligning Anything
|
||||
|
||||
<p align="center">
|
||||
<a href="http://arxiv.org/abs/2410.07002">[📄arXiv]</a> |
|
||||
<a href="https://hf.co/papers/2410.07002">[🤗HF Paper]</a> |
|
||||
<a href="https://huggingface.co/collections/TechxGenus/cursorcore-series-6706618c38598468866b60e2">[🤖Models]</a> |
|
||||
<a href="https://github.com/TechxGenus/CursorCore">[🛠️Code]</a> |
|
||||
<a href="https://github.com/TechxGenus/CursorWeb">[Web]</a> |
|
||||
<a href="https://discord.gg/Z5Tev8fV">[Discord]</a>
|
||||
</p>
|
||||
|
||||
<hr>
|
||||
|
||||
- [CursorCore: Assist Programming through Aligning Anything](#cursorcore-assist-programming-through-aligning-anything)
|
||||
- [Introduction](#introduction)
|
||||
- [Models](#models)
|
||||
- [Usage](#usage)
|
||||
- [1) Normal chat](#1-normal-chat)
|
||||
- [2) Assistant-Conversation](#2-assistant-conversation)
|
||||
- [3) Web Demo](#3-web-demo)
|
||||
- [Future Work](#future-work)
|
||||
- [Citation](#citation)
|
||||
- [Contribution](#contribution)
|
||||
|
||||
<hr>
|
||||
|
||||
## Introduction
|
||||
|
||||
CursorCore is a series of open-source models designed for AI-assisted programming. It aims to support features such as automated editing and inline chat, replicating the core abilities of closed-source AI-assisted programming tools like Cursor. This is achieved by aligning data generated through Programming-Instruct. Please read [our paper](http://arxiv.org/abs/2410.07002) to learn more.
|
||||
|
||||
<p align="center">
|
||||
<img width="100%" alt="conversation" src="https://raw.githubusercontent.com/TechxGenus/CursorCore/main/pictures/conversation.png">
|
||||
</p>
|
||||
|
||||
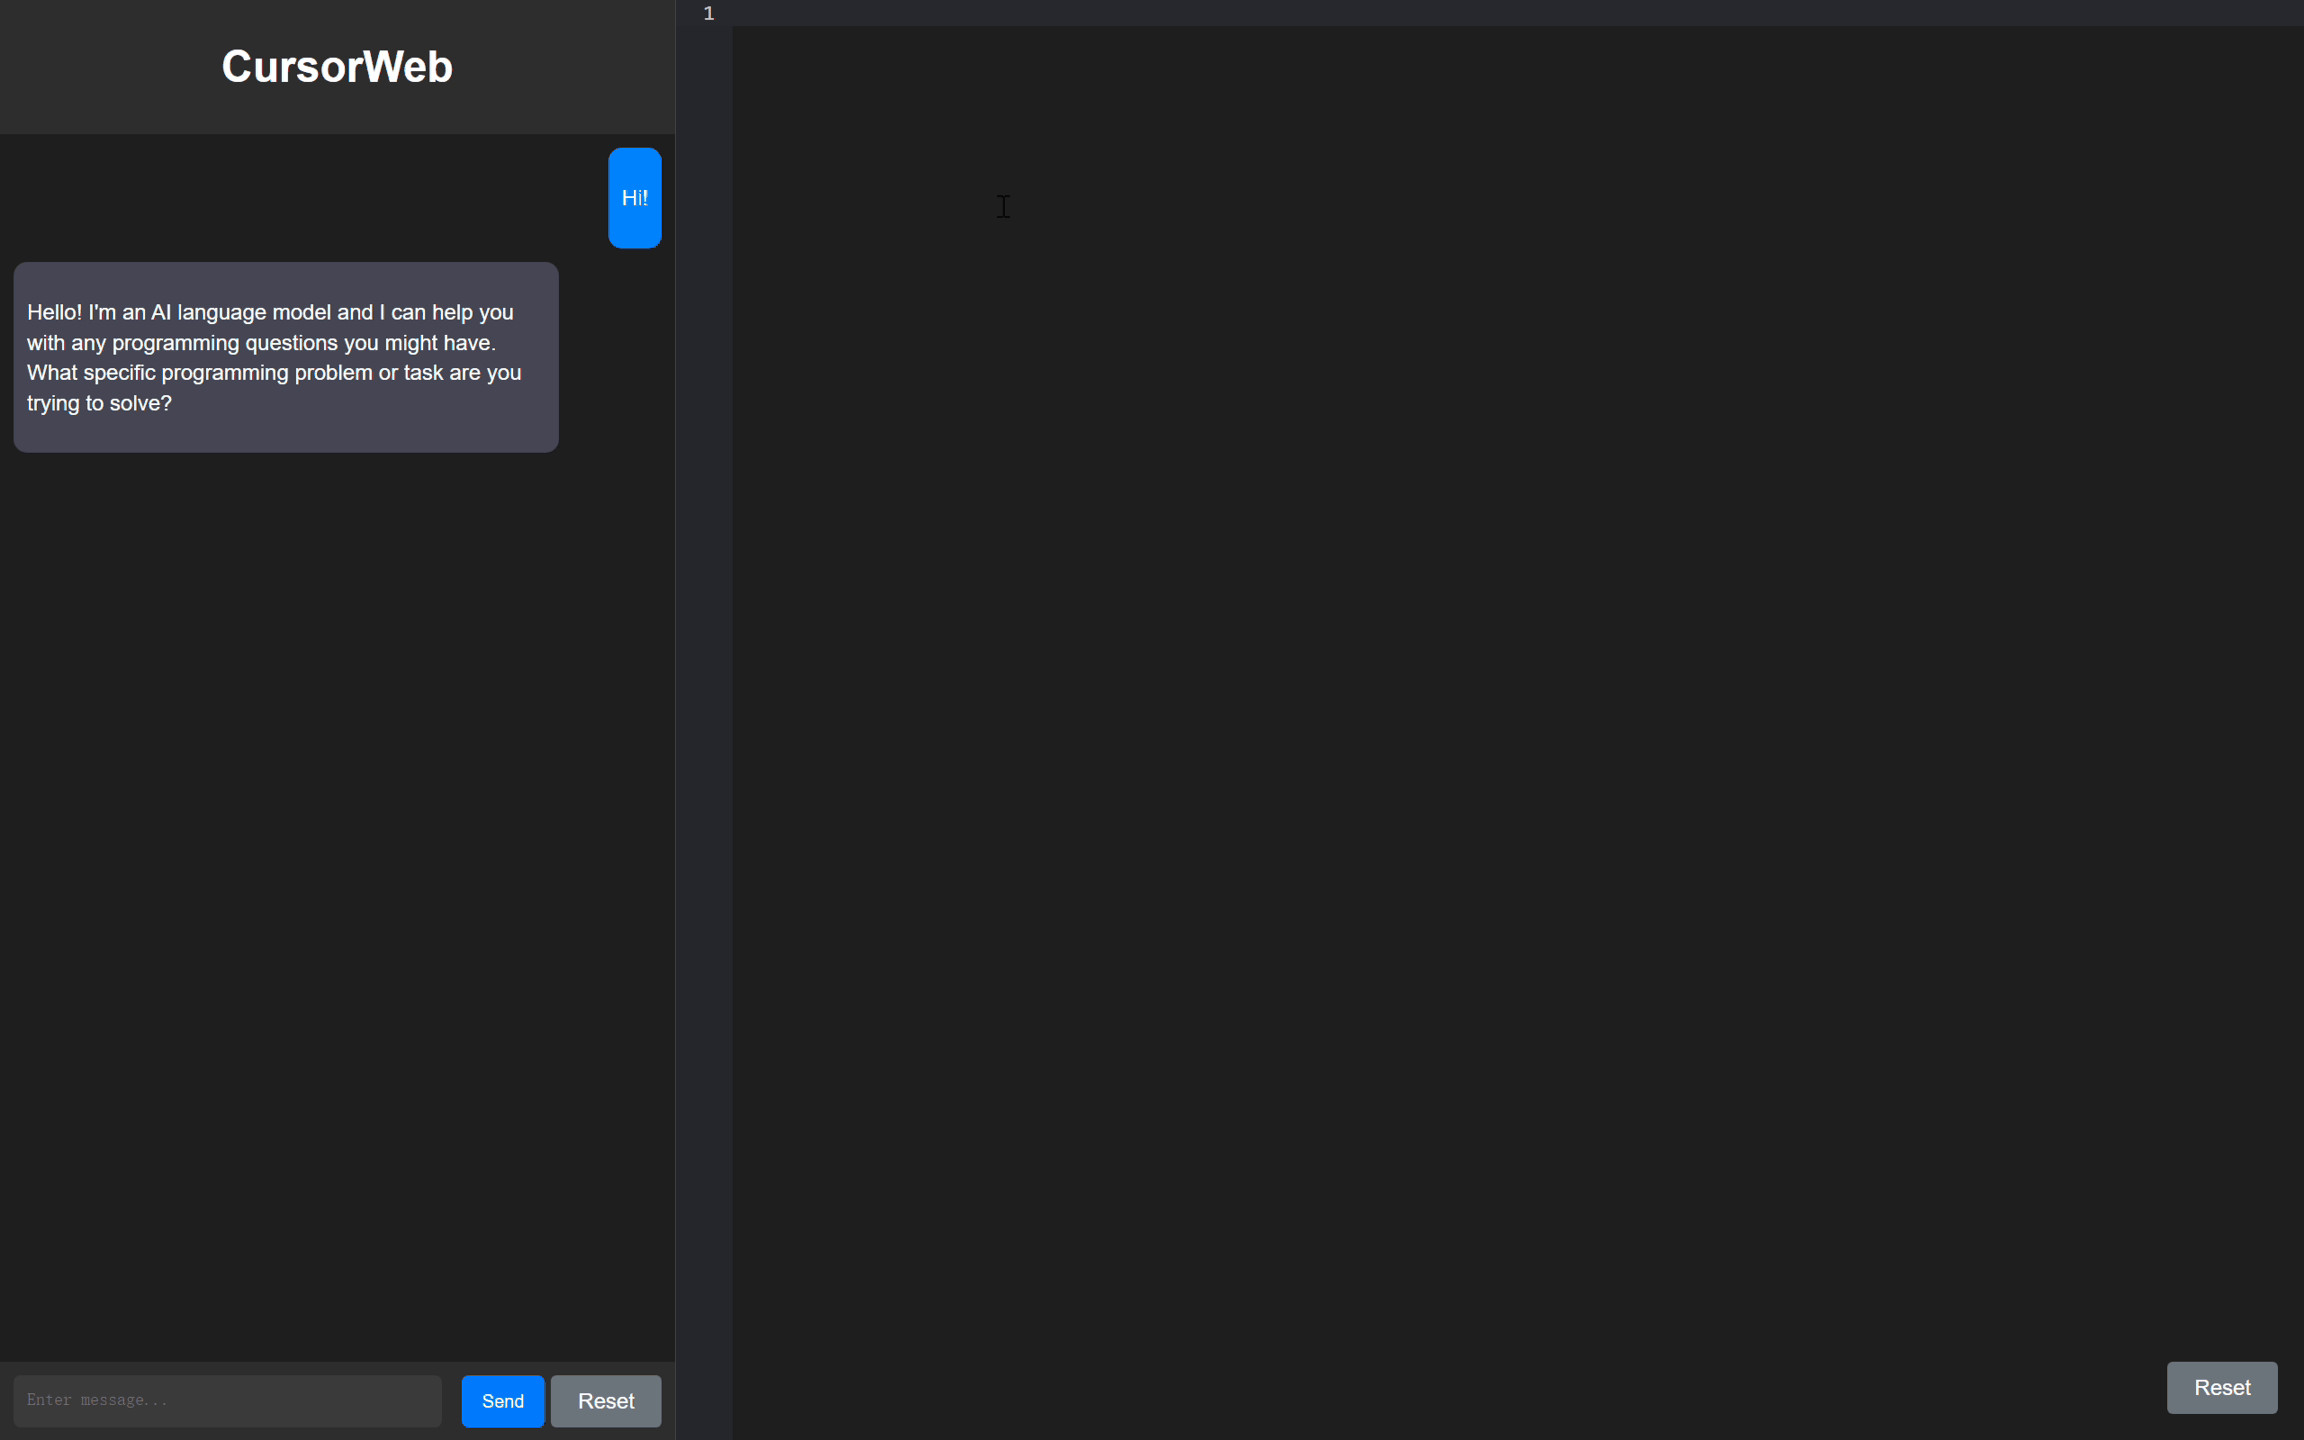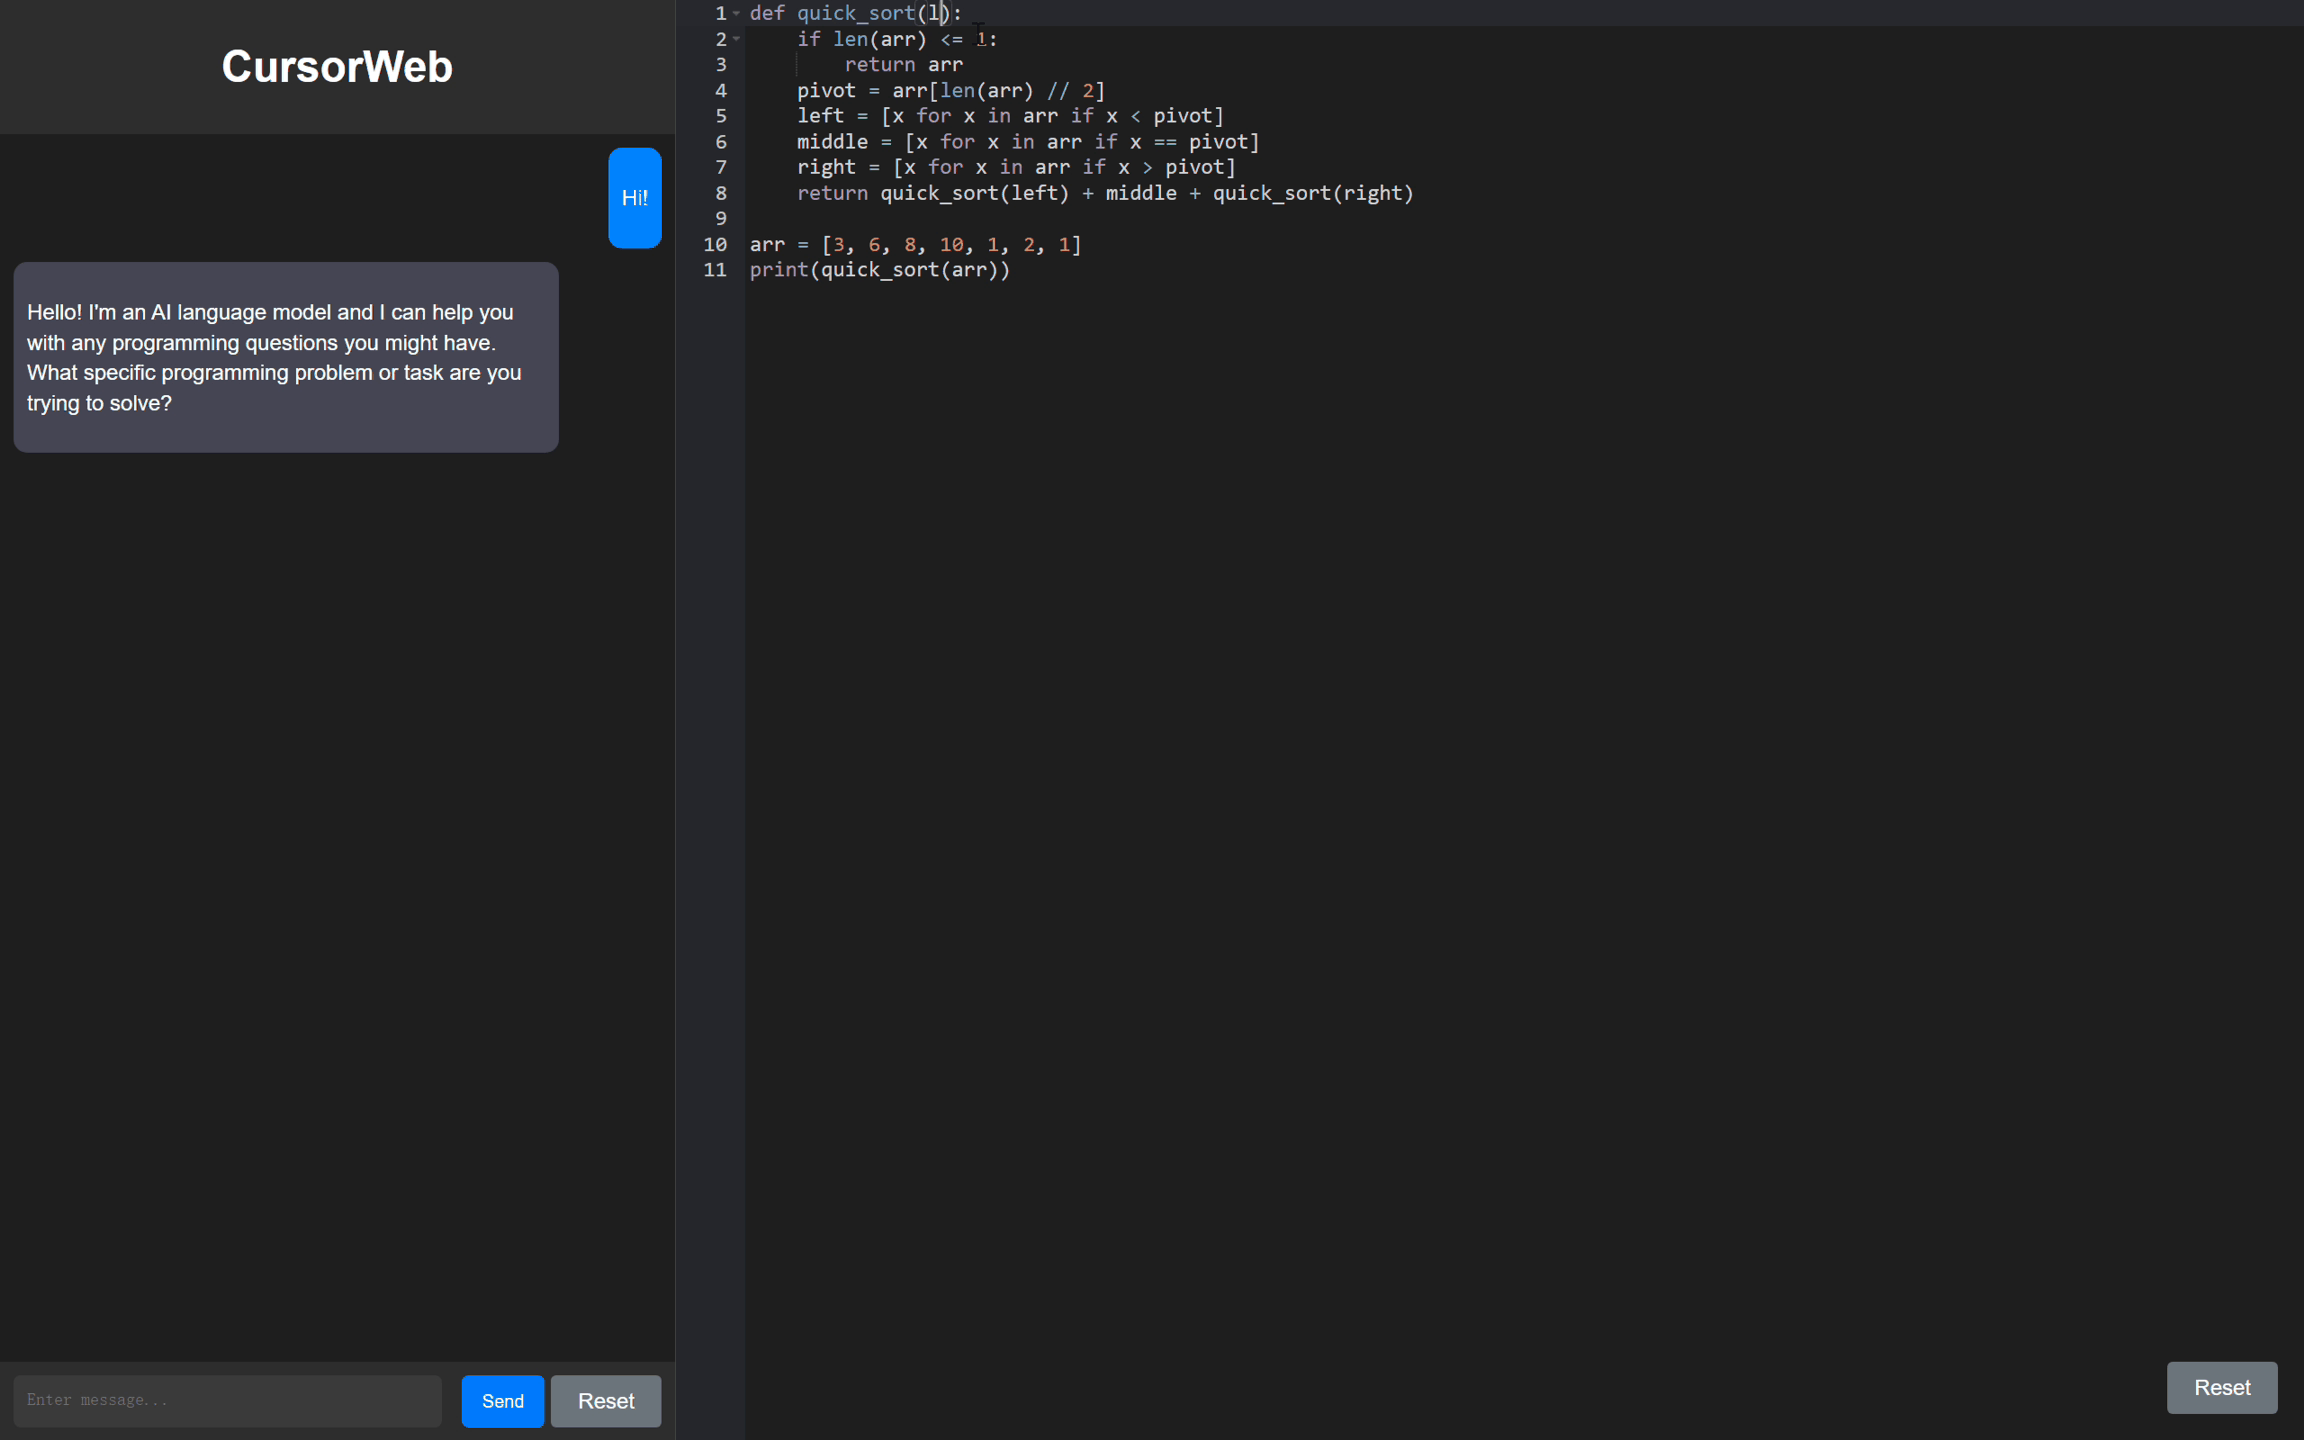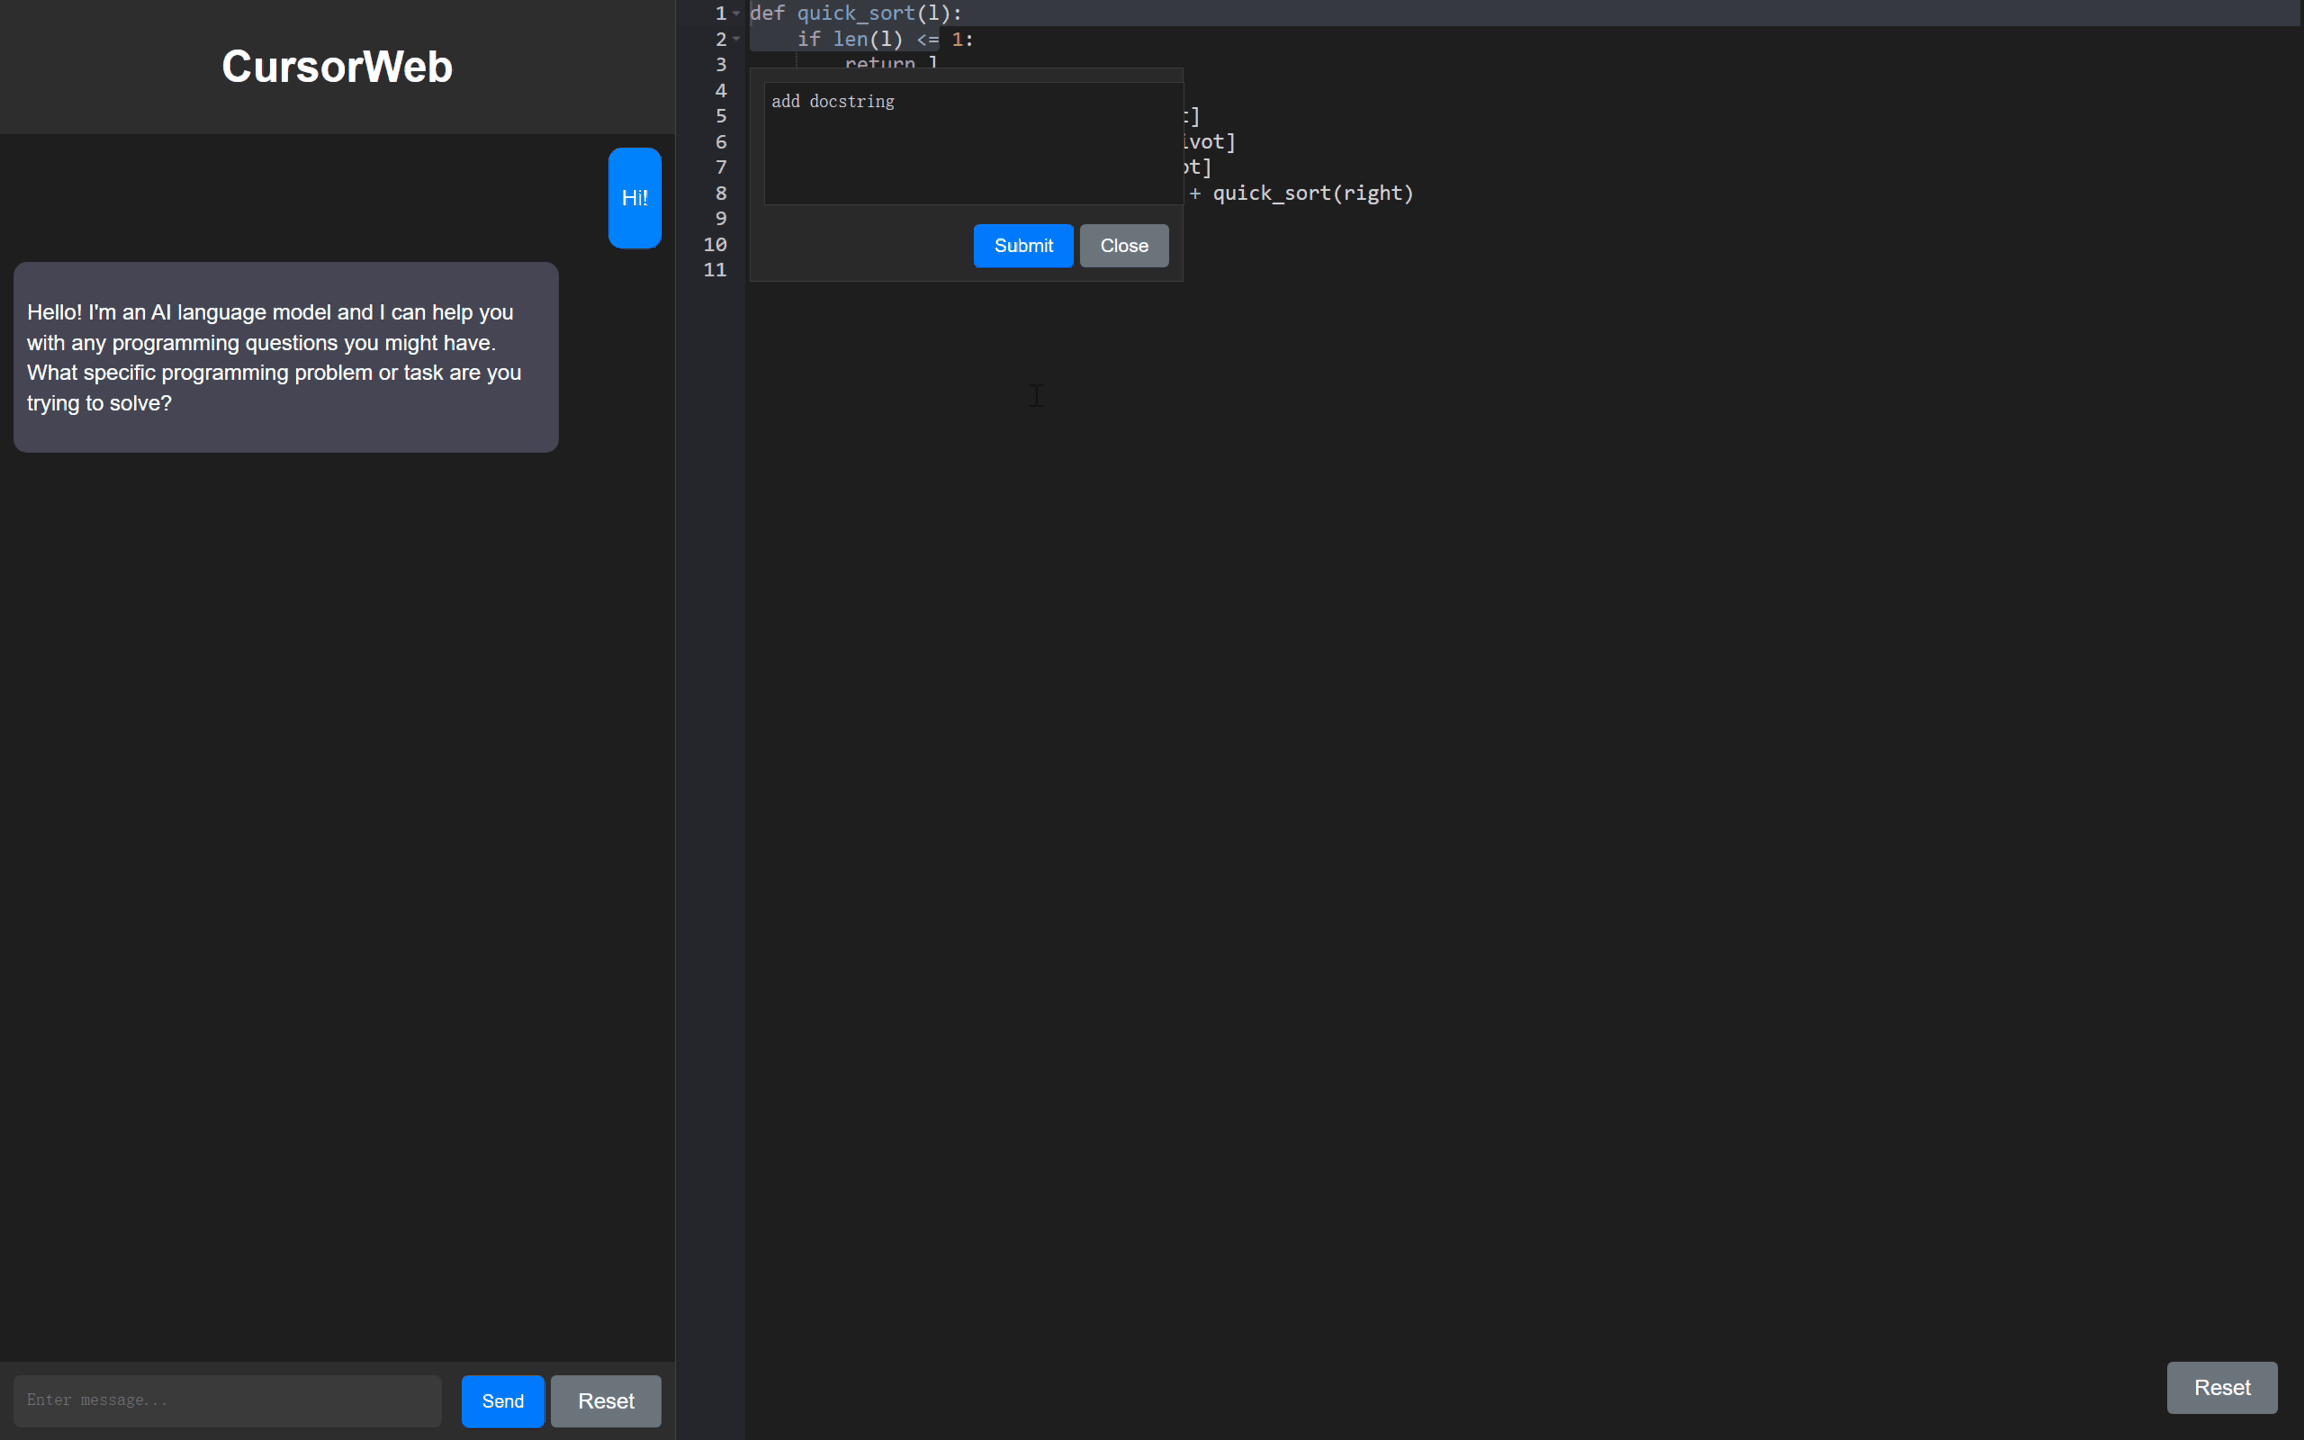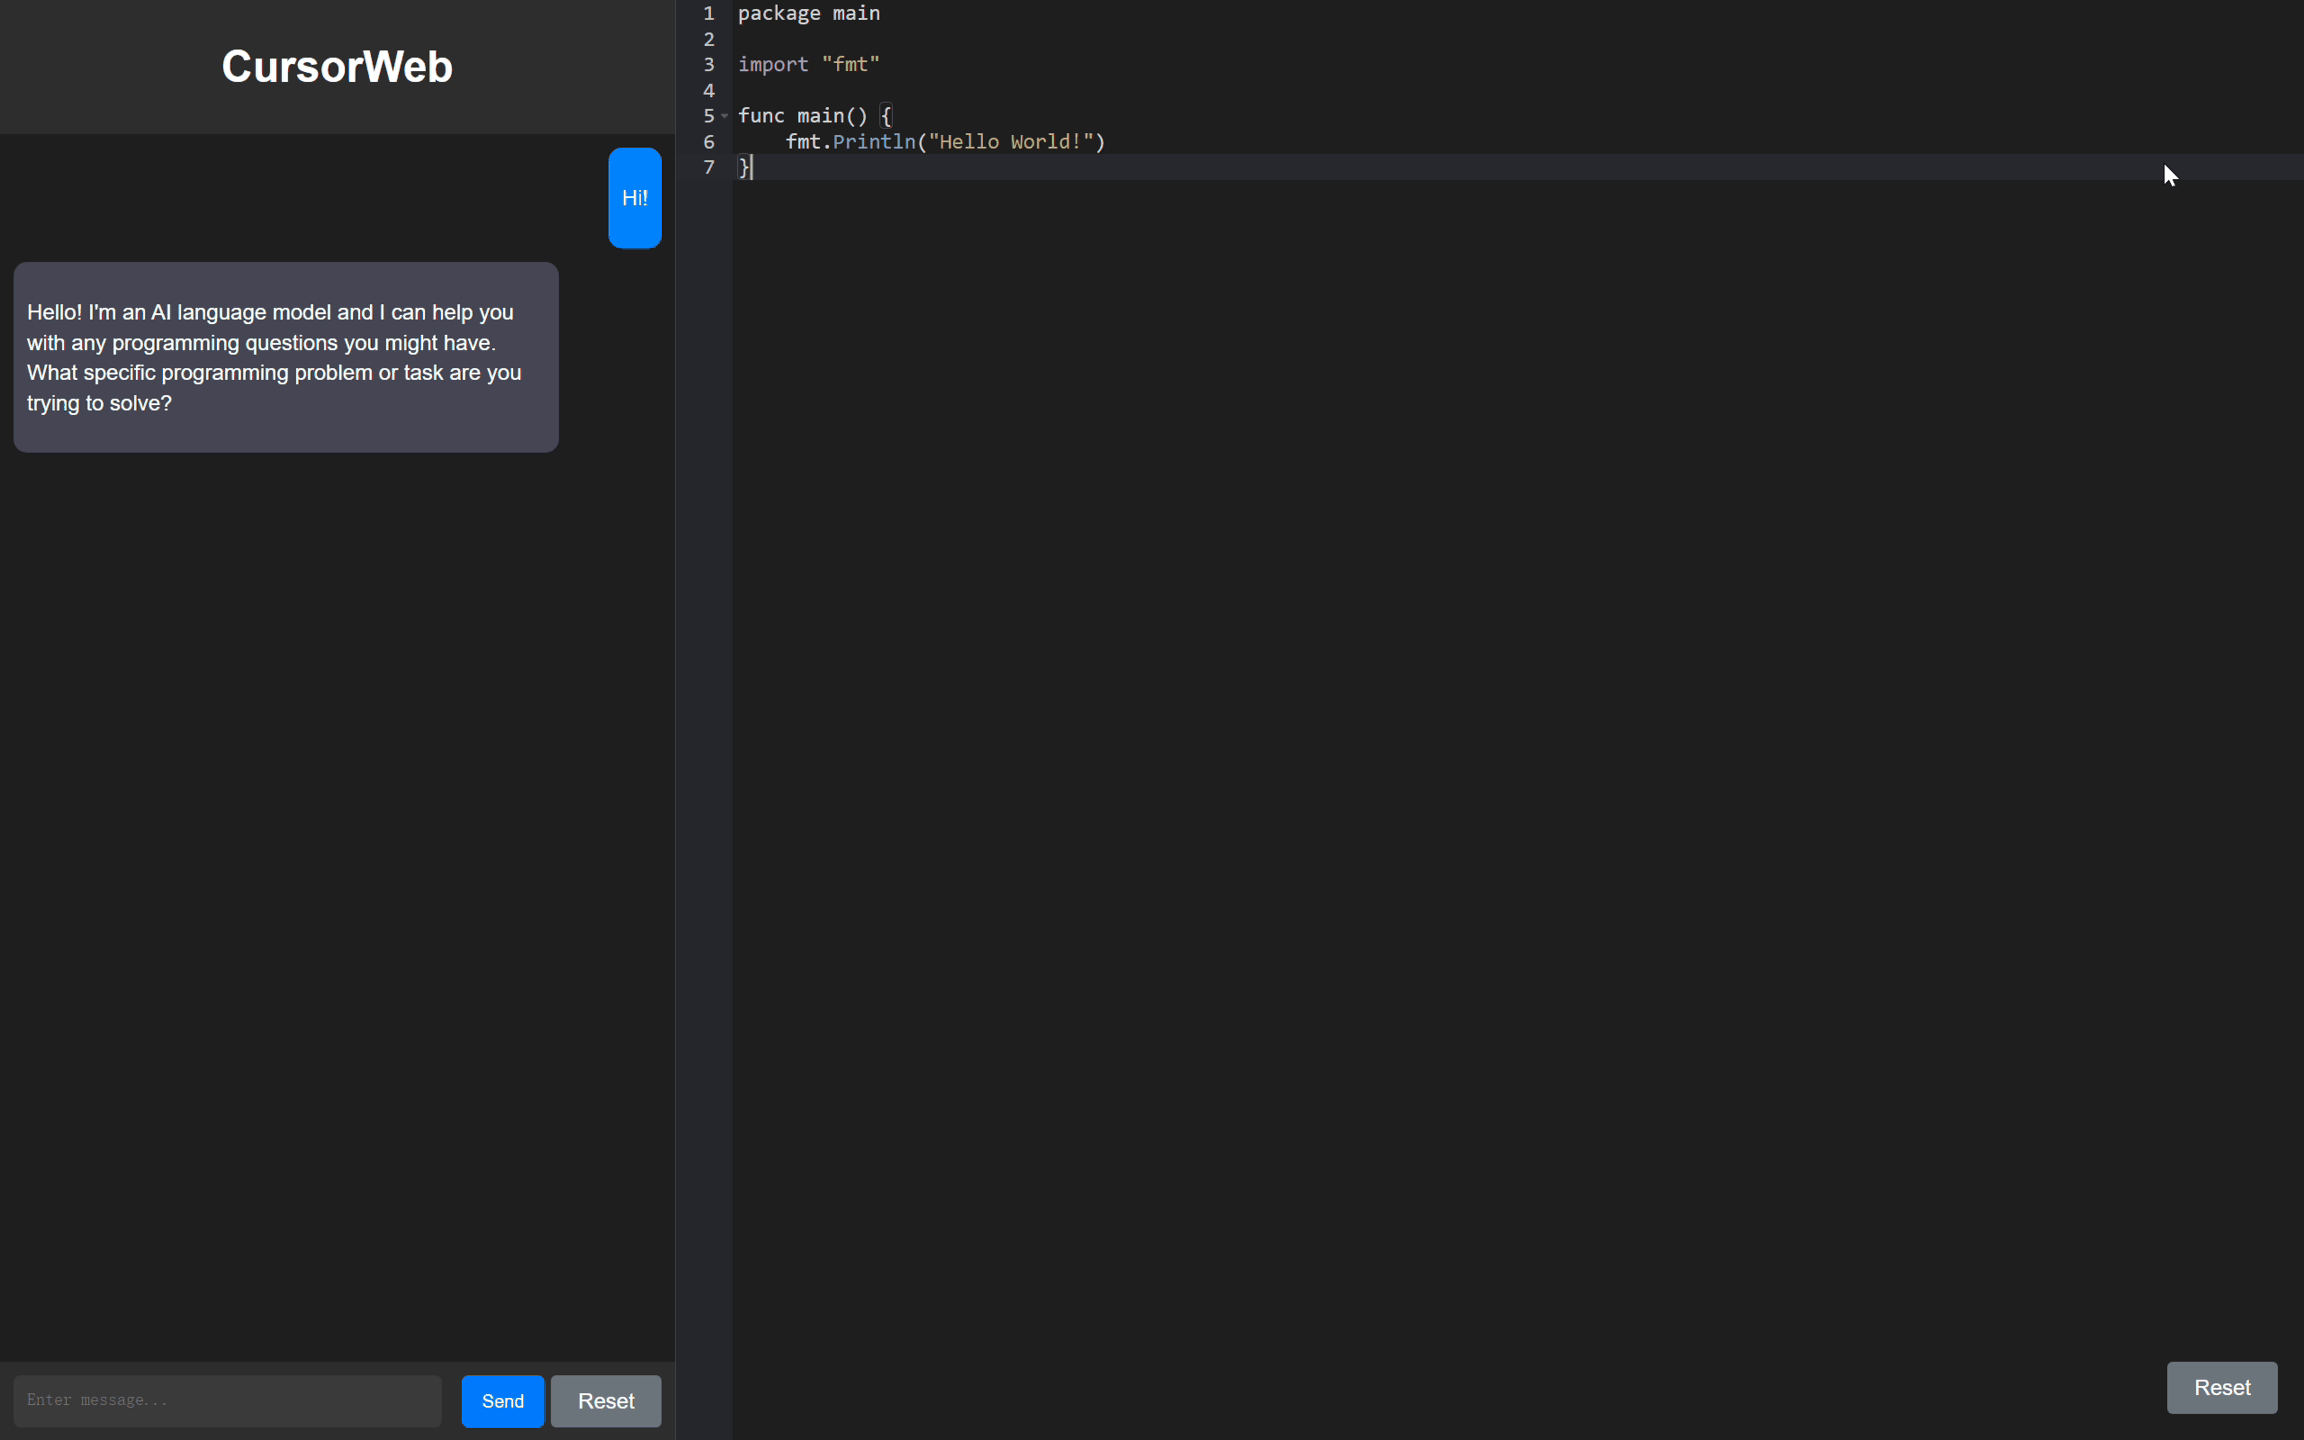
|
||||
|
||||
## Models
|
||||
|
||||
Our models have been open-sourced on Hugging Face. You can access our models here: [CursorCore-Series](https://huggingface.co/collections/TechxGenus/cursorcore-series-6706618c38598468866b60e2"). We also provide pre-quantized weights for GPTQ and AWQ here: [CursorCore-Quantization](https://huggingface.co/collections/TechxGenus/cursorcore-quantization-67066431f29f252494ee8cf3)
|
||||
|
||||
## Usage
|
||||
|
||||
Here are some examples of how to use our model:
|
||||
|
||||
### 1) Normal chat
|
||||
|
||||
Script:
|
||||
|
||||
````python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("TechxGenus/CursorCore-Yi-9B")
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
"TechxGenus/CursorCore-Yi-9B",
|
||||
torch_dtype=torch.bfloat16,
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "Hi!"},
|
||||
]
|
||||
prompt = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True
|
||||
)
|
||||
|
||||
inputs = tokenizer.encode(prompt, return_tensors="pt")
|
||||
outputs = model.generate(input_ids=inputs.to(model.device), max_new_tokens=512)
|
||||
print(tokenizer.decode(outputs[0]))
|
||||
````
|
||||
|
||||
Output:
|
||||
|
||||
````txt
|
||||
<|im_start|>system
|
||||
You are a helpful programming assistant.<|im_end|>
|
||||
<|im_start|>user
|
||||
Hi!<|im_end|>
|
||||
<|im_start|>assistant
|
||||
Hello! I'm an AI language model and I can help you with any programming questions you might have. What specific problem or task are you trying to solve?<|im_end|>
|
||||
````
|
||||
|
||||
### 2) Assistant-Conversation
|
||||
|
||||
In our work, we introduce a new framework of AI-assisted programming task. It is designed for aligning anything during programming process, used for the implementation of features like Tab and Inline Chat.
|
||||
|
||||
Script 1:
|
||||
|
||||
````python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
from eval.utils import prepare_input_for_wf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("TechxGenus/CursorCore-Yi-9B")
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
"TechxGenus/CursorCore-Yi-9B",
|
||||
torch_dtype=torch.bfloat16,
|
||||
device_map="auto"
|
||||
)
|
||||
sample = {
|
||||
"history": [
|
||||
{
|
||||
"type": "code",
|
||||
"lang": "python",
|
||||
"code": """def quick_sort(arr):\n if len(arr) <= 1:\n return arr\n pivot = arr[len(arr) // 2]\n left = [x for x in arr if x < pivot]\n middle = [x for x in arr if x == pivot]\n right = [x for x in arr if x > pivot]\n return quick_sort(left) + middle + quick_sort(right)"""
|
||||
}
|
||||
],
|
||||
"current": {
|
||||
"type": "code",
|
||||
"lang": "python",
|
||||
"code": """def quick_sort(array):\n if len(arr) <= 1:\n return arr\n pivot = arr[len(arr) // 2]\n left = [x for x in arr if x < pivot]\n middle = [x for x in arr if x == pivot]\n right = [x for x in arr if x > pivot]\n return quick_sort(left) + middle + quick_sort(right)"""
|
||||
},
|
||||
"user": ""
|
||||
}
|
||||
|
||||
prompt = tokenizer.apply_chat_template(
|
||||
prepare_input_for_wf(sample),
|
||||
tokenize=False,
|
||||
chat_template="assistant-conversation",
|
||||
add_generation_prompt=True
|
||||
)
|
||||
|
||||
inputs = tokenizer.encode(prompt, return_tensors="pt")
|
||||
outputs = model.generate(input_ids=inputs.to(model.device), max_new_tokens=512, do_sample=False)
|
||||
print(tokenizer.decode(outputs[0]))
|
||||
````
|
||||
|
||||
Output 1:
|
||||
|
||||
````txt
|
||||
<|im_start|>system
|
||||
You are a helpful programming assistant.<|im_end|>
|
||||
<|im_start|>history
|
||||
```python
|
||||
def quick_sort(arr):
|
||||
if len(arr) <= 1:
|
||||
return arr
|
||||
pivot = arr[len(arr) // 2]
|
||||
left = [x for x in arr if x < pivot]
|
||||
middle = [x for x in arr if x == pivot]
|
||||
right = [x for x in arr if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|im_end|>
|
||||
<|im_start|>current
|
||||
```python
|
||||
def quick_sort(array):
|
||||
if len(arr) <= 1:
|
||||
return arr
|
||||
pivot = arr[len(arr) // 2]
|
||||
left = [x for x in arr if x < pivot]
|
||||
middle = [x for x in arr if x == pivot]
|
||||
right = [x for x in arr if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|im_end|>
|
||||
<|im_start|>assistant
|
||||
<|next_start|>```python
|
||||
def quick_sort(array):
|
||||
if len(array) <= 1:
|
||||
return array
|
||||
pivot = array[len(array) // 2]
|
||||
left = [x for x in array if x < pivot]
|
||||
middle = [x for x in array if x == pivot]
|
||||
right = [x for x in array if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|next_end|>
|
||||
The user has provided a revised code change that corrects the parameter name from `arr` to `array` in the `quick_sort` function. This change ensures consistency in the function definition and avoids potential confusion or errors.
|
||||
|
||||
To implement this, we will:
|
||||
1. Update the parameter name in the function definition from `arr` to `array`.
|
||||
2. Ensure that all references to `arr` within the function are updated to `array`.
|
||||
|
||||
This will make the function definition and internal references consistent, improving code readability and maintainability.<|im_end|>
|
||||
````
|
||||
|
||||
Script 2:
|
||||
|
||||
````python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
from eval.utils import prepare_input_for_wf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("TechxGenus/CursorCore-Yi-9B")
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
"TechxGenus/CursorCore-Yi-9B",
|
||||
torch_dtype=torch.bfloat16,
|
||||
device_map="auto"
|
||||
)
|
||||
sample = {
|
||||
"history": [],
|
||||
"current": {
|
||||
"type": "code",
|
||||
"lang": "python",
|
||||
"code": """def quick_sort(array):\n if len(arr) <= 1:\n return arr\n pivot = arr[len(arr) // 2]\n left = [x for x in arr if x < pivot]\n middle = [x for x in arr if x == pivot]\n right = [x for x in arr if x > pivot]\n return quick_sort(left) + middle + quick_sort(right)"""
|
||||
},
|
||||
"user": "Add Docstring."
|
||||
}
|
||||
|
||||
prompt = tokenizer.apply_chat_template(
|
||||
prepare_input_for_wf(sample),
|
||||
tokenize=False,
|
||||
chat_template="assistant-conversation",
|
||||
add_generation_prompt=True
|
||||
)
|
||||
|
||||
inputs = tokenizer.encode(prompt, return_tensors="pt")
|
||||
outputs = model.generate(input_ids=inputs.to(model.device), max_new_tokens=512, do_sample=False)
|
||||
print(tokenizer.decode(outputs[0]))
|
||||
````
|
||||
|
||||
Output 2:
|
||||
|
||||
````txt
|
||||
<|im_start|>system
|
||||
You are a helpful programming assistant.<|im_end|>
|
||||
<|im_start|>current
|
||||
```python
|
||||
def quick_sort(array):
|
||||
if len(arr) <= 1:
|
||||
return arr
|
||||
pivot = arr[len(arr) // 2]
|
||||
left = [x for x in arr if x < pivot]
|
||||
middle = [x for x in arr if x == pivot]
|
||||
right = [x for x in arr if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|im_end|>
|
||||
<|im_start|>user
|
||||
Add Docstring.<|im_end|>
|
||||
<|im_start|>assistant
|
||||
<|next_start|>```python
|
||||
def quick_sort(array):
|
||||
"""
|
||||
This is an implementation of the quick sort algorithm.
|
||||
"""
|
||||
if len(arr) <= 1:
|
||||
return arr
|
||||
pivot = arr[len(arr) // 2]
|
||||
left = [x for x in arr if x < pivot]
|
||||
middle = [x for x in arr if x == pivot]
|
||||
right = [x for x in arr if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|next_end|><|im_end|>
|
||||
````
|
||||
|
||||
For models in Locate-and-Change (LC) and Search-and-Replace (SR) formats, the output examples are as follows:
|
||||
|
||||
Script for LC:
|
||||
|
||||
````python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
from eval.utils import prepare_input_for_lc
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("TechxGenus/CursorCore-Yi-1.5B-LC")
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
"TechxGenus/CursorCore-Yi-1.5B-LC",
|
||||
torch_dtype=torch.bfloat16,
|
||||
device_map="auto"
|
||||
)
|
||||
sample = {
|
||||
"history": [],
|
||||
"current": {
|
||||
"type": "code",
|
||||
"lang": "python",
|
||||
"code": """def quick_sort(array):\n if len(arr) <= 1:\n return arr\n pivot = arr[len(arr) // 2]\n left = [x for x in arr if x < pivot]\n middle = [x for x in arr if x == pivot]\n right = [x for x in arr if x > pivot]\n return quick_sort(left) + middle + quick_sort(right)"""
|
||||
},
|
||||
"user": "Add Docstring."
|
||||
}
|
||||
|
||||
prompt = tokenizer.apply_chat_template(
|
||||
prepare_input_for_lc(sample),
|
||||
tokenize=False,
|
||||
chat_template="assistant-conversation",
|
||||
add_generation_prompt=True
|
||||
)
|
||||
|
||||
inputs = tokenizer.encode(prompt, return_tensors="pt")
|
||||
outputs = model.generate(input_ids=inputs.to(model.device), max_new_tokens=512, do_sample=False)
|
||||
print(tokenizer.decode(outputs[0]))
|
||||
````
|
||||
|
||||
Output for LC:
|
||||
|
||||
````txt
|
||||
<|im_start|>system
|
||||
You are a helpful programming assistant.<|im_end|>
|
||||
<|im_start|>current
|
||||
```python
|
||||
1 def quick_sort(array):
|
||||
2 if len(arr) <= 1:
|
||||
3 return arr
|
||||
4 pivot = arr[len(arr) // 2]
|
||||
5 left = [x for x in arr if x < pivot]
|
||||
6 middle = [x for x in arr if x == pivot]
|
||||
7 right = [x for x in arr if x > pivot]
|
||||
8 return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|im_end|>
|
||||
<|im_start|>user
|
||||
Add Docstring.<|im_end|>
|
||||
<|im_start|>assistant
|
||||
<|next_start|>1,1
|
||||
```
|
||||
'''This function will sort an array using quick sort algorithm'''
|
||||
```<|next_end|>
|
||||
To enhance the readability and maintainability of the code, we should add a docstring to the `quick_sort` function. A docstring provides a clear description of what the function does, which is particularly useful for other developers who might use or modify this code in the future.
|
||||
|
||||
The docstring will be added immediately after the function definition, explaining that the function uses the quick sort algorithm to sort an array. This will make the code more self-explanatory and easier to understand.
|
||||
|
||||
Here's the plan:
|
||||
1. Add a docstring at the beginning of the `quick_sort` function.
|
||||
2. Ensure the docstring is clear and concise, describing the purpose of the function.
|
||||
|
||||
This modification will improve the code's documentation without altering its functionality.<|im_end|>
|
||||
````
|
||||
|
||||
Script for SR:
|
||||
|
||||
````python
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||
from eval.utils import prepare_input_for_sr
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("TechxGenus/CursorCore-Yi-1.5B-SR")
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
"TechxGenus/CursorCore-Yi-1.5B-SR",
|
||||
torch_dtype=torch.bfloat16,
|
||||
device_map="auto"
|
||||
)
|
||||
sample = {
|
||||
"history": [],
|
||||
"current": {
|
||||
"type": "code",
|
||||
"lang": "python",
|
||||
"code": """def quick_sort(array):\n if len(arr) <= 1:\n return arr\n pivot = arr[len(arr) // 2]\n left = [x for x in arr if x < pivot]\n middle = [x for x in arr if x == pivot]\n right = [x for x in arr if x > pivot]\n return quick_sort(left) + middle + quick_sort(right)"""
|
||||
},
|
||||
"user": "Add Docstring."
|
||||
}
|
||||
|
||||
prompt = tokenizer.apply_chat_template(
|
||||
prepare_input_for_sr(sample),
|
||||
tokenize=False,
|
||||
chat_template="assistant-conversation",
|
||||
add_generation_prompt=True
|
||||
)
|
||||
|
||||
inputs = tokenizer.encode(prompt, return_tensors="pt")
|
||||
outputs = model.generate(input_ids=inputs.to(model.device), max_new_tokens=512, do_sample=False)
|
||||
print(tokenizer.decode(outputs[0]))
|
||||
````
|
||||
|
||||
Output for SR:
|
||||
|
||||
````txt
|
||||
<|im_start|>system
|
||||
You are a helpful programming assistant.<|im_end|>
|
||||
<|im_start|>current
|
||||
```python
|
||||
def quick_sort(array):
|
||||
if len(arr) <= 1:
|
||||
return arr
|
||||
pivot = arr[len(arr) // 2]
|
||||
left = [x for x in arr if x < pivot]
|
||||
middle = [x for x in arr if x == pivot]
|
||||
right = [x for x in arr if x > pivot]
|
||||
return quick_sort(left) + middle + quick_sort(right)
|
||||
```<|im_end|>
|
||||
<|im_start|>user
|
||||
Add Docstring.<|im_end|>
|
||||
<|im_start|>assistant
|
||||
<|next_start|>```python
|
||||
def quick_sort(array):
|
||||
<|search_and_replace|>
|
||||
def quick_sort(array):
|
||||
"""
|
||||
This function implements quick sort algorithm
|
||||
"""
|
||||
```<|next_end|><|im_end|>
|
||||
````
|
||||
|
||||
### 3) Web Demo
|
||||
|
||||
We create a web demo for CursorCore. Please visit [CursorWeb](https://github.com/TechxGenus/CursorWeb) for more details.
|
||||
|
||||
## Future Work
|
||||
|
||||
CursorCore is still in a very early stage, and lots of work is needed to achieve a better user experience. For example:
|
||||
|
||||
- Repository-level editing support
|
||||
- Better and faster editing formats
|
||||
- Better user interface and presentation
|
||||
- ...
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@article{jiang2024cursorcore,
|
||||
title = {CursorCore: Assist Programming through Aligning Anything},
|
||||
author = {Hao Jiang and Qi Liu and Rui Li and Shengyu Ye and Shijin Wang},
|
||||
year = {2024},
|
||||
journal = {arXiv preprint arXiv: 2410.07002}
|
||||
}
|
||||
```
|
||||
|
||||
## Contribution
|
||||
|
||||
Contributions are welcome! If you find any bugs or have suggestions for improvements, please open an issue or submit a pull request.
|
||||
|
||||
|
||||
Reference in New Issue
Block a user