初始化项目,由ModelHub XC社区提供模型
Model: Mungert/OpenReasoning-Nemotron-7B-GGUF
Source: Original Platform
This commit is contained in:
 ModelHub XC
77
.gitattributes
vendored
Normal file
77
.gitattributes
vendored
Normal file
@@ -0,0 +1,77 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-f16.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-f16_q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-bf16_q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-f16_q6_k.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-bf16_q6_k.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-f16_q4_k.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-bf16_q4_k.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q2_k_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q3_k_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_k_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_k_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q6_k_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q2_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q2_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q3_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q3_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q6_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_0_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q4_1_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_0_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-q5_1_l.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq2_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq2_xxs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq2_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq2_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq3_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq3_xxs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq3_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq3_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq4_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-iq4_nl.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B.imatrix filter=lfs diff=lfs merge=lfs -text
|
||||
OpenReasoning-Nemotron-7B-bf16.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
3
OpenReasoning-Nemotron-7B-bf16.gguf
Normal file
3
OpenReasoning-Nemotron-7B-bf16.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8e6b01ac95ae63d886702d6225a576cde6b89c9a2fcce9e559eb1cdebcb5ef74
|
||||
size 15237851744
|
||||
3
OpenReasoning-Nemotron-7B-bf16_q8_0.gguf
Normal file
3
OpenReasoning-Nemotron-7B-bf16_q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:4eb5ca0354c5217248d33fe7ea553d348512c2d3fe843f137925751b431f7829
|
||||
size 11287997024
|
||||
3
OpenReasoning-Nemotron-7B-f16_q8_0.gguf
Normal file
3
OpenReasoning-Nemotron-7B-f16_q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:c29e23a62f9456590e9be7d564253c7506500ee238cc1c2054a8dfe47c50105e
|
||||
size 11287997024
|
||||
3
OpenReasoning-Nemotron-7B-iq2_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq2_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:77cda6a8add39f38fb95b36f520f77cd1a2155cc20b80ad2efa6f76abae96c20
|
||||
size 3059563424
|
||||
3
OpenReasoning-Nemotron-7B-iq2_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq2_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:2d60a58e14049f32dc9086f3f64511c3a693359f09cbbd5c2babcf1accd5b592
|
||||
size 2933406624
|
||||
3
OpenReasoning-Nemotron-7B-iq2_xs.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq2_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:4244416abfc72395a1a3efc6ca95cd164fa58da97d36dceb4019921f96da2f7e
|
||||
size 2849139616
|
||||
3
OpenReasoning-Nemotron-7B-iq2_xxs.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq2_xxs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:5b01ee840b0c07de463c3cda13332345fdbcb4fb0a5e93d2f5beac6fc3ff7637
|
||||
size 2652033952
|
||||
3
OpenReasoning-Nemotron-7B-iq3_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq3_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d0892acf551730fccafb28a717b489bfe0aabe080589c4fbb0ec25fccb127cd2
|
||||
size 3820891040
|
||||
3
OpenReasoning-Nemotron-7B-iq3_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq3_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:49b7055227ec5537b87d718c197aaf39b096a32e1802b997081cba86fa6de682
|
||||
size 3780950944
|
||||
3
OpenReasoning-Nemotron-7B-iq3_xs.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq3_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:62be88be83a620f4da98487d21765a3466dff8d5c0a8e484bd0552f0c3ac9ede
|
||||
size 3455753120
|
||||
3
OpenReasoning-Nemotron-7B-iq3_xxs.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq3_xxs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ed44d1a4f6b58de138614b53027b0fef96b6b5ccce71a109b20bbee018ea3a87
|
||||
size 3385506720
|
||||
3
OpenReasoning-Nemotron-7B-iq4_nl.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq4_nl.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:1caa7028b9316c4a5ad704aec0a8bc391f37a89d6af166bb51406b216f0ac690
|
||||
size 4437812128
|
||||
3
OpenReasoning-Nemotron-7B-iq4_xs.gguf
Normal file
3
OpenReasoning-Nemotron-7B-iq4_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:77db98766d78bba8c51190e89a9926ae74ae95e0fc9bab5fd64d2876c6c91640
|
||||
size 4218471328
|
||||
3
OpenReasoning-Nemotron-7B-q2_k_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q2_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:3ad46e170985950762eb93f8ca96f9f6b23dce339578c4142221e4bfa2d944d4
|
||||
size 3284179872
|
||||
3
OpenReasoning-Nemotron-7B-q2_k_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q2_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:da2e4e8ebd324837a3e23296561e8d7866038036a59c761e880cbaa63e222054
|
||||
size 3137766304
|
||||
3
OpenReasoning-Nemotron-7B-q3_k_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q3_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:29e588feb33485ede274fec394e88ea62401f5df5cebeba2038f27493ca16013
|
||||
size 4021279648
|
||||
3
OpenReasoning-Nemotron-7B-q3_k_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q3_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:4c199bb7bab58d10e8711090908fec411779210a125fa764a09d8b95a41860f3
|
||||
size 3858738080
|
||||
3
OpenReasoning-Nemotron-7B-q4_0.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q4_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:287c01e6503bb9fb0a1dc1f523fa05a1d6881f7b8115edf09b1b149dce7f1a84
|
||||
size 4290882464
|
||||
3
OpenReasoning-Nemotron-7B-q4_1.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q4_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:55c4705c1e8e99dbaa4783c9c993427ab7a488fba8e8299f638ccc6a660e8229
|
||||
size 4766837664
|
||||
3
OpenReasoning-Nemotron-7B-q4_k_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q4_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6d88f7a17f0e486c31a93f4e9b740b0ab27a719a27b5437a59e8ed66e5f46997
|
||||
size 4833213344
|
||||
3
OpenReasoning-Nemotron-7B-q4_k_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q4_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:f14a1e0670a0d1759ddca98d8870a8cf8f4317479e7b5fe71b2426056d6d7ea5
|
||||
size 4634057632
|
||||
3
OpenReasoning-Nemotron-7B-q5_0.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q5_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:08d7fa3e603ea87dd73ac475bcd4e3a1a7c0c1ecab13f310115f62f1a1282b63
|
||||
size 5242792864
|
||||
3
OpenReasoning-Nemotron-7B-q5_1.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q5_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:66f55913562dd3cff4cc4e3d754f7583451d60050d10dbc05e2786022f75edce
|
||||
size 5718748064
|
||||
3
OpenReasoning-Nemotron-7B-q5_k_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q5_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8bad893a8101a2fd1a95ac85c69b9081e56952e78d22a8181302a655410675d8
|
||||
size 5527448480
|
||||
3
OpenReasoning-Nemotron-7B-q5_k_s.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q5_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:032af5232956b6db6f1b72b988ee30a840ecb32b398cf0a53a0ee1c7824031b3
|
||||
size 5453360032
|
||||
3
OpenReasoning-Nemotron-7B-q6_k_m.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q6_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6d47af72dfb7acfac6bc0a5ad3a27f8406e7435bbf6616a1f253345a3a0f5045
|
||||
size 6254197664
|
||||
3
OpenReasoning-Nemotron-7B-q8_0.gguf
Normal file
3
OpenReasoning-Nemotron-7B-q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9ded8e79ff14b4366c6530a9d99e8526b48d23d6ecc653a444a69b4d6fef524a
|
||||
size 8098523744
|
||||
3
OpenReasoning-Nemotron-7B.imatrix
Normal file
3
OpenReasoning-Nemotron-7B.imatrix
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:39842d37ef7ac00b18a80a6a3880be02f3331f257e7afa47b88bf08c82c1dcf1
|
||||
size 4536678
|
||||
378
README.md
Normal file
378
README.md
Normal file
@@ -0,0 +1,378 @@
|
||||
---
|
||||
license: cc-by-4.0
|
||||
language:
|
||||
- en
|
||||
base_model:
|
||||
- Qwen/Qwen2.5-7B-Instruct
|
||||
pipeline_tag: text-generation
|
||||
library_name: transformers
|
||||
tags:
|
||||
- nvidia
|
||||
- code
|
||||
---
|
||||
|
||||
# <span style="color: #7FFF7F;">OpenReasoning-Nemotron-7B GGUF Models</span>
|
||||
|
||||
|
||||
## <span style="color: #7F7FFF;">Model Generation Details</span>
|
||||
|
||||
This model was generated using [llama.cpp](https://github.com/ggerganov/llama.cpp) at commit [`3f4fc97f`](https://github.com/ggerganov/llama.cpp/commit/3f4fc97f1d745f1d5d3c853949503136d419e6de).
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## <span style="color: #7FFF7F;">Quantization Beyond the IMatrix</span>
|
||||
|
||||
I've been experimenting with a new quantization approach that selectively elevates the precision of key layers beyond what the default IMatrix configuration provides.
|
||||
|
||||
In my testing, standard IMatrix quantization underperforms at lower bit depths, especially with Mixture of Experts (MoE) models. To address this, I'm using the `--tensor-type` option in `llama.cpp` to manually "bump" important layers to higher precision. You can see the implementation here:
|
||||
👉 [Layer bumping with llama.cpp](https://github.com/Mungert69/GGUFModelBuilder/blob/main/model-converter/tensor_list_builder.py)
|
||||
|
||||
While this does increase model file size, it significantly improves precision for a given quantization level.
|
||||
|
||||
### **I'd love your feedback—have you tried this? How does it perform for you?**
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
<a href="https://readyforquantum.com/huggingface_gguf_selection_guide.html" style="color: #7FFF7F;">
|
||||
Click here to get info on choosing the right GGUF model format
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
<!--Begin Original Model Card-->
|
||||
|
||||
# OpenReasoning-Nemotron-7B Overview
|
||||
|
||||
## Description: <br>
|
||||
OpenReasoning-Nemotron-7B is a large language model (LLM) which is a derivative of Qwen2.5-7B-Instruct (AKA the reference model). It is a reasoning model that is post-trained for reasoning about math, code and science solution generation. We evaluated this model with up to 64K output tokens. The OpenReasoning model is available in the following sizes: 1.5B, 7B and 14B and 32B. <br>
|
||||
|
||||
This model is ready for commercial/non-commercial research use. <br>
|
||||
|
||||
### License/Terms of Use: <br>
|
||||
GOVERNING TERMS: Use of the models listed above are governed by the [Creative Commons Attribution 4.0 International License (CC-BY-4.0)](https://creativecommons.org/licenses/by/4.0/legalcode.en). ADDITIONAL INFORMATION: [Apache 2.0 License](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct/blob/main/LICENSE)
|
||||
|
||||
## Scores on Reasoning Benchmarks
|
||||
|
||||
|
||||
|
||||
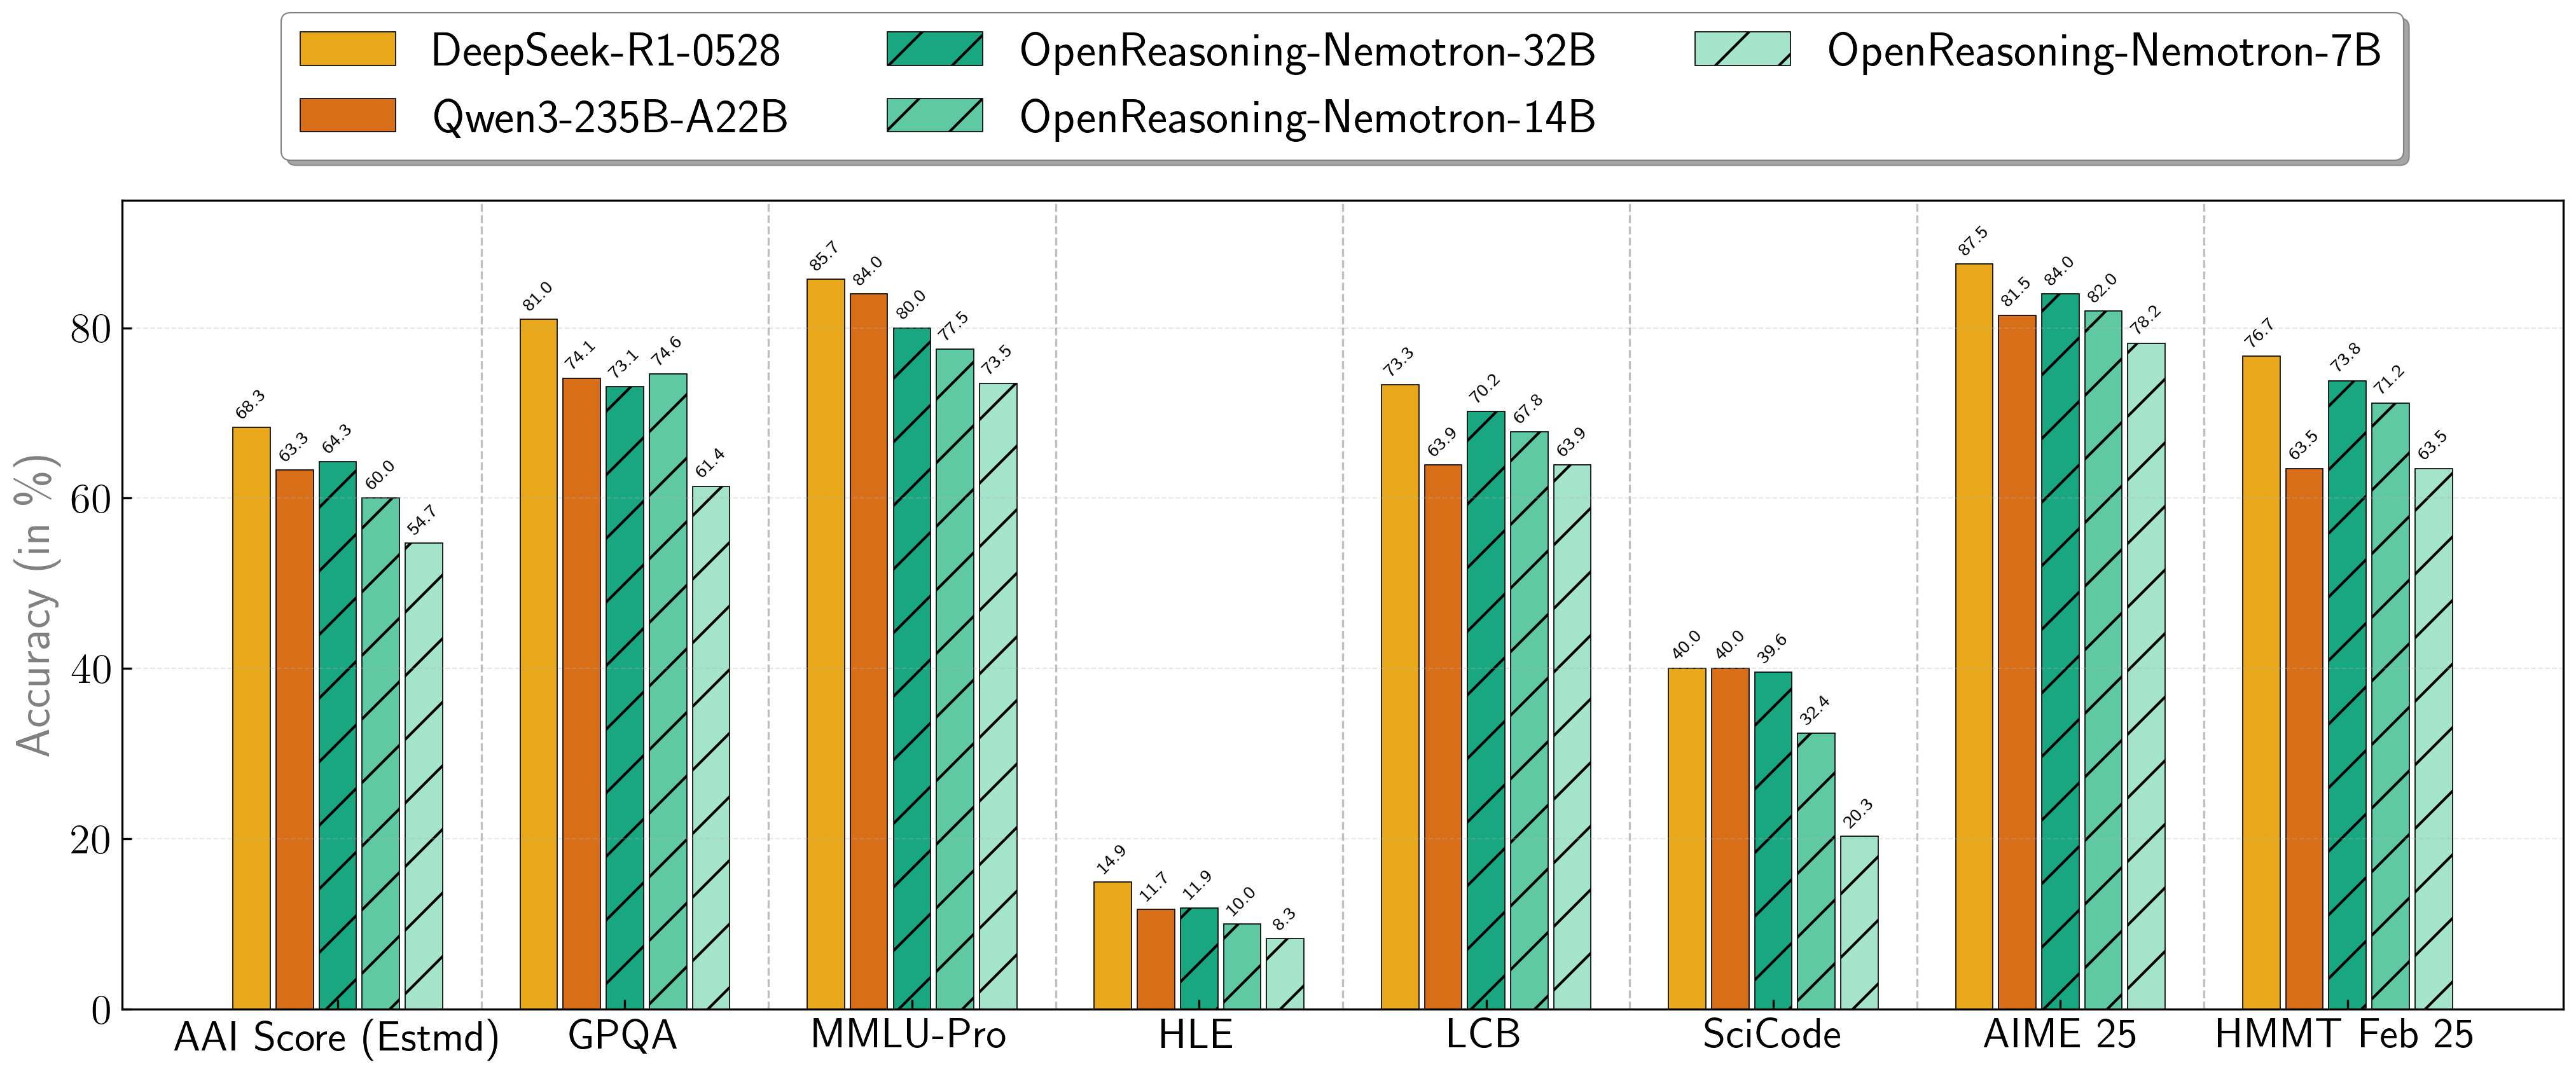
Our models demonstrate exceptional performance across a suite of challenging reasoning benchmarks. The 7B, 14B, and 32B models consistently set new state-of-the-art records for their size classes.
|
||||
|
||||
| **Model** | **AritificalAnalysisIndex*** | **GPQA** | **MMLU-PRO** | **HLE** | **LiveCodeBench*** | **SciCode** | **AIME24** | **AIME25** | **HMMT FEB 25** |
|
||||
| :--- | :--- | :--- | :--- | :--- | :--- | :--- | :--- | :--- | :--- |
|
||||
| **1.5B**| 31.0 | 31.6 | 47.5 | 5.5 | 28.6 | 2.2 | 55.5 | 45.6 | 31.5 |
|
||||
| **7B** | 54.7 | 61.1 | 71.9 | 8.3 | 63.3 | 16.2 | 84.7 | 78.2 | 63.5 |
|
||||
| **14B** | 60.9 | 71.6 | 77.5 | 10.1 | 67.8 | 23.5 | 87.8 | 82.0 | 71.2 |
|
||||
| **32B** | 64.3 | 73.1 | 80.0 | 11.9 | 70.2 | 28.5 | 89.2 | 84.0 | 73.8 |
|
||||
|
||||
\* This is our estimation of the Artificial Analysis Intelligence Index, not an official score.
|
||||
|
||||
\* LiveCodeBench version 6, date range 2408-2505.
|
||||
|
||||
## Combining the work of multiple agents
|
||||
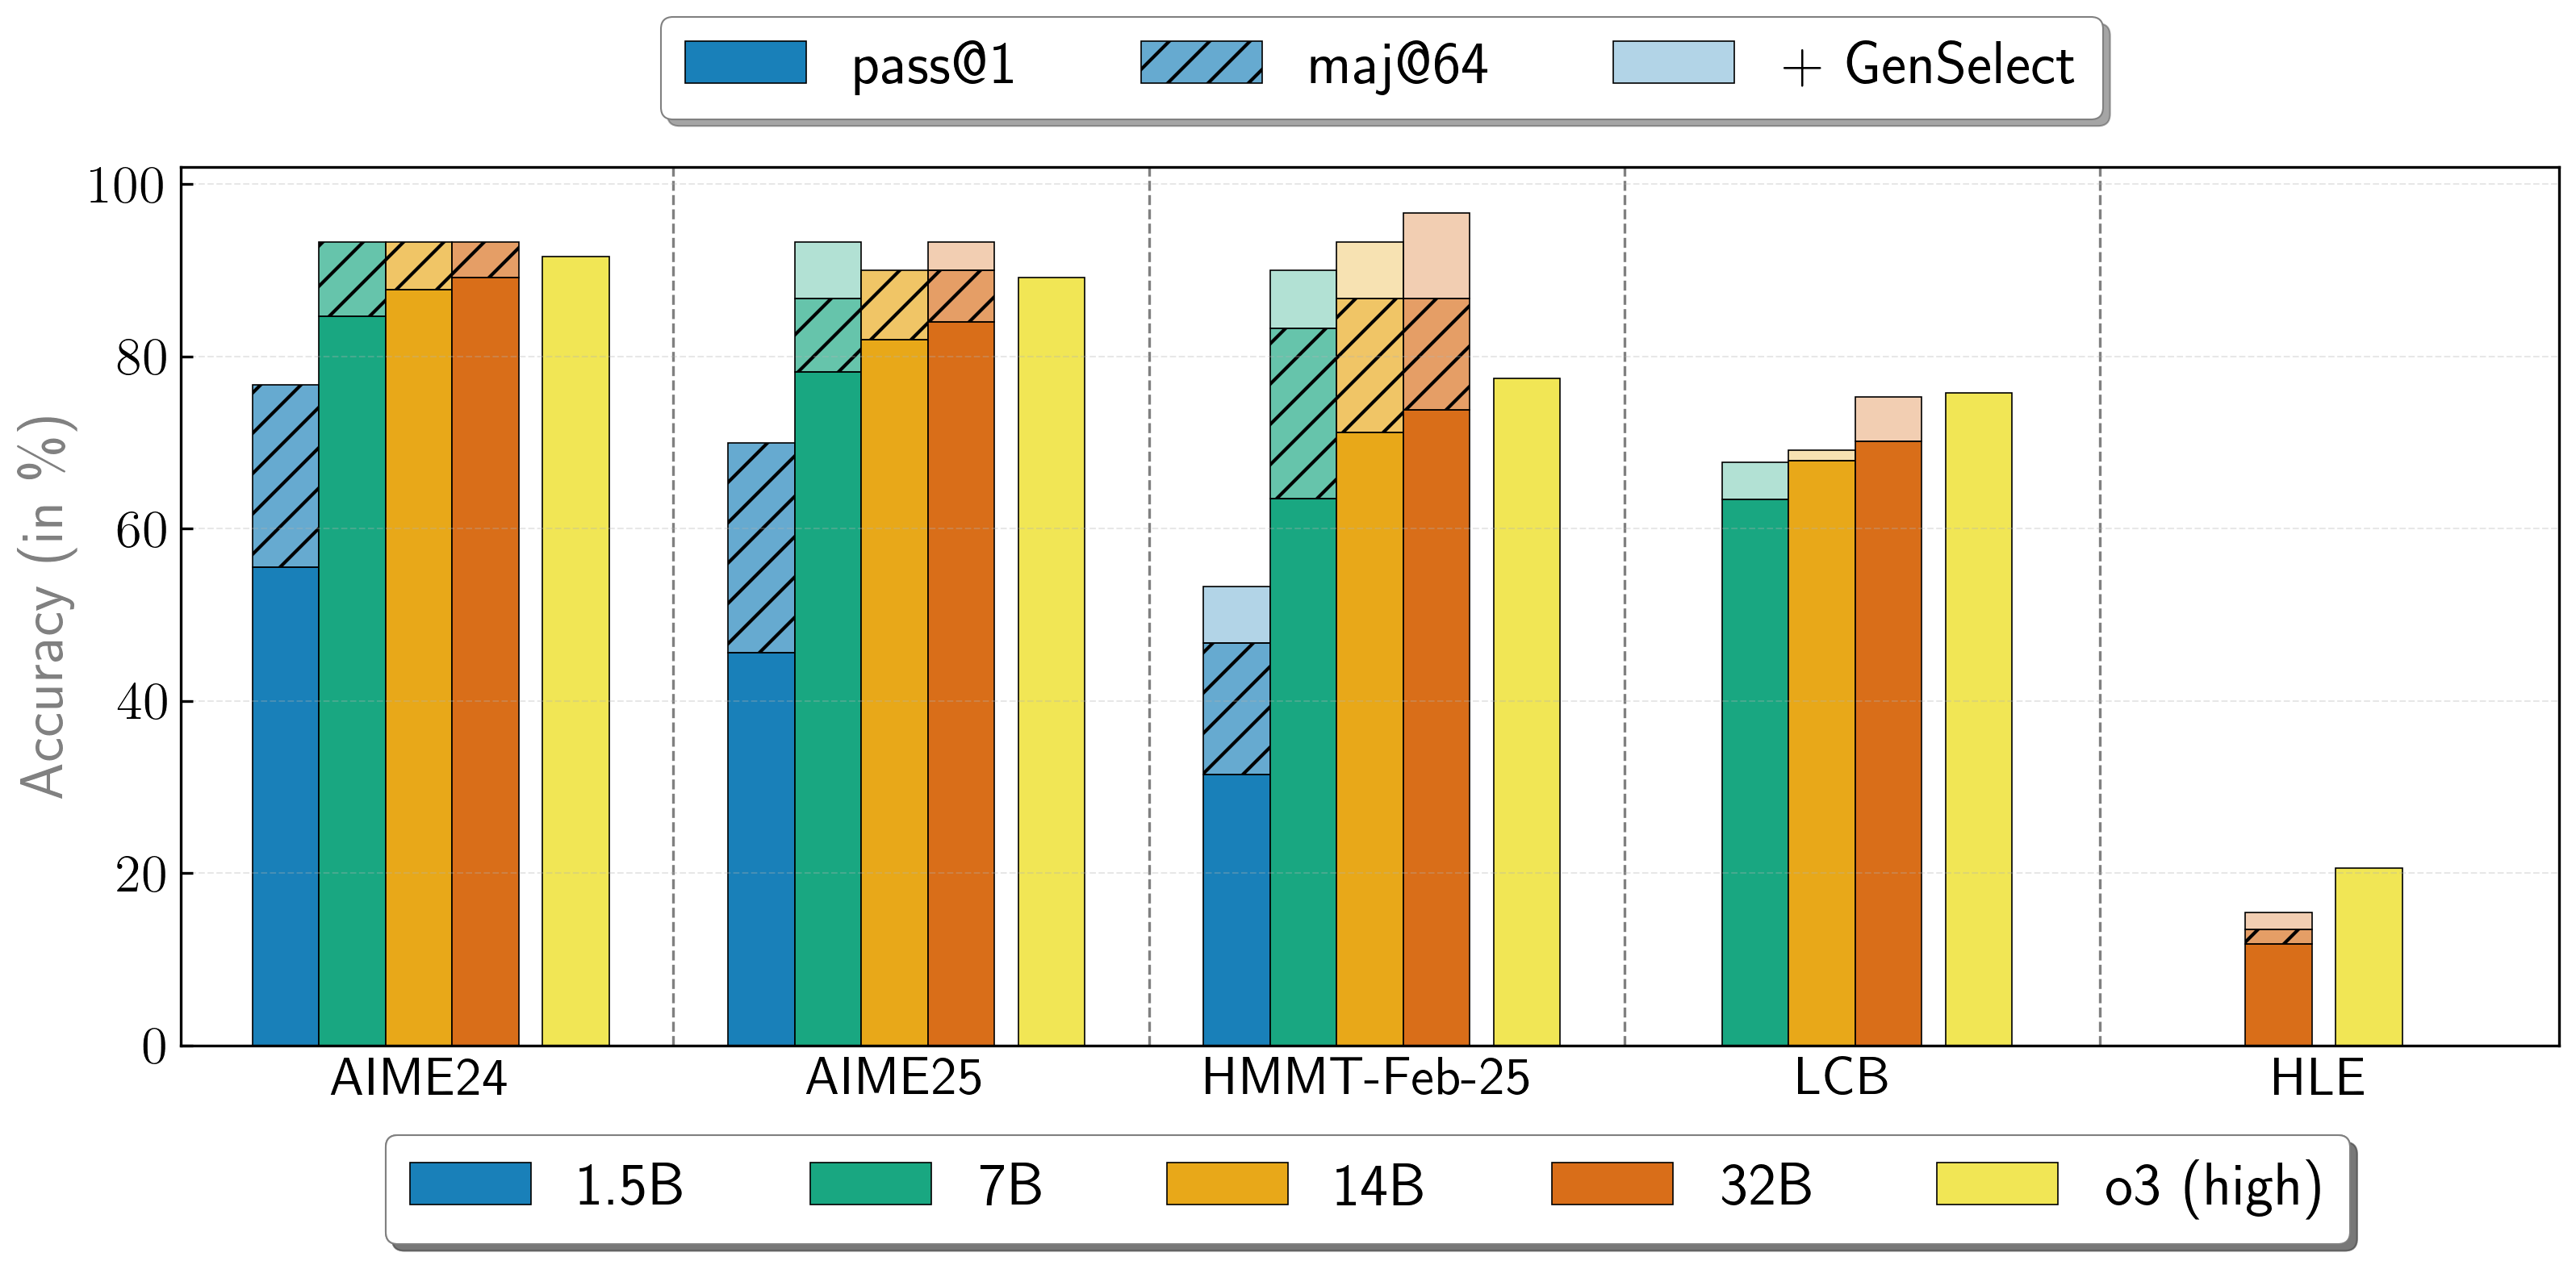
OpenReasoning-Nemotron models can be used in a "heavy" mode by starting multiple parallel generations and combining them together via [generative solution selection (GenSelect)](https://arxiv.org/abs/2504.16891). To add this "skill" we follow the original GenSelect training pipeline except we do not train on the selection summary but use the full reasoning trace of DeepSeek R1 0528 671B instead. We only train models to select the best solution for math problems but surprisingly find that this capability directly generalizes to code and science questions! With this "heavy" GenSelect inference mode, OpenReasoning-Nemotron-32B model surpasses O3 (High) on math and coding benchmarks.
|
||||
|
||||
|
||||
|
||||
| **Model** | **Pass@1 (Avg@64)** | **Majority@64** | **GenSelect** |
|
||||
| :--- | :--- | :--- | :--- |
|
||||
| **1.5B** | | | |
|
||||
| **AIME24** | 55.5 | 76.7 | 76.7 |
|
||||
| **AIME25** | 45.6 | 70.0 | 70.0 |
|
||||
| **HMMT Feb 25** | 31.5 | 46.7 | 53.3 |
|
||||
| **7B** | | | |
|
||||
| **AIME24** | 84.7 | 93.3 | 93.3 |
|
||||
| **AIME25** | 78.2 | 86.7 | 93.3 |
|
||||
| **HMMT Feb 25** | 63.5 | 83.3 | 90.0 |
|
||||
| **LCB v6 2408-2505** | 63.4 | n/a | 67.7 |
|
||||
| **14B** | | | |
|
||||
| **AIME24** | 87.8 | 93.3 | 93.3 |
|
||||
| **AIME25** | 82.0 | 90.0 | 90.0 |
|
||||
| **HMMT Feb 25** | 71.2 | 86.7 | 93.3 |
|
||||
| **LCB v6 2408-2505** | 67.9 | n/a | 69.1 |
|
||||
| **32B** | | | |
|
||||
| **AIME24** | 89.2 | 93.3 | 93.3 |
|
||||
| **AIME25** | 84.0 | 90.0 | 93.3 |
|
||||
| **HMMT Feb 25** | 73.8 | 86.7 | 96.7 |
|
||||
| **LCB v6 2408-2505** | 70.2 | n/a | 75.3 |
|
||||
| **HLE** | 11.8 | 13.4 | 15.5 |
|
||||
|
||||
|
||||
## How to use the models?
|
||||
|
||||
To run inference on coding problems:
|
||||
|
||||
````python
|
||||
import transformers
|
||||
import torch
|
||||
model_id = "nvidia/OpenReasoning-Nemotron-7B"
|
||||
pipeline = transformers.pipeline(
|
||||
"text-generation",
|
||||
model=model_id,
|
||||
model_kwargs={"torch_dtype": torch.bfloat16},
|
||||
device_map="auto",
|
||||
)
|
||||
# Code generation prompt
|
||||
prompt = """You are a helpful and harmless assistant. You should think step-by-step before responding to the instruction below.
|
||||
Please use python programming language only.
|
||||
You must use ```python for just the final solution code block with the following format:
|
||||
```python
|
||||
# Your code here
|
||||
```
|
||||
{user}
|
||||
"""
|
||||
|
||||
# Math generation prompt
|
||||
# prompt = """Solve the following math problem. Make sure to put the answer (and only answer) inside \\boxed{}.
|
||||
#
|
||||
# {user}
|
||||
# """
|
||||
|
||||
# Science generation prompt
|
||||
# You can refer to prompts here -
|
||||
# https://github.com/NVIDIA/NeMo-Skills/blob/main/nemo_skills/prompt/config/generic/hle.yaml (HLE)
|
||||
# https://github.com/NVIDIA/NeMo-Skills/blob/main/nemo_skills/prompt/config/eval/aai/mcq-4choices-boxed.yaml (for GPQA)
|
||||
# https://github.com/NVIDIA/NeMo-Skills/blob/main/nemo_skills/prompt/config/eval/aai/mcq-10choices-boxed.yaml (MMLU-Pro)
|
||||
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": prompt.format(user="Write a program to calculate the sum of the first $N$ fibonacci numbers")},
|
||||
]
|
||||
outputs = pipeline(
|
||||
messages,
|
||||
max_new_tokens=64000,
|
||||
)
|
||||
print(outputs[0]["generated_text"][-1]['content'])
|
||||
````
|
||||
|
||||
We have added [a simple transformer-based script](https://huggingface.co/nvidia/OpenReasoning-Nemotron-7B/blob/main/genselect_hf.py) in this repo to illustrate GenSelect.
|
||||
To learn how to use the models in GenSelect mode with NeMo-Skills, see our [documentation](https://nvidia.github.io/NeMo-Skills/releases/openreasoning/evaluation/).
|
||||
|
||||
To use the model with GenSelect inference, we recommend following our
|
||||
[reference implementation in NeMo-Skills](https://github.com/NVIDIA/NeMo-Skills/blob/main/nemo_skills/pipeline/genselect.py). Alternatively, you can manually extract the summary from all solutions and use this
|
||||
[prompt](https://github.com/NVIDIA/NeMo-Skills/blob/main/nemo_skills/prompt/config/openmath/genselect.yaml) for the math problems. We will add the prompt we used for the coding problems and a reference implementation soon!
|
||||
|
||||
You can learn more about GenSelect in these papers:
|
||||
* [AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning dataset](https://arxiv.org/abs/2504.16891)
|
||||
* [GenSelect: A Generative Approach to Best-of-N](https://openreview.net/forum?id=8LhnmNmUDb)
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
If you find the data useful, please cite:
|
||||
```
|
||||
@article{ahmad2025opencodereasoning,
|
||||
title={{OpenCodeReasoning: Advancing Data Distillation for Competitive Coding}},
|
||||
author={Wasi Uddin Ahmad, Sean Narenthiran, Somshubra Majumdar, Aleksander Ficek, Siddhartha Jain, Jocelyn Huang, Vahid Noroozi, Boris Ginsburg},
|
||||
year={2025},
|
||||
eprint={2504.01943},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2504.01943},
|
||||
}
|
||||
```
|
||||
|
||||
```
|
||||
@misc{ahmad2025opencodereasoningiisimpletesttime,
|
||||
title={{OpenCodeReasoning-II: A Simple Test Time Scaling Approach via Self-Critique}},
|
||||
author={Wasi Uddin Ahmad and Somshubra Majumdar and Aleksander Ficek and Sean Narenthiran and Mehrzad Samadi and Jocelyn Huang and Siddhartha Jain and Vahid Noroozi and Boris Ginsburg},
|
||||
year={2025},
|
||||
eprint={2507.09075},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2507.09075},
|
||||
}
|
||||
```
|
||||
|
||||
```
|
||||
@misc{moshkov2025aimo2winningsolutionbuilding,
|
||||
title={{AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning dataset}},
|
||||
author={Ivan Moshkov and Darragh Hanley and Ivan Sorokin and Shubham Toshniwal and Christof Henkel and Benedikt Schifferer and Wei Du and Igor Gitman},
|
||||
year={2025},
|
||||
eprint={2504.16891},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.AI},
|
||||
url={https://arxiv.org/abs/2504.16891},
|
||||
}
|
||||
```
|
||||
|
||||
```
|
||||
@inproceedings{toshniwal2025genselect,
|
||||
title={{GenSelect: A Generative Approach to Best-of-N}},
|
||||
author={Shubham Toshniwal and Ivan Sorokin and Aleksander Ficek and Ivan Moshkov and Igor Gitman},
|
||||
booktitle={2nd AI for Math Workshop @ ICML 2025},
|
||||
year={2025},
|
||||
url={https://openreview.net/forum?id=8LhnmNmUDb}
|
||||
}
|
||||
```
|
||||
|
||||
## Additional Information:
|
||||
|
||||
### Deployment Geography:
|
||||
Global<br>
|
||||
|
||||
### Use Case: <br>
|
||||
This model is intended for developers and researchers who work on competitive math, code and science problems. It has been trained via only supervised fine-tuning to achieve strong scores on benchmarks. <br>
|
||||
|
||||
### Release Date: <br>
|
||||
Huggingface [07/16/2025] via https://huggingface.co/nvidia/OpenReasoning-Nemotron-7B/ <br>
|
||||
|
||||
## Reference(s):
|
||||
* [2504.01943] OpenCodeReasoning: Advancing Data Distillation for Competitive Coding
|
||||
* [2504.01943] OpenCodeReasoning: Advancing Data Distillation for Competitive Coding
|
||||
* [2504.16891] AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning dataset
|
||||
<br>
|
||||
|
||||
## Model Architecture: <br>
|
||||
Architecture Type: Dense decoder-only Transformer model
|
||||
Network Architecture: Qwen-7B-Instruct
|
||||
<br>
|
||||
**This model was developed based on Qwen2.5-7B-Instruct and has 7B model parameters. <br>**
|
||||
|
||||
**OpenReasoning-Nemotron-1.5B was developed based on Qwen2.5-1.5B-Instruct and has 1.5B model parameters. <br>**
|
||||
|
||||
**OpenReasoning-Nemotron-7B was developed based on Qwen2.5-7B-Instruct and has 7B model parameters. <br>**
|
||||
|
||||
**OpenReasoning-Nemotron-14B was developed based on Qwen2.5-14B-Instruct and has 14B model parameters. <br>**
|
||||
|
||||
**OpenReasoning-Nemotron-32B was developed based on Qwen2.5-32B-Instruct and has 32B model parameters. <br>**
|
||||
|
||||
## Input: <br>
|
||||
**Input Type(s):** Text <br>
|
||||
**Input Format(s):** String <br>
|
||||
**Input Parameters:** One-Dimensional (1D) <br>
|
||||
**Other Properties Related to Input:** Trained for up to 64,000 output tokens <br>
|
||||
|
||||
## Output: <br>
|
||||
**Output Type(s):** Text <br>
|
||||
**Output Format:** String <br>
|
||||
**Output Parameters:** One-Dimensional (1D) <br>
|
||||
**Other Properties Related to Output:** Trained for up to 64,000 output tokens <br>
|
||||
|
||||
Our AI models are designed and/or optimized to run on NVIDIA GPU-accelerated systems. By leveraging NVIDIA’s hardware (e.g. GPU cores) and software frameworks (e.g., CUDA libraries), the model achieves faster training and inference times compared to CPU-only solutions. <br>
|
||||
|
||||
## Software Integration : <br>
|
||||
* Runtime Engine: NeMo 2.3.0 <br>
|
||||
* Recommended Hardware Microarchitecture Compatibility: <br>
|
||||
NVIDIA Ampere <br>
|
||||
NVIDIA Hopper <br>
|
||||
* Preferred/Supported Operating System(s): Linux <br>
|
||||
|
||||
## Model Version(s):
|
||||
1.0 (7/16/2025) <br>
|
||||
OpenReasoning-Nemotron-32B<br>
|
||||
OpenReasoning-Nemotron-14B<br>
|
||||
OpenReasoning-Nemotron-7B<br>
|
||||
OpenReasoning-Nemotron-1.5B<br>
|
||||
|
||||
# Training and Evaluation Datasets: <br>
|
||||
|
||||
## Training Dataset:
|
||||
|
||||
The training corpus for OpenReasoning-Nemotron-7B is comprised of questions from [OpenCodeReasoning](https://huggingface.co/datasets/nvidia/OpenCodeReasoning) dataset, [OpenCodeReasoning-II](https://arxiv.org/abs/2507.09075), [OpenMathReasoning](https://huggingface.co/datasets/nvidia/OpenMathReasoning), and the Synthetic Science questions from the [Llama-Nemotron-Post-Training-Dataset](https://huggingface.co/datasets/nvidia/Llama-Nemotron-Post-Training-Dataset). All responses are generated using DeepSeek-R1-0528. We also include the instruction following and tool calling data from Llama-Nemotron-Post-Training-Dataset without modification.
|
||||
|
||||
Data Collection Method: Hybrid: Automated, Human, Synthetic <br>
|
||||
Labeling Method: Hybrid: Automated, Human, Synthetic <br>
|
||||
Properties: 5M DeepSeek-R1-0528 generated responses from OpenCodeReasoning questions (https://huggingface.co/datasets/nvidia/OpenCodeReasoning), [OpenMathReasoning](https://huggingface.co/datasets/nvidia/OpenMathReasoning), and the Synthetic Science questions from the [Llama-Nemotron-Post-Training-Dataset](https://huggingface.co/datasets/nvidia/Llama-Nemotron-Post-Training-Dataset). We also include the instruction following and tool calling data from Llama-Nemotron-Post-Training-Dataset without modification.
|
||||
|
||||
## Evaluation Dataset:
|
||||
We used the following benchmarks to evaluate the model holistically.
|
||||
|
||||
### Math
|
||||
- AIME 2024/2025 <br>
|
||||
- HMMT <br>
|
||||
- BRUNO 2025 <br>
|
||||
|
||||
### Code
|
||||
- LiveCodeBench <br>
|
||||
- SciCode <br>
|
||||
|
||||
### Science
|
||||
- GPQA <br>
|
||||
- MMLU-PRO <br>
|
||||
- HLE <br>
|
||||
|
||||
|
||||
Data Collection Method: Hybrid: Automated, Human, Synthetic <br>
|
||||
Labeling Method: Hybrid: Automated, Human, Synthetic <br>
|
||||
|
||||
## Inference:
|
||||
**Acceleration Engine:** vLLM, Tensor(RT)-LLM <br>
|
||||
**Test Hardware** NVIDIA H100-80GB <br>
|
||||
|
||||
## Ethical Considerations:
|
||||
NVIDIA believes Trustworthy AI is a shared responsibility and we have established policies and practices to enable development for a wide array of AI applications. When downloaded or used in accordance with our terms of service, developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse.
|
||||
|
||||
For more detailed information on ethical considerations for this model, please see the Model Card++ Explainability, Bias, Safety & Security, and Privacy Subcards.
|
||||
|
||||
Please report model quality, risk, security vulnerabilities or NVIDIA AI Concerns [here](https://www.nvidia.com/en-us/support/submit-security-vulnerability/).
|
||||
|
||||
|
||||
|
||||
<!--End Original Model Card-->
|
||||
|
||||
---
|
||||
|
||||
# <span id="testllm" style="color: #7F7FFF;">🚀 If you find these models useful</span>
|
||||
|
||||
Help me test my **AI-Powered Quantum Network Monitor Assistant** with **quantum-ready security checks**:
|
||||
|
||||
👉 [Quantum Network Monitor](https://readyforquantum.com/?assistant=open&utm_source=huggingface&utm_medium=referral&utm_campaign=huggingface_repo_readme)
|
||||
|
||||
|
||||
The full Open Source Code for the Quantum Network Monitor Service available at my github repos ( repos with NetworkMonitor in the name) : [Source Code Quantum Network Monitor](https://github.com/Mungert69). You will also find the code I use to quantize the models if you want to do it yourself [GGUFModelBuilder](https://github.com/Mungert69/GGUFModelBuilder)
|
||||
|
||||
💬 **How to test**:
|
||||
Choose an **AI assistant type**:
|
||||
- `TurboLLM` (GPT-4.1-mini)
|
||||
- `HugLLM` (Hugginface Open-source models)
|
||||
- `TestLLM` (Experimental CPU-only)
|
||||
|
||||
### **What I’m Testing**
|
||||
I’m pushing the limits of **small open-source models for AI network monitoring**, specifically:
|
||||
- **Function calling** against live network services
|
||||
- **How small can a model go** while still handling:
|
||||
- Automated **Nmap security scans**
|
||||
- **Quantum-readiness checks**
|
||||
- **Network Monitoring tasks**
|
||||
|
||||
🟡 **TestLLM** – Current experimental model (llama.cpp on 2 CPU threads on huggingface docker space):
|
||||
- ✅ **Zero-configuration setup**
|
||||
- ⏳ 30s load time (slow inference but **no API costs**) . No token limited as the cost is low.
|
||||
- 🔧 **Help wanted!** If you’re into **edge-device AI**, let’s collaborate!
|
||||
|
||||
### **Other Assistants**
|
||||
🟢 **TurboLLM** – Uses **gpt-4.1-mini** :
|
||||
- **It performs very well but unfortunatly OpenAI charges per token. For this reason tokens usage is limited.
|
||||
- **Create custom cmd processors to run .net code on Quantum Network Monitor Agents**
|
||||
- **Real-time network diagnostics and monitoring**
|
||||
- **Security Audits**
|
||||
- **Penetration testing** (Nmap/Metasploit)
|
||||
|
||||
🔵 **HugLLM** – Latest Open-source models:
|
||||
- 🌐 Runs on Hugging Face Inference API. Performs pretty well using the lastest models hosted on Novita.
|
||||
|
||||
### 💡 **Example commands you could test**:
|
||||
1. `"Give me info on my websites SSL certificate"`
|
||||
2. `"Check if my server is using quantum safe encyption for communication"`
|
||||
3. `"Run a comprehensive security audit on my server"`
|
||||
4. '"Create a cmd processor to .. (what ever you want)" Note you need to install a [Quantum Network Monitor Agent](https://readyforquantum.com/Download/?utm_source=huggingface&utm_medium=referral&utm_campaign=huggingface_repo_readme) to run the .net code on. This is a very flexible and powerful feature. Use with caution!
|
||||
|
||||
### Final Word
|
||||
|
||||
I fund the servers used to create these model files, run the Quantum Network Monitor service, and pay for inference from Novita and OpenAI—all out of my own pocket. All the code behind the model creation and the Quantum Network Monitor project is [open source](https://github.com/Mungert69). Feel free to use whatever you find helpful.
|
||||
|
||||
If you appreciate the work, please consider [buying me a coffee](https://www.buymeacoffee.com/mahadeva) ☕. Your support helps cover service costs and allows me to raise token limits for everyone.
|
||||
|
||||
I'm also open to job opportunities or sponsorship.
|
||||
|
||||
Thank you! 😊
|
||||
Reference in New Issue
Block a user