初始化项目,由ModelHub XC社区提供模型
Model: Harsh/qwen3-0.6b-pii-sft-v2
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||||
162
README.md
Normal file
162
README.md
Normal file
@@ -0,0 +1,162 @@
|
|||||||
|
---
|
||||||
|
license: apache-2.0
|
||||||
|
base_model: Qwen/Qwen3-0.6B
|
||||||
|
language:
|
||||||
|
- en
|
||||||
|
pipeline_tag: text-generation
|
||||||
|
tags:
|
||||||
|
- pii-detection
|
||||||
|
- named-entity-recognition
|
||||||
|
- token-classification
|
||||||
|
- constrained-decoding
|
||||||
|
- privacy
|
||||||
|
---
|
||||||
|
|
||||||
|
# qwen3-0.6b-pii-sft-v2 · SPANIEL
|
||||||
|
|
||||||
|
*Part of the [SPANIEL project](https://github.com/harshsinghal/SPANIEL) — SPAN Identification from Everyday Language.*
|
||||||
|
|
||||||
|
**[GitHub repo](https://github.com/harshsinghal/SPANIEL)** (code, constrained decoder, eval harness) ·
|
||||||
|
**[Run the demo app](https://github.com/harshsinghal/SPANIEL#try-it-the-demo-app)** (one Docker command, local-only) ·
|
||||||
|
**[Blog series](https://github.com/harshsinghal/SPANIEL#the-journey-as-blog-entries)** (the full training journey)
|
||||||
|
|
||||||
|
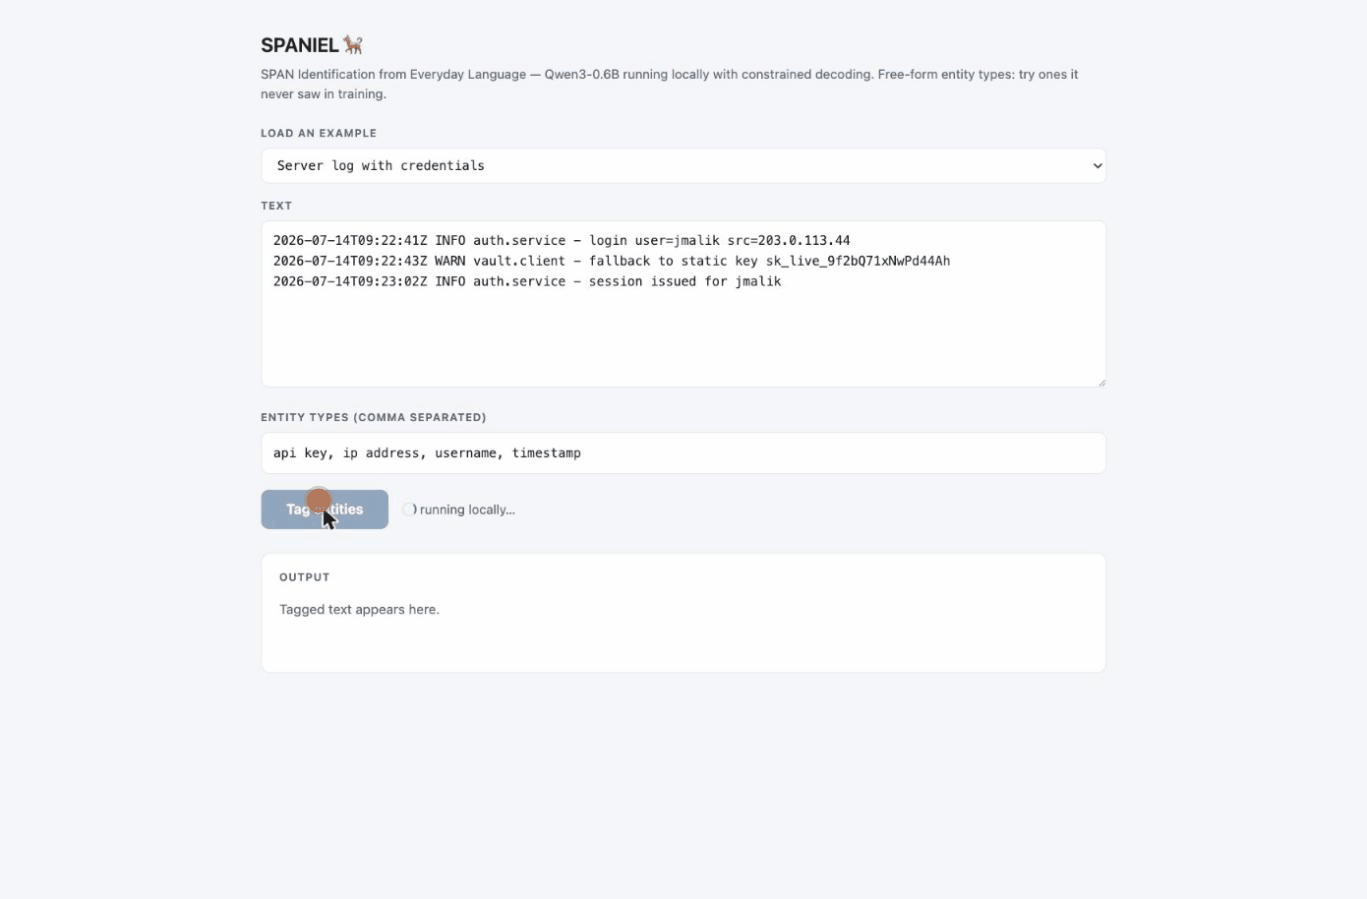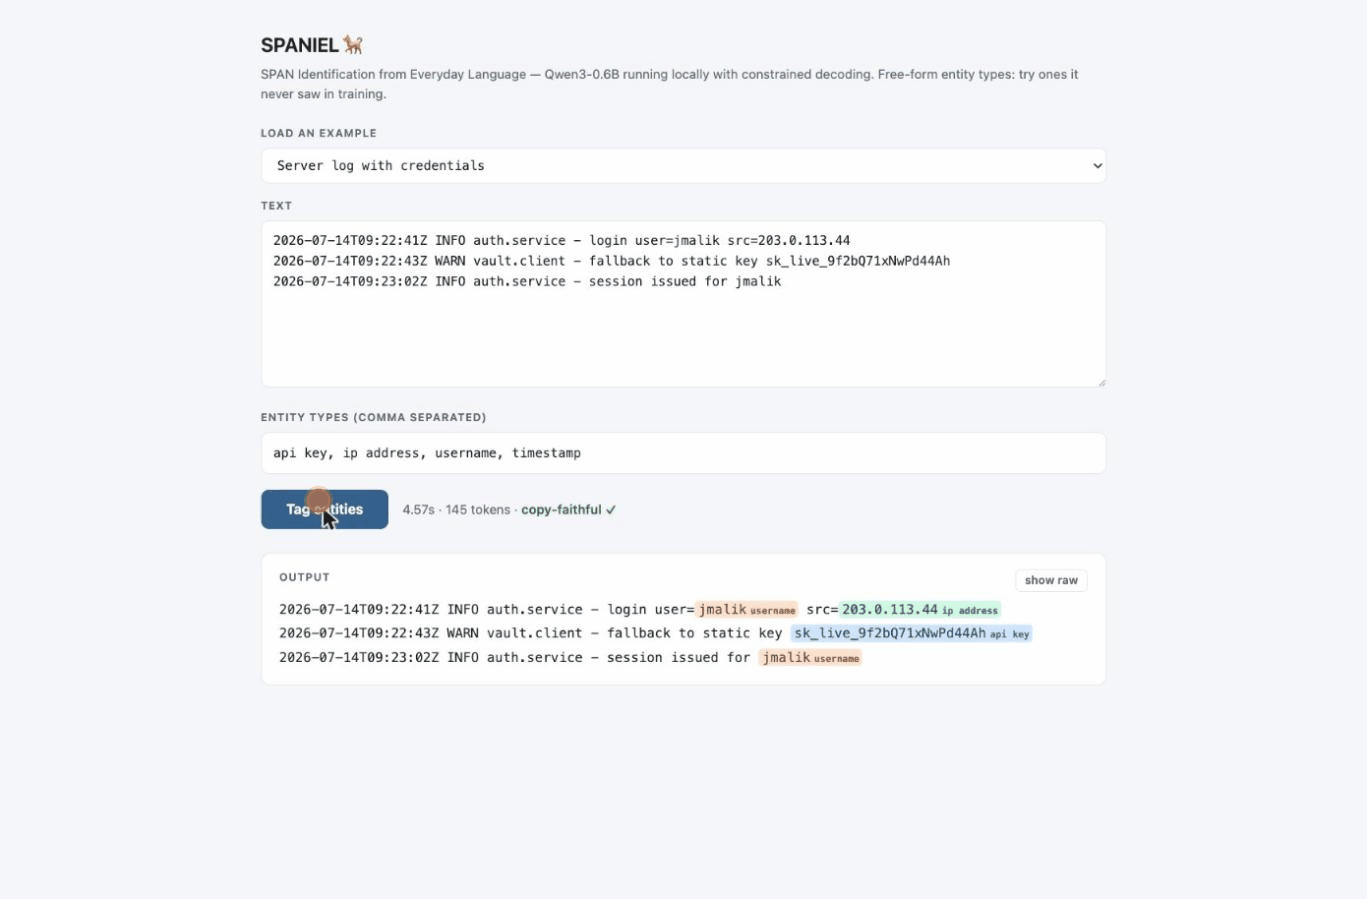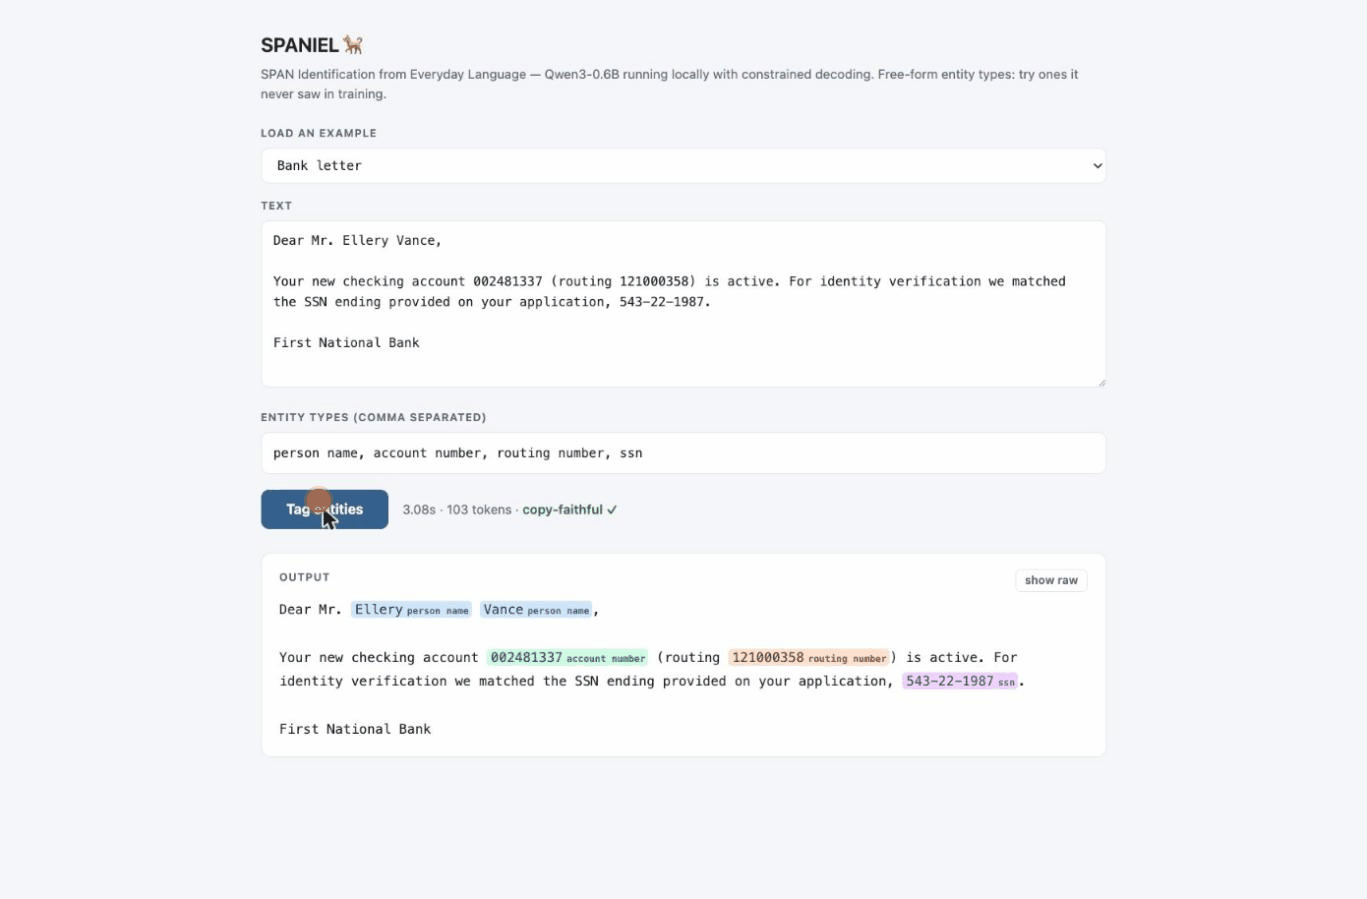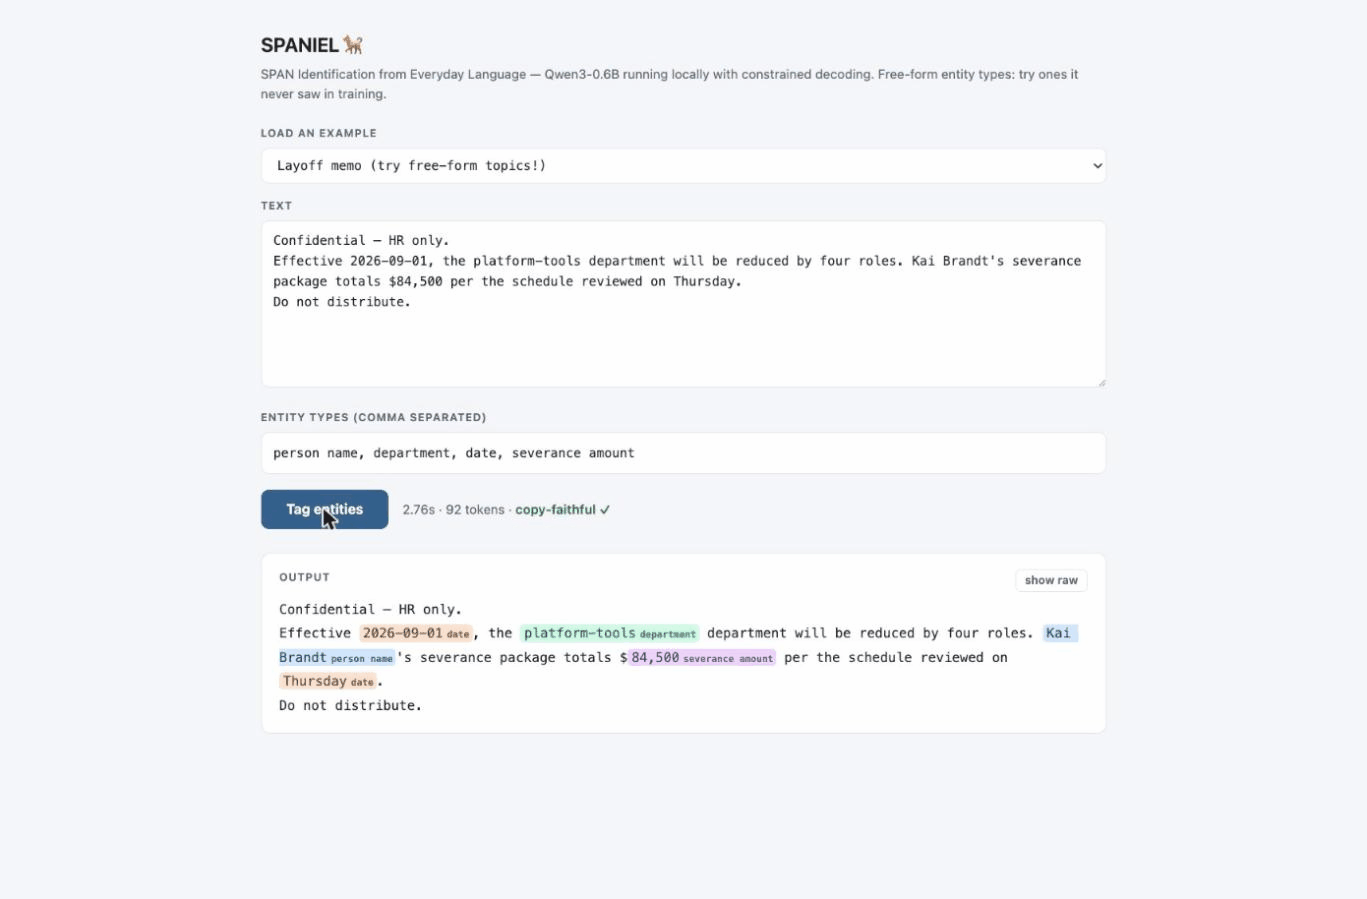
A 0.6B-parameter PII extraction model that accepts **free-form entity type
|
||||||
|
names**. Given a document and a list of types to find — including types never
|
||||||
|
seen in training — it reproduces the document byte-identically with matching
|
||||||
|
spans wrapped in XML tags.
|
||||||
|
|
||||||
|
```
|
||||||
|
Entity types:
|
||||||
|
- person name
|
||||||
|
- patient mrn
|
||||||
|
|
||||||
|
Text:
|
||||||
|
Patient Brian Weaver (MRN BX-40912) called yesterday.
|
||||||
|
```
|
||||||
|
```
|
||||||
|
Patient <person name>Brian Weaver</person name> (MRN <patient mrn>BX-40912</patient mrn>) called yesterday.
|
||||||
|
```
|
||||||
|
|
||||||
|
Designed to be served with a **copy-or-tag constrained decoder** (grammar
|
||||||
|
masking at the logits level) that makes copy drift and malformed tags
|
||||||
|
structurally impossible; the model also behaves well unconstrained
|
||||||
|
(~96% copy-faithful).
|
||||||
|
|
||||||
|
## Try it in two minutes
|
||||||
|
|
||||||
|
A local web app with 15 preloaded examples (medical forms, server logs,
|
||||||
|
transcripts, invoices) and editable free-form entity types — no data leaves
|
||||||
|
your machine:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
docker run -p 8377:8377 -v spaniel-models:/models ghcr.io/harshsinghal/spaniel
|
||||||
|
# open http://localhost:8377
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
The weights are pulled from this repo on first start and cached. On Linux
|
||||||
|
with an NVIDIA GPU add `--gpus all`; on Mac/Windows it runs on CPU. Full
|
||||||
|
details in the [SPANIEL repository](https://github.com/harshsinghal/SPANIEL).
|
||||||
|
|
||||||
|
## Results
|
||||||
|
|
||||||
|
Strict span-level exact-match F1 on a 300-document held-out eval
|
||||||
|
(nvidia/Nemotron-PII test split), constrained decoding:
|
||||||
|
|
||||||
|
| Evaluation axis | F1 |
|
||||||
|
|---|---|
|
||||||
|
| Original gold labels | 0.930 |
|
||||||
|
| Adjudicated gold (annotation noise corrected, human-spot-checked) | 0.918 |
|
||||||
|
| **Requests using entity-type names unseen in training** | **0.864** |
|
||||||
|
|
||||||
|
Reference points: gpt-oss-120b zero-shot with the same prompt scores 0.580
|
||||||
|
(45% copy-drift rate); the v1 model trained on 2–4 aliases per label scored
|
||||||
|
0.747 on unseen names — the wide-alias training in v2 recovered 11.7 points.
|
||||||
|
|
||||||
|
## Training
|
||||||
|
|
||||||
|
- **Base**: Qwen/Qwen3-0.6B, full-parameter SFT (no LoRA), bf16.
|
||||||
|
- **Recipe**: TRL `SFTTrainer`, prompt-completion format with loss on the
|
||||||
|
tagged completion only; sequence length 3072; effective batch 32
|
||||||
|
(16 × grad-accum 2); lr 1e-5 cosine, 1 epoch = 12,142 steps.
|
||||||
|
- **GPU time (this model)**: ~11 hours on a single H100 NVL, plus ~2 hours of
|
||||||
|
evaluation generation. Checkpoints were pushed to this repo every 500 steps
|
||||||
|
(`hub_strategy="every_save"`), so the full training trajectory is preserved
|
||||||
|
in the commit history.
|
||||||
|
- **Lineage GPU time**: v1-50k ablation ~3.7h (A100 40GB), v1-full ~8h
|
||||||
|
(H100 NVL), 0.6B/1.7B size ablations ~3h (A100). Entire project including
|
||||||
|
all failures: roughly $85 of rented spot GPU time.
|
||||||
|
|
||||||
|
## Datasets and how they were combined
|
||||||
|
|
||||||
|
389,521 training examples from four sources:
|
||||||
|
|
||||||
|
| Source | Share | Notes |
|
||||||
|
|---|---|---|
|
||||||
|
| [gravitee-io/pii-detection-dataset](https://huggingface.co/datasets/gravitee-io/pii-detection-dataset) | 44.6% | 22 coarse labels; format diversity (HTML/JSON/logs); 3 junk labels dropped |
|
||||||
|
| [nvidia/Nemotron-PII](https://huggingface.co/datasets/nvidia/Nemotron-PII) | 25.7% | 55 fine labels; `date_time` spans lacking a clock time deterministically relabeled to `date` |
|
||||||
|
| [ai4privacy/pii-masking-openpii-1.5m](https://huggingface.co/datasets/ai4privacy/pii-masking-openpii-1.5m) | 28.2% | English slice only (163k rows, 110k sampled); 20 high-frequency labels; 1-char spans dropped |
|
||||||
|
| Synthetic register documents | 1.5% | 1,966 batch-generated JSON-log / checkbox-form / prose docs (upsampled ×3), filling register gaps found by error analysis |
|
||||||
|
|
||||||
|
Combination principles (full details and seeded, reproducible builders in the [SPANIEL repository](https://github.com/harshsinghal/SPANIEL)):
|
||||||
|
|
||||||
|
- **Label schemas are not unified.** Each example's request carries its own
|
||||||
|
source's vocabulary; the label set is an input, so cross-source synonyms
|
||||||
|
(`US_SSN` vs `ssn` vs `SOCIALNUM`) are conditioning signal, not conflicts.
|
||||||
|
- **Label names are sampled from ~22 natural-language aliases per label**
|
||||||
|
("date of birth" / "dob" / "birthdate" / "day someone was born"...), which
|
||||||
|
is the mechanism behind unseen-name generalization.
|
||||||
|
- **Request construction**: 40% full source vocabulary, 40% present labels
|
||||||
|
plus 2–6 negatives (biased toward containment families — city/state/country,
|
||||||
|
first/last name — where abstention is hardest), 20% strict subsets.
|
||||||
|
- **Guideline conditioning**: 30% of examples carry short per-label rules in
|
||||||
|
the request, with targets relabeled to obey them.
|
||||||
|
- **Every target is byte-exact**: stripping tags reproduces the input
|
||||||
|
exactly (validated at build time; 0 violations in 5,000 sampled).
|
||||||
|
|
||||||
|
## Usage
|
||||||
|
|
||||||
|
```python
|
||||||
|
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||||
|
|
||||||
|
tok = AutoTokenizer.from_pretrained("Harsh/qwen3-0.6b-pii-sft-v2")
|
||||||
|
model = AutoModelForCausalLM.from_pretrained("Harsh/qwen3-0.6b-pii-sft-v2",
|
||||||
|
dtype="bfloat16", device_map="auto")
|
||||||
|
|
||||||
|
SYSTEM = ("You tag entities in text. Reproduce the user's text exactly, wrapping each "
|
||||||
|
"entity that matches a requested type in XML tags, like <label>entity</label>. "
|
||||||
|
"Use only the requested labels. Tag every match. If nothing matches, reproduce "
|
||||||
|
"the text unchanged. Never alter, add, or omit any other characters.")
|
||||||
|
|
||||||
|
types = ["person name", "email", "employee badge id"] # free-form
|
||||||
|
text = "Reach Anita (badge A-7731) at anita.k@corp.io."
|
||||||
|
user = "Entity types:\n" + "\n".join(f"- {t}" for t in types) + "\n\nText:\n" + text
|
||||||
|
|
||||||
|
prompt = tok.apply_chat_template(
|
||||||
|
[{"role": "system", "content": SYSTEM}, {"role": "user", "content": user}],
|
||||||
|
tokenize=False, add_generation_prompt=True, enable_thinking=False) # important
|
||||||
|
out = model.generate(**tok(prompt, return_tensors="pt").to(model.device),
|
||||||
|
max_new_tokens=1024, do_sample=False)
|
||||||
|
print(tok.decode(out[0], skip_special_tokens=True))
|
||||||
|
```
|
||||||
|
|
||||||
|
Pass `enable_thinking=False` — the model was trained without thinking blocks.
|
||||||
|
For production use, pair with the constrained decoder from the [SPANIEL
|
||||||
|
repository](https://github.com/harshsinghal/SPANIEL) (`pii_decode.py`): it guarantees output validity and is slightly
|
||||||
|
faster than unconstrained generation.
|
||||||
|
|
||||||
|
## Limitations
|
||||||
|
|
||||||
|
- **English only.** Multilingual source data was deliberately filtered out.
|
||||||
|
- **Attribute semantics**: entities are spans disclosing information about a
|
||||||
|
person or their record. World-fact mentions (a country named in encyclopedic
|
||||||
|
prose) are intentionally *not* tagged. This is a documented annotation
|
||||||
|
stance, not a bug.
|
||||||
|
- Unseen type names work well when semantically near the training
|
||||||
|
distribution; paraphrases far outside any alias set's reach can fail
|
||||||
|
entirely (measured floor exists — see the evaluation writeups).
|
||||||
|
- Softer semantic types (occupation, times) remain the weakest labels.
|
||||||
|
- Trained and evaluated on synthetic PII corpora; validate on your own
|
||||||
|
distribution before production use. Review the source datasets' licenses
|
||||||
|
before commercial redistribution.
|
||||||
89
chat_template.jinja
Normal file
89
chat_template.jinja
Normal file
@@ -0,0 +1,89 @@
|
|||||||
|
{%- if tools %}
|
||||||
|
{{- '<|im_start|>system\n' }}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- messages[0].content + '\n\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
||||||
|
{%- for tool in tools %}
|
||||||
|
{{- "\n" }}
|
||||||
|
{{- tool | tojson }}
|
||||||
|
{%- endfor %}
|
||||||
|
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
||||||
|
{%- else %}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
||||||
|
{%- for message in messages[::-1] %}
|
||||||
|
{%- set index = (messages|length - 1) - loop.index0 %}
|
||||||
|
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
||||||
|
{%- set ns.multi_step_tool = false %}
|
||||||
|
{%- set ns.last_query_index = index %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- for message in messages %}
|
||||||
|
{%- if message.content is string %}
|
||||||
|
{%- set content = message.content %}
|
||||||
|
{%- else %}
|
||||||
|
{%- set content = '' %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
||||||
|
{%- elif message.role == "assistant" %}
|
||||||
|
{%- set reasoning_content = '' %}
|
||||||
|
{%- if message.reasoning_content is string %}
|
||||||
|
{%- set reasoning_content = message.reasoning_content %}
|
||||||
|
{%- else %}
|
||||||
|
{%- if '</think>' in content %}
|
||||||
|
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
||||||
|
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if loop.index0 > ns.last_query_index %}
|
||||||
|
{%- if loop.last or (not loop.last and reasoning_content) %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip('\n') + '\n</think>\n\n' + content.lstrip('\n') }}
|
||||||
|
{%- else %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- else %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if message.tool_calls %}
|
||||||
|
{%- for tool_call in message.tool_calls %}
|
||||||
|
{%- if (loop.first and content) or (not loop.first) %}
|
||||||
|
{{- '\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if tool_call.function %}
|
||||||
|
{%- set tool_call = tool_call.function %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<tool_call>\n{"name": "' }}
|
||||||
|
{{- tool_call.name }}
|
||||||
|
{{- '", "arguments": ' }}
|
||||||
|
{%- if tool_call.arguments is string %}
|
||||||
|
{{- tool_call.arguments }}
|
||||||
|
{%- else %}
|
||||||
|
{{- tool_call.arguments | tojson }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '}\n</tool_call>' }}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- elif message.role == "tool" %}
|
||||||
|
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
||||||
|
{{- '<|im_start|>user' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '\n<tool_response>\n' }}
|
||||||
|
{{- content }}
|
||||||
|
{{- '\n</tool_response>' }}
|
||||||
|
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- if add_generation_prompt %}
|
||||||
|
{{- '<|im_start|>assistant\n' }}
|
||||||
|
{%- if enable_thinking is defined and enable_thinking is false %}
|
||||||
|
{{- '<think>\n\n</think>\n\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
63
config.json
Normal file
63
config.json
Normal file
@@ -0,0 +1,63 @@
|
|||||||
|
{
|
||||||
|
"architectures": [
|
||||||
|
"Qwen3ForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_bias": false,
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"bos_token_id": null,
|
||||||
|
"dtype": "bfloat16",
|
||||||
|
"eos_token_id": 151645,
|
||||||
|
"head_dim": 128,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 1024,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 3072,
|
||||||
|
"layer_types": [
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention"
|
||||||
|
],
|
||||||
|
"max_position_embeddings": 40960,
|
||||||
|
"max_window_layers": 28,
|
||||||
|
"model_type": "qwen3",
|
||||||
|
"num_attention_heads": 16,
|
||||||
|
"num_hidden_layers": 28,
|
||||||
|
"num_key_value_heads": 8,
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"rope_parameters": {
|
||||||
|
"rope_theta": 1000000,
|
||||||
|
"rope_type": "default"
|
||||||
|
},
|
||||||
|
"sliding_window": null,
|
||||||
|
"tie_word_embeddings": true,
|
||||||
|
"transformers_version": "5.14.1",
|
||||||
|
"use_cache": false,
|
||||||
|
"use_sliding_window": false,
|
||||||
|
"vocab_size": 151936
|
||||||
|
}
|
||||||
89
final/chat_template.jinja
Normal file
89
final/chat_template.jinja
Normal file
@@ -0,0 +1,89 @@
|
|||||||
|
{%- if tools %}
|
||||||
|
{{- '<|im_start|>system\n' }}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- messages[0].content + '\n\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
||||||
|
{%- for tool in tools %}
|
||||||
|
{{- "\n" }}
|
||||||
|
{{- tool | tojson }}
|
||||||
|
{%- endfor %}
|
||||||
|
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
||||||
|
{%- else %}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
||||||
|
{%- for message in messages[::-1] %}
|
||||||
|
{%- set index = (messages|length - 1) - loop.index0 %}
|
||||||
|
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
||||||
|
{%- set ns.multi_step_tool = false %}
|
||||||
|
{%- set ns.last_query_index = index %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- for message in messages %}
|
||||||
|
{%- if message.content is string %}
|
||||||
|
{%- set content = message.content %}
|
||||||
|
{%- else %}
|
||||||
|
{%- set content = '' %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
||||||
|
{%- elif message.role == "assistant" %}
|
||||||
|
{%- set reasoning_content = '' %}
|
||||||
|
{%- if message.reasoning_content is string %}
|
||||||
|
{%- set reasoning_content = message.reasoning_content %}
|
||||||
|
{%- else %}
|
||||||
|
{%- if '</think>' in content %}
|
||||||
|
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
||||||
|
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if loop.index0 > ns.last_query_index %}
|
||||||
|
{%- if loop.last or (not loop.last and reasoning_content) %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip('\n') + '\n</think>\n\n' + content.lstrip('\n') }}
|
||||||
|
{%- else %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- else %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if message.tool_calls %}
|
||||||
|
{%- for tool_call in message.tool_calls %}
|
||||||
|
{%- if (loop.first and content) or (not loop.first) %}
|
||||||
|
{{- '\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if tool_call.function %}
|
||||||
|
{%- set tool_call = tool_call.function %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<tool_call>\n{"name": "' }}
|
||||||
|
{{- tool_call.name }}
|
||||||
|
{{- '", "arguments": ' }}
|
||||||
|
{%- if tool_call.arguments is string %}
|
||||||
|
{{- tool_call.arguments }}
|
||||||
|
{%- else %}
|
||||||
|
{{- tool_call.arguments | tojson }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '}\n</tool_call>' }}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- elif message.role == "tool" %}
|
||||||
|
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
||||||
|
{{- '<|im_start|>user' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '\n<tool_response>\n' }}
|
||||||
|
{{- content }}
|
||||||
|
{{- '\n</tool_response>' }}
|
||||||
|
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- if add_generation_prompt %}
|
||||||
|
{{- '<|im_start|>assistant\n' }}
|
||||||
|
{%- if enable_thinking is defined and enable_thinking is false %}
|
||||||
|
{{- '<think>\n\n</think>\n\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
63
final/config.json
Normal file
63
final/config.json
Normal file
@@ -0,0 +1,63 @@
|
|||||||
|
{
|
||||||
|
"architectures": [
|
||||||
|
"Qwen3ForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_bias": false,
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"bos_token_id": null,
|
||||||
|
"dtype": "bfloat16",
|
||||||
|
"eos_token_id": 151645,
|
||||||
|
"head_dim": 128,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 1024,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 3072,
|
||||||
|
"layer_types": [
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention"
|
||||||
|
],
|
||||||
|
"max_position_embeddings": 40960,
|
||||||
|
"max_window_layers": 28,
|
||||||
|
"model_type": "qwen3",
|
||||||
|
"num_attention_heads": 16,
|
||||||
|
"num_hidden_layers": 28,
|
||||||
|
"num_key_value_heads": 8,
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"rope_parameters": {
|
||||||
|
"rope_theta": 1000000,
|
||||||
|
"rope_type": "default"
|
||||||
|
},
|
||||||
|
"sliding_window": null,
|
||||||
|
"tie_word_embeddings": true,
|
||||||
|
"transformers_version": "5.14.1",
|
||||||
|
"use_cache": false,
|
||||||
|
"use_sliding_window": false,
|
||||||
|
"vocab_size": 151936
|
||||||
|
}
|
||||||
12
final/generation_config.json
Normal file
12
final/generation_config.json
Normal file
@@ -0,0 +1,12 @@
|
|||||||
|
{
|
||||||
|
"do_sample": true,
|
||||||
|
"eos_token_id": [
|
||||||
|
151645,
|
||||||
|
151643
|
||||||
|
],
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"temperature": 0.6,
|
||||||
|
"top_k": 20,
|
||||||
|
"top_p": 0.95,
|
||||||
|
"transformers_version": "5.14.1"
|
||||||
|
}
|
||||||
3
final/model.safetensors
Normal file
3
final/model.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:3ce13010b5f0430e188be1261654cc41d7f05eafc6cb1ebffa6576c5e020dc6b
|
||||||
|
size 1192135096
|
||||||
3
final/tokenizer.json
Normal file
3
final/tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:be75606093db2094d7cd20f3c2f385c212750648bd6ea4fb2bf507a6a4c55506
|
||||||
|
size 11422650
|
||||||
30
final/tokenizer_config.json
Normal file
30
final/tokenizer_config.json
Normal file
@@ -0,0 +1,30 @@
|
|||||||
|
{
|
||||||
|
"add_prefix_space": false,
|
||||||
|
"backend": "tokenizers",
|
||||||
|
"bos_token": null,
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": "<|im_end|>",
|
||||||
|
"errors": "replace",
|
||||||
|
"extra_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"is_local": false,
|
||||||
|
"local_files_only": false,
|
||||||
|
"model_max_length": 131072,
|
||||||
|
"pad_token": "<|endoftext|>",
|
||||||
|
"split_special_tokens": false,
|
||||||
|
"tokenizer_class": "Qwen2Tokenizer",
|
||||||
|
"unk_token": null
|
||||||
|
}
|
||||||
3
final/training_args.bin
Normal file
3
final/training_args.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:e9cf1e48f0e596621ab62b1cf847e02fe77482cf32b2b9aa9a7f328201dc9b94
|
||||||
|
size 5777
|
||||||
12
generation_config.json
Normal file
12
generation_config.json
Normal file
@@ -0,0 +1,12 @@
|
|||||||
|
{
|
||||||
|
"do_sample": true,
|
||||||
|
"eos_token_id": [
|
||||||
|
151645,
|
||||||
|
151643
|
||||||
|
],
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"temperature": 0.6,
|
||||||
|
"top_k": 20,
|
||||||
|
"top_p": 0.95,
|
||||||
|
"transformers_version": "5.14.1"
|
||||||
|
}
|
||||||
3
model.safetensors
Normal file
3
model.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:3ce13010b5f0430e188be1261654cc41d7f05eafc6cb1ebffa6576c5e020dc6b
|
||||||
|
size 1192135096
|
||||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:be75606093db2094d7cd20f3c2f385c212750648bd6ea4fb2bf507a6a4c55506
|
||||||
|
size 11422650
|
||||||
30
tokenizer_config.json
Normal file
30
tokenizer_config.json
Normal file
@@ -0,0 +1,30 @@
|
|||||||
|
{
|
||||||
|
"add_prefix_space": false,
|
||||||
|
"backend": "tokenizers",
|
||||||
|
"bos_token": null,
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": "<|im_end|>",
|
||||||
|
"errors": "replace",
|
||||||
|
"extra_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"is_local": false,
|
||||||
|
"local_files_only": false,
|
||||||
|
"model_max_length": 131072,
|
||||||
|
"pad_token": "<|endoftext|>",
|
||||||
|
"split_special_tokens": false,
|
||||||
|
"tokenizer_class": "Qwen2Tokenizer",
|
||||||
|
"unk_token": null
|
||||||
|
}
|
||||||
3
training_args.bin
Normal file
3
training_args.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:e9cf1e48f0e596621ab62b1cf847e02fe77482cf32b2b9aa9a7f328201dc9b94
|
||||||
|
size 5777
|
||||||
Reference in New Issue
Block a user