
license, base_model, language, pipeline_tag, tags
| license | base_model | language | pipeline_tag | tags | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| apache-2.0 | Qwen/Qwen3-0.6B |
|
text-generation |
|
qwen3-0.6b-pii-sft-v2 · SPANIEL
Part of the SPANIEL project — SPAN Identification from Everyday Language.
GitHub repo (code, constrained decoder, eval harness) · Run the demo app (one Docker command, local-only) · Blog series (the full training journey)
A 0.6B-parameter PII extraction model that accepts free-form entity type names. Given a document and a list of types to find — including types never seen in training — it reproduces the document byte-identically with matching spans wrapped in XML tags.
Entity types:
- person name
- patient mrn

Text:
Patient Brian Weaver (MRN BX-40912) called yesterday.
Patient <person name>Brian Weaver</person name> (MRN <patient mrn>BX-40912</patient mrn>) called yesterday.
Designed to be served with a copy-or-tag constrained decoder (grammar masking at the logits level) that makes copy drift and malformed tags structurally impossible; the model also behaves well unconstrained (~96% copy-faithful).
Try it in two minutes
A local web app with 15 preloaded examples (medical forms, server logs, transcripts, invoices) and editable free-form entity types — no data leaves your machine:
docker run -p 8377:8377 -v spaniel-models:/models ghcr.io/harshsinghal/spaniel
# open http://localhost:8377
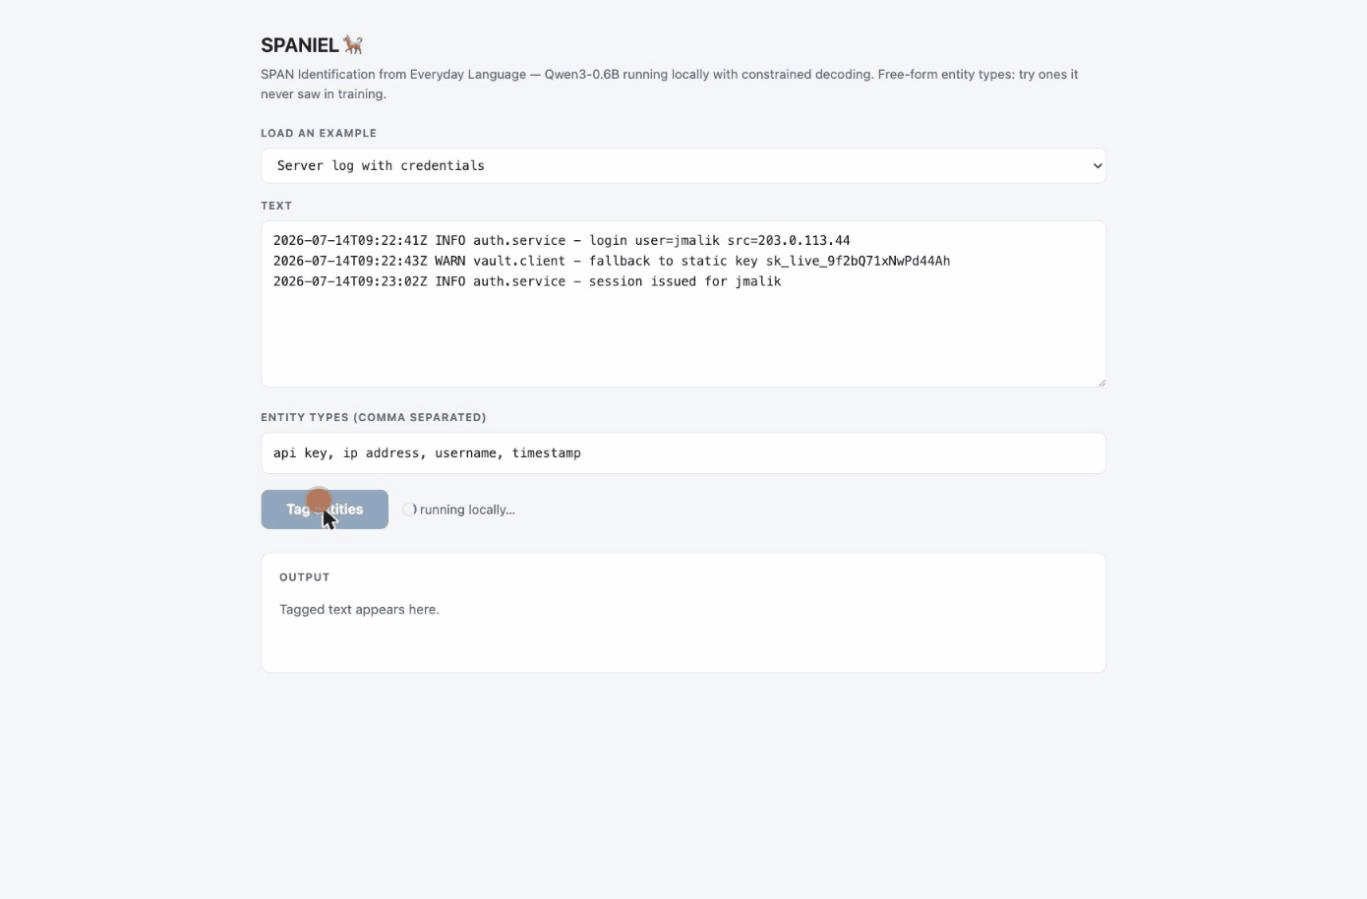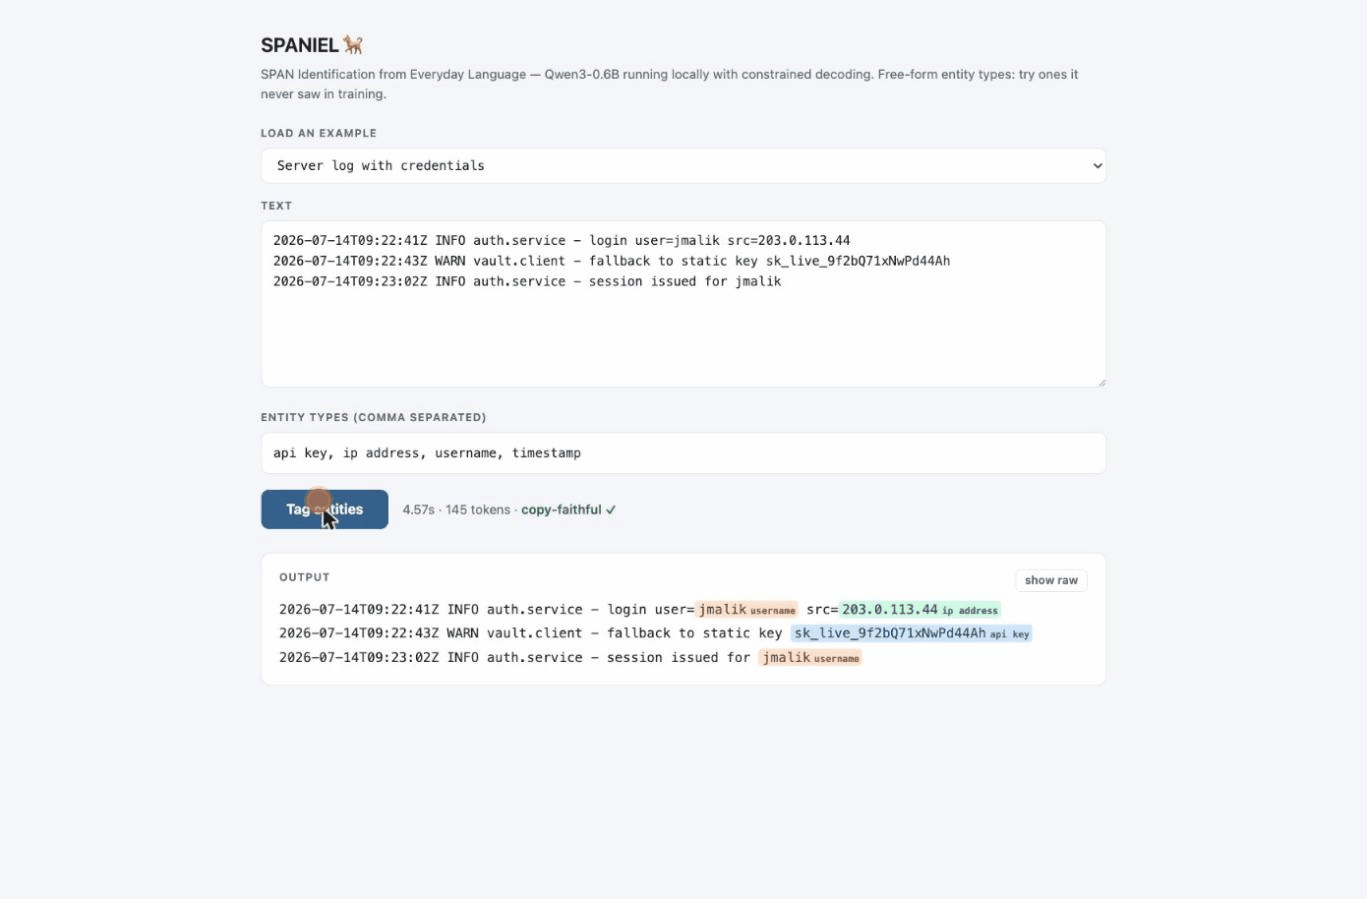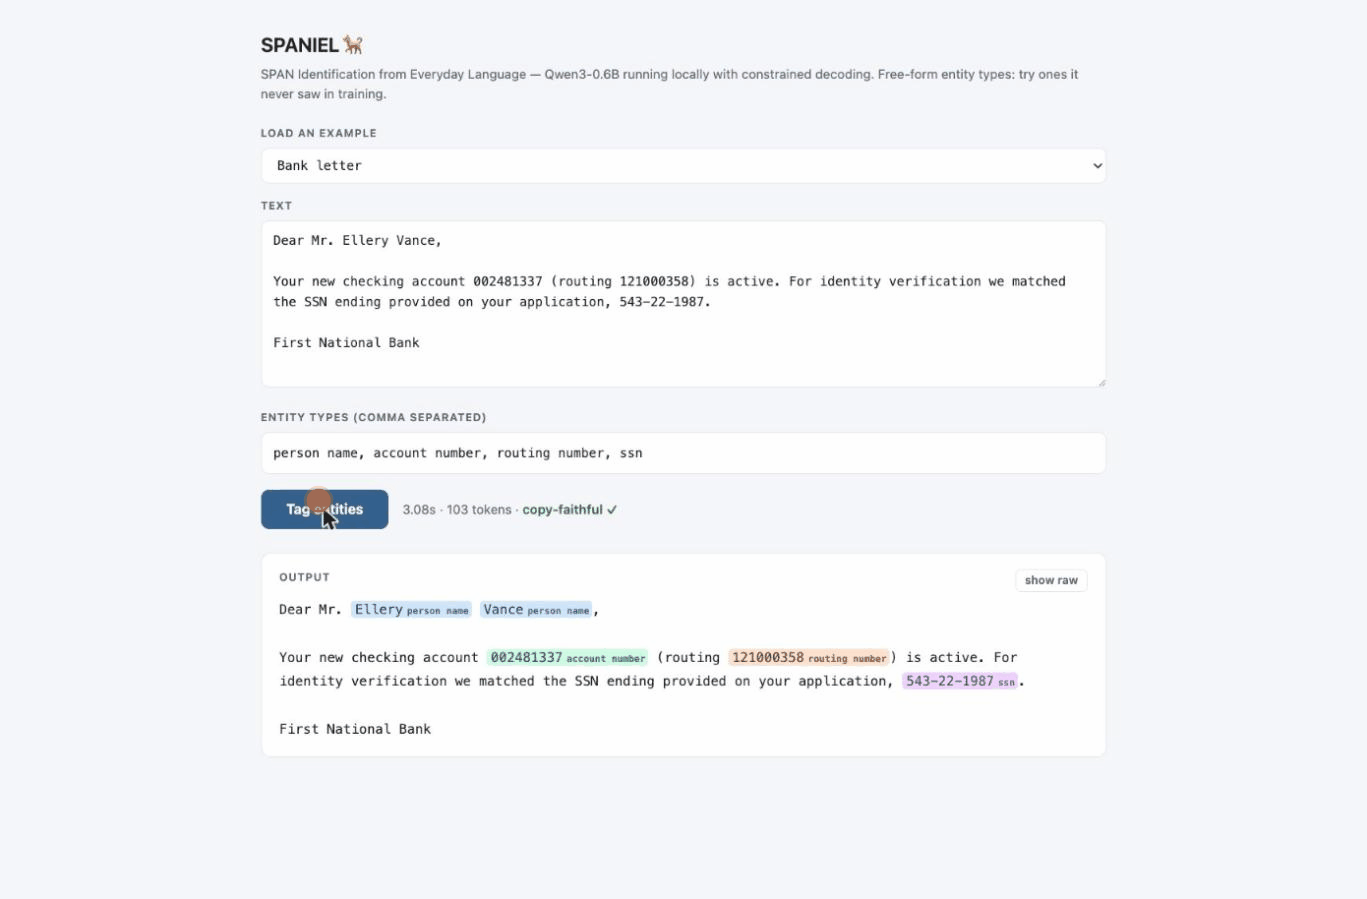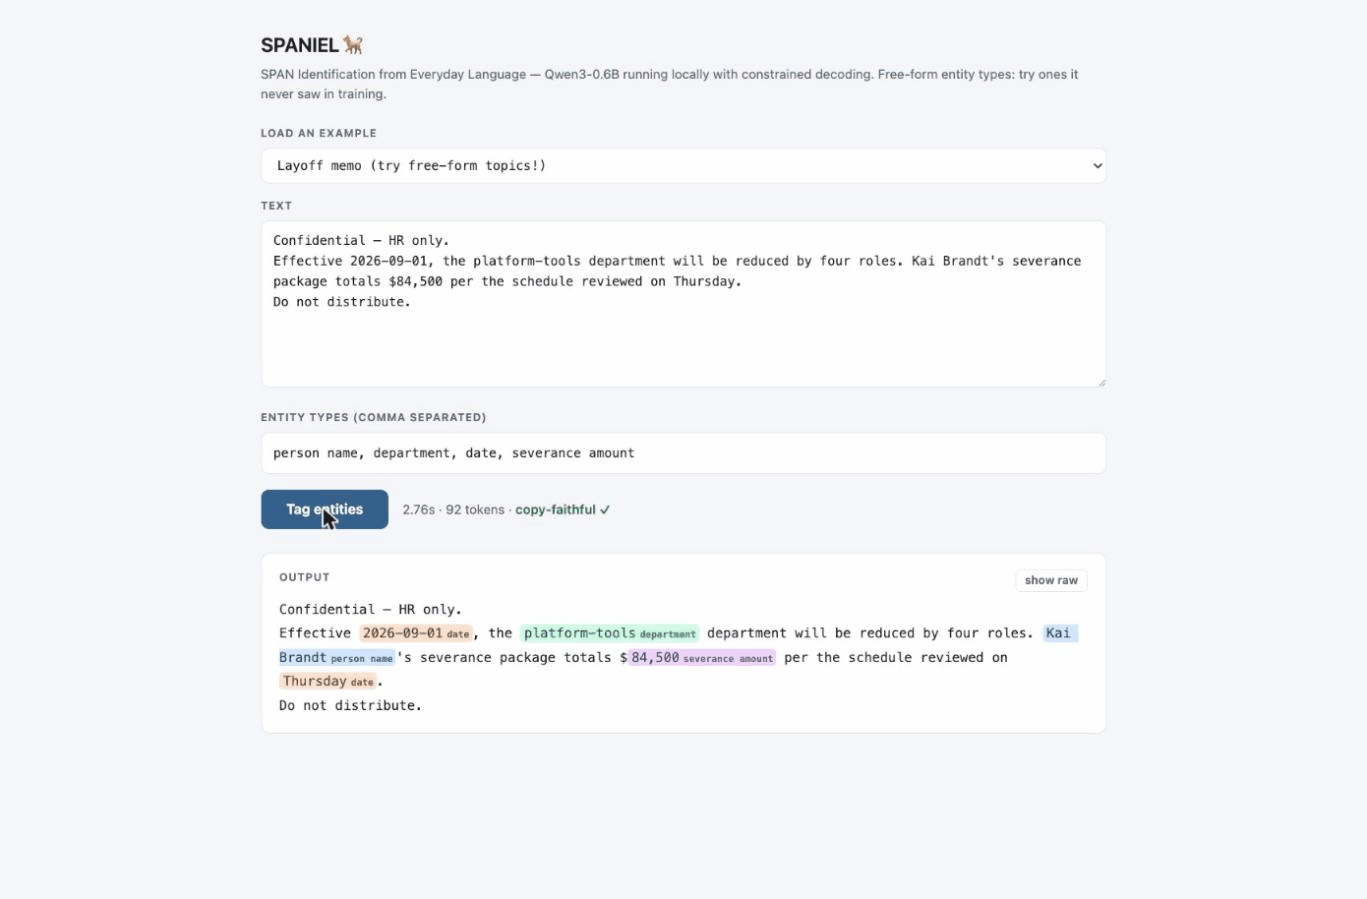
The weights are pulled from this repo on first start and cached. On Linux
with an NVIDIA GPU add --gpus all; on Mac/Windows it runs on CPU. Full
details in the SPANIEL repository.
Results
Strict span-level exact-match F1 on a 300-document held-out eval (nvidia/Nemotron-PII test split), constrained decoding:
| Evaluation axis | F1 |
|---|---|
| Original gold labels | 0.930 |
| Adjudicated gold (annotation noise corrected, human-spot-checked) | 0.918 |
| Requests using entity-type names unseen in training | 0.864 |
Reference points: gpt-oss-120b zero-shot with the same prompt scores 0.580 (45% copy-drift rate); the v1 model trained on 2–4 aliases per label scored 0.747 on unseen names — the wide-alias training in v2 recovered 11.7 points.
Training
- Base: Qwen/Qwen3-0.6B, full-parameter SFT (no LoRA), bf16.
- Recipe: TRL
SFTTrainer, prompt-completion format with loss on the tagged completion only; sequence length 3072; effective batch 32 (16 × grad-accum 2); lr 1e-5 cosine, 1 epoch = 12,142 steps. - GPU time (this model): ~11 hours on a single H100 NVL, plus ~2 hours of
evaluation generation. Checkpoints were pushed to this repo every 500 steps
(
hub_strategy="every_save"), so the full training trajectory is preserved in the commit history. - Lineage GPU time: v1-50k ablation ~3.7h (A100 40GB), v1-full ~8h (H100 NVL), 0.6B/1.7B size ablations ~3h (A100). Entire project including all failures: roughly $85 of rented spot GPU time.
Datasets and how they were combined
389,521 training examples from four sources:
| Source | Share | Notes |
|---|---|---|
| gravitee-io/pii-detection-dataset | 44.6% | 22 coarse labels; format diversity (HTML/JSON/logs); 3 junk labels dropped |
| nvidia/Nemotron-PII | 25.7% | 55 fine labels; date_time spans lacking a clock time deterministically relabeled to date |
| ai4privacy/pii-masking-openpii-1.5m | 28.2% | English slice only (163k rows, 110k sampled); 20 high-frequency labels; 1-char spans dropped |
| Synthetic register documents | 1.5% | 1,966 batch-generated JSON-log / checkbox-form / prose docs (upsampled ×3), filling register gaps found by error analysis |
Combination principles (full details and seeded, reproducible builders in the SPANIEL repository):
- Label schemas are not unified. Each example's request carries its own
source's vocabulary; the label set is an input, so cross-source synonyms
(
US_SSNvsssnvsSOCIALNUM) are conditioning signal, not conflicts. - Label names are sampled from ~22 natural-language aliases per label ("date of birth" / "dob" / "birthdate" / "day someone was born"...), which is the mechanism behind unseen-name generalization.
- Request construction: 40% full source vocabulary, 40% present labels plus 2–6 negatives (biased toward containment families — city/state/country, first/last name — where abstention is hardest), 20% strict subsets.
- Guideline conditioning: 30% of examples carry short per-label rules in the request, with targets relabeled to obey them.
- Every target is byte-exact: stripping tags reproduces the input exactly (validated at build time; 0 violations in 5,000 sampled).
Usage
from transformers import AutoModelForCausalLM, AutoTokenizer

tok = AutoTokenizer.from_pretrained("Harsh/qwen3-0.6b-pii-sft-v2")
model = AutoModelForCausalLM.from_pretrained("Harsh/qwen3-0.6b-pii-sft-v2",
                                             dtype="bfloat16", device_map="auto")

SYSTEM = ("You tag entities in text. Reproduce the user's text exactly, wrapping each "
          "entity that matches a requested type in XML tags, like <label>entity</label>. "
          "Use only the requested labels. Tag every match. If nothing matches, reproduce "
          "the text unchanged. Never alter, add, or omit any other characters.")

types = ["person name", "email", "employee badge id"]   # free-form
text = "Reach Anita (badge A-7731) at anita.k@corp.io."
user = "Entity types:\n" + "\n".join(f"- {t}" for t in types) + "\n\nText:\n" + text

prompt = tok.apply_chat_template(
    [{"role": "system", "content": SYSTEM}, {"role": "user", "content": user}],
    tokenize=False, add_generation_prompt=True, enable_thinking=False)  # important
out = model.generate(**tok(prompt, return_tensors="pt").to(model.device),
                     max_new_tokens=1024, do_sample=False)
print(tok.decode(out[0], skip_special_tokens=True))
Pass enable_thinking=False — the model was trained without thinking blocks.
For production use, pair with the constrained decoder from the SPANIEL
repository (pii_decode.py): it guarantees output validity and is slightly
faster than unconstrained generation.
Limitations
- English only. Multilingual source data was deliberately filtered out.
- Attribute semantics: entities are spans disclosing information about a person or their record. World-fact mentions (a country named in encyclopedic prose) are intentionally not tagged. This is a documented annotation stance, not a bug.
- Unseen type names work well when semantically near the training distribution; paraphrases far outside any alias set's reach can fail entirely (measured floor exists — see the evaluation writeups).
- Softer semantic types (occupation, times) remain the weakest labels.
- Trained and evaluated on synthetic PII corpora; validate on your own distribution before production use. Review the source datasets' licenses before commercial redistribution.