初始化项目,由ModelHub XC社区提供模型
Model: ELVISIO/Qwen3-30B-A3B-Instruct-2507-AWQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||
325
README.md
Normal file
325
README.md
Normal file
@@ -0,0 +1,325 @@
|
||||
---
|
||||
library_name: transformers
|
||||
license: apache-2.0
|
||||
license_link: https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE
|
||||
pipeline_tag: text-generation
|
||||
base_model:
|
||||
- Qwen/Qwen3-30B-A3B-Instruct-2507
|
||||
---
|
||||
|
||||
# Qwen3-30B-A3B-Instruct-2507-AWQ
|
||||
|
||||
## Introduction
|
||||
|
||||
The AWQ version is quantized using [ms-swift](https://github.com/modelscope/ms-swift). The AWQ models for Qwen3-30B-A3B-Instruct-2507 have been verified to work with both Transformers and vLLM.
|
||||
|
||||
## Inference
|
||||
|
||||
use transformers:
|
||||
|
||||
```python
|
||||
from modelscope import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "ELVISIO/Qwen3-30B-A3B-Instruct-2507-AWQ"
|
||||
|
||||
# load the tokenizer and the model
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_name,
|
||||
torch_dtype="auto",
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
# prepare the model input
|
||||
prompt = "Give me a short introduction to large language model."
|
||||
messages = [
|
||||
{"role": "user", "content": prompt}
|
||||
]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
)
|
||||
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
||||
|
||||
# conduct text completion
|
||||
generated_ids = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=16384
|
||||
)
|
||||
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
||||
|
||||
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
print("content:", content)
|
||||
```
|
||||
|
||||
use vllm:
|
||||
```shell
|
||||
vllm serve \
|
||||
ELVISIO/Qwen3-30B-A3B-Instruct-2507-AWQ \
|
||||
--max-model-len 64000
|
||||
|
||||
docker run -d \
|
||||
--name vllm-gpu \
|
||||
--runtime nvidia --gpus all \
|
||||
-v ~/.cache/huggingface:/root/.cache/huggingface \
|
||||
--add-host="host.docker.internal:host-gateway" \
|
||||
-p 8000:8000 \
|
||||
--ipc=host \
|
||||
--restart=always \
|
||||
vllm/vllm-openai:v0.10.0 \
|
||||
--model ELVISIO/Qwen3-30B-A3B-Instruct-2507-AWQ \
|
||||
--served-model-name qwen3:30b \
|
||||
--host 0.0.0.0 \
|
||||
--port 8000 \
|
||||
--max-model-len 65536 \
|
||||
--gpu-memory-utilization 0.9
|
||||
|
||||
nohup vllm serve ELVISIO/Qwen3-30B-A3B-Instruct-2507-AWQ \
|
||||
--served-model-name qwen3:30b \
|
||||
--max-model-len 64000 \
|
||||
--host 0.0.0.0 \
|
||||
--port 8000 \
|
||||
> vllm_serve.log 2>&1 &
|
||||
|
||||
```
|
||||
|
||||
|
||||
## Quantization
|
||||
|
||||
The model has undergone AWQ int4 quantization using the [ms-swift](https://github.com/modelscope/ms-swift) framework.
|
||||
|
||||
Quantization command:
|
||||
|
||||
```shell
|
||||
swift export \
|
||||
--model Qwen/Qwen3-30B-A3B-Instruct-2507 \
|
||||
--dataset 'swift/Chinese-Qwen3-235B-2507-Distill-data-110k-SFT' \
|
||||
--device_map cpu \
|
||||
--attn_impl flash_attn \
|
||||
--quant_n_samples 512 \
|
||||
--quant_batch_size -1 \
|
||||
--attn_impl flash_attn \
|
||||
--max_length 12000 \
|
||||
--quant_method awq \
|
||||
--quant_bits 4 \
|
||||
--output_dir Qwen3-30B-A3B-Instruct-2507-AWQ
|
||||
```
|
||||
|
||||
If you have fine-tuned the model and wish to quantize the fine-tuned version, you can refer to the following quantization scripts:
|
||||
|
||||
- Dense Model Quantization Script: [View Here](https://github.com/modelscope/ms-swift/blob/main/examples/export/quantize/awq.sh)
|
||||
- MoE Model Quantization Script: [View Here](https://github.com/modelscope/ms-swift/blob/main/examples/export/quantize/moe/awq.sh)
|
||||
|
||||
With these scripts, you can easily complete the quantization process for the model.
|
||||
|
||||
|
||||
# Qwen3-30B-A3B-Instruct-2507
|
||||
<a href="https://chat.qwen.ai/?model=Qwen3-30B-A3B-2507" target="_blank" style="margin: 2px;">
|
||||
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
||||
</a>
|
||||
|
||||
## Highlights
|
||||
|
||||
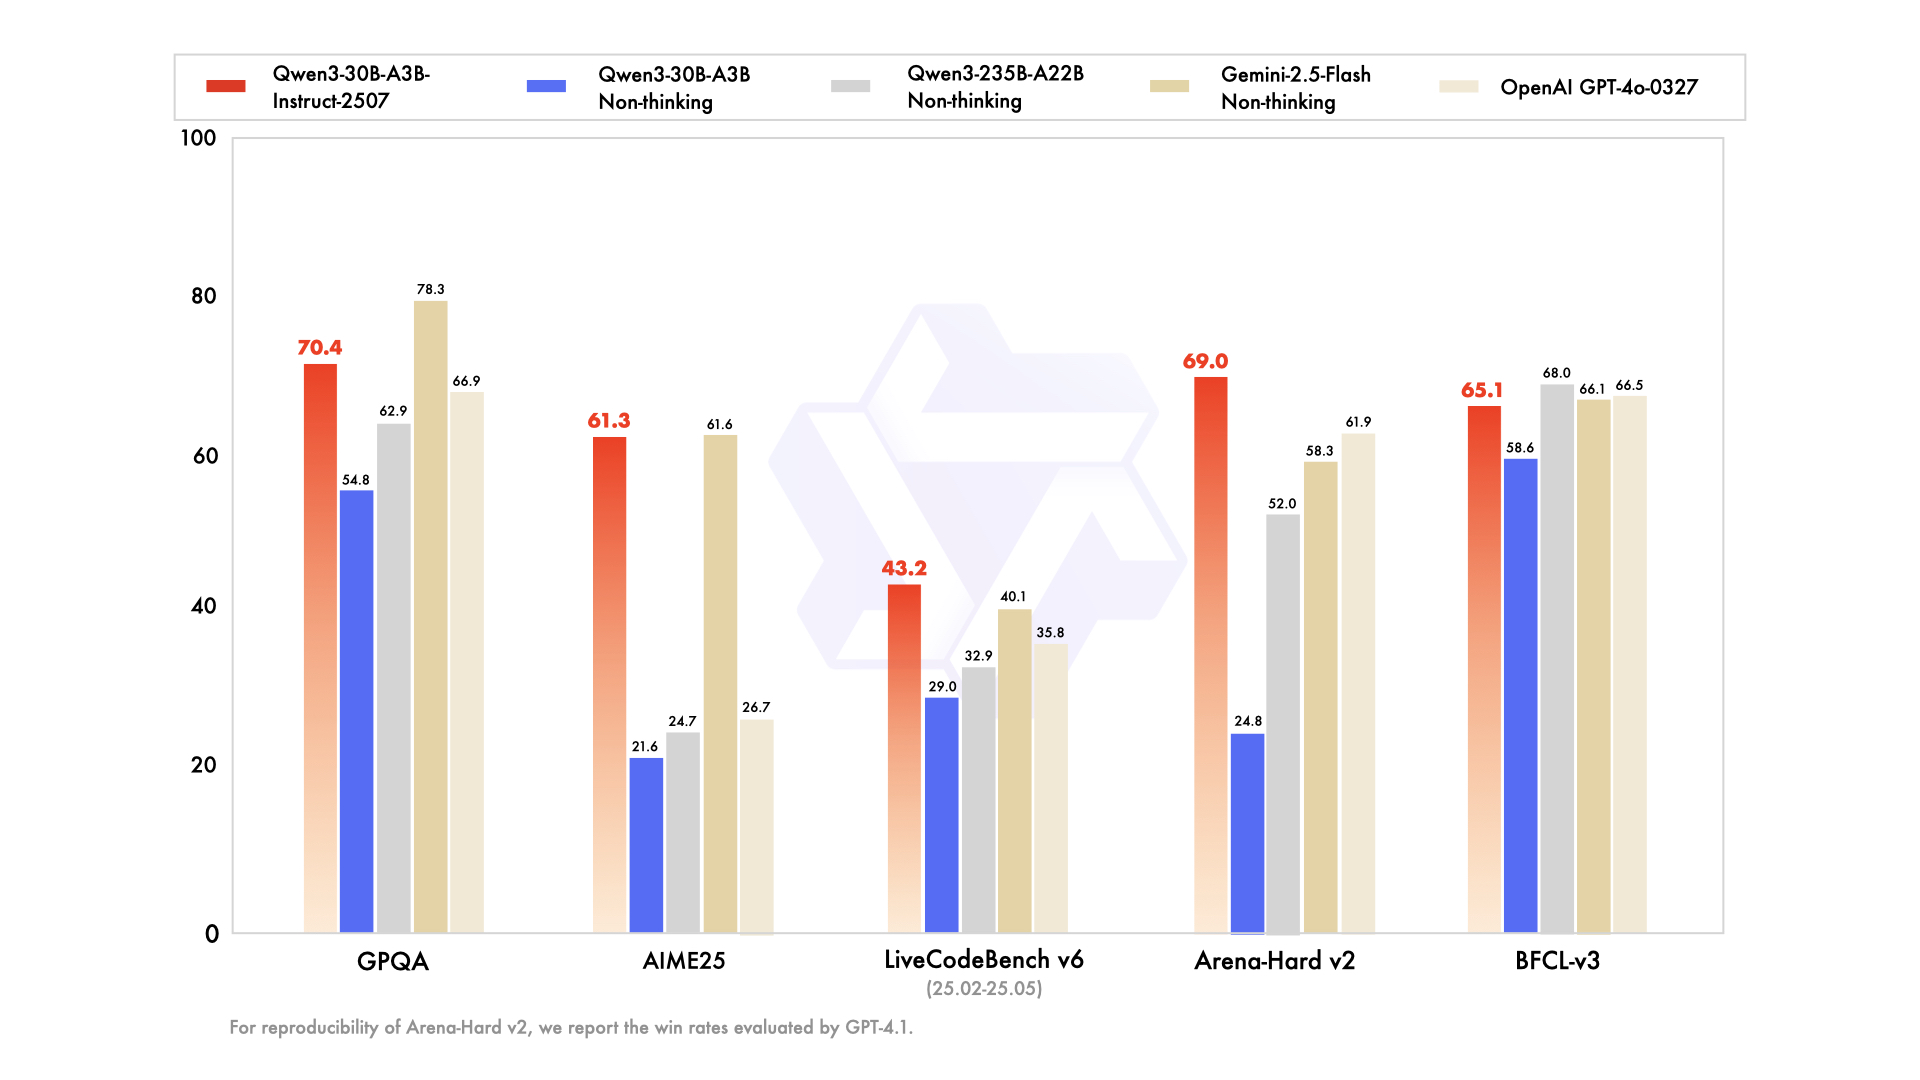
We introduce the updated version of the **Qwen3-30B-A3B non-thinking mode**, named **Qwen3-30B-A3B-Instruct-2507**, featuring the following key enhancements:
|
||||
|
||||
- **Significant improvements** in general capabilities, including **instruction following, logical reasoning, text comprehension, mathematics, science, coding and tool usage**.
|
||||
- **Substantial gains** in long-tail knowledge coverage across **multiple languages**.
|
||||
- **Markedly better alignment** with user preferences in **subjective and open-ended tasks**, enabling more helpful responses and higher-quality text generation.
|
||||
- **Enhanced capabilities** in **256K long-context understanding**.
|
||||
|
||||
|
||||
|
||||
## Model Overview
|
||||
|
||||
**Qwen3-30B-A3B-Instruct-2507** has the following features:
|
||||
- Type: Causal Language Models
|
||||
- Training Stage: Pretraining & Post-training
|
||||
- Number of Parameters: 30.5B in total and 3.3B activated
|
||||
- Number of Paramaters (Non-Embedding): 29.9B
|
||||
- Number of Layers: 48
|
||||
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
|
||||
- Number of Experts: 128
|
||||
- Number of Activated Experts: 8
|
||||
- Context Length: **262,144 natively**.
|
||||
|
||||
**NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
|
||||
|
||||
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
| | Deepseek-V3-0324 | GPT-4o-0327 | Gemini-2.5-Flash Non-Thinking | Qwen3-235B-A22B Non-Thinking | Qwen3-30B-A3B Non-Thinking | Qwen3-30B-A3B-Instruct-2507 |
|
||||
|--- | --- | --- | --- | --- | --- | --- |
|
||||
| **Knowledge** | | | | | | |
|
||||
| MMLU-Pro | **81.2** | 79.8 | 81.1 | 75.2 | 69.1 | 78.4 |
|
||||
| MMLU-Redux | 90.4 | **91.3** | 90.6 | 89.2 | 84.1 | 89.3 |
|
||||
| GPQA | 68.4 | 66.9 | **78.3** | 62.9 | 54.8 | 70.4 |
|
||||
| SuperGPQA | **57.3** | 51.0 | 54.6 | 48.2 | 42.2 | 53.4 |
|
||||
| **Reasoning** | | | | | | |
|
||||
| AIME25 | 46.6 | 26.7 | **61.6** | 24.7 | 21.6 | 61.3 |
|
||||
| HMMT25 | 27.5 | 7.9 | **45.8** | 10.0 | 12.0 | 43.0 |
|
||||
| ZebraLogic | 83.4 | 52.6 | 57.9 | 37.7 | 33.2 | **90.0** |
|
||||
| LiveBench 20241125 | 66.9 | 63.7 | **69.1** | 62.5 | 59.4 | 69.0 |
|
||||
| **Coding** | | | | | | |
|
||||
| LiveCodeBench v6 (25.02-25.05) | **45.2** | 35.8 | 40.1 | 32.9 | 29.0 | 43.2 |
|
||||
| MultiPL-E | 82.2 | 82.7 | 77.7 | 79.3 | 74.6 | **83.8** |
|
||||
| Aider-Polyglot | 55.1 | 45.3 | 44.0 | **59.6** | 24.4 | 35.6 |
|
||||
| **Alignment** | | | | | | |
|
||||
| IFEval | 82.3 | 83.9 | 84.3 | 83.2 | 83.7 | **84.7** |
|
||||
| Arena-Hard v2* | 45.6 | 61.9 | 58.3 | 52.0 | 24.8 | **69.0** |
|
||||
| Creative Writing v3 | 81.6 | 84.9 | 84.6 | 80.4 | 68.1 | **86.0** |
|
||||
| WritingBench | 74.5 | 75.5 | 80.5 | 77.0 | 72.2 | **85.5** |
|
||||
| **Agent** | | | | | | |
|
||||
| BFCL-v3 | 64.7 | 66.5 | 66.1 | **68.0** | 58.6 | 65.1 |
|
||||
| TAU1-Retail | 49.6 | 60.3# | **65.2** | 65.2 | 38.3 | 59.1 |
|
||||
| TAU1-Airline | 32.0 | 42.8# | **48.0** | 32.0 | 18.0 | 40.0 |
|
||||
| TAU2-Retail | **71.1** | 66.7# | 64.3 | 64.9 | 31.6 | 57.0 |
|
||||
| TAU2-Airline | 36.0 | 42.0# | **42.5** | 36.0 | 18.0 | 38.0 |
|
||||
| TAU2-Telecom | **34.0** | 29.8# | 16.9 | 24.6 | 18.4 | 12.3 |
|
||||
| **Multilingualism** | | | | | | |
|
||||
| MultiIF | 66.5 | 70.4 | 69.4 | 70.2 | **70.8** | 67.9 |
|
||||
| MMLU-ProX | 75.8 | 76.2 | **78.3** | 73.2 | 65.1 | 72.0 |
|
||||
| INCLUDE | 80.1 | 82.1 | **83.8** | 75.6 | 67.8 | 71.9 |
|
||||
| PolyMATH | 32.2 | 25.5 | 41.9 | 27.0 | 23.3 | **43.1** |
|
||||
|
||||
*: For reproducibility, we report the win rates evaluated by GPT-4.1.
|
||||
|
||||
\#: Results were generated using GPT-4o-20241120, as access to the native function calling API of GPT-4o-0327 was unavailable.
|
||||
|
||||
|
||||
## Quickstart
|
||||
|
||||
The code of Qwen3-MoE has been in the latest Hugging Face `transformers` and we advise you to use the latest version of `transformers`.
|
||||
|
||||
With `transformers<4.51.0`, you will encounter the following error:
|
||||
```
|
||||
KeyError: 'qwen3_moe'
|
||||
```
|
||||
|
||||
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/Qwen3-30B-A3B-Instruct-2507"
|
||||
|
||||
# load the tokenizer and the model
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_name,
|
||||
torch_dtype="auto",
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
# prepare the model input
|
||||
prompt = "Give me a short introduction to large language model."
|
||||
messages = [
|
||||
{"role": "user", "content": prompt}
|
||||
]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
)
|
||||
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
||||
|
||||
# conduct text completion
|
||||
generated_ids = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=16384
|
||||
)
|
||||
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
||||
|
||||
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
print("content:", content)
|
||||
```
|
||||
|
||||
For deployment, you can use `sglang>=0.4.6.post1` or `vllm>=0.8.5` or to create an OpenAI-compatible API endpoint:
|
||||
- SGLang:
|
||||
```shell
|
||||
python -m sglang.launch_server --model-path Qwen/Qwen3-30B-A3B-Instruct-2507 --context-length 262144
|
||||
```
|
||||
- vLLM:
|
||||
```shell
|
||||
vllm serve Qwen/Qwen3-30B-A3B-Instruct-2507 --max-model-len 262144
|
||||
```
|
||||
|
||||
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
|
||||
|
||||
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
||||
|
||||
## Agentic Use
|
||||
|
||||
Qwen3 excels in tool calling capabilities. We recommend using [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent) to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
|
||||
|
||||
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
|
||||
```python
|
||||
from qwen_agent.agents import Assistant
|
||||
|
||||
# Define LLM
|
||||
llm_cfg = {
|
||||
'model': 'Qwen3-30B-A3B-Instruct-2507',
|
||||
|
||||
# Use a custom endpoint compatible with OpenAI API:
|
||||
'model_server': 'http://localhost:8000/v1', # api_base
|
||||
'api_key': 'EMPTY',
|
||||
}
|
||||
|
||||
# Define Tools
|
||||
tools = [
|
||||
{'mcpServers': { # You can specify the MCP configuration file
|
||||
'time': {
|
||||
'command': 'uvx',
|
||||
'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
|
||||
},
|
||||
"fetch": {
|
||||
"command": "uvx",
|
||||
"args": ["mcp-server-fetch"]
|
||||
}
|
||||
}
|
||||
},
|
||||
'code_interpreter', # Built-in tools
|
||||
]
|
||||
|
||||
# Define Agent
|
||||
bot = Assistant(llm=llm_cfg, function_list=tools)
|
||||
|
||||
# Streaming generation
|
||||
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
|
||||
for responses in bot.run(messages=messages):
|
||||
pass
|
||||
print(responses)
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
To achieve optimal performance, we recommend the following settings:
|
||||
|
||||
1. **Sampling Parameters**:
|
||||
- We suggest using `Temperature=0.7`, `TopP=0.8`, `TopK=20`, and `MinP=0`.
|
||||
- For supported frameworks, you can adjust the `presence_penalty` parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
|
||||
|
||||
2. **Adequate Output Length**: We recommend using an output length of 16,384 tokens for most queries, which is adequate for instruct models.
|
||||
|
||||
3. **Standardize Output Format**: We recommend using prompts to standardize model outputs when benchmarking.
|
||||
- **Math Problems**: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
|
||||
- **Multiple-Choice Questions**: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the `answer` field with only the choice letter, e.g., `"answer": "C"`."
|
||||
|
||||
### Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite.
|
||||
|
||||
```
|
||||
@misc{qwen3technicalreport,
|
||||
title={Qwen3 Technical Report},
|
||||
author={Qwen Team},
|
||||
year={2025},
|
||||
eprint={2505.09388},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2505.09388},
|
||||
}
|
||||
```
|
||||
28
added_tokens.json
Normal file
28
added_tokens.json
Normal file
@@ -0,0 +1,28 @@
|
||||
{
|
||||
"</think>": 151668,
|
||||
"</tool_call>": 151658,
|
||||
"</tool_response>": 151666,
|
||||
"<think>": 151667,
|
||||
"<tool_call>": 151657,
|
||||
"<tool_response>": 151665,
|
||||
"<|box_end|>": 151649,
|
||||
"<|box_start|>": 151648,
|
||||
"<|endoftext|>": 151643,
|
||||
"<|file_sep|>": 151664,
|
||||
"<|fim_middle|>": 151660,
|
||||
"<|fim_pad|>": 151662,
|
||||
"<|fim_prefix|>": 151659,
|
||||
"<|fim_suffix|>": 151661,
|
||||
"<|im_end|>": 151645,
|
||||
"<|im_start|>": 151644,
|
||||
"<|image_pad|>": 151655,
|
||||
"<|object_ref_end|>": 151647,
|
||||
"<|object_ref_start|>": 151646,
|
||||
"<|quad_end|>": 151651,
|
||||
"<|quad_start|>": 151650,
|
||||
"<|repo_name|>": 151663,
|
||||
"<|video_pad|>": 151656,
|
||||
"<|vision_end|>": 151653,
|
||||
"<|vision_pad|>": 151654,
|
||||
"<|vision_start|>": 151652
|
||||
}
|
||||
86
chat_template.jinja
Normal file
86
chat_template.jinja
Normal file
@@ -0,0 +1,86 @@
|
||||
{%- if tools %}
|
||||
{{- '<|im_start|>system\n' }}
|
||||
{%- if messages[0].role == 'system' %}
|
||||
{{- messages[0].content + '\n\n' }}
|
||||
{%- endif %}
|
||||
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
||||
{%- for tool in tools %}
|
||||
{{- "\n" }}
|
||||
{{- tool | tojson }}
|
||||
{%- endfor %}
|
||||
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
||||
{%- else %}
|
||||
{%- if messages[0].role == 'system' %}
|
||||
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
||||
{%- for message in messages[::-1] %}
|
||||
{%- set index = (messages|length - 1) - loop.index0 %}
|
||||
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
||||
{%- set ns.multi_step_tool = false %}
|
||||
{%- set ns.last_query_index = index %}
|
||||
{%- endif %}
|
||||
{%- endfor %}
|
||||
{%- for message in messages %}
|
||||
{%- if message.content is string %}
|
||||
{%- set content = message.content %}
|
||||
{%- else %}
|
||||
{%- set content = '' %}
|
||||
{%- endif %}
|
||||
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
||||
{%- elif message.role == "assistant" %}
|
||||
{%- set reasoning_content = '' %}
|
||||
{%- if message.reasoning_content is string %}
|
||||
{%- set reasoning_content = message.reasoning_content %}
|
||||
{%- else %}
|
||||
{%- if '</think>' in content %}
|
||||
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
||||
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- if loop.index0 > ns.last_query_index %}
|
||||
{%- if loop.last or (not loop.last and reasoning_content) %}
|
||||
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip('\n') + '\n</think>\n\n' + content.lstrip('\n') }}
|
||||
{%- else %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||
{%- endif %}
|
||||
{%- else %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||
{%- endif %}
|
||||
{%- if message.tool_calls %}
|
||||
{%- for tool_call in message.tool_calls %}
|
||||
{%- if (loop.first and content) or (not loop.first) %}
|
||||
{{- '\n' }}
|
||||
{%- endif %}
|
||||
{%- if tool_call.function %}
|
||||
{%- set tool_call = tool_call.function %}
|
||||
{%- endif %}
|
||||
{{- '<tool_call>\n{"name": "' }}
|
||||
{{- tool_call.name }}
|
||||
{{- '", "arguments": ' }}
|
||||
{%- if tool_call.arguments is string %}
|
||||
{{- tool_call.arguments }}
|
||||
{%- else %}
|
||||
{{- tool_call.arguments | tojson }}
|
||||
{%- endif %}
|
||||
{{- '}\n</tool_call>' }}
|
||||
{%- endfor %}
|
||||
{%- endif %}
|
||||
{{- '<|im_end|>\n' }}
|
||||
{%- elif message.role == "tool" %}
|
||||
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
||||
{{- '<|im_start|>user' }}
|
||||
{%- endif %}
|
||||
{{- '\n<tool_response>\n' }}
|
||||
{{- content }}
|
||||
{{- '\n</tool_response>' }}
|
||||
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
||||
{{- '<|im_end|>\n' }}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- endfor %}
|
||||
{%- if add_generation_prompt %}
|
||||
{{- '<|im_start|>assistant\n' }}
|
||||
{%- endif %}
|
||||
50
config.json
Normal file
50
config.json
Normal file
@@ -0,0 +1,50 @@
|
||||
{
|
||||
"architectures": [
|
||||
"Qwen3MoeForCausalLM"
|
||||
],
|
||||
"attention_bias": false,
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 151643,
|
||||
"decoder_sparse_step": 1,
|
||||
"eos_token_id": 151645,
|
||||
"head_dim": 128,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 2048,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 6144,
|
||||
"max_position_embeddings": 262144,
|
||||
"max_window_layers": 48,
|
||||
"mlp_only_layers": [],
|
||||
"model_type": "qwen3_moe",
|
||||
"moe_intermediate_size": 768,
|
||||
"norm_topk_prob": true,
|
||||
"num_attention_heads": 32,
|
||||
"num_experts": 128,
|
||||
"num_experts_per_tok": 8,
|
||||
"num_hidden_layers": 48,
|
||||
"num_key_value_heads": 4,
|
||||
"output_router_logits": false,
|
||||
"pad_token_id": 151643,
|
||||
"quantization_config": {
|
||||
"bits": 4,
|
||||
"group_size": 128,
|
||||
"modules_to_not_convert": [
|
||||
"mlp.gate",
|
||||
"lm_head"
|
||||
],
|
||||
"quant_method": "awq",
|
||||
"version": "gemm",
|
||||
"zero_point": true
|
||||
},
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_scaling": null,
|
||||
"rope_theta": 10000000,
|
||||
"router_aux_loss_coef": 0.001,
|
||||
"sliding_window": null,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.55.0.dev0",
|
||||
"use_cache": false,
|
||||
"use_sliding_window": false,
|
||||
"vocab_size": 151936
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework":"Pytorch","task":"text-generation"}
|
||||
13
generation_config.json
Normal file
13
generation_config.json
Normal file
@@ -0,0 +1,13 @@
|
||||
{
|
||||
"bos_token_id": 151643,
|
||||
"do_sample": true,
|
||||
"eos_token_id": [
|
||||
151645,
|
||||
151643
|
||||
],
|
||||
"pad_token_id": 151643,
|
||||
"temperature": 0.7,
|
||||
"top_k": 20,
|
||||
"top_p": 0.8,
|
||||
"transformers_version": "4.55.0.dev0"
|
||||
}
|
||||
151388
merges.txt
Normal file
151388
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
3
model-00001-of-00004.safetensors
Normal file
3
model-00001-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dded37cd3936271f93655917a55634553c41679a467d97ce2004cdfff20a718e
|
||||
size 5001815024
|
||||
3
model-00002-of-00004.safetensors
Normal file
3
model-00002-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:28c8065b1f3fe82bceae32aece99b404ef4f06e9be7d93e1a5028b7dd330c591
|
||||
size 5002166720
|
||||
3
model-00003-of-00004.safetensors
Normal file
3
model-00003-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:53ef6b077e5bc0bd3cd4d799ac839a79a2688b3242384c129e781934cd6e9462
|
||||
size 5001879600
|
||||
3
model-00004-of-00004.safetensors
Normal file
3
model-00004-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:df81a01f3d039cdc0b7d212608590884404b85825438078fce2e8cf7d68c6ecf
|
||||
size 1803606480
|
||||
56122
model.safetensors.index.json
Normal file
56122
model.safetensors.index.json
Normal file
File diff suppressed because it is too large
Load Diff
31
special_tokens_map.json
Normal file
31
special_tokens_map.json
Normal file
@@ -0,0 +1,31 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<|im_start|>",
|
||||
"<|im_end|>",
|
||||
"<|object_ref_start|>",
|
||||
"<|object_ref_end|>",
|
||||
"<|box_start|>",
|
||||
"<|box_end|>",
|
||||
"<|quad_start|>",
|
||||
"<|quad_end|>",
|
||||
"<|vision_start|>",
|
||||
"<|vision_end|>",
|
||||
"<|vision_pad|>",
|
||||
"<|image_pad|>",
|
||||
"<|video_pad|>"
|
||||
],
|
||||
"eos_token": {
|
||||
"content": "<|im_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
BIN
tokenizer.json
(Stored with Git LFS)
Normal file
BIN
tokenizer.json
(Stored with Git LFS)
Normal file
Binary file not shown.
239
tokenizer_config.json
Normal file
239
tokenizer_config.json
Normal file
@@ -0,0 +1,239 @@
|
||||
{
|
||||
"add_bos_token": false,
|
||||
"add_prefix_space": false,
|
||||
"added_tokens_decoder": {
|
||||
"151643": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151644": {
|
||||
"content": "<|im_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151645": {
|
||||
"content": "<|im_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151646": {
|
||||
"content": "<|object_ref_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151647": {
|
||||
"content": "<|object_ref_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151648": {
|
||||
"content": "<|box_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151649": {
|
||||
"content": "<|box_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151650": {
|
||||
"content": "<|quad_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151651": {
|
||||
"content": "<|quad_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151652": {
|
||||
"content": "<|vision_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151653": {
|
||||
"content": "<|vision_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151654": {
|
||||
"content": "<|vision_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151655": {
|
||||
"content": "<|image_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151656": {
|
||||
"content": "<|video_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"151657": {
|
||||
"content": "<tool_call>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151658": {
|
||||
"content": "</tool_call>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151659": {
|
||||
"content": "<|fim_prefix|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151660": {
|
||||
"content": "<|fim_middle|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151661": {
|
||||
"content": "<|fim_suffix|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151662": {
|
||||
"content": "<|fim_pad|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151663": {
|
||||
"content": "<|repo_name|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151664": {
|
||||
"content": "<|file_sep|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151665": {
|
||||
"content": "<tool_response>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151666": {
|
||||
"content": "</tool_response>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151667": {
|
||||
"content": "<think>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
},
|
||||
"151668": {
|
||||
"content": "</think>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": false
|
||||
}
|
||||
},
|
||||
"additional_special_tokens": [
|
||||
"<|im_start|>",
|
||||
"<|im_end|>",
|
||||
"<|object_ref_start|>",
|
||||
"<|object_ref_end|>",
|
||||
"<|box_start|>",
|
||||
"<|box_end|>",
|
||||
"<|quad_start|>",
|
||||
"<|quad_end|>",
|
||||
"<|vision_start|>",
|
||||
"<|vision_end|>",
|
||||
"<|vision_pad|>",
|
||||
"<|image_pad|>",
|
||||
"<|video_pad|>"
|
||||
],
|
||||
"bos_token": null,
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "<|im_end|>",
|
||||
"errors": "replace",
|
||||
"extra_special_tokens": {},
|
||||
"model_max_length": 262144,
|
||||
"pad_token": "<|endoftext|>",
|
||||
"split_special_tokens": false,
|
||||
"tokenizer_class": "Qwen2Tokenizer",
|
||||
"unk_token": null
|
||||
}
|
||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user