
77 lines
3.2 KiB
Markdown
77 lines
3.2 KiB
Markdown
---
|
|
frameworks:
|
|
- Pytorch
|
|
license: Apache License 2.0
|
|
tasks:
|
|
- text-generation
|
|
datasets:
|
|
train:
|
|
- Data-Juicer/redpajama-wiki-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-arxiv-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-c4-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-book-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-cc-2019-30-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-cc-2020-05-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-cc-2021-04-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-cc-2022-05-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-cc-2023-06-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-pile-stackexchange-refined-by-data-juicer
|
|
- Data-Juicer/redpajama-stack-code-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-nih-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-europarl-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-philpaper-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-pubmed-abstracts-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-pubmed-central-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-freelaw-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-hackernews-refined-by-data-juicer
|
|
- Data-Juicer/the-pile-uspto-refined-by-data-juicer
|
|
tags:
|
|
- data-juicer
|
|
- arxiv:2309.02033
|
|
---
|
|
## News
|
|
Our first data-centric LLM competition begins! Please visit the competition's official websites, **FT-Data Ranker** ([1B Track](https://tianchi.aliyun.com/competition/entrance/532157), [7B Track](https://tianchi.aliyun.com/competition/entrance/532158)), for more information.
|
|
## Introduction
|
|
This is a reference LLM from [Data-Juicer](https://github.com/alibaba/data-juicer).
|
|
|
|
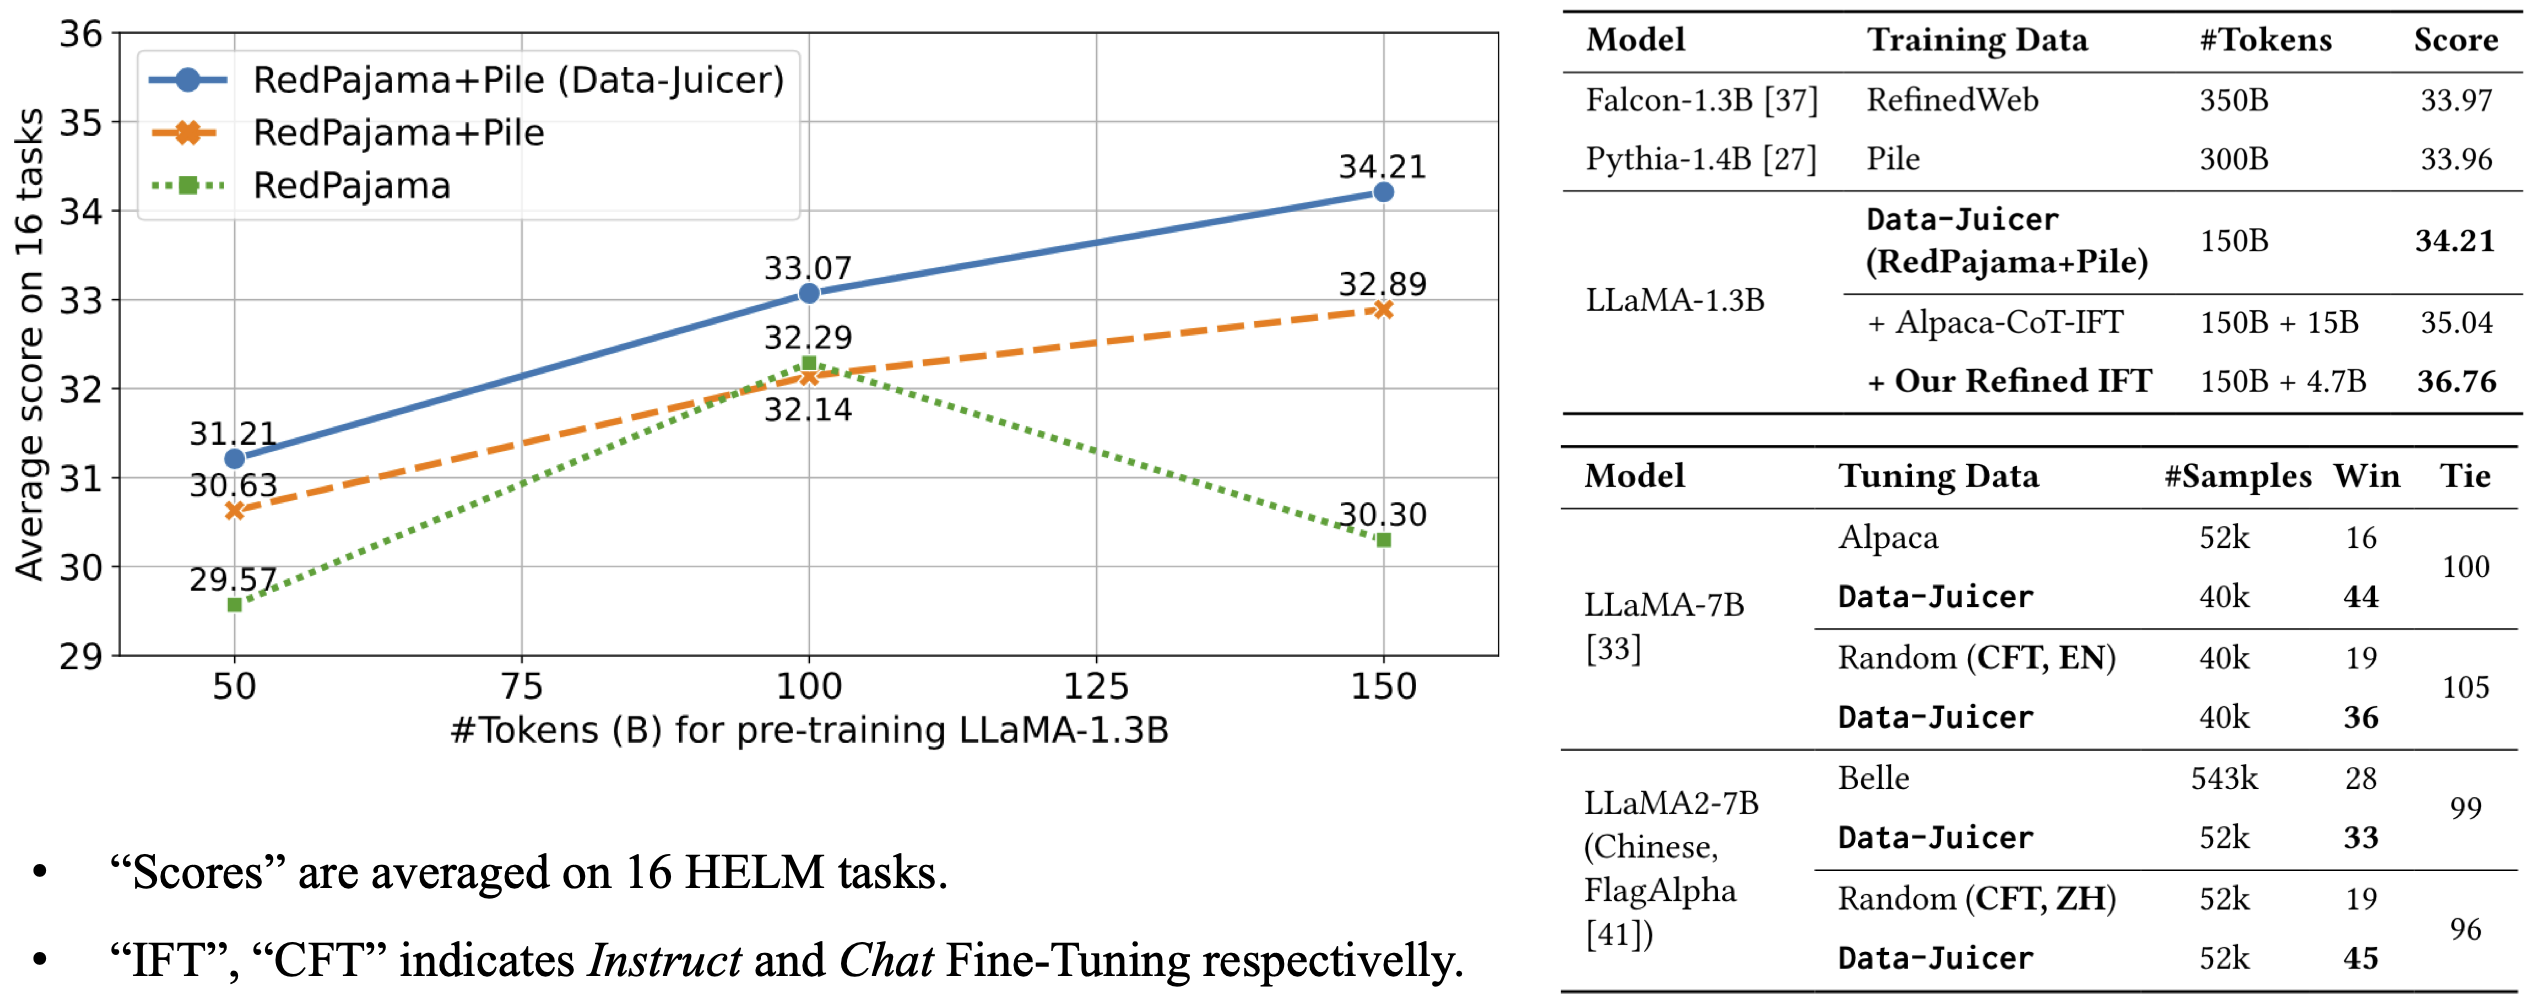
The model is pre-trained on 150B tokens of Data-Juicer's refined RedPajama and Pile, and 4.7B tokens of Data-Juicer refined instruct data.
|
|
It achieves an average score of 36.76 over 16 HELM tasks, improved the OpenLLaMA-DJ-150B by 2.55 point.
|
|
|
|
For more details, please refer to our [paper](https://arxiv.org/abs/2309.02033).
|
|
|
|
|
|
|
|
## 使用
|
|
```python
|
|
|
|
from modelscope import (
|
|
AutoModelForCausalLM, AutoTokenizer, GenerationConfig, snapshot_download
|
|
)
|
|
model_dir = 'Data-Juicer/LLaMA-1B-dj-refine-150B-instruct-4.7B'
|
|
|
|
tokenizer = AutoTokenizer.from_pretrained(model_dir)
|
|
model = AutoModelForCausalLM.from_pretrained(model_dir).eval()
|
|
|
|
inputs = tokenizer('How are you?', return_tensors='pt').to(model.device)
|
|
response = model.generate(inputs.input_ids, max_length=128)
|
|
print(tokenizer.decode(response.cpu()[0], skip_special_tokens=True))
|
|
```
|
|
|
|
## 参考
|
|
If you find our work useful for your research or development, please kindly cite the following [paper](https://arxiv.org/abs/2309.02033).
|
|
```
|
|
@misc{chen2023datajuicer,
|
|
title={Data-Juicer: A One-Stop Data Processing System for Large Language Models},
|
|
author={Daoyuan Chen and Yilun Huang and Zhijian Ma and Hesen Chen and Xuchen Pan and Ce Ge and Dawei Gao and Yuexiang Xie and Zhaoyang Liu and Jinyang Gao and Yaliang Li and Bolin Ding and Jingren Zhou},
|
|
year={2023},
|
|
eprint={2309.02033},
|
|
archivePrefix={arXiv},
|
|
primaryClass={cs.LG}
|
|
}
|
|
```
|
|
|
|
#### Clone with HTTP
|
|
```bash
|
|
git clone https://www.modelscope.cn/Data-Juicer/LLaMA-1B-dj-refine-150B-instruct-4.7B.git
|
|
```
|