初始化项目,由ModelHub XC社区提供模型
Model: Data-Juicer/LLaMA-1B-dj-refine-100B
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
pytorch_model.bin filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.model filter=lfs diff=lfs merge=lfs -text
|
||||
77
README.md
Normal file
77
README.md
Normal file
@@ -0,0 +1,77 @@
|
||||
---
|
||||
frameworks:
|
||||
- Pytorch
|
||||
license: Apache License 2.0
|
||||
tasks:
|
||||
- text-generation
|
||||
datasets:
|
||||
train:
|
||||
- Data-Juicer/redpajama-wiki-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-arxiv-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-c4-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-book-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-cc-2019-30-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-cc-2020-05-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-cc-2021-04-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-cc-2022-05-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-cc-2023-06-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-pile-stackexchange-refined-by-data-juicer
|
||||
- Data-Juicer/redpajama-stack-code-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-nih-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-europarl-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-philpaper-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-pubmed-abstracts-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-pubmed-central-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-freelaw-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-hackernews-refined-by-data-juicer
|
||||
- Data-Juicer/the-pile-uspto-refined-by-data-juicer
|
||||
tags:
|
||||
- data-juicer
|
||||
- arxiv:2309.02033
|
||||
---
|
||||
## News
|
||||
Our first data-centric LLM competition begins! Please visit the competition's official websites, **FT-Data Ranker** ([1B Track](https://tianchi.aliyun.com/competition/entrance/532157), [7B Track](https://tianchi.aliyun.com/competition/entrance/532158)), for more information.
|
||||
## Introduction
|
||||
This is a reference LLM from [Data-Juicer](https://github.com/alibaba/data-juicer).
|
||||
|
||||
The model architecture is LLaMA-1.3B and we adopt the [OpenLLaMA](https://github.com/openlm-research/open_llama) implementation.
|
||||
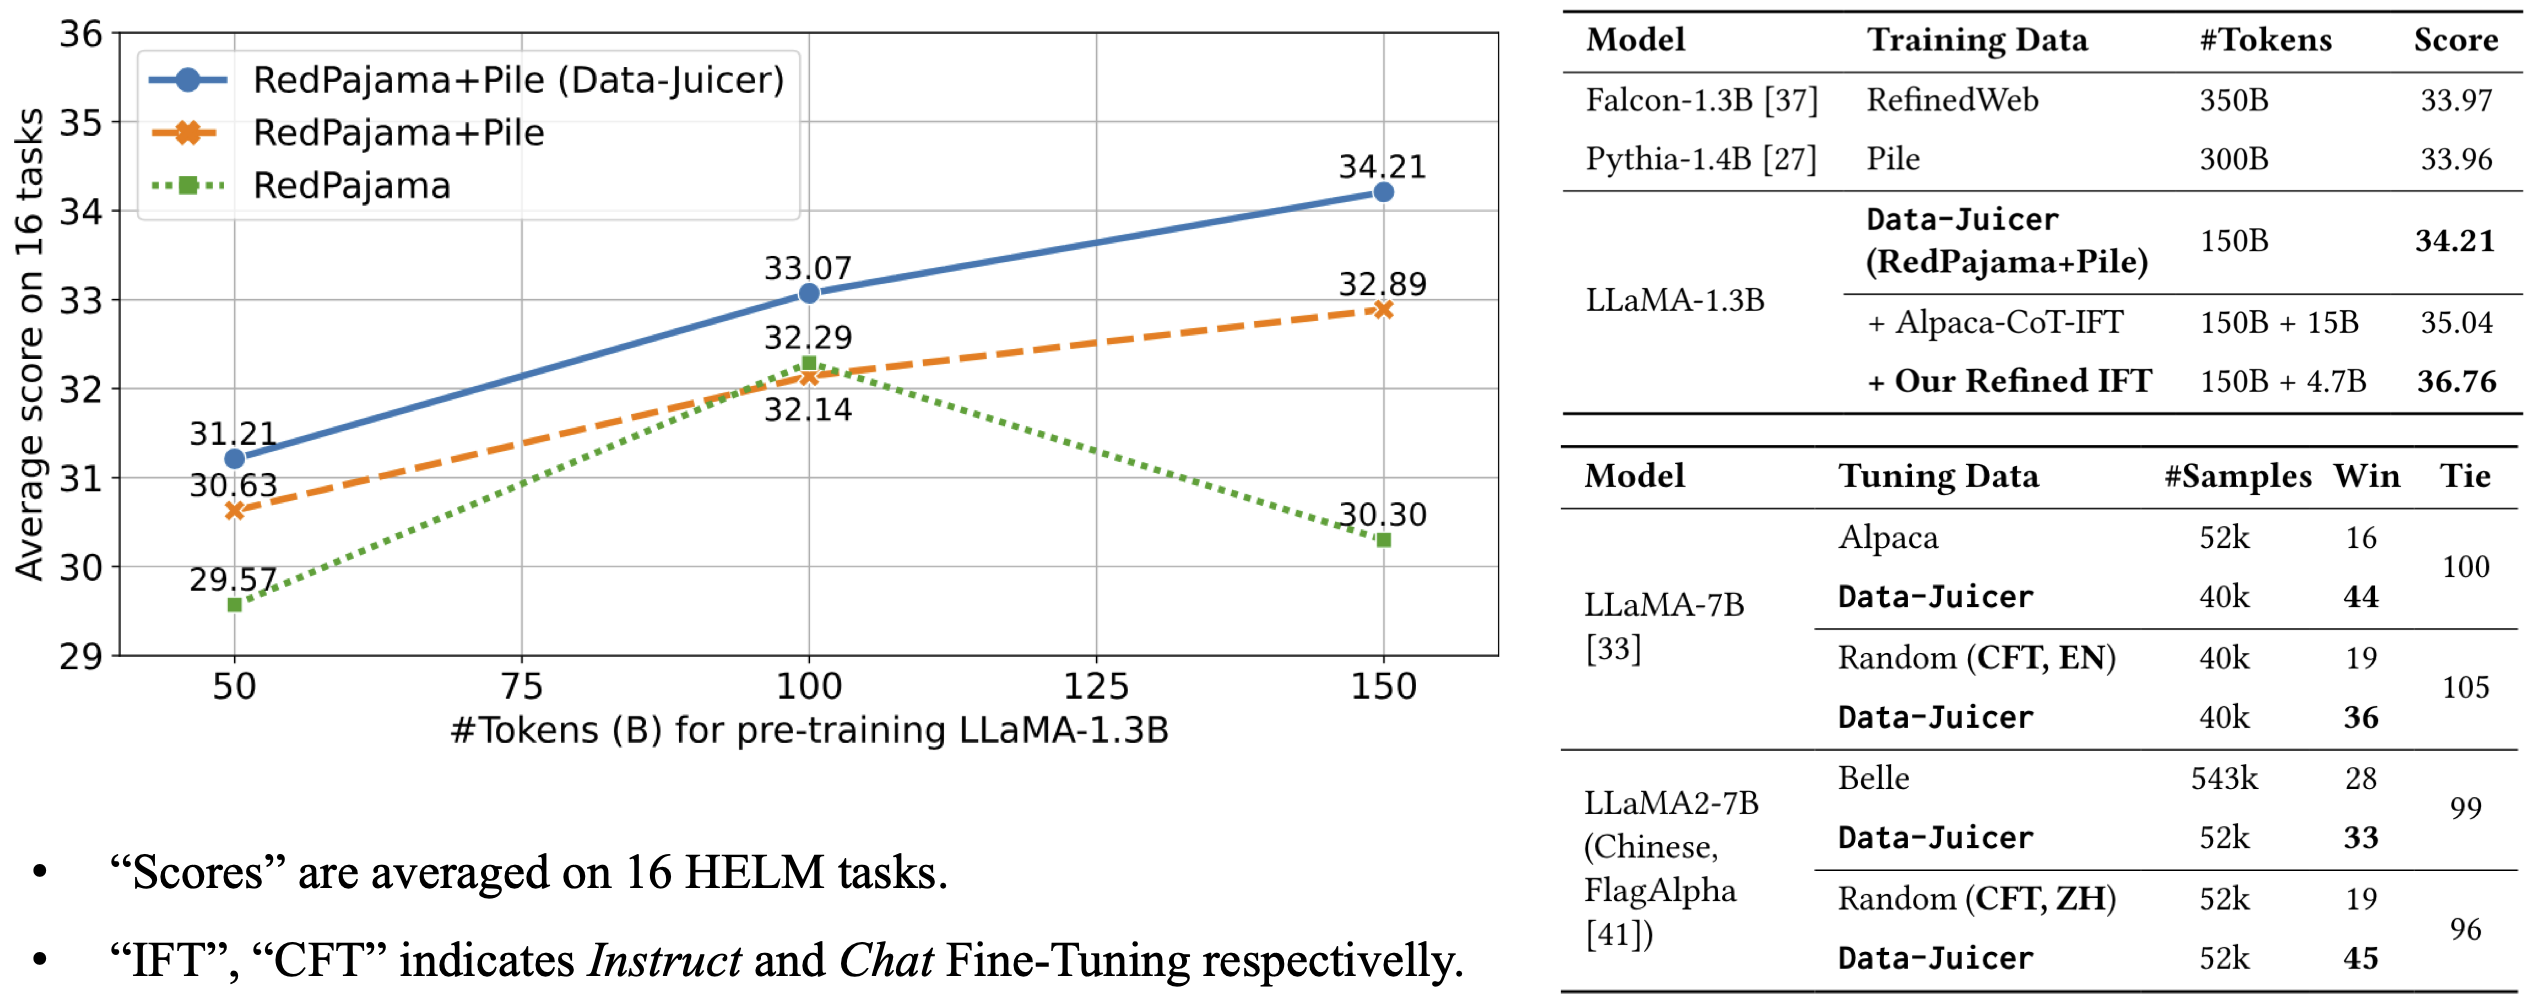
The model is pre-trained on 100B tokens of Data-Juicer's refined RedPajama and Pile.
|
||||
It achieves an average score of 33.07 over 16 HELM tasks, beating LLMs trained on original RedPajama and Pile datasets.
|
||||
|
||||
For more details, please refer to our [paper](https://arxiv.org/abs/2309.02033).
|
||||
|
||||
|
||||
|
||||
## 使用
|
||||
```python
|
||||
|
||||
from modelscope import (
|
||||
AutoModelForCausalLM, AutoTokenizer, GenerationConfig, snapshot_download
|
||||
)
|
||||
model_dir = 'Data-Juicer/LLaMA-1B-dj-refine-100B'
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_dir)
|
||||
model = AutoModelForCausalLM.from_pretrained(model_dir).eval()
|
||||
|
||||
inputs = tokenizer('How are you?', return_tensors='pt').to(model.device)
|
||||
response = model.generate(inputs.input_ids, max_length=128)
|
||||
print(tokenizer.decode(response.cpu()[0], skip_special_tokens=True))
|
||||
```
|
||||
|
||||
## 参考
|
||||
If you find our work useful for your research or development, please kindly cite the following [paper](https://arxiv.org/abs/2309.02033).
|
||||
```
|
||||
@misc{chen2023datajuicer,
|
||||
title={Data-Juicer: A One-Stop Data Processing System for Large Language Models},
|
||||
author={Daoyuan Chen and Yilun Huang and Zhijian Ma and Hesen Chen and Xuchen Pan and Ce Ge and Dawei Gao and Yuexiang Xie and Zhaoyang Liu and Jinyang Gao and Yaliang Li and Bolin Ding and Jingren Zhou},
|
||||
year={2023},
|
||||
eprint={2309.02033},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.LG}
|
||||
}
|
||||
```
|
||||
|
||||
#### Clone with HTTP
|
||||
```bash
|
||||
git clone https://www.modelscope.cn/Data-Juicer/LLaMA-1B-dj-refine-100B.git
|
||||
```
|
||||
7
added_tokens.json
Normal file
7
added_tokens.json
Normal file
@@ -0,0 +1,7 @@
|
||||
{
|
||||
"<CLS>": 32000,
|
||||
"<EOD>": 32002,
|
||||
"<MASK>": 32003,
|
||||
"<PAD>": 32004,
|
||||
"<SEP>": 32001
|
||||
}
|
||||
26
config.json
Normal file
26
config.json
Normal file
@@ -0,0 +1,26 @@
|
||||
{
|
||||
"architectures": [
|
||||
"LLaMAForCausalLM"
|
||||
],
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 2048,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 5504,
|
||||
"max_position_embeddings": 2048,
|
||||
"max_sequence_length": 2048,
|
||||
"model_type": "llama",
|
||||
"num_attention_heads": 16,
|
||||
"num_hidden_layers": 24,
|
||||
"num_key_value_heads": 16,
|
||||
"pad_token_id": 32004,
|
||||
"pretraining_tp": 1,
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_scaling": null,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.31.0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 32128
|
||||
}
|
||||
3
pytorch_model.bin
Normal file
3
pytorch_model.bin
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b0b70c83c36df9332fd9001395d864c2722222c9e9fa32fa765e8e6d8dfd533d
|
||||
size 2560383189
|
||||
18
special_tokens_map.json
Normal file
18
special_tokens_map.json
Normal file
@@ -0,0 +1,18 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<EOD>"
|
||||
],
|
||||
"bos_token": "<s>",
|
||||
"cls_token": "<CLS>",
|
||||
"eos_token": "</s>",
|
||||
"mask_token": "<MASK>",
|
||||
"pad_token": "<PAD>",
|
||||
"sep_token": "<SEP>",
|
||||
"unk_token": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
34
tokenizer_config.json
Normal file
34
tokenizer_config.json
Normal file
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"add_bos_token": true,
|
||||
"add_eos_token": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"legacy": true,
|
||||
"model_max_length": 2048,
|
||||
"pad_token": null,
|
||||
"sp_model_kwargs": {},
|
||||
"tokenizer_class": "LlamaTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
Reference in New Issue
Block a user