
152 lines
6.4 KiB
Markdown
152 lines
6.4 KiB
Markdown
---
|
|
datasets:
|
|
- BatsResearch/ctga-v1
|
|
language:
|
|
- en
|
|
library_name: transformers
|
|
pipeline_tag: text2text-generation
|
|
tags:
|
|
- data generation
|
|
license: apache-2.0
|
|
---
|
|
|
|
# Model Card for bonito
|
|
|
|
<!-- Provide a quick summary of what the model is/does. -->
|
|
|
|
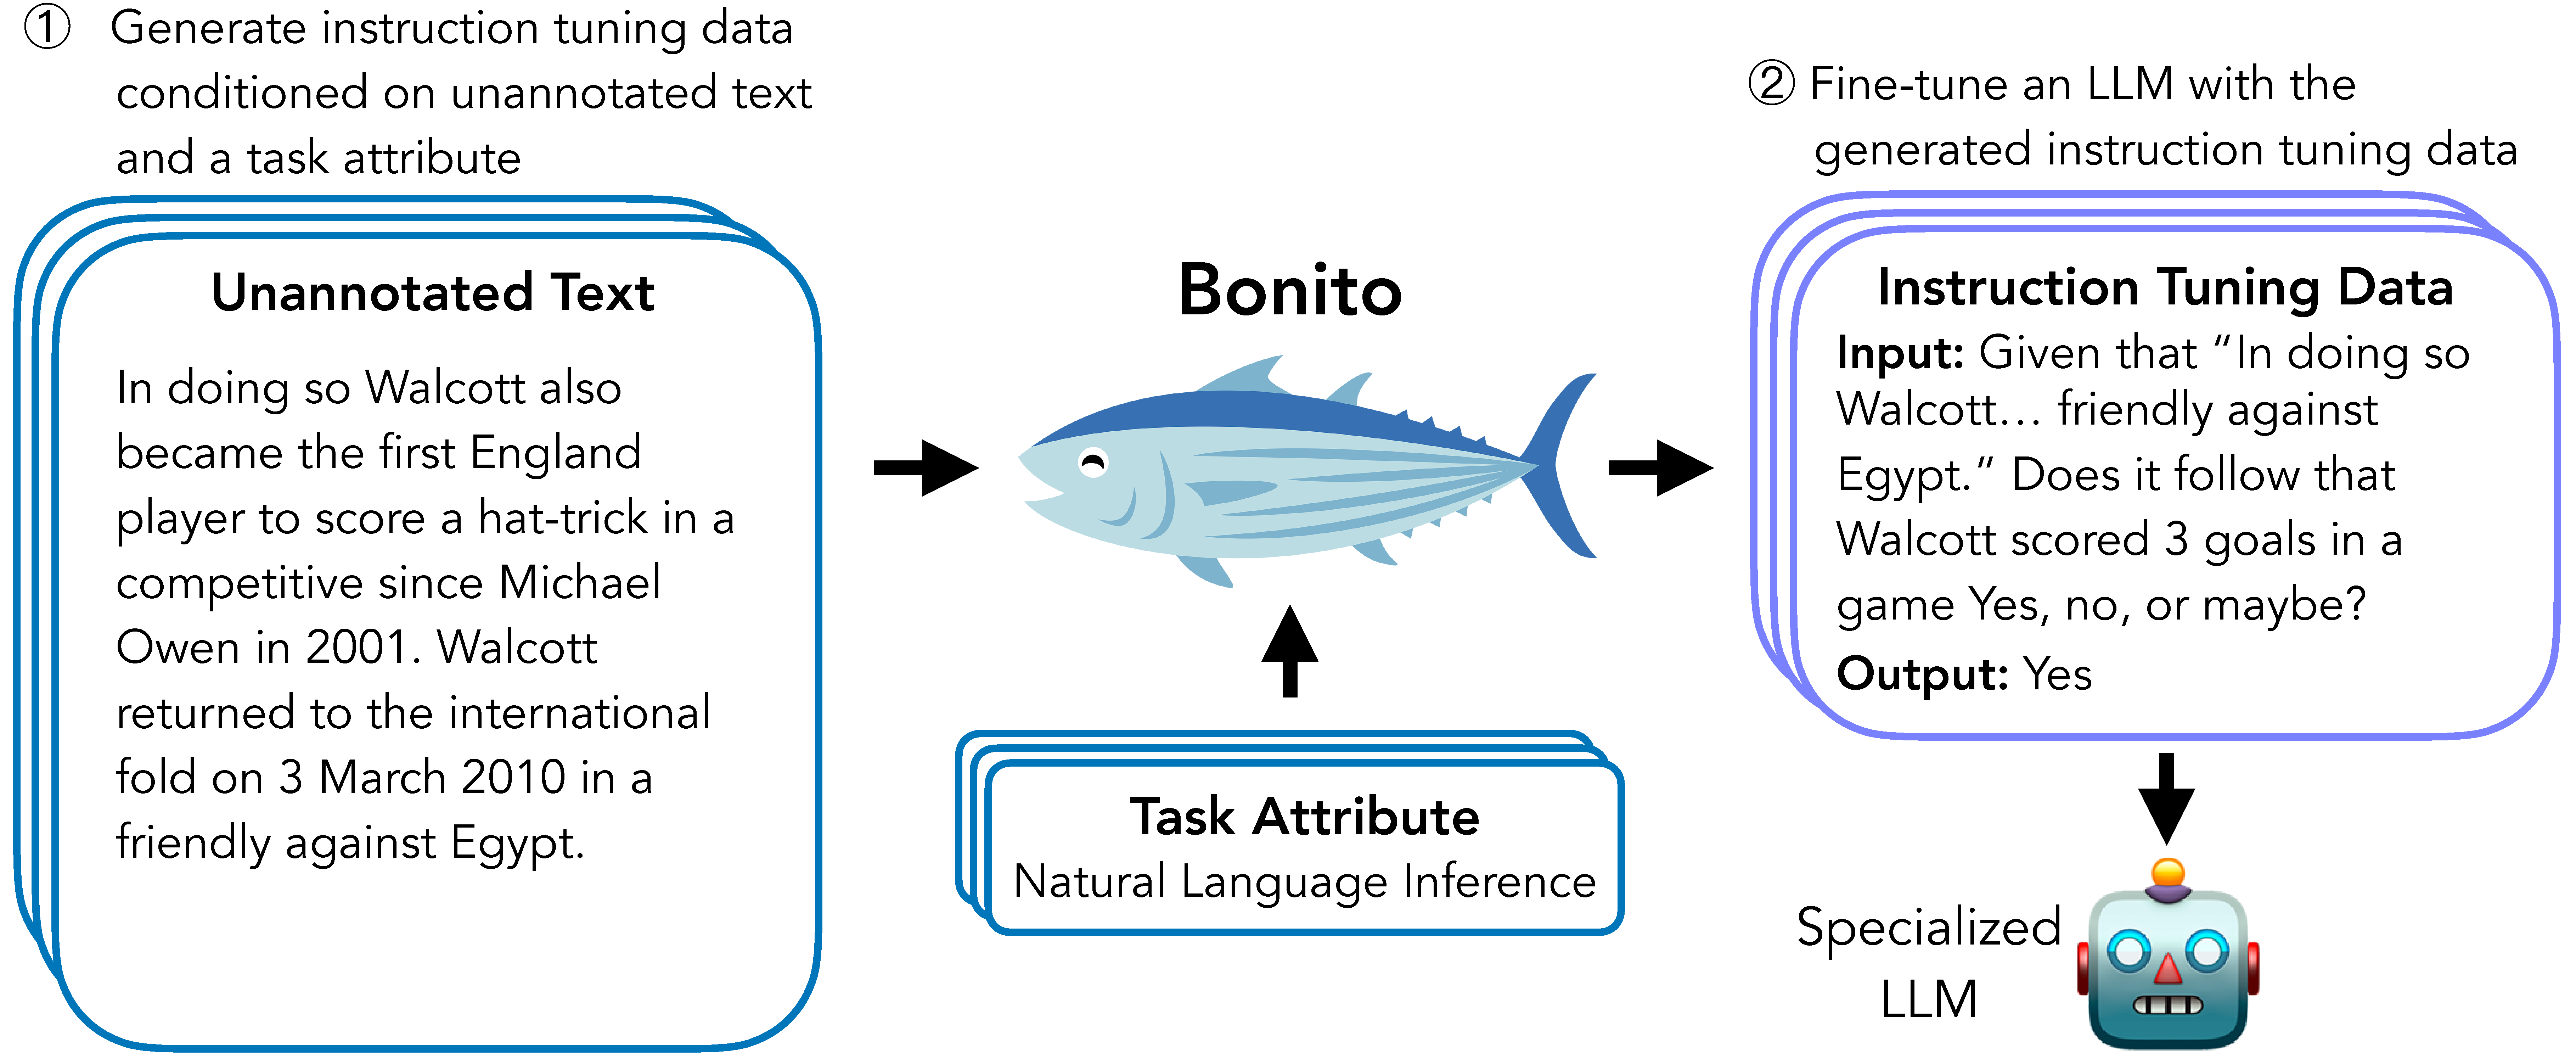
Bonito is an open-source model for conditional task generation: the task of converting unannotated text into task-specific training datasets for instruction tuning.
|
|
|
|
|
|
|
|
## Model Details
|
|
|
|
### Model Description
|
|
|
|
<!-- Provide a longer summary of what this model is. -->
|
|
|
|
Bonito can be used to create synthetic instruction tuning datasets to adapt large language models on users' specialized, private data.
|
|
In our [paper](https://arxiv.org/abs/2402.18334), we show that Bonito can be used to adapt both pretrained and instruction tuned models to tasks without any annotations.
|
|
|
|
- **Developed by:** Nihal V. Nayak, Yiyang Nan, Avi Trost, and Stephen H. Bach
|
|
- **Model type:** MistralForCausalLM
|
|
- **Language(s) (NLP):** English
|
|
- **License:** Apache 2.0
|
|
- **Finetuned from model:** `mistralai/Mistral-7B-v0.1`
|
|
|
|
### Model Sources
|
|
|
|
<!-- Provide the basic links for the model. -->
|
|
|
|
- **Repository:** [https://github.com/BatsResearch/bonito](https://github.com/BatsResearch/bonito)
|
|
- **Paper:** [Learning to Generate Instruction Tuning Datasets for
|
|
Zero-Shot Task Adaptation](https://arxiv.org/abs/2402.18334)
|
|
|
|
## Uses
|
|
|
|
<!-- Address questions around how the model is intended to be used, including the foreseeable users of the model and those affected by the model. -->
|
|
|
|
### Direct Use
|
|
|
|
<!-- This section is for the model use without fine-tuning or plugging into a larger ecosystem/app. -->
|
|
To easily generate synthetic instruction tuning datasets, we recommend using the [bonito](https://github.com/BatsResearch/bonito) package built using the `transformers` and the `vllm` libraries.
|
|
|
|
```python
|
|
from bonito import Bonito
|
|
from vllm import SamplingParams
|
|
from datasets import load_dataset
|
|
|
|
# Initialize the Bonito model
|
|
bonito = Bonito("BatsResearch/bonito-v1")
|
|
|
|
# load dataaset with unannotated text
|
|
unannotated_text = load_dataset(
|
|
"BatsResearch/bonito-experiment",
|
|
"unannotated_contract_nli"
|
|
)["train"].select(range(10))
|
|
|
|
# Generate synthetic instruction tuning dataset
|
|
sampling_params = SamplingParams(max_tokens=256, top_p=0.95, temperature=0.5, n=1)
|
|
synthetic_dataset = bonito.generate_tasks(
|
|
unannotated_text,
|
|
context_col="input",
|
|
task_type="nli",
|
|
sampling_params=sampling_params
|
|
)
|
|
```
|
|
|
|
|
|
### Out-of-Scope Use
|
|
|
|
<!-- This section addresses misuse, malicious use, and uses that the model will not work well for. -->
|
|
|
|
Our model is trained to generate the following task types: summarization, sentiment analysis, multiple-choice question answering, extractive question answering, topic classification, natural language inference, question generation, text generation, question answering without choices, paraphrase identification, sentence completion, yes-no question answering, word sense disambiguation, paraphrase generation, textual entailment, and
|
|
coreference resolution.
|
|
The model might not produce accurate synthetic tasks beyond these task types.
|
|
|
|
## Bias, Risks, and Limitations
|
|
|
|
<!-- This section is meant to convey both technical and sociotechnical limitations. -->
|
|
**Limitations**
|
|
|
|
Our work relies on the availability of large amounts of unannotated text.
|
|
If only a small quantity of unannotated text is present, the target language model, after adaptation, may experience a drop in performance.
|
|
While we demonstrate positive improvements on pretrained and instruction-tuned models, our observations are limited to the three task types (yes-no question answering, extractive question answering, and natural language inference) considered in our paper.
|
|
|
|
**Risks**
|
|
|
|
Bonito poses risks similar to those of any large language model.
|
|
For example, our model could be used to generate factually incorrect datasets in specialized domains.
|
|
Our model can exhibit the biases and stereotypes of the base model, Mistral-7B, even after extensive supervised fine-tuning.
|
|
Finally, our model does not include safety training and can potentially generate harmful content.
|
|
|
|
### Recommendations
|
|
|
|
<!-- This section is meant to convey recommendations with respect to the bias, risk, and technical limitations. -->
|
|
|
|
We recommend users thoroughly inspect the generated tasks and benchmark performance on critical datasets before deploying the models trained with the synthetic tasks into the real world.
|
|
|
|
## Training Details
|
|
|
|
### Training Data
|
|
|
|
<!-- This should link to a Dataset Card, perhaps with a short stub of information on what the training data is all about as well as documentation related to data pre-processing or additional filtering. -->
|
|
To train Bonito, we create a new dataset called conditional task generation with attributes by remixing existing instruction tuning datasets.
|
|
See [ctga-v1](https://huggingface.co/datasets/BatsResearch/ctga-v1) for more details.
|
|
|
|
### Training Procedure
|
|
|
|
<!-- This relates heavily to the Technical Specifications. Content here should link to that section when it is relevant to the training procedure. -->
|
|
|
|
#### Training Hyperparameters
|
|
|
|
- **Training regime:** <!--fp32, fp16 mixed precision, bf16 mixed precision, bf16 non-mixed precision, fp16 non-mixed precision, fp8 mixed precision -->
|
|
We train the model using [Q-LoRA](https://github.com/artidoro/qlora) by optimizing the cross entropy loss over the output tokens.
|
|
The model is trained for 100,000 steps.
|
|
The training takes about 4 days on four GPUs to complete.
|
|
|
|
We use the following hyperparameters:
|
|
- Q-LoRA rank (r): 64
|
|
- Q-LoRA scaling factor (alpha): 4
|
|
- Q-LoRA dropout: 0
|
|
- Optimizer: Paged AdamW
|
|
- Learning rate scheduler: linear
|
|
- Max. learning rate: 1e-04
|
|
- Min. learning rate: 0
|
|
- Weight decay: 0
|
|
- Dropout: 0
|
|
- Max. gradient norm: 0.3
|
|
- Effective batch size: 16
|
|
- Max. input length: 2,048
|
|
- Max. output length: 2,048
|
|
- Num. steps: 100,000
|
|
|
|
## Citation
|
|
|
|
<!-- If there is a paper or blog post introducing the model, the APA and Bibtex information for that should go in this section. -->
|
|
```
|
|
@inproceedings{bonito:aclfindings24,
|
|
title = {Learning to Generate Instruction Tuning Datasets for Zero-Shot Task Adaptation},
|
|
author = {Nayak, Nihal V. and Nan, Yiyang and Trost, Avi and Bach, Stephen H.},
|
|
booktitle = {Findings of the Association for Computational Linguistics: ACL 2024},
|
|
year = {2024}}
|
|
``` |