初始化项目,由ModelHub XC社区提供模型
Model: typhoon-ai/typhoon-s-thaillm-8b-instruct-research-preview
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||||
173
README.md
Normal file
173
README.md
Normal file
@@ -0,0 +1,173 @@
|
|||||||
|
---
|
||||||
|
library_name: transformers
|
||||||
|
pipeline_tag: text-generation
|
||||||
|
license: apache-2.0
|
||||||
|
license_link: https://huggingface.co/Qwen/Qwen3-8B-Base/blob/main/LICENSE
|
||||||
|
base_model:
|
||||||
|
- ThaiLLM/ThaiLLM-8B
|
||||||
|
---
|
||||||
|
|
||||||
|
## **Typhoon-S-ThaiLLM-8B-Instruct 🇹🇭 (Research Preview)**
|
||||||
|
|
||||||
|
**Typhoon-S-ThaiLLM-8B-Instruct** 🇹🇭 is a "**S**overeign", instruction-tuned Thai large language model based on [**ThaiLLM**](https://huggingface.co/ThaiLLM/ThaiLLM-8B) focusing on **openness and reproducibility** with the **training dataset**, **training code**, and **technical report** all fully open [here](https://arxiv.org/abs/2601.18129).
|
||||||
|
|
||||||
|
This work represents an early effort to **democratize post-training from base models** for sovereign AI. Due to the growing complexity of modern post-training pipelines used by large labs (e.g., DeepSeek, Qwen, Google, Nvidia), building high-quality sovereign instruction-tuned models has become increasingly difficult without leveraging proprietary instruction models. This reliance reduces the effectiveness of sovereign base-model adaptation techniques—such as continual pretraining—because instruction-following capabilities learned during post-training are often lost due to **catastrophic forgetting**.
|
||||||
|
|
||||||
|
This project builds upon the sovereign-tuned base model [**ThaiLLM**](https://huggingface.co/ThaiLLM/ThaiLLM-8B) and applies post-training methods such as:
|
||||||
|
|
||||||
|
- **Supervised Fine-Tuning (SFT)**
|
||||||
|
- **On-policy distillation (OPD)**
|
||||||
|
|
||||||
|
All of this is accomplished with only an **academic budget**—equivalent to **two days on a single H100 node**.
|
||||||
|
|
||||||
|
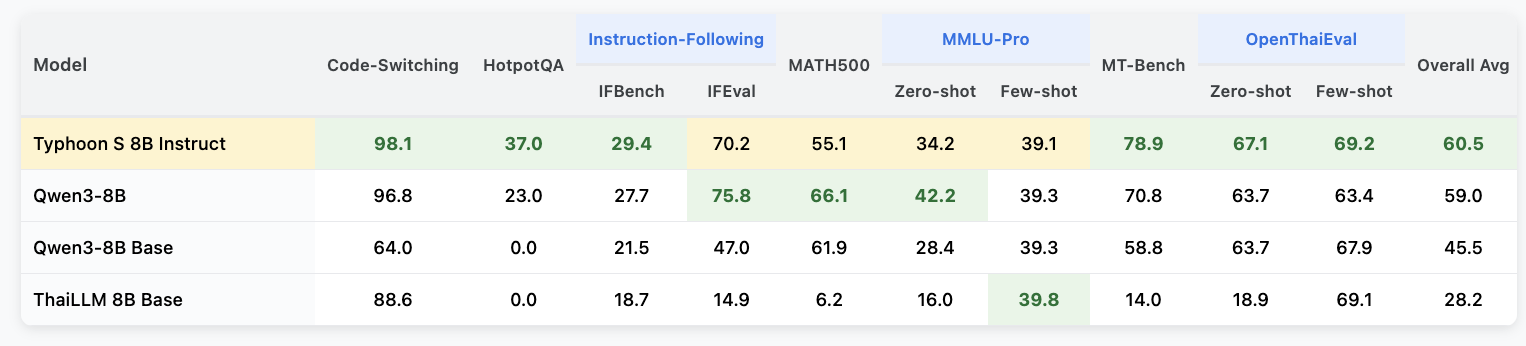
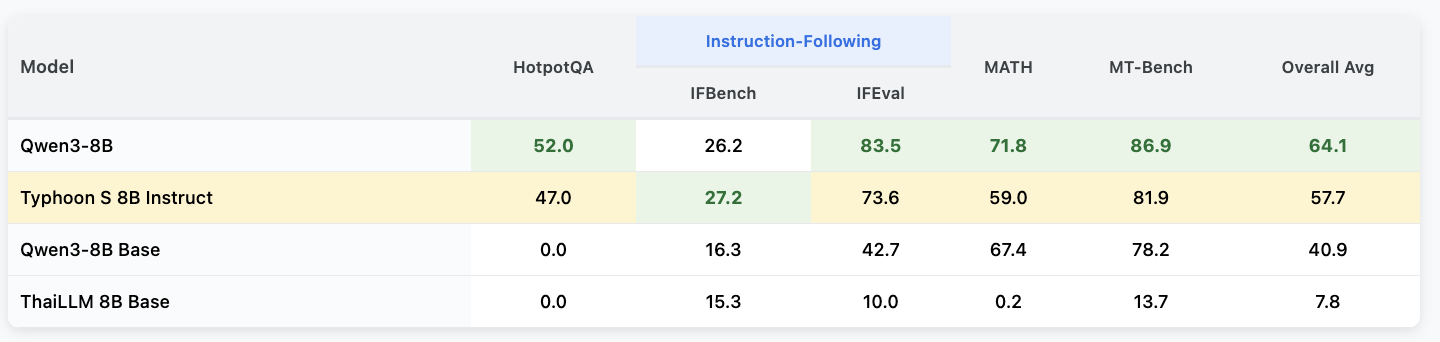
The overarching goal is to **demonstrate** that it is possible to build a **competitive instruction model**—on par with leading globally tuned models like **Qwen3-8B**—while maintaining **strong performance advantages in local languages**.
|
||||||
|
|
||||||
|
For more information, please read the full technical report on [arXiv](https://arxiv.org/abs/2601.18129).
|
||||||
|
|
||||||
|
## **Performance**
|
||||||
|
|
||||||
|
**Thai performance**
|
||||||
|
|
||||||
|
|
||||||
|
**English performance**
|
||||||
|
|
||||||
|
|
||||||
|
## **Model Description**
|
||||||
|
|
||||||
|
- **Model type**: A 8B instruct decoder-only model based on Qwen3 architecture and [ThaiLLM](https://huggingface.co/ThaiLLM/ThaiLLM-8B) base model.
|
||||||
|
- **Requirement**: transformers 4.57.0 or newer.
|
||||||
|
- **Primary Language(s)**: Thai 🇹🇭 and English 🇬🇧
|
||||||
|
- **Context Length**: 32K
|
||||||
|
- **License**: [Apache 2.0 License](https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE)
|
||||||
|
|
||||||
|
|
||||||
|
## Usage Example
|
||||||
|
|
||||||
|
This code snippet shows how to use the Typhoon model for Thai or English text generation using the transformers library. It includes setting up the model and tokenizer, formatting chat messages in a system-user style, and generating a response.
|
||||||
|
|
||||||
|
```python
|
||||||
|
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||||
|
import torch
|
||||||
|
|
||||||
|
model_id = "typhoon-ai/typhoon-s-thaillm-8b-instruct-research-preview"
|
||||||
|
|
||||||
|
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
||||||
|
model = AutoModelForCausalLM.from_pretrained(
|
||||||
|
model_id,
|
||||||
|
torch_dtype=torch.bfloat16,
|
||||||
|
device_map="auto",
|
||||||
|
)
|
||||||
|
|
||||||
|
messages = [
|
||||||
|
{"role": "system", "content": "You are a male AI assistant named Typhoon created by SCB 10X to be helpful, harmless, and honest. Typhoon is happy to help with analysis, question answering, math, coding, creative writing, teaching, role-play, general discussion, and all sorts of other tasks. Typhoon responds directly to all human messages without unnecessary affirmations or filler phrases like “Certainly!”, “Of course!”, “Absolutely!”, “Great!”, “Sure!”, etc. Specifically, Typhoon avoids starting responses with the word “Certainly” in any way. Typhoon follows this information in all languages, and always responds to the user in the language they use or request. Typhoon is now being connected with a human. Write in fluid, conversational prose, Show genuine interest in understanding requests, Express appropriate emotions and empathy. Also showing information in term that is easy to understand and visualized."},
|
||||||
|
{"role": "user", "content": "ขอสูตรไก่ย่าง"},
|
||||||
|
]
|
||||||
|
|
||||||
|
input_ids = tokenizer.apply_chat_template(
|
||||||
|
messages,
|
||||||
|
add_generation_prompt=True,
|
||||||
|
return_tensors="pt",
|
||||||
|
).to(model.device)
|
||||||
|
|
||||||
|
outputs = model.generate(
|
||||||
|
input_ids,
|
||||||
|
max_new_tokens=512,
|
||||||
|
do_sample=True,
|
||||||
|
temperature=0.4,
|
||||||
|
top_p=0.95,
|
||||||
|
repetition_penalty=1.05,
|
||||||
|
)
|
||||||
|
response = outputs[0][input_ids.shape[-1]:]
|
||||||
|
print(tokenizer.decode(response, skip_special_tokens=True))
|
||||||
|
```
|
||||||
|
|
||||||
|
## Deploy as Server
|
||||||
|
|
||||||
|
This section shows how to run Typhoon as an OpenAI-compatible API server using vllm.
|
||||||
|
|
||||||
|
```bash
|
||||||
|
pip install vllm
|
||||||
|
vllm serve typhoon-ai/typhoon-s-thaillm-8b-instruct-research-preview --max-model-len 8192 --tool-call-parser hermes --enable-auto-tool-choice --gpu-memory-utilization 0.95
|
||||||
|
# adjust --max-model-len based on your avaliable memory
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## Using Tools
|
||||||
|
|
||||||
|
You can provide tools to the vLLM-powered OpenAI-compatible API for functionality.
|
||||||
|
|
||||||
|
```
|
||||||
|
from openai import OpenAI
|
||||||
|
import json
|
||||||
|
|
||||||
|
client = OpenAI(base_url="http://localhost:8000/v1", api_key="dummy")
|
||||||
|
|
||||||
|
def get_weather(location: str, unit: str):
|
||||||
|
return f"Getting the weather for {location} in {unit}..."
|
||||||
|
|
||||||
|
tool_functions = {"get_weather": get_weather}
|
||||||
|
|
||||||
|
tools = [{
|
||||||
|
"type": "function",
|
||||||
|
"function": {
|
||||||
|
"name": "get_weather",
|
||||||
|
"description": "Get the current weather in a given location",
|
||||||
|
"parameters": {
|
||||||
|
"type": "object",
|
||||||
|
"properties": {
|
||||||
|
"location": {"type": "string", "description": "City and state, e.g., 'San Francisco, CA'"},
|
||||||
|
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
|
||||||
|
},
|
||||||
|
"required": ["location", "unit"]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}]
|
||||||
|
|
||||||
|
response = client.chat.completions.create(
|
||||||
|
model=client.models.list().data[0].id,
|
||||||
|
messages=[{"role": "user", "content": "What's the weather like in San Francisco?"}],
|
||||||
|
tools=tools,
|
||||||
|
tool_choice="auto",
|
||||||
|
extra_body={
|
||||||
|
"repetition_penalty": 1.05
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
tool_call = response.choices[0].message.tool_calls[0].function
|
||||||
|
print(f"Function called: {tool_call.name}")
|
||||||
|
print(f"Arguments: {tool_call.arguments}")
|
||||||
|
print(f"Result: {get_weather(**json.loads(tool_call.arguments))}")
|
||||||
|
```
|
||||||
|
|
||||||
|
## Sampling Parameters
|
||||||
|
|
||||||
|
For this model, we encourage you to use a low "temperature" eg.(0.4) and set "repetition_penalty" = 1.05 to improve performance and reduce repetition.
|
||||||
|
|
||||||
|
|
||||||
|
## **Intended Uses & Limitations**
|
||||||
|
|
||||||
|
This model is an instructional model. However, it’s still undergoing development. It incorporates some level of guardrails, but it still may produce answers that are inaccurate, biased, or otherwise objectionable in response to user prompts. We recommend that developers assess these risks in the context of their use case.
|
||||||
|
|
||||||
|
## **Follow us**
|
||||||
|
|
||||||
|
**https://twitter.com/opentyphoon**
|
||||||
|
|
||||||
|
## **Support**
|
||||||
|
|
||||||
|
**https://discord.gg/us5gAYmrxw**
|
||||||
|
|
||||||
|
|
||||||
|
## **Citation**
|
||||||
|
|
||||||
|
- If you find Typhoon-S useful for your work, please cite it using:
|
||||||
|
```
|
||||||
|
@misc{pipatanakul2026typhoonsminimalopenposttraining,
|
||||||
|
title={Typhoon-S: Minimal Open Post-Training for Sovereign Large Language Models},
|
||||||
|
author={Kunat Pipatanakul and Pittawat Taveekitworachai},
|
||||||
|
year={2026},
|
||||||
|
eprint={2601.18129},
|
||||||
|
archivePrefix={arXiv},
|
||||||
|
primaryClass={cs.CL},
|
||||||
|
url={https://arxiv.org/abs/2601.18129},
|
||||||
|
}
|
||||||
|
```
|
||||||
28
added_tokens.json
Normal file
28
added_tokens.json
Normal file
@@ -0,0 +1,28 @@
|
|||||||
|
{
|
||||||
|
"</think>": 151668,
|
||||||
|
"</tool_call>": 151658,
|
||||||
|
"</tool_response>": 151666,
|
||||||
|
"<think>": 151667,
|
||||||
|
"<tool_call>": 151657,
|
||||||
|
"<tool_response>": 151665,
|
||||||
|
"<|box_end|>": 151649,
|
||||||
|
"<|box_start|>": 151648,
|
||||||
|
"<|endoftext|>": 151643,
|
||||||
|
"<|file_sep|>": 151664,
|
||||||
|
"<|fim_middle|>": 151660,
|
||||||
|
"<|fim_pad|>": 151662,
|
||||||
|
"<|fim_prefix|>": 151659,
|
||||||
|
"<|fim_suffix|>": 151661,
|
||||||
|
"<|im_end|>": 151645,
|
||||||
|
"<|im_start|>": 151644,
|
||||||
|
"<|image_pad|>": 151655,
|
||||||
|
"<|object_ref_end|>": 151647,
|
||||||
|
"<|object_ref_start|>": 151646,
|
||||||
|
"<|quad_end|>": 151651,
|
||||||
|
"<|quad_start|>": 151650,
|
||||||
|
"<|repo_name|>": 151663,
|
||||||
|
"<|video_pad|>": 151656,
|
||||||
|
"<|vision_end|>": 151653,
|
||||||
|
"<|vision_pad|>": 151654,
|
||||||
|
"<|vision_start|>": 151652
|
||||||
|
}
|
||||||
61
chat_template.jinja
Normal file
61
chat_template.jinja
Normal file
@@ -0,0 +1,61 @@
|
|||||||
|
{%- if tools %}
|
||||||
|
{{- '<|im_start|>system\n' }}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- messages[0].content + '\n\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
||||||
|
{%- for tool in tools %}
|
||||||
|
{{- "\n" }}
|
||||||
|
{{- tool | tojson }}
|
||||||
|
{%- endfor %}
|
||||||
|
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
||||||
|
{%- else %}
|
||||||
|
{%- if messages[0].role == 'system' %}
|
||||||
|
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- for message in messages %}
|
||||||
|
{%- if message.content is string %}
|
||||||
|
{%- set content = message.content %}
|
||||||
|
{%- else %}
|
||||||
|
{%- set content = '' %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
||||||
|
{%- elif message.role == "assistant" %}
|
||||||
|
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||||
|
{%- if message.tool_calls %}
|
||||||
|
{%- for tool_call in message.tool_calls %}
|
||||||
|
{%- if (loop.first and content) or (not loop.first) %}
|
||||||
|
{{- '\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- if tool_call.function %}
|
||||||
|
{%- set tool_call = tool_call.function %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<tool_call>\n{"name": "' }}
|
||||||
|
{{- tool_call.name }}
|
||||||
|
{{- '", "arguments": ' }}
|
||||||
|
{%- if tool_call.arguments is string %}
|
||||||
|
{{- tool_call.arguments }}
|
||||||
|
{%- else %}
|
||||||
|
{{- tool_call.arguments | tojson }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '}\n</tool_call>' }}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- elif message.role == "tool" %}
|
||||||
|
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
||||||
|
{{- '<|im_start|>user' }}
|
||||||
|
{%- endif %}
|
||||||
|
{{- '\n<tool_response>\n' }}
|
||||||
|
{{- content }}
|
||||||
|
{{- '\n</tool_response>' }}
|
||||||
|
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
||||||
|
{{- '<|im_end|>\n' }}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endif %}
|
||||||
|
{%- endfor %}
|
||||||
|
{%- if add_generation_prompt %}
|
||||||
|
{{- '<|im_start|>assistant\n' }}
|
||||||
|
{%- endif %}
|
||||||
68
config.json
Normal file
68
config.json
Normal file
@@ -0,0 +1,68 @@
|
|||||||
|
{
|
||||||
|
"architectures": [
|
||||||
|
"Qwen3ForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_bias": false,
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"dtype": "bfloat16",
|
||||||
|
"eos_token_id": 151645,
|
||||||
|
"head_dim": 128,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 4096,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 12288,
|
||||||
|
"layer_types": [
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention",
|
||||||
|
"full_attention"
|
||||||
|
],
|
||||||
|
"max_position_embeddings": 32768,
|
||||||
|
"max_window_layers": 36,
|
||||||
|
"model_type": "qwen3",
|
||||||
|
"num_attention_heads": 32,
|
||||||
|
"num_hidden_layers": 36,
|
||||||
|
"num_key_value_heads": 8,
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"rope_scaling": null,
|
||||||
|
"rope_theta": 1000000,
|
||||||
|
"sliding_window": null,
|
||||||
|
"tie_word_embeddings": false,
|
||||||
|
"transformers_version": "4.57.3",
|
||||||
|
"use_cache": false,
|
||||||
|
"use_sliding_window": false,
|
||||||
|
"vocab_size": 151936
|
||||||
|
}
|
||||||
11
generation_config.json
Normal file
11
generation_config.json
Normal file
@@ -0,0 +1,11 @@
|
|||||||
|
{
|
||||||
|
"do_sample": true,
|
||||||
|
"eos_token_id": [
|
||||||
|
151645,
|
||||||
|
151643
|
||||||
|
],
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"temperature": 0.4,
|
||||||
|
"transformers_version": "4.57.3",
|
||||||
|
"use_cache": false
|
||||||
|
}
|
||||||
151388
merges.txt
Normal file
151388
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
3
model-00001-of-00004.safetensors
Normal file
3
model-00001-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:26fda0ec1e8a954d30e345034738b239102e8c63a3838ffb563ee743861c46ba
|
||||||
|
size 4902257696
|
||||||
3
model-00002-of-00004.safetensors
Normal file
3
model-00002-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:a25f40736bb3bf1bea1df49658af4faf353b565e681d9a403b34f09e1711393d
|
||||||
|
size 4915960368
|
||||||
3
model-00003-of-00004.safetensors
Normal file
3
model-00003-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:a19bd4ac04e0b5052382977cf75435c9727950f423d7539558d78dc942299af8
|
||||||
|
size 4983068496
|
||||||
3
model-00004-of-00004.safetensors
Normal file
3
model-00004-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:d7fe148875137c3c6b7aef102ec6ed9ccde62c66029fa5eacf825137eeaf0f4c
|
||||||
|
size 1580230264
|
||||||
407
model.safetensors.index.json
Normal file
407
model.safetensors.index.json
Normal file
@@ -0,0 +1,407 @@
|
|||||||
|
{
|
||||||
|
"metadata": {
|
||||||
|
"total_parameters": 8190735360,
|
||||||
|
"total_size": 16381470720
|
||||||
|
},
|
||||||
|
"weight_map": {
|
||||||
|
"lm_head.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.embed_tokens.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.10.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.10.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.11.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.12.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.13.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.14.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.15.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.16.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.17.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.18.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.19.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.2.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.20.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.20.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.mlp.gate_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.21.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.22.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.22.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.22.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.22.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.22.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.23.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.23.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.24.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.25.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.26.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.27.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.28.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.29.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.3.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.30.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.30.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.31.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.32.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.33.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.input_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.mlp.gate_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.post_attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.34.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.35.input_layernorm.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.mlp.down_proj.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.mlp.gate_proj.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.mlp.up_proj.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.post_attention_layernorm.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.k_norm.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.o_proj.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.q_norm.weight": "model-00004-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.35.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
||||||
|
"model.layers.4.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.7.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.input_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.post_attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.8.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.input_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.9.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.9.mlp.gate_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.9.post_attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.layers.9.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
||||||
|
"model.norm.weight": "model-00004-of-00004.safetensors"
|
||||||
|
}
|
||||||
|
}
|
||||||
31
special_tokens_map.json
Normal file
31
special_tokens_map.json
Normal file
@@ -0,0 +1,31 @@
|
|||||||
|
{
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"eos_token": {
|
||||||
|
"content": "<|im_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"pad_token": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
}
|
||||||
|
}
|
||||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:4ccc4899ba0014b689f093ee0c60d606a302b71e7d5778b9f2d17c05381e2a17
|
||||||
|
size 11422920
|
||||||
246
tokenizer_config.json
Normal file
246
tokenizer_config.json
Normal file
@@ -0,0 +1,246 @@
|
|||||||
|
{
|
||||||
|
"add_bos_token": false,
|
||||||
|
"add_prefix_space": false,
|
||||||
|
"added_tokens_decoder": {
|
||||||
|
"151643": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151644": {
|
||||||
|
"content": "<|im_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151645": {
|
||||||
|
"content": "<|im_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151646": {
|
||||||
|
"content": "<|object_ref_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151647": {
|
||||||
|
"content": "<|object_ref_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151648": {
|
||||||
|
"content": "<|box_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151649": {
|
||||||
|
"content": "<|box_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151650": {
|
||||||
|
"content": "<|quad_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151651": {
|
||||||
|
"content": "<|quad_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151652": {
|
||||||
|
"content": "<|vision_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151653": {
|
||||||
|
"content": "<|vision_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151654": {
|
||||||
|
"content": "<|vision_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151655": {
|
||||||
|
"content": "<|image_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151656": {
|
||||||
|
"content": "<|video_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151657": {
|
||||||
|
"content": "<tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151658": {
|
||||||
|
"content": "</tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151659": {
|
||||||
|
"content": "<|fim_prefix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151660": {
|
||||||
|
"content": "<|fim_middle|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151661": {
|
||||||
|
"content": "<|fim_suffix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151662": {
|
||||||
|
"content": "<|fim_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151663": {
|
||||||
|
"content": "<|repo_name|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151664": {
|
||||||
|
"content": "<|file_sep|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151665": {
|
||||||
|
"content": "<tool_response>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151666": {
|
||||||
|
"content": "</tool_response>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151667": {
|
||||||
|
"content": "<think>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151668": {
|
||||||
|
"content": "</think>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"bos_token": null,
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": "<|im_end|>",
|
||||||
|
"errors": "replace",
|
||||||
|
"extra_special_tokens": {},
|
||||||
|
"max_length": 2048,
|
||||||
|
"model_max_length": 1010000,
|
||||||
|
"pad_to_multiple_of": null,
|
||||||
|
"pad_token": "<|endoftext|>",
|
||||||
|
"pad_token_type_id": 0,
|
||||||
|
"padding_side": "left",
|
||||||
|
"split_special_tokens": false,
|
||||||
|
"stride": 0,
|
||||||
|
"tokenizer_class": "Qwen2Tokenizer",
|
||||||
|
"truncation_side": "right",
|
||||||
|
"truncation_strategy": "longest_first",
|
||||||
|
"unk_token": null
|
||||||
|
}
|
||||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user