初始化项目,由ModelHub XC社区提供模型
Model: stelterlab/openhands-lm-32b-v0.1-AWQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||||
102
README.md
Normal file
102
README.md
Normal file
@@ -0,0 +1,102 @@
|
|||||||
|
---
|
||||||
|
license: mit
|
||||||
|
datasets:
|
||||||
|
- SWE-Gym/SWE-Gym
|
||||||
|
language:
|
||||||
|
- en
|
||||||
|
base_model:
|
||||||
|
- all-hands/openhands-lm-32b-v0.1
|
||||||
|
pipeline_tag: text-generation
|
||||||
|
tags:
|
||||||
|
- agent
|
||||||
|
- coding
|
||||||
|
---
|
||||||
|
|
||||||
|
AWQ quantization: done by stelterlab in INT4 GEMM with AutoAWQ by casper-hansen (https://github.com/casper-hansen/AutoAWQ/)
|
||||||
|
|
||||||
|
Original Weights by the Mistral AI. Original Model Card follows:
|
||||||
|
|
||||||
|
<div align="center">
|
||||||
|
<img src="https://github.com/All-Hands-AI/OpenHands/blob/main/docs/static/img/logo.png?raw=true" alt="Logo" width="200">
|
||||||
|
<h1 align="center">OpenHands LM v0.1</h1>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href="https://www.all-hands.dev/blog/introducing-openhands-lm-32b----a-strong-open-coding-agent-model">Blog</a>
|
||||||
|
•
|
||||||
|
<a href="https://docs.all-hands.dev/modules/usage/llms/local-llms" >Use it in OpenHands</a>
|
||||||
|
</p>
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
Autonomous agents for software development are already contributing to a [wide range of software development tasks](/blog/8-use-cases-for-generalist-software-development-agents).
|
||||||
|
But up to this point, strong coding agents have relied on proprietary models, which means that even if you use an open-source agent like [OpenHands](https://github.com/All-Hands-AI/OpenHands), you are still reliant on API calls to an external service.
|
||||||
|
|
||||||
|
Today, we are excited to introduce OpenHands LM, a new open coding model that:
|
||||||
|
|
||||||
|
- Is open and [available on Hugging Face](https://huggingface.co/all-hands/openhands-lm-32b-v0.1), so you can download it and run it locally
|
||||||
|
- Is a reasonable size, 32B, so it can be run locally on hardware such as a single 3090 GPU
|
||||||
|
- Achieves strong performance on software engineering tasks, including 37.2% resolve rate on SWE-Bench Verified
|
||||||
|
|
||||||
|
Read below for more details and our future plans!
|
||||||
|
|
||||||
|
## What is OpenHands LM?
|
||||||
|
|
||||||
|
OpenHands LM is built on the foundation of [Qwen Coder 2.5 Instruct 32B](https://huggingface.co/Qwen/Qwen2.5-Coder-32B-Instruct), leveraging its powerful base capabilities for coding tasks. What sets OpenHands LM apart is our specialized fine-tuning process:
|
||||||
|
|
||||||
|
- We used training data generated by OpenHands itself on a diverse set of open-source repositories
|
||||||
|
- Specifically, we use an RL-based framework outlined in [SWE-Gym](https://arxiv.org/abs/2412.21139), where we set up a training environment, generate training data using an existing agent, and then fine-tune the model on examples that were resolved successfully
|
||||||
|
- It features a 128K token context window, ideal for handling large codebases and long-horizon software engineering tasks
|
||||||
|
|
||||||
|
|
||||||
|
## Performance: Punching Above Its Weight
|
||||||
|
|
||||||
|
We evaluated OpenHands LM using our latest [iterative evaluation protocol](https://github.com/All-Hands-AI/OpenHands/tree/main/evaluation/benchmarks/swe_bench#run-inference-rollout-on-swe-bench-instances-generate-patch-from-problem-statement) on the [SWE-Bench Verified benchmark](https://www.swebench.com/#verified).
|
||||||
|
|
||||||
|
The results are impressive:
|
||||||
|
|
||||||
|
- **37.2% verified resolve rate** on SWE-Bench Verified
|
||||||
|
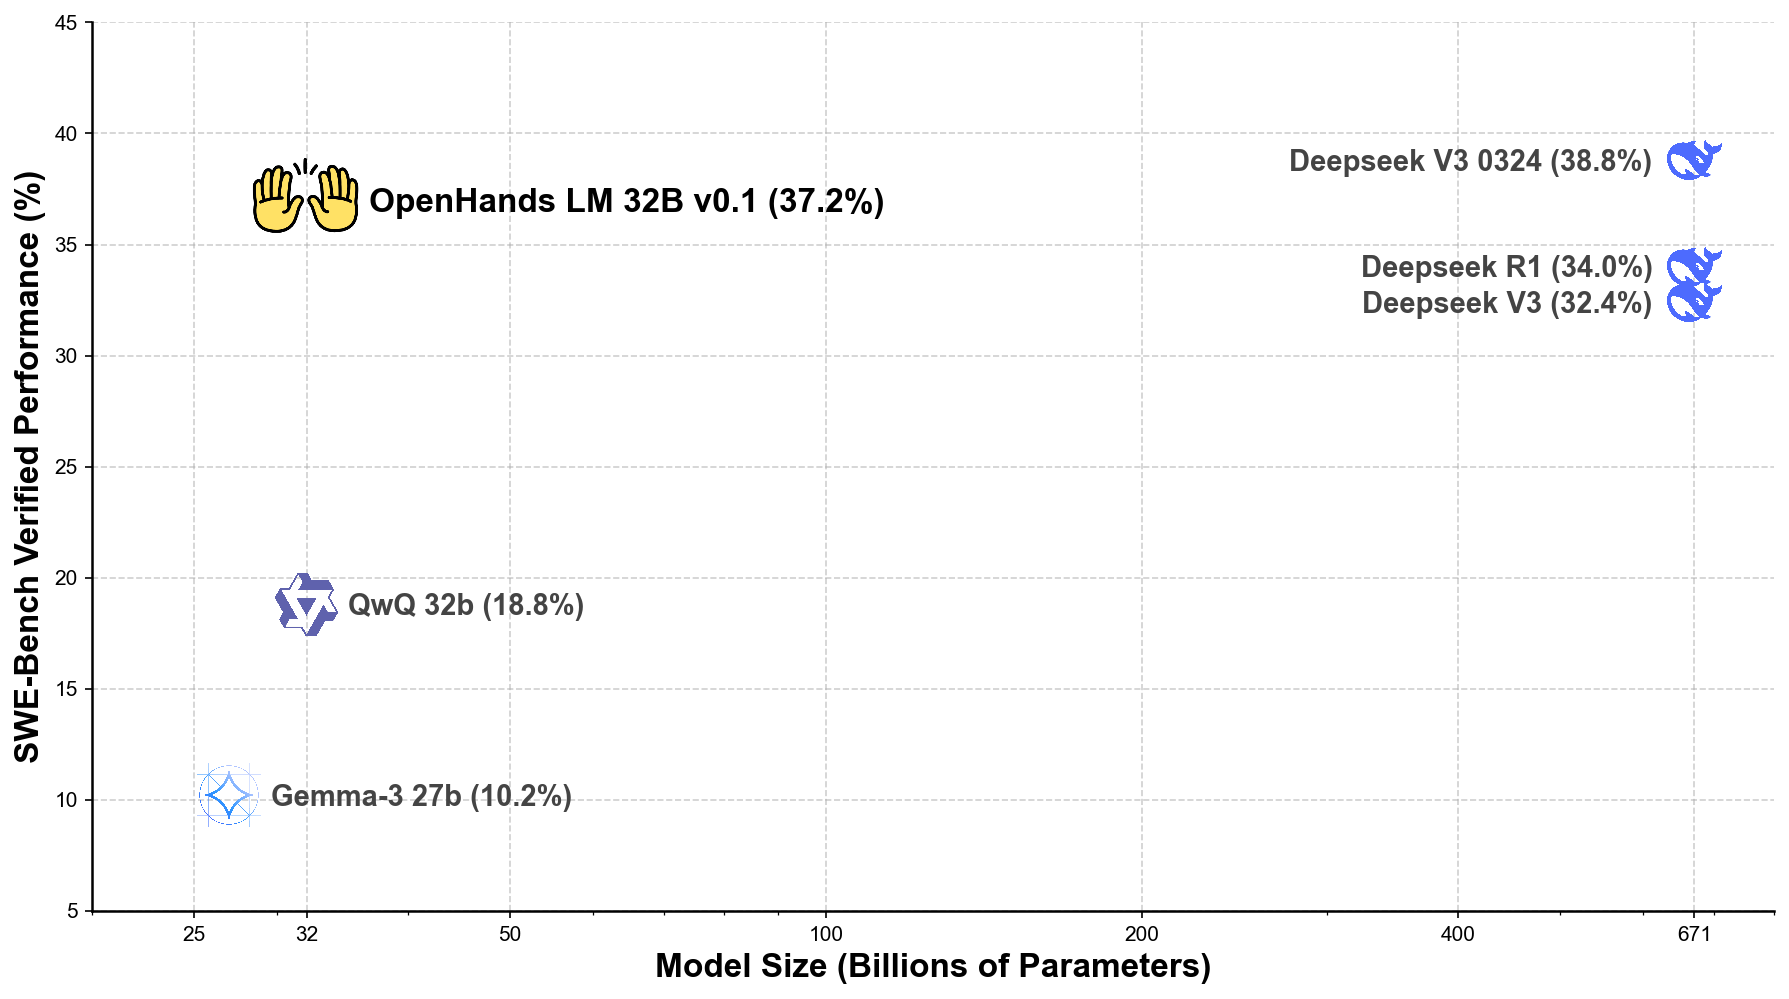
- Performance comparable to models with **20x more parameters**, including Deepseek V3 0324 (38.8%) with 671B parameters
|
||||||
|
|
||||||
|
Here's how OpenHands LM compares to other leading open-source models:
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
As the plot demonstrates, our 32B parameter model achieves efficiency that approaches much larger models. While the largest models (671B parameters) achieve slightly higher scores, our 32B parameter model performs remarkably well, opening up possibilities for local deployment that are not possible with larger models.
|
||||||
|
|
||||||
|
## Getting Started: How to Use OpenHands LM Today
|
||||||
|
|
||||||
|
You can start using OpenHands LM immediately through these channels:
|
||||||
|
|
||||||
|
1. **Download the model from Hugging Face**
|
||||||
|
The model is available on [Hugging Face](https://huggingface.co/all-hands/openhands-lm-32b-v0.1) and can be downloaded directly from there.
|
||||||
|
|
||||||
|
2. **Create an OpenAI-compatible endpoint with a model serving framework**
|
||||||
|
For optimal performance, it is recommended to serve this model with a GPU using [SGLang](https://github.com/sgl-project/sglang) or [vLLM](https://github.com/vllm-project/vllm).
|
||||||
|
|
||||||
|
3. **Point your OpenHands agent to the new model**
|
||||||
|
Download [OpenHands](https://github.com/All-Hands-AI/OpenHands) and follow the instructions for [using an OpenAI-compatible endpoint](https://docs.all-hands.dev/modules/usage/llms/openai-llms#using-openai-compatible-endpoints).
|
||||||
|
|
||||||
|
|
||||||
|
## The Road Ahead: Our Development Plans
|
||||||
|
|
||||||
|
This initial release marks just the beginning of our journey. We will continue enhancing OpenHands LM based on community feedback and ongoing research initiatives.
|
||||||
|
|
||||||
|
In particular, it should be noted that the model is still a research preview, and (1) may be best suited for tasks regarding solving github issues and perform less well on more varied software engineering tasks, (2) may sometimes generate repetitive steps, and (3) is somewhat sensitive to quantization, and may not function at full performance at lower quantization levels.
|
||||||
|
Our next releases will focus on addressing these limitations.
|
||||||
|
|
||||||
|
We're also developing more compact versions of the model (including a 7B parameter variant) to support users with limited computational resources. These smaller models will preserve OpenHands LM's core strengths while dramatically reducing hardware requirements.
|
||||||
|
|
||||||
|
We encourage you to experiment with OpenHands LM, share your experiences, and participate in its evolution. Together, we can create better tools for tomorrow's software development landscape.
|
||||||
|
|
||||||
|
## Join Our Community
|
||||||
|
|
||||||
|
We invite you to be part of the OpenHands LM journey:
|
||||||
|
|
||||||
|
- Explore our [GitHub repository](https://github.com/All-Hands-AI/OpenHands)
|
||||||
|
- Connect with us on [Slack](https://join.slack.com/t/openhands-ai/shared_invite/zt-2tom0er4l-JeNUGHt_AxpEfIBstbLPiw)
|
||||||
|
- Follow our [documentation](https://docs.all-hands.dev) to get started
|
||||||
|
|
||||||
|
By contributing your experiences and feedback, you'll help shape the future of this open-source initiative. Together, we can create better tools for tomorrow's software development landscape.
|
||||||
|
|
||||||
|
We can't wait to see what you'll create with OpenHands LM!
|
||||||
24
added_tokens.json
Normal file
24
added_tokens.json
Normal file
@@ -0,0 +1,24 @@
|
|||||||
|
{
|
||||||
|
"</tool_call>": 151658,
|
||||||
|
"<tool_call>": 151657,
|
||||||
|
"<|box_end|>": 151649,
|
||||||
|
"<|box_start|>": 151648,
|
||||||
|
"<|endoftext|>": 151643,
|
||||||
|
"<|file_sep|>": 151664,
|
||||||
|
"<|fim_middle|>": 151660,
|
||||||
|
"<|fim_pad|>": 151662,
|
||||||
|
"<|fim_prefix|>": 151659,
|
||||||
|
"<|fim_suffix|>": 151661,
|
||||||
|
"<|im_end|>": 151645,
|
||||||
|
"<|im_start|>": 151644,
|
||||||
|
"<|image_pad|>": 151655,
|
||||||
|
"<|object_ref_end|>": 151647,
|
||||||
|
"<|object_ref_start|>": 151646,
|
||||||
|
"<|quad_end|>": 151651,
|
||||||
|
"<|quad_start|>": 151650,
|
||||||
|
"<|repo_name|>": 151663,
|
||||||
|
"<|video_pad|>": 151656,
|
||||||
|
"<|vision_end|>": 151653,
|
||||||
|
"<|vision_pad|>": 151654,
|
||||||
|
"<|vision_start|>": 151652
|
||||||
|
}
|
||||||
42
config.json
Normal file
42
config.json
Normal file
@@ -0,0 +1,42 @@
|
|||||||
|
{
|
||||||
|
"_name_or_path": "/data/hf/models/models--all-hands--openhands-lm-32b-v0.1/snapshots/1ce6c6d98200f19b24e138e64d43481b5ccdf208",
|
||||||
|
"architectures": [
|
||||||
|
"Qwen2ForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"bos_token_id": 151643,
|
||||||
|
"eos_token_id": 151645,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 5120,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 27648,
|
||||||
|
"max_position_embeddings": 32768,
|
||||||
|
"max_window_layers": 64,
|
||||||
|
"model_type": "qwen2",
|
||||||
|
"num_attention_heads": 40,
|
||||||
|
"num_hidden_layers": 64,
|
||||||
|
"num_key_value_heads": 8,
|
||||||
|
"quantization_config": {
|
||||||
|
"bits": 4,
|
||||||
|
"group_size": 128,
|
||||||
|
"modules_to_not_convert": null,
|
||||||
|
"quant_method": "awq",
|
||||||
|
"version": "gemm",
|
||||||
|
"zero_point": true
|
||||||
|
},
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"rope_scaling": {
|
||||||
|
"factor": 4.0,
|
||||||
|
"original_max_position_embeddings": 32768,
|
||||||
|
"rope_type": "yarn",
|
||||||
|
"type": "yarn"
|
||||||
|
},
|
||||||
|
"rope_theta": 1000000.0,
|
||||||
|
"sliding_window": null,
|
||||||
|
"tie_word_embeddings": false,
|
||||||
|
"torch_dtype": "bfloat16",
|
||||||
|
"transformers_version": "4.47.1",
|
||||||
|
"use_cache": false,
|
||||||
|
"use_sliding_window": false,
|
||||||
|
"vocab_size": 152064
|
||||||
|
}
|
||||||
14
generation_config.json
Normal file
14
generation_config.json
Normal file
@@ -0,0 +1,14 @@
|
|||||||
|
{
|
||||||
|
"bos_token_id": 151643,
|
||||||
|
"do_sample": true,
|
||||||
|
"eos_token_id": [
|
||||||
|
151645,
|
||||||
|
151643
|
||||||
|
],
|
||||||
|
"pad_token_id": 151643,
|
||||||
|
"repetition_penalty": 1.05,
|
||||||
|
"temperature": 0.7,
|
||||||
|
"top_k": 20,
|
||||||
|
"top_p": 0.8,
|
||||||
|
"transformers_version": "4.47.1"
|
||||||
|
}
|
||||||
151388
merges.txt
Normal file
151388
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
3
model-00001-of-00004.safetensors
Normal file
3
model-00001-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:da95e4bf92b3a918cc84ae7ccb01b085fec29009b70177c8ed10797b2f98501f
|
||||||
|
size 4956994936
|
||||||
3
model-00002-of-00004.safetensors
Normal file
3
model-00002-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:bd8a4da3e2727886c11b886f91b3b9b1400bbaf0eecd66e336c3f42764bef1e0
|
||||||
|
size 4993553856
|
||||||
3
model-00003-of-00004.safetensors
Normal file
3
model-00003-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:6624aa373b81d52f6698743db49cb16500fa416172258214727615b8fd83b3ef
|
||||||
|
size 4960831008
|
||||||
3
model-00004-of-00004.safetensors
Normal file
3
model-00004-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:c9cd8d6e54b2029b77344eaf670cd155d89125505feec50b705af6b493a703d6
|
||||||
|
size 4417614320
|
||||||
1674
model.safetensors.index.json
Normal file
1674
model.safetensors.index.json
Normal file
File diff suppressed because it is too large
Load Diff
31
special_tokens_map.json
Normal file
31
special_tokens_map.json
Normal file
@@ -0,0 +1,31 @@
|
|||||||
|
{
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"eos_token": {
|
||||||
|
"content": "<|im_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"pad_token": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
}
|
||||||
|
}
|
||||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:9c5ae00e602b8860cbd784ba82a8aa14e8feecec692e7076590d014d7b7fdafa
|
||||||
|
size 11421896
|
||||||
208
tokenizer_config.json
Normal file
208
tokenizer_config.json
Normal file
@@ -0,0 +1,208 @@
|
|||||||
|
{
|
||||||
|
"add_bos_token": false,
|
||||||
|
"add_prefix_space": false,
|
||||||
|
"added_tokens_decoder": {
|
||||||
|
"151643": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151644": {
|
||||||
|
"content": "<|im_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151645": {
|
||||||
|
"content": "<|im_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151646": {
|
||||||
|
"content": "<|object_ref_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151647": {
|
||||||
|
"content": "<|object_ref_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151648": {
|
||||||
|
"content": "<|box_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151649": {
|
||||||
|
"content": "<|box_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151650": {
|
||||||
|
"content": "<|quad_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151651": {
|
||||||
|
"content": "<|quad_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151652": {
|
||||||
|
"content": "<|vision_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151653": {
|
||||||
|
"content": "<|vision_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151654": {
|
||||||
|
"content": "<|vision_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151655": {
|
||||||
|
"content": "<|image_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151656": {
|
||||||
|
"content": "<|video_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151657": {
|
||||||
|
"content": "<tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151658": {
|
||||||
|
"content": "</tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151659": {
|
||||||
|
"content": "<|fim_prefix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151660": {
|
||||||
|
"content": "<|fim_middle|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151661": {
|
||||||
|
"content": "<|fim_suffix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151662": {
|
||||||
|
"content": "<|fim_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151663": {
|
||||||
|
"content": "<|repo_name|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151664": {
|
||||||
|
"content": "<|file_sep|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"bos_token": null,
|
||||||
|
"chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen, created by Alibaba Cloud. You are a helpful assistant.' }}\n {%- endif %}\n {{- \"\\n\\n# Tools\\n\\nYou may call one or more functions to assist with the user query.\\n\\nYou are provided with function signatures within <tools></tools> XML tags:\\n<tools>\" }}\n {%- for tool in tools %}\n {{- \"\\n\" }}\n {{- tool | tojson }}\n {%- endfor %}\n {{- \"\\n</tools>\\n\\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\\n<tool_call>\\n{\\\"name\\\": <function-name>, \\\"arguments\\\": <args-json-object>}\\n</tool_call><|im_end|>\\n\" }}\n{%- else %}\n {%- if messages[0]['role'] == 'system' %}\n {{- '<|im_start|>system\\n' + messages[0]['content'] + '<|im_end|>\\n' }}\n {%- else %}\n {{- '<|im_start|>system\\nYou are Qwen, created by Alibaba Cloud. You are a helpful assistant.<|im_end|>\\n' }}\n {%- endif %}\n{%- endif %}\n{%- for message in messages %}\n {%- if (message.role == \"user\") or (message.role == \"system\" and not loop.first) or (message.role == \"assistant\" and not message.tool_calls) %}\n {{- '<|im_start|>' + message.role + '\\n' + message.content + '<|im_end|>' + '\\n' }}\n {%- elif message.role == \"assistant\" %}\n {{- '<|im_start|>' + message.role }}\n {%- if message.content %}\n {{- '\\n' + message.content }}\n {%- endif %}\n {%- for tool_call in message.tool_calls %}\n {%- if tool_call.function is defined %}\n {%- set tool_call = tool_call.function %}\n {%- endif %}\n {{- '\\n<tool_call>\\n{\"name\": \"' }}\n {{- tool_call.name }}\n {{- '\", \"arguments\": ' }}\n {{- tool_call.arguments | tojson }}\n {{- '}\\n</tool_call>' }}\n {%- endfor %}\n {{- '<|im_end|>\\n' }}\n {%- elif message.role == \"tool\" %}\n {%- if (loop.index0 == 0) or (messages[loop.index0 - 1].role != \"tool\") %}\n {{- '<|im_start|>user' }}\n {%- endif %}\n {{- '\\n<tool_response>\\n' }}\n {{- message.content }}\n {{- '\\n</tool_response>' }}\n {%- if loop.last or (messages[loop.index0 + 1].role != \"tool\") %}\n {{- '<|im_end|>\\n' }}\n {%- endif %}\n {%- endif %}\n{%- endfor %}\n{%- if add_generation_prompt %}\n {{- '<|im_start|>assistant\\n' }}\n{%- endif %}\n",
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": "<|im_end|>",
|
||||||
|
"errors": "replace",
|
||||||
|
"extra_special_tokens": {},
|
||||||
|
"model_max_length": 131072,
|
||||||
|
"pad_token": "<|endoftext|>",
|
||||||
|
"split_special_tokens": false,
|
||||||
|
"tokenizer_class": "Qwen2Tokenizer",
|
||||||
|
"unk_token": null
|
||||||
|
}
|
||||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user