初始化项目,由ModelHub XC社区提供模型
Model: seanzhang/Llama3-Chinese
Source: Original Platform
This commit is contained in:
 ModelHub XC
34
.gitattributes
vendored
Normal file
34
.gitattributes
vendored
Normal file
@@ -0,0 +1,34 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
191
README.md
Normal file
191
README.md
Normal file
@@ -0,0 +1,191 @@
|
|||||||
|
<p align="left">
|
||||||
|
<a href="README_CN.md">中文</a>  |  English
|
||||||
|
</p>
|
||||||
|
<br><br>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href='https://huggingface.co/spaces/zhichen'>
|
||||||
|
<img src='./images/logo.png'>
|
||||||
|
</a>
|
||||||
|
</p>
|
||||||
|
|
||||||
|
<div align="center">
|
||||||
|
<p align="center">
|
||||||
|
<h3> Llama3-Chinese </h3>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href='https://huggingface.co/zhichen'>
|
||||||
|
<img src='https://img.shields.io/badge/%F0%9F%A4%97%20HuggingFace-Llama3%20Chinese-yellow'>
|
||||||
|
</a>
|
||||||
|
<a href='https://modelscope.cn/profile/seanzhang'>
|
||||||
|
<img src='https://img.shields.io/badge/🤖 ModelScope-Llama3%20Chinese-blue'>
|
||||||
|
</a>
|
||||||
|
<br>
|
||||||
|
<a href=href="https://github.com/seanzhang-zhichen/llama3-chinese/stargazers">
|
||||||
|
<img src="https://img.shields.io/github/stars/seanzhang-zhichen/llama3-chinese?color=ccf">
|
||||||
|
</a>
|
||||||
|
<a href="https://github.com/seanzhang-zhichen/llama3-chinese/blob/main/LICENSE">
|
||||||
|
<img alt="GitHub Contributors" src="https://img.shields.io/badge/license-Apache%202.0-blue.svg" />
|
||||||
|
</a>
|
||||||
|
</p>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
## Introduce
|
||||||
|
|
||||||
|
**Llama3-Chinese** is a large model trained on 500k high-quality Chinese multi-turn SFT data, 100k English multi-turn SFT data, and 2k single-turn self-cognition data, using the training methods of [DORA](https://arxiv.org/pdf/2402.09353.pdf) and [LORA+](https://arxiv.org/pdf/2402.12354.pdf) based on **Meta-Llama-3-8B** as the base.
|
||||||
|
|
||||||
|
**Github:** [https://github.com/seanzhang-zhichen/llama3-chinese.git](https://github.com/seanzhang-zhichen/llama3-chinese.git)
|
||||||
|
|
||||||
|

|
||||||
|
|
||||||
|
|
||||||
|
## Download Model
|
||||||
|
|
||||||
|
|
||||||
|
| Model | Download |
|
||||||
|
|:-------------------:|:-----------:|
|
||||||
|
| Meta-Llama-3-8B |[ 🤗 HuggingFace](https://huggingface.co/meta-llama/Meta-Llama-3-8B) [ 🤖 ModelScope](https://modelscope.cn/models/LLM-Research/Meta-Llama-3-8B)|
|
||||||
|
| Llama3-Chinese-Lora |[ 🤗 HuggingFace](https://huggingface.co/zhichen/Llama3-Chinese-Lora) [ 🤖 ModelScope](https://modelscope.cn/models/seanzhang/Llama3-Chinese-Lora)|
|
||||||
|
| Llama3-Chinese (merged model) |[ 🤗 HuggingFace](https://huggingface.co/zhichen/Llama3-Chinese) [ 🤖 ModelScope](https://modelscope.cn/models/seanzhang/Llama3-Chinese)|
|
||||||
|
|
||||||
|
|
||||||
|
## Merge LORA Model (Skippable)
|
||||||
|
|
||||||
|
1、Download [Meta-Llama-3-8B](https://modelscope.cn/models/LLM-Research/Meta-Llama-3-8B)
|
||||||
|
|
||||||
|
```bash
|
||||||
|
git clone https://www.modelscope.cn/LLM-Research/Meta-Llama-3-8B.git
|
||||||
|
```
|
||||||
|
|
||||||
|
2、Download [Llama3-Chinese-Lora](https://www.modelscope.cn/models/seanzhang/Llama3-Chinese-Lora)
|
||||||
|
|
||||||
|
**From ModelScope**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://www.modelscope.cn/seanzhang/Llama3-Chinese-Lora.git
|
||||||
|
|
||||||
|
```
|
||||||
|
|
||||||
|
**From HuggingFace**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://huggingface.co/zhichen/Llama3-Chinese-Lora
|
||||||
|
```
|
||||||
|
|
||||||
|
3、Merge Model
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python merge_lora.py \
|
||||||
|
--base_model path/to/Meta-Llama-3-8B \
|
||||||
|
--lora_model path/to/lora/Llama3-Chinese-Lora \
|
||||||
|
--output_dir ./Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## Download Llama3-Chinese (Merged Model)
|
||||||
|
|
||||||
|
**From ModelScope**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://www.modelscope.cn/seanzhang/Llama3-Chinese.git
|
||||||
|
```
|
||||||
|
|
||||||
|
**From HuggingFace**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://huggingface.co/zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
## Inference
|
||||||
|
|
||||||
|
```python
|
||||||
|
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||||
|
|
||||||
|
model_id = "zhichen/Llama3-Chinese"
|
||||||
|
|
||||||
|
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
||||||
|
model = AutoModelForCausalLM.from_pretrained(model_id, torch_dtype="auto", device_map="auto")
|
||||||
|
|
||||||
|
messages = [
|
||||||
|
{"role": "system", "content": "You are a helpful assistant."},
|
||||||
|
{"role": "user", "content": "你好"},
|
||||||
|
]
|
||||||
|
|
||||||
|
input_ids = tokenizer.apply_chat_template(
|
||||||
|
messages, add_generation_prompt=True, return_tensors="pt"
|
||||||
|
).to(model.device)
|
||||||
|
|
||||||
|
outputs = model.generate(
|
||||||
|
input_ids,
|
||||||
|
max_new_tokens=2048,
|
||||||
|
do_sample=True,
|
||||||
|
temperature=0.7,
|
||||||
|
top_p=0.95,
|
||||||
|
)
|
||||||
|
response = outputs[0][input_ids.shape[-1]:]
|
||||||
|
print(tokenizer.decode(response, skip_special_tokens=True))
|
||||||
|
```
|
||||||
|
|
||||||
|
## CLI DEMO
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python cli_demo.py --model_path zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
## WEB DEMO
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python web_demo.py --model_path zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## VLLM WEB DEMO
|
||||||
|
|
||||||
|
1、Use [vllm](https://github.com/vllm-project/vllm) deploy model
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python -m vllm.entrypoints.openai.api_server --served-model-name Llama3-Chinese --model ./Llama3-Chinese(Replace it with your own merged model path)
|
||||||
|
```
|
||||||
|
|
||||||
|
2、This command is executed on the CLI
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python vllm_web_demo.py --model Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
## Train Dataset
|
||||||
|
|
||||||
|
[deepctrl-sft-data](https://modelscope.cn/datasets/deepctrl/deepctrl-sft-data)
|
||||||
|
|
||||||
|
|
||||||
|
## LICENSE
|
||||||
|
|
||||||
|
This project can only be used for research purposes, and the project developer shall not bear any harm or loss caused by the use of this project (including but not limited to data, models, codes, etc.). For details, please refer to [DISCLAIMER](https://github.com/seanzhang-zhichen/Llama3-Chinese/blob/main/DISCLAIMER)。
|
||||||
|
|
||||||
|
The License agreement of the Llama3-Chinese project code is the [Apache License 2.0](./LICENSE). The code is free for commercial use, and the model weights and data can only be used for research purposes. Please attach a link to Llama3-Chinese and the licensing agreement in the product description.
|
||||||
|
|
||||||
|
|
||||||
|
## Citation
|
||||||
|
|
||||||
|
If you used Llama3-Chinese in your research, cite it in the following format:
|
||||||
|
|
||||||
|
|
||||||
|
```latex
|
||||||
|
@misc{Llama3-Chinese,
|
||||||
|
title={Llama3-Chinese},
|
||||||
|
author={Zhichen Zhang, Xin LU, Long Chen},
|
||||||
|
year={2024},
|
||||||
|
howpublished={\url{https://github.com/seanzhang-zhichen/llama3-chinese}},
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
## Acknowledgement
|
||||||
|
|
||||||
|
[meta-llama/llama3](https://github.com/meta-llama/llama3)
|
||||||
|
<br>
|
||||||
|
[hiyouga/LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory)
|
||||||
|
|
||||||
|
|
||||||
|
## Star History
|
||||||
|
|
||||||
|
[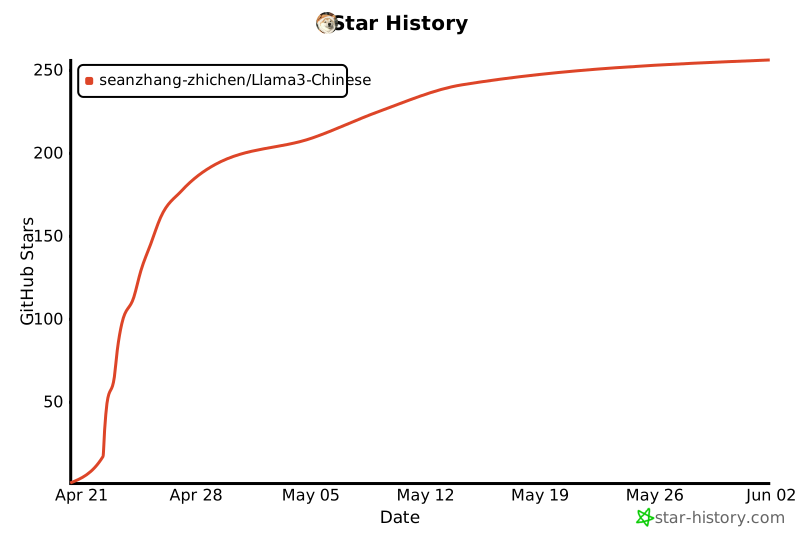](https://star-history.com/#seanzhang-zhichen/Llama3-Chinese&Date)
|
||||||
195
README_CN.md
Normal file
195
README_CN.md
Normal file
@@ -0,0 +1,195 @@
|
|||||||
|
<p align="left">
|
||||||
|
中文</a>  |  <a href="README.md">English</a>
|
||||||
|
</p>
|
||||||
|
<br><br>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href='https://huggingface.co/spaces/zhichen'>
|
||||||
|
<img src='./images/logo.png'>
|
||||||
|
</a>
|
||||||
|
</p>
|
||||||
|
|
||||||
|
<div align="center">
|
||||||
|
<p align="center">
|
||||||
|
<h3> Llama3-Chinese </h3>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href='https://huggingface.co/zhichen'>
|
||||||
|
<img src='https://img.shields.io/badge/%F0%9F%A4%97%20HuggingFace-Llama3%20Chinese-yellow'>
|
||||||
|
</a>
|
||||||
|
<a href='https://modelscope.cn/profile/seanzhang'>
|
||||||
|
<img src='https://img.shields.io/badge/🤖 ModelScope-Llama3%20Chinese-blue'>
|
||||||
|
</a>
|
||||||
|
<br>
|
||||||
|
<a href=href="https://github.com/seanzhang-zhichen/llama3-chinese/stargazers">
|
||||||
|
<img src="https://img.shields.io/github/stars/seanzhang-zhichen/llama3-chinese?color=ccf">
|
||||||
|
</a>
|
||||||
|
<a href="https://github.com/seanzhang-zhichen/llama3-chinese/blob/main/LICENSE">
|
||||||
|
<img alt="GitHub Contributors" src="https://img.shields.io/badge/license-Apache%202.0-blue.svg" />
|
||||||
|
</a>
|
||||||
|
</p>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
## 介绍
|
||||||
|
|
||||||
|
**Llama3-Chinese**是**以Meta-Llama-3-8B为底座**,使用 [DORA](https://arxiv.org/pdf/2402.09353.pdf) + [LORA+](https://arxiv.org/pdf/2402.12354.pdf) 的训练方法,在50w高质量中文多轮SFT数据 + 10w英文多轮SFT数据 + 2000单轮自我认知数据训练而来的大模型。
|
||||||
|
|
||||||
|
**Github:** [https://github.com/seanzhang-zhichen/llama3-chinese.git](https://github.com/seanzhang-zhichen/llama3-chinese.git)
|
||||||
|
|
||||||
|

|
||||||
|
|
||||||
|
|
||||||
|
## 模型下载
|
||||||
|
|
||||||
|
| Model | Download |
|
||||||
|
|:-------------------:|:-----------:|
|
||||||
|
| Meta-Llama-3-8B |[ 🤗 HuggingFace](https://huggingface.co/meta-llama/Meta-Llama-3-8B) [ 🤖 ModelScope](https://modelscope.cn/models/LLM-Research/Meta-Llama-3-8B)|
|
||||||
|
| Llama3-Chinese-Lora |[ 🤗 HuggingFace](https://huggingface.co/zhichen/Llama3-Chinese-Lora) [ 🤖 ModelScope](https://modelscope.cn/models/seanzhang/Llama3-Chinese-Lora)|
|
||||||
|
| Llama3-Chinese (合并好的模型) |[ 🤗 HuggingFace](https://huggingface.co/zhichen/Llama3-Chinese) [ 🤖 ModelScope](https://modelscope.cn/models/seanzhang/Llama3-Chinese)|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
## 合并LORA模型(可跳过)
|
||||||
|
|
||||||
|
1、下载 [Meta-Llama-3-8B](https://modelscope.cn/models/LLM-Research/Meta-Llama-3-8B)
|
||||||
|
|
||||||
|
```bash
|
||||||
|
git clone https://www.modelscope.cn/LLM-Research/Meta-Llama-3-8B.git
|
||||||
|
```
|
||||||
|
|
||||||
|
2、下载[Llama3-Chinese-Lora](https://www.modelscope.cn/models/seanzhang/Llama3-Chinese-Lora)
|
||||||
|
|
||||||
|
**From ModelScope**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://www.modelscope.cn/seanzhang/Llama3-Chinese-Lora.git
|
||||||
|
```
|
||||||
|
|
||||||
|
**From HuggingFace**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://huggingface.co/zhichen/Llama3-Chinese-Lora
|
||||||
|
```
|
||||||
|
|
||||||
|
3、合并模型
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python merge_lora.py \
|
||||||
|
--base_model path/to/Meta-Llama-3-8B \
|
||||||
|
--lora_model path/to/lora/Llama3-Chinese-Lora \
|
||||||
|
--output_dir ./Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
## 下载 Llama3-Chinese(合并好的模型)
|
||||||
|
|
||||||
|
**From ModelScope**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://www.modelscope.cn/seanzhang/Llama3-Chinese.git
|
||||||
|
```
|
||||||
|
|
||||||
|
**From HuggingFace**
|
||||||
|
```bash
|
||||||
|
git lfs install
|
||||||
|
git clone https://huggingface.co/zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## 推理
|
||||||
|
|
||||||
|
```python
|
||||||
|
from transformers import AutoTokenizer, AutoModelForCausalLM
|
||||||
|
|
||||||
|
model_id = "zhichen/Llama3-Chinese"
|
||||||
|
|
||||||
|
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
||||||
|
model = AutoModelForCausalLM.from_pretrained(model_id, torch_dtype="auto", device_map="auto")
|
||||||
|
|
||||||
|
messages = [
|
||||||
|
{"role": "system", "content": "You are a helpful assistant."},
|
||||||
|
{"role": "user", "content": "你好"},
|
||||||
|
]
|
||||||
|
|
||||||
|
input_ids = tokenizer.apply_chat_template(
|
||||||
|
messages, add_generation_prompt=True, return_tensors="pt"
|
||||||
|
).to(model.device)
|
||||||
|
|
||||||
|
outputs = model.generate(
|
||||||
|
input_ids,
|
||||||
|
max_new_tokens=2048,
|
||||||
|
do_sample=True,
|
||||||
|
temperature=0.7,
|
||||||
|
top_p=0.95,
|
||||||
|
)
|
||||||
|
response = outputs[0][input_ids.shape[-1]:]
|
||||||
|
print(tokenizer.decode(response, skip_special_tokens=True))
|
||||||
|
```
|
||||||
|
|
||||||
|
## 命令行推理
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python cli_demo.py --model_path zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
## web推理
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python web_demo.py --model_path zhichen/Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## vllm web 推理
|
||||||
|
|
||||||
|
1、使用[vllm](https://github.com/vllm-project/vllm)部署模型
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python -m vllm.entrypoints.openai.api_server --served-model-name Llama3-Chinese --model ./Llama3-Chinese(换成你自己的合并后的模型路径)
|
||||||
|
```
|
||||||
|
|
||||||
|
2、在命令行执行
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python vllm_web_demo.py --model Llama3-Chinese
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
## 训练数据集
|
||||||
|
|
||||||
|
[匠数科技大模型sft数据集](https://modelscope.cn/datasets/deepctrl/deepctrl-sft-data)
|
||||||
|
|
||||||
|
|
||||||
|
## LICENSE
|
||||||
|
|
||||||
|
本项目仅可应用于研究目的,项目开发者不承担任何因使用本项目(包含但不限于数据、模型、代码等)导致的危害或损失。详细请参考[免责声明](https://github.com/seanzhang-zhichen/Llama3-Chinese/blob/main/DISCLAIMER)。
|
||||||
|
|
||||||
|
Llama3-Chinese项目代码的授权协议为 [The Apache License 2.0](./LICENSE),代码可免费用做商业用途,模型权重和数据只能用于研究目的。请在产品说明中附加Llama3-Chinese的链接和授权协议。
|
||||||
|
|
||||||
|
## Citation
|
||||||
|
|
||||||
|
如果你在研究中使用了Llama3-Chinese,请按如下格式引用:
|
||||||
|
|
||||||
|
```latex
|
||||||
|
@misc{Llama3-Chinese,
|
||||||
|
title={Llama3-Chinese},
|
||||||
|
author={Zhichen Zhang, Xin LU, Long Chen},
|
||||||
|
year={2024},
|
||||||
|
howpublished={\url{https://github.com/seanzhang-zhichen/llama3-chinese}},
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
## Acknowledgement
|
||||||
|
|
||||||
|
[meta-llama/llama3](https://github.com/meta-llama/llama3)
|
||||||
|
<br>
|
||||||
|
[hiyouga/LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory)
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
## Star History
|
||||||
|
|
||||||
|
[](https://star-history.com/#seanzhang-zhichen/Llama3-Chinese&Date)
|
||||||
|
|
||||||
28
config.json
Normal file
28
config.json
Normal file
@@ -0,0 +1,28 @@
|
|||||||
|
{
|
||||||
|
"_name_or_path": "/root/data/model/llama/Meta-Llama-3-8B",
|
||||||
|
"architectures": [
|
||||||
|
"LlamaForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_bias": false,
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"bos_token_id": 128000,
|
||||||
|
"eos_token_id": 128001,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 4096,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 14336,
|
||||||
|
"max_position_embeddings": 8192,
|
||||||
|
"model_type": "llama",
|
||||||
|
"num_attention_heads": 32,
|
||||||
|
"num_hidden_layers": 32,
|
||||||
|
"num_key_value_heads": 8,
|
||||||
|
"pretraining_tp": 1,
|
||||||
|
"rms_norm_eps": 1e-05,
|
||||||
|
"rope_scaling": null,
|
||||||
|
"rope_theta": 500000.0,
|
||||||
|
"tie_word_embeddings": false,
|
||||||
|
"torch_dtype": "bfloat16",
|
||||||
|
"transformers_version": "4.39.3",
|
||||||
|
"use_cache": true,
|
||||||
|
"vocab_size": 128256
|
||||||
|
}
|
||||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"framework":"Pytorch","task":"text-generation"}
|
||||||
6
generation_config.json
Normal file
6
generation_config.json
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
{
|
||||||
|
"_from_model_config": true,
|
||||||
|
"bos_token_id": 128000,
|
||||||
|
"eos_token_id": 128001,
|
||||||
|
"transformers_version": "4.39.3"
|
||||||
|
}
|
||||||
BIN
images/logo.png
Normal file
BIN
images/logo.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 169 KiB |
BIN
images/web_demo.png
Normal file
BIN
images/web_demo.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 62 KiB |
3
model-00001-of-00005.safetensors
Normal file
3
model-00001-of-00005.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:0edb0bdbfd21c42a1de857950d96bea501a5d6b73ae58835ce04c1e0fa3832dd
|
||||||
|
size 3986791344
|
||||||
3
model-00002-of-00005.safetensors
Normal file
3
model-00002-of-00005.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:f664377e78609768b45d782d8cd300008e41cb3ef14c49bc109099853c8eb9a0
|
||||||
|
size 3926025416
|
||||||
3
model-00003-of-00005.safetensors
Normal file
3
model-00003-of-00005.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:48d08b65e0428ae71a24fee4d037d4f73ef22265af4fd9bdd2170e04a2b3fbb5
|
||||||
|
size 3926025440
|
||||||
3
model-00004-of-00005.safetensors
Normal file
3
model-00004-of-00005.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:92971b5233f4f1dfba8c029b1dc40806db51ad1eb63a964cb807bca94096a006
|
||||||
|
size 3171040864
|
||||||
3
model-00005-of-00005.safetensors
Normal file
3
model-00005-of-00005.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:7c5394fe848f6eafef2a44f085e7b72e5ef0d315f98aa87b3827c2b1e6983b89
|
||||||
|
size 1050673280
|
||||||
298
model.safetensors.index.json
Normal file
298
model.safetensors.index.json
Normal file
@@ -0,0 +1,298 @@
|
|||||||
|
{
|
||||||
|
"metadata": {
|
||||||
|
"total_size": 16060522496
|
||||||
|
},
|
||||||
|
"weight_map": {
|
||||||
|
"lm_head.weight": "model-00005-of-00005.safetensors",
|
||||||
|
"model.embed_tokens.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.10.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.10.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.11.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.12.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.13.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.14.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.15.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.15.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.15.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.15.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.16.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.16.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.17.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.18.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.19.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.2.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.20.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.20.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.21.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.22.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.input_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.mlp.down_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.post_attention_layernorm.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.23.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.24.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.24.mlp.gate_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.mlp.up_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.24.self_attn.k_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.self_attn.o_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.self_attn.q_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.24.self_attn.v_proj.weight": "model-00003-of-00005.safetensors",
|
||||||
|
"model.layers.25.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.25.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.26.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.27.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.28.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.29.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.3.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.30.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.30.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.input_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.mlp.down_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.mlp.gate_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.mlp.up_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.post_attention_layernorm.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.self_attn.k_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.self_attn.o_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.self_attn.q_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.31.self_attn.v_proj.weight": "model-00004-of-00005.safetensors",
|
||||||
|
"model.layers.4.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.input_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.post_attention_layernorm.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.6.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.6.mlp.gate_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00005.safetensors",
|
||||||
|
"model.layers.7.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.7.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.8.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.input_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.mlp.down_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.mlp.gate_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.mlp.up_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.post_attention_layernorm.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.self_attn.k_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.self_attn.o_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.self_attn.q_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.layers.9.self_attn.v_proj.weight": "model-00002-of-00005.safetensors",
|
||||||
|
"model.norm.weight": "model-00004-of-00005.safetensors"
|
||||||
|
}
|
||||||
|
}
|
||||||
17
special_tokens_map.json
Normal file
17
special_tokens_map.json
Normal file
@@ -0,0 +1,17 @@
|
|||||||
|
{
|
||||||
|
"bos_token": {
|
||||||
|
"content": "<|begin_of_text|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"eos_token": {
|
||||||
|
"content": "<|end_of_text|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"pad_token": "<|end_of_text|>"
|
||||||
|
}
|
||||||
410503
tokenizer.json
Normal file
410503
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
2065
tokenizer_config.json
Normal file
2065
tokenizer_config.json
Normal file
File diff suppressed because it is too large
Load Diff
Reference in New Issue
Block a user