初始化项目,由ModelHub XC社区提供模型
Model: mrm8488/GPT-2-finetuned-covid-bio-medrxiv
Source: Original Platform
This commit is contained in:
 ModelHub XC
9
.gitattributes
vendored
Normal file
9
.gitattributes
vendored
Normal file
@@ -0,0 +1,9 @@
|
|||||||
|
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
52
README.md
Normal file
52
README.md
Normal file
@@ -0,0 +1,52 @@
|
|||||||
|
---
|
||||||
|
language: en
|
||||||
|
thumbnail:
|
||||||
|
widget:
|
||||||
|
- text: "Old people with COVID-19 tends to suffer"
|
||||||
|
---
|
||||||
|
|
||||||
|
# GPT-2 + bio/medrxiv files from CORD19: 🦠 ✍ ⚕
|
||||||
|
|
||||||
|
**GPT-2** fine-tuned on **biorxiv_medrxiv** files from [CORD-19](https://www.kaggle.com/allen-institute-for-ai/CORD-19-research-challenge) dataset.
|
||||||
|
|
||||||
|
|
||||||
|
## Datasets details:
|
||||||
|
|
||||||
|
| Dataset | # Files |
|
||||||
|
| ---------------------- | ----- |
|
||||||
|
| biorxiv_medrxiv | 885 |
|
||||||
|
|
||||||
|
|
||||||
|
## Model training:
|
||||||
|
|
||||||
|
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
|
||||||
|
export TRAIN_FILE=/path/to/dataset/train.txt
|
||||||
|
|
||||||
|
python run_language_modeling.py \\n --model_type gpt2 \\n --model_name_or_path gpt2 \\n --do_train \\n --train_data_file $TRAIN_FILE \\n --num_train_epochs 4 \\n --output_dir model_output \\n --overwrite_output_dir \\n --save_steps 2000 \\n --per_gpu_train_batch_size 3
|
||||||
|
```
|
||||||
|
|
||||||
|
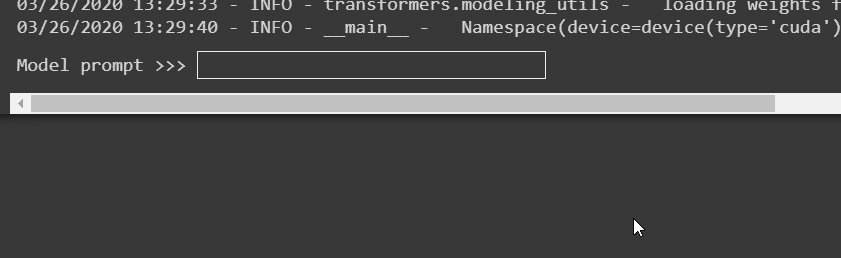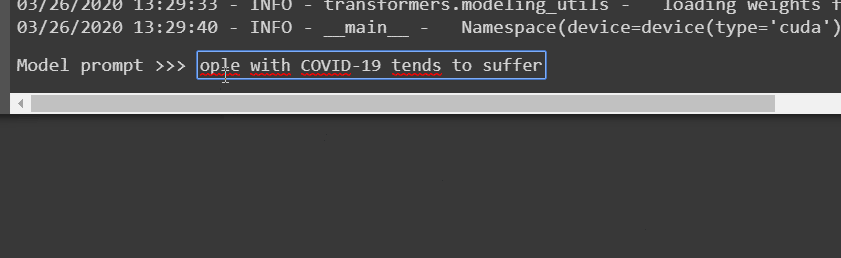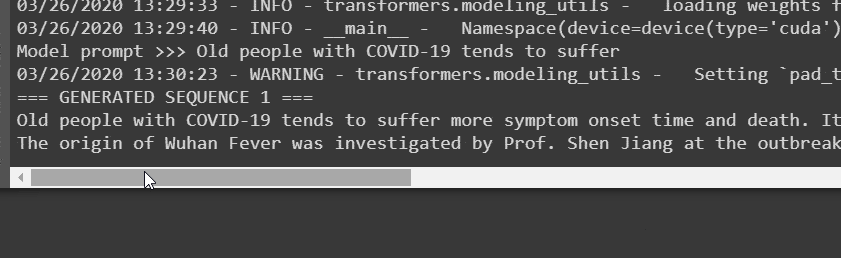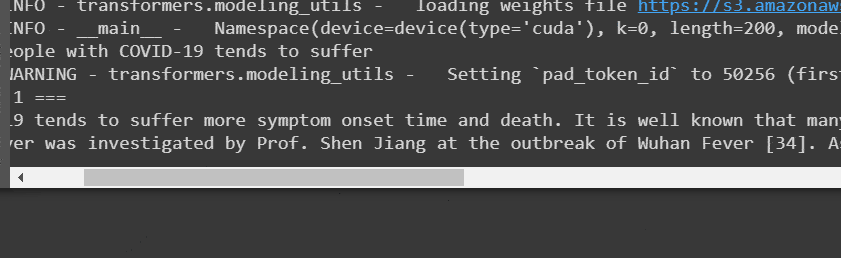
## Model in action / Example of usage: ✒
|
||||||
|
|
||||||
|
You can get the following script [here](https://github.com/huggingface/transformers/blob/master/examples/text-generation/run_generation.py)
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python run_generation.py \\n --model_type gpt2 \\n --model_name_or_path mrm8488/GPT-2-finetuned-CORD19 \\n --length 200
|
||||||
|
```
|
||||||
|
```txt
|
||||||
|
👵👴🦠
|
||||||
|
# Input: Old people with COVID-19 tends to suffer
|
||||||
|
# Output: === GENERATED SEQUENCE 1 ===
|
||||||
|
Old people with COVID-19 tends to suffer more symptom onset time and death. It is well known that many people with COVID-19 have high homozygous ZIKV infection in the face of severe symptoms in both severe and severe cases.
|
||||||
|
The origin of Wuhan Fever was investigated by Prof. Shen Jiang at the outbreak of Wuhan Fever [34]. As Huanan Province is the epicenter of this outbreak, Huanan, the epicenter of epidemic Wuhan Fever, is the most potential location for the direct transmission of infection (source: Zhongzhen et al., 2020). A negative risk ratio indicates more frequent underlying signs in the people in Huanan Province with COVID-19 patients. Further analysis of reported Huanan Fever onset data in the past two years indicated that the intensity of exposure is the key risk factor for developing MERS-CoV infection in this region, especially among children and elderly. To be continued to develop infected patients would be a very important area for
|
||||||
|
```
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||||
|
|
||||||
|
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||||
26
config.json
Normal file
26
config.json
Normal file
@@ -0,0 +1,26 @@
|
|||||||
|
{
|
||||||
|
"activation_function": "gelu_new",
|
||||||
|
"architectures": [
|
||||||
|
"GPT2LMHeadModel"
|
||||||
|
],
|
||||||
|
"attn_pdrop": 0.1,
|
||||||
|
"bos_token_id": 50256,
|
||||||
|
"embd_pdrop": 0.1,
|
||||||
|
"eos_token_id": 50256,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"layer_norm_epsilon": 1e-05,
|
||||||
|
"model_type": "gpt2",
|
||||||
|
"n_ctx": 1024,
|
||||||
|
"n_embd": 768,
|
||||||
|
"n_head": 12,
|
||||||
|
"n_layer": 12,
|
||||||
|
"n_positions": 1024,
|
||||||
|
"output_past": true,
|
||||||
|
"resid_pdrop": 0.1,
|
||||||
|
"summary_activation": null,
|
||||||
|
"summary_first_dropout": 0.1,
|
||||||
|
"summary_proj_to_labels": true,
|
||||||
|
"summary_type": "cls_index",
|
||||||
|
"summary_use_proj": true,
|
||||||
|
"vocab_size": 50257
|
||||||
|
}
|
||||||
3
flax_model.msgpack
Normal file
3
flax_model.msgpack
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:9c1eba88ee680ea1c6d73c3f391ff9efae4ed808263a9e24567dcacffa802ab8
|
||||||
|
size 497764120
|
||||||
50001
merges.txt
Normal file
50001
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
3
pytorch_model.bin
Normal file
3
pytorch_model.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:bf8f734a476855cdcd57b2ccaa2e6dc3f1d8ee0e7c330daf9c77e6953f73a0d5
|
||||||
|
size 548123884
|
||||||
1
special_tokens_map.json
Normal file
1
special_tokens_map.json
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}
|
||||||
1
tokenizer_config.json
Normal file
1
tokenizer_config.json
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"max_len": 1024}
|
||||||
3
training_args.bin
Normal file
3
training_args.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:9b5f6dd2d58b8ffd5eeae77de59f14ed59e1747616a9924869a911a68f44fcf5
|
||||||
|
size 1228
|
||||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user