初始化项目,由ModelHub XC社区提供模型
Model: kitsdk/bonito-chinese-v1
Source: Original Platform
This commit is contained in:
 ModelHub XC
1
.cache/huggingface/.gitignore
vendored
Normal file
1
.cache/huggingface/.gitignore
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
*
|
||||||
3
.cache/huggingface/download/.gitattributes.metadata
Normal file
3
.cache/huggingface/download/.gitattributes.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
a6344aac8c09253b3b630fb776ae94478aa0275b
|
||||||
|
1739428077.8711479
|
||||||
3
.cache/huggingface/download/added_tokens.json.metadata
Normal file
3
.cache/huggingface/download/added_tokens.json.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
482ced4679301bf287ebb310bdd1790eb4514232
|
||||||
|
1739428077.896147
|
||||||
3
.cache/huggingface/download/config.json.metadata
Normal file
3
.cache/huggingface/download/config.json.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
491622a51e0bb52f701ebb11f3bcbd92974c5311
|
||||||
|
1739428079.4770932
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
1b23b70fa0eabcdd1dc2099c9c3a5e67e2e5022f
|
||||||
|
1739428082.2493896
|
||||||
3
.cache/huggingface/download/merges.txt.metadata
Normal file
3
.cache/huggingface/download/merges.txt.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
31349551d90c7606f325fe0f11bbb8bd5fa0d7c7
|
||||||
|
1739428079.4885063
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
7ec20556b6133f54a86230f2460147b35234df28db20b8eabb3a7906865e3ad2
|
||||||
|
1739428997.3825617
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
14203c1f78c261cf250aaa67fca3d80129e1e984f738dff7d32ba27c54e3ab19
|
||||||
|
1739429069.8379316
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
e2d276af00db709f5d3678e1b3baa1664c982787bc445916e6d8b64dd826cb69
|
||||||
|
1739429055.8835785
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
8979e99f148b35c1bb32011193b9d823314a1aeefd99df2195291ddda7b64d25
|
||||||
|
1739429079.0143988
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
30275a1c2a77280b83758836faf1a8d03ac8493f7cd432fa181fd321c580e451
|
||||||
|
1739429058.8485725
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
0c976c06a4aeb37e61f0b25def4d5f12f80254af24d8d9d8bb0a1a85accd64b2
|
||||||
|
1739429077.0800521
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
9115567544665140923981b227d61d96a8f906c1a136b43b131e3bc83ec59364
|
||||||
|
1739428523.4205244
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
5c74a4af8cca10d0ee98febb73250856fadcdd9c
|
||||||
|
1739428082.8352613
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
17305b3603dfb19ccc0f658ec2cd2cd3adff4a58
|
||||||
|
1739428085.3138757
|
||||||
3
.cache/huggingface/download/tokenizer.json.metadata
Normal file
3
.cache/huggingface/download/tokenizer.json.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
450c878a19e58fd31cdd5f99d9fea007e0d29771
|
||||||
|
1739428105.948357
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
406693560f41adf6f5f08bb8148407a8bc2c598c
|
||||||
|
1739428107.0251818
|
||||||
3
.cache/huggingface/download/vocab.json.metadata
Normal file
3
.cache/huggingface/download/vocab.json.metadata
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
3fb44fdc1f5aded39e160de6f5c467311ff9dabd
|
||||||
|
4783fe10ac3adce15ac8f358ef5462739852c569
|
||||||
|
1739428119.354553
|
||||||
49
.gitattributes
vendored
Normal file
49
.gitattributes
vendored
Normal file
@@ -0,0 +1,49 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||||
|
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gguf* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ggml filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.llamafile* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
|
||||||
|
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||||
67
README.md
Normal file
67
README.md
Normal file
@@ -0,0 +1,67 @@
|
|||||||
|
---
|
||||||
|
license: apache-2.0
|
||||||
|
datasets:
|
||||||
|
- kitsdk/ctga-v1-1w-chinese
|
||||||
|
base_model:
|
||||||
|
- Qwen/Qwen2.5-3B
|
||||||
|
tasks:
|
||||||
|
- text-generation
|
||||||
|
- question-answering
|
||||||
|
- text-ranking
|
||||||
|
frameworks: PyTorch
|
||||||
|
language:
|
||||||
|
- zh
|
||||||
|
base_model_relation: finetune
|
||||||
|
---
|
||||||
|
# Bonito(支持中文版本)
|
||||||
|
|
||||||
|
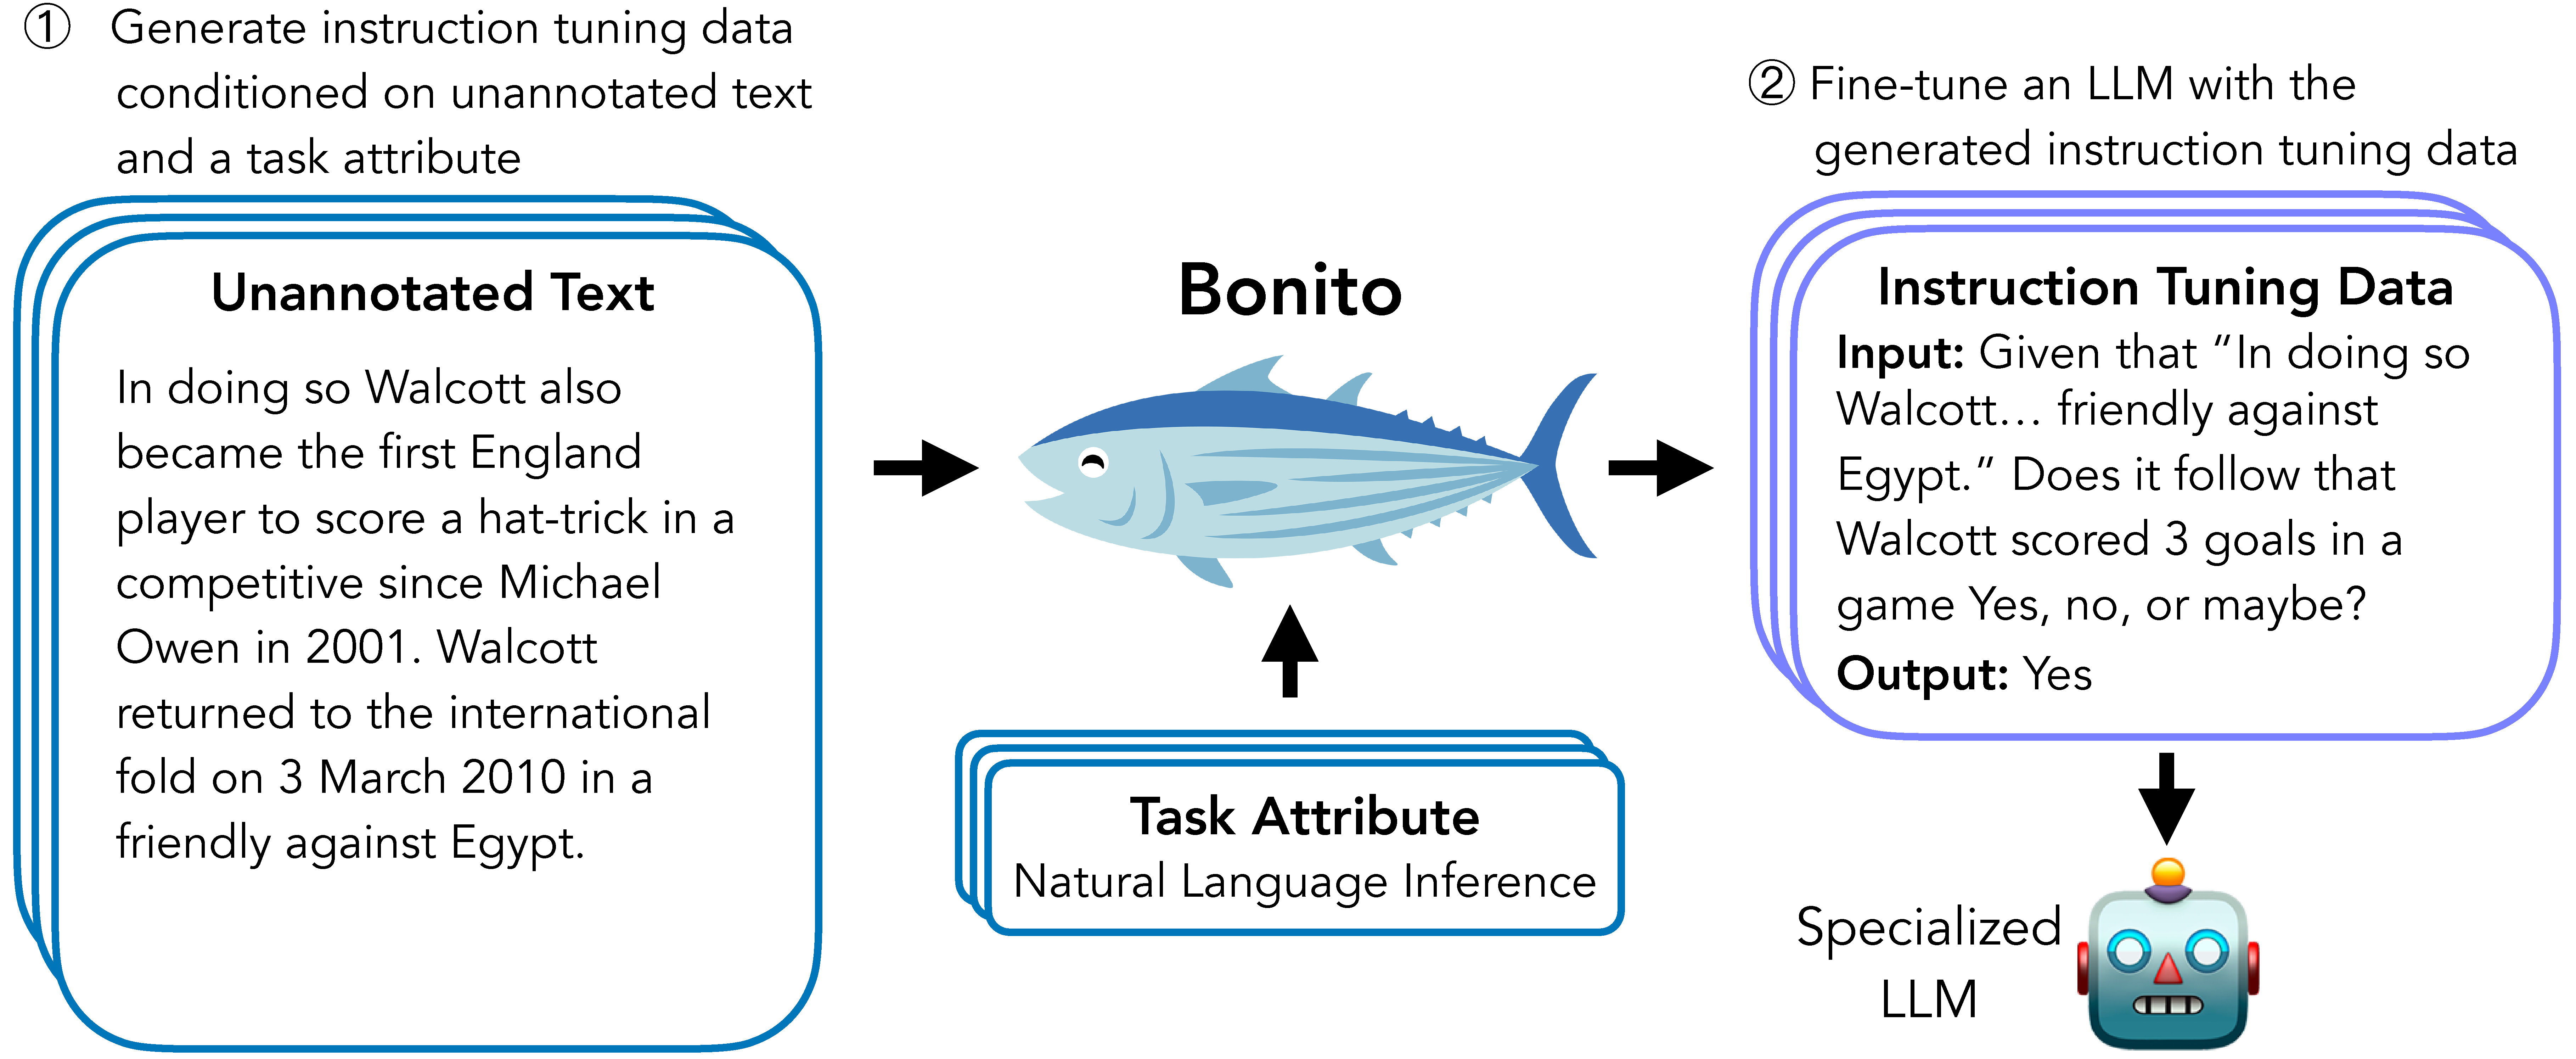
Bonito is an open-source model for conditional task generation: the task of converting unannotated text into task-specific training datasets for instruction tuning. This repo is a lightweight library for Bonito to easily create synthetic datasets built on top of the Hugging Face `transformers` and `vllm` libraries.
|
||||||
|
|
||||||
|
- Paper: [Learning to Generate Instruction Tuning Datasets for
|
||||||
|
Zero-Shot Task Adaptation](https://arxiv.org/abs/2402.18334)
|
||||||
|
- Model: [bonito-v1](https://huggingface.co/BatsResearch/bonito-v1)(English)
|
||||||
|
- Model: [bonito-chinese-v1](https://huggingface.co/kitsdk/bonito-chinese-v1)(中文)
|
||||||
|
- Demo: [Bonito on Spaces](https://huggingface.co/spaces/nihalnayak/bonito)(English)
|
||||||
|
- Demo: [Google Colab](https://colab.research.google.com/drive/1vZ78RFywM1pkuGpxGWGLude_L2XZ5wpw?usp=sharing)(中文)
|
||||||
|
- Dataset: [ctga-v1](https://huggingface.co/datasets/BatsResearch/ctga-v1)(English)
|
||||||
|
- Code: To reproduce experiments in our paper, see [nayak-aclfindings24-code](https://github.com/BatsResearch/nayak-aclfindings24-code).
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
## This version supports the Chinese language
|
||||||
|
Because of the training data limitations, this version supports only the 3 task types
|
||||||
|
- 🐠 1.question generation.
|
||||||
|
- 🐡 2.multiple-choice question answering.
|
||||||
|
- 🐟 3.question answering without choices.
|
||||||
|
## Google Colab: [Demo](https://colab.research.google.com/drive/1vZ78RFywM1pkuGpxGWGLude_L2XZ5wpw?usp=sharing)
|
||||||
|
## Basic Usage
|
||||||
|
To generate synthetic instruction tuning dataset using Bonito, you can use the following code:
|
||||||
|
pip3 install bonito-llm
|
||||||
|
```python
|
||||||
|
from pprint import pprint
|
||||||
|
from datasets import Dataset
|
||||||
|
from vllm import SamplingParams
|
||||||
|
from transformers import set_seed
|
||||||
|
from bonito import Bonito
|
||||||
|
|
||||||
|
unannotated_paragraph = """灌区以往的闸门控制系统在实际应用过程中普遍以人工操作为主,容易受到多种因素的影响,不可避免出现较多缺陷。如操作人员自身的综合能力、业务水平、工作态度等对工作质量和效率产生较大影响;工作人员实践操作中遇到极端气候、工作环境恶劣等问题,大大增加了工作难度,并存在较多安全隐患。"""
|
||||||
|
pprint(unannotated_paragraph)
|
||||||
|
bonito = Bonito("kitsdk/bonito-chinese-v1")
|
||||||
|
set_seed(2)
|
||||||
|
|
||||||
|
def convert_to_dataset(text):
|
||||||
|
dataset = Dataset.from_list([{"input": text}])
|
||||||
|
return dataset
|
||||||
|
|
||||||
|
sampling_params = SamplingParams(max_tokens=256, top_p=0.95, temperature=0.5, n=1)
|
||||||
|
synthetic_dataset = bonito.generate_tasks(
|
||||||
|
convert_to_dataset(unannotated_paragraph),
|
||||||
|
context_col="input",
|
||||||
|
task_type="mcqa",
|
||||||
|
sampling_params=sampling_params
|
||||||
|
)
|
||||||
|
pprint("----Generated Instructions----")
|
||||||
|
pprint(f'Input: {synthetic_dataset[0]["input"]}')
|
||||||
|
pprint(f'Output: {synthetic_dataset[0]["output"]}')
|
||||||
|
```
|
||||||
24
added_tokens.json
Normal file
24
added_tokens.json
Normal file
@@ -0,0 +1,24 @@
|
|||||||
|
{
|
||||||
|
"</tool_call>": 151658,
|
||||||
|
"<tool_call>": 151657,
|
||||||
|
"<|box_end|>": 151649,
|
||||||
|
"<|box_start|>": 151648,
|
||||||
|
"<|endoftext|>": 151643,
|
||||||
|
"<|file_sep|>": 151664,
|
||||||
|
"<|fim_middle|>": 151660,
|
||||||
|
"<|fim_pad|>": 151662,
|
||||||
|
"<|fim_prefix|>": 151659,
|
||||||
|
"<|fim_suffix|>": 151661,
|
||||||
|
"<|im_end|>": 151645,
|
||||||
|
"<|im_start|>": 151644,
|
||||||
|
"<|image_pad|>": 151655,
|
||||||
|
"<|object_ref_end|>": 151647,
|
||||||
|
"<|object_ref_start|>": 151646,
|
||||||
|
"<|quad_end|>": 151651,
|
||||||
|
"<|quad_start|>": 151650,
|
||||||
|
"<|repo_name|>": 151663,
|
||||||
|
"<|video_pad|>": 151656,
|
||||||
|
"<|vision_end|>": 151653,
|
||||||
|
"<|vision_pad|>": 151654,
|
||||||
|
"<|vision_start|>": 151652
|
||||||
|
}
|
||||||
29
config.json
Normal file
29
config.json
Normal file
@@ -0,0 +1,29 @@
|
|||||||
|
{
|
||||||
|
"_name_or_path": "/root/.cache/modelscope/hub/Qwen/Qwen2.5-3B",
|
||||||
|
"architectures": [
|
||||||
|
"Qwen2ForCausalLM"
|
||||||
|
],
|
||||||
|
"attention_dropout": 0.0,
|
||||||
|
"bos_token_id": 151643,
|
||||||
|
"eos_token_id": 151643,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 2048,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 11008,
|
||||||
|
"max_position_embeddings": 32768,
|
||||||
|
"max_window_layers": 36,
|
||||||
|
"model_type": "qwen2",
|
||||||
|
"num_attention_heads": 16,
|
||||||
|
"num_hidden_layers": 36,
|
||||||
|
"num_key_value_heads": 2,
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"rope_theta": 1000000.0,
|
||||||
|
"sliding_window": 32768,
|
||||||
|
"tie_word_embeddings": true,
|
||||||
|
"torch_dtype": "float16",
|
||||||
|
"transformers_version": "4.37.2",
|
||||||
|
"use_cache": true,
|
||||||
|
"use_mrope": false,
|
||||||
|
"use_sliding_window": false,
|
||||||
|
"vocab_size": 151936
|
||||||
|
}
|
||||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"task":"other"}
|
||||||
6
generation_config.json
Normal file
6
generation_config.json
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
{
|
||||||
|
"bos_token_id": 151643,
|
||||||
|
"eos_token_id": 151643,
|
||||||
|
"max_new_tokens": 2048,
|
||||||
|
"transformers_version": "4.37.2"
|
||||||
|
}
|
||||||
151388
merges.txt
Normal file
151388
merges.txt
Normal file
File diff suppressed because it is too large
Load Diff
3
model-00001-of-00007.safetensors
Normal file
3
model-00001-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:7ec20556b6133f54a86230f2460147b35234df28db20b8eabb3a7906865e3ad2
|
||||||
|
size 994609768
|
||||||
3
model-00002-of-00007.safetensors
Normal file
3
model-00002-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:14203c1f78c261cf250aaa67fca3d80129e1e984f738dff7d32ba27c54e3ab19
|
||||||
|
size 970020792
|
||||||
3
model-00003-of-00007.safetensors
Normal file
3
model-00003-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:e2d276af00db709f5d3678e1b3baa1664c982787bc445916e6d8b64dd826cb69
|
||||||
|
size 988909544
|
||||||
3
model-00004-of-00007.safetensors
Normal file
3
model-00004-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:8979e99f148b35c1bb32011193b9d823314a1aeefd99df2195291ddda7b64d25
|
||||||
|
size 970020872
|
||||||
3
model-00005-of-00007.safetensors
Normal file
3
model-00005-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:30275a1c2a77280b83758836faf1a8d03ac8493f7cd432fa181fd321c580e451
|
||||||
|
size 970020864
|
||||||
3
model-00006-of-00007.safetensors
Normal file
3
model-00006-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:0c976c06a4aeb37e61f0b25def4d5f12f80254af24d8d9d8bb0a1a85accd64b2
|
||||||
|
size 988909552
|
||||||
3
model-00007-of-00007.safetensors
Normal file
3
model-00007-of-00007.safetensors
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:9115567544665140923981b227d61d96a8f906c1a136b43b131e3bc83ec59364
|
||||||
|
size 289434592
|
||||||
441
model.safetensors.index.json
Normal file
441
model.safetensors.index.json
Normal file
@@ -0,0 +1,441 @@
|
|||||||
|
{
|
||||||
|
"metadata": {
|
||||||
|
"total_size": 6171877376
|
||||||
|
},
|
||||||
|
"weight_map": {
|
||||||
|
"model.embed_tokens.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.input_layernorm.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.k_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.q_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.v_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.input_layernorm.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.k_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.q_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.v_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.10.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.10.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.11.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.12.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.13.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.14.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.15.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.15.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.15.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.15.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.15.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.16.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.16.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.17.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.18.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.19.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.2.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.2.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.2.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.k_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.q_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.v_proj.bias": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00007.safetensors",
|
||||||
|
"model.layers.20.input_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.mlp.down_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.mlp.up_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.post_attention_layernorm.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.20.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.21.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.21.mlp.gate_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.21.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.k_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.k_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.o_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.q_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.q_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.v_proj.bias": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.21.self_attn.v_proj.weight": "model-00004-of-00007.safetensors",
|
||||||
|
"model.layers.22.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.22.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.23.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.24.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.25.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.input_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.mlp.down_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.post_attention_layernorm.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.26.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.27.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.27.mlp.gate_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.mlp.up_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.k_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.k_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.o_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.q_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.q_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.v_proj.bias": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.27.self_attn.v_proj.weight": "model-00005-of-00007.safetensors",
|
||||||
|
"model.layers.28.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.28.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.29.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.3.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.3.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.30.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.30.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.31.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.32.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.input_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.mlp.down_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.mlp.gate_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.mlp.up_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.post_attention_layernorm.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.33.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.input_layernorm.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.34.mlp.down_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.34.mlp.gate_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.34.mlp.up_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.34.post_attention_layernorm.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.k_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.k_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.o_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.q_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.q_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.v_proj.bias": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.34.self_attn.v_proj.weight": "model-00006-of-00007.safetensors",
|
||||||
|
"model.layers.35.input_layernorm.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.mlp.down_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.mlp.gate_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.mlp.up_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.post_attention_layernorm.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.k_proj.bias": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.k_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.o_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.q_proj.bias": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.q_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.v_proj.bias": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.35.self_attn.v_proj.weight": "model-00007-of-00007.safetensors",
|
||||||
|
"model.layers.4.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.4.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.5.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.6.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.input_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.mlp.down_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.post_attention_layernorm.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.7.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.8.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.8.mlp.gate_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.mlp.up_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.k_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.k_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.o_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.q_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.q_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.v_proj.bias": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.8.self_attn.v_proj.weight": "model-00002-of-00007.safetensors",
|
||||||
|
"model.layers.9.input_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.mlp.down_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.mlp.gate_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.mlp.up_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.post_attention_layernorm.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.k_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.k_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.o_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.q_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.q_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.v_proj.bias": "model-00003-of-00007.safetensors",
|
||||||
|
"model.layers.9.self_attn.v_proj.weight": "model-00003-of-00007.safetensors",
|
||||||
|
"model.norm.weight": "model-00007-of-00007.safetensors"
|
||||||
|
}
|
||||||
|
}
|
||||||
31
special_tokens_map.json
Normal file
31
special_tokens_map.json
Normal file
@@ -0,0 +1,31 @@
|
|||||||
|
{
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"eos_token": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"pad_token": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
}
|
||||||
|
}
|
||||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:22bfef58b74d2fa40f402ac0c8d638d9e54d12137da2e2c7e9f32a1e7534e42f
|
||||||
|
size 7031645
|
||||||
207
tokenizer_config.json
Normal file
207
tokenizer_config.json
Normal file
@@ -0,0 +1,207 @@
|
|||||||
|
{
|
||||||
|
"add_bos_token": false,
|
||||||
|
"add_prefix_space": false,
|
||||||
|
"added_tokens_decoder": {
|
||||||
|
"151643": {
|
||||||
|
"content": "<|endoftext|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151644": {
|
||||||
|
"content": "<|im_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151645": {
|
||||||
|
"content": "<|im_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151646": {
|
||||||
|
"content": "<|object_ref_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151647": {
|
||||||
|
"content": "<|object_ref_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151648": {
|
||||||
|
"content": "<|box_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151649": {
|
||||||
|
"content": "<|box_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151650": {
|
||||||
|
"content": "<|quad_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151651": {
|
||||||
|
"content": "<|quad_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151652": {
|
||||||
|
"content": "<|vision_start|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151653": {
|
||||||
|
"content": "<|vision_end|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151654": {
|
||||||
|
"content": "<|vision_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151655": {
|
||||||
|
"content": "<|image_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151656": {
|
||||||
|
"content": "<|video_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": true
|
||||||
|
},
|
||||||
|
"151657": {
|
||||||
|
"content": "<tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151658": {
|
||||||
|
"content": "</tool_call>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151659": {
|
||||||
|
"content": "<|fim_prefix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151660": {
|
||||||
|
"content": "<|fim_middle|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151661": {
|
||||||
|
"content": "<|fim_suffix|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151662": {
|
||||||
|
"content": "<|fim_pad|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151663": {
|
||||||
|
"content": "<|repo_name|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
},
|
||||||
|
"151664": {
|
||||||
|
"content": "<|file_sep|>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": false,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false,
|
||||||
|
"special": false
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"additional_special_tokens": [
|
||||||
|
"<|im_start|>",
|
||||||
|
"<|im_end|>",
|
||||||
|
"<|object_ref_start|>",
|
||||||
|
"<|object_ref_end|>",
|
||||||
|
"<|box_start|>",
|
||||||
|
"<|box_end|>",
|
||||||
|
"<|quad_start|>",
|
||||||
|
"<|quad_end|>",
|
||||||
|
"<|vision_start|>",
|
||||||
|
"<|vision_end|>",
|
||||||
|
"<|vision_pad|>",
|
||||||
|
"<|image_pad|>",
|
||||||
|
"<|video_pad|>"
|
||||||
|
],
|
||||||
|
"bos_token": null,
|
||||||
|
"chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are a helpful assistant.' }}\n {%- endif %}\n {{- \"\\n\\n# Tools\\n\\nYou may call one or more functions to assist with the user query.\\n\\nYou are provided with function signatures within <tools></tools> XML tags:\\n<tools>\" }}\n {%- for tool in tools %}\n {{- \"\\n\" }}\n {{- tool | tojson }}\n {%- endfor %}\n {{- \"\\n</tools>\\n\\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\\n<tool_call>\\n{\\\"name\\\": <function-name>, \\\"arguments\\\": <args-json-object>}\\n</tool_call><|im_end|>\\n\" }}\n{%- else %}\n {%- if messages[0]['role'] == 'system' %}\n {{- '<|im_start|>system\\n' + messages[0]['content'] + '<|im_end|>\\n' }}\n {%- else %}\n {{- '<|im_start|>system\\nYou are a helpful assistant.<|im_end|>\\n' }}\n {%- endif %}\n{%- endif %}\n{%- for message in messages %}\n {%- if (message.role == \"user\") or (message.role == \"system\" and not loop.first) or (message.role == \"assistant\" and not message.tool_calls) %}\n {{- '<|im_start|>' + message.role + '\\n' + message.content + '<|im_end|>' + '\\n' }}\n {%- elif message.role == \"assistant\" %}\n {{- '<|im_start|>' + message.role }}\n {%- if message.content %}\n {{- '\\n' + message.content }}\n {%- endif %}\n {%- for tool_call in message.tool_calls %}\n {%- if tool_call.function is defined %}\n {%- set tool_call = tool_call.function %}\n {%- endif %}\n {{- '\\n<tool_call>\\n{\"name\": \"' }}\n {{- tool_call.name }}\n {{- '\", \"arguments\": ' }}\n {{- tool_call.arguments | tojson }}\n {{- '}\\n</tool_call>' }}\n {%- endfor %}\n {{- '<|im_end|>\\n' }}\n {%- elif message.role == \"tool\" %}\n {%- if (loop.index0 == 0) or (messages[loop.index0 - 1].role != \"tool\") %}\n {{- '<|im_start|>user' }}\n {%- endif %}\n {{- '\\n<tool_response>\\n' }}\n {{- message.content }}\n {{- '\\n</tool_response>' }}\n {%- if loop.last or (messages[loop.index0 + 1].role != \"tool\") %}\n {{- '<|im_end|>\\n' }}\n {%- endif %}\n {%- endif %}\n{%- endfor %}\n{%- if add_generation_prompt %}\n {{- '<|im_start|>assistant\\n' }}\n{%- endif %}\n",
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": "<|endoftext|>",
|
||||||
|
"errors": "replace",
|
||||||
|
"model_max_length": 131072,
|
||||||
|
"pad_token": "<|endoftext|>",
|
||||||
|
"split_special_tokens": false,
|
||||||
|
"tokenizer_class": "Qwen2Tokenizer",
|
||||||
|
"unk_token": null
|
||||||
|
}
|
||||||
1
vocab.json
Normal file
1
vocab.json
Normal file
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user