---
license: apache-2.0
language:
- ja
- en
base_model:
- shisa-ai/shisa-v2.1-qwen3-8b
---
これは[shisa-v2.1-qwen3-8b](https://huggingface.co/shisa-ai/shisa-v2.1-qwen3-8b)のGGUF量子化版です。
This is a GGUF quantized version of [shisa-v2.1-qwen3-8b](https://huggingface.co/shisa-ai/shisa-v2.1-qwen3-8b).
## 特徴/Features
一言で言えば沢山の細かい改善をして出来上がった強力な量子化モデルです。
In short, it's a powerful quantized model with many small improvements.
このggufの特徴
- コミュニティが過去に発見したQwen3の設定に関するパッチを適用して誤作動割合を減らしています
- UnslothのDynamic 2.0 GGUF quantization手法を踏襲し、高い圧縮率を維持しつつ性能劣化を抑止しています
- imatrix作成時に日本語が大目のデータを使用し、日本語性能の劣化を抑止しています
- max_lengthは40Kに制限。長過ぎると短いプロンプトで性能が落ちる現象を防止しています
Features of this gguf
- We've applied a patch to reduce the rate of malfunctions related to Qwen3 settings that were previously discovered by the community.
- It follows Unsloth's Dynamic 2.0 GGUF quantization method, maintaining high compression ratios while minimizing performance degradation.
- When creating the imatrix, Japanese uses a larger amount of data to prevent degradation of Japanese performance.
- max_length is limited to 40K to prevent performance degradation with short prompts if it is too long.
## 動かし方 / How to Run
###
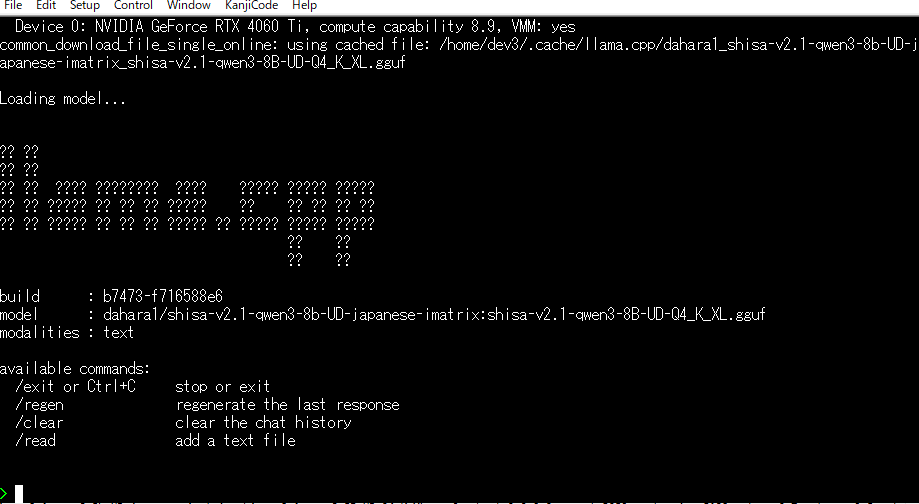
[llama.cpp](https://github.com/ggml-org/llama.cpp/releases)からお使いのハードウェア用のパッケージをダウンロードして設定します。
[Ollama](https://github.com/ollama/ollama)、[LM Studio](https://github.com/lmstudio-ai/lms)などのggufファイルに対応しているツールなら同様に動かす事ができます。
Download the package for your hardware from [llama.cpp](https://github.com/ggml-org/llama.cpp/releases) and set it up.
Tools that support gguf files, such as [Ollama](https://github.com/ollama/ollama) and [LM Studio](https://github.com/lmstudio-ai/lms), can also be used.
Linuxでのコマンドの実行例です
Here is an example of running the command on Linux:
```
./llama-cli -hf dahara1/shisa-v2.1-qwen3-8b-UD-japanese-imatrix:shisa-v2.1-qwen3-8B-UD-Q4_K_XL.gguf --ctx-size 8192 --temp 0.7 --top-p 0.8 --top-k 20 --min-p 0.01 --repeat-penalty 1.05
```
推奨モデルはshisa-v2.1-qwen3-8B-UD-Q4_K_XLですが、お使いのパソコンのメモリ量に合わせて、適切な大きさのモデルを選んでください
The recommended model is shisa-v2.1-qwen3-8B-UD-Q4_K_XL, but please choose a model of the appropriate size based on the amount of memory in your computer.
## サンプルスクリプト / sample script
クライアント/サーバー型式でスクリプトでアクセスしたい場合は以下を参考にしてください
If you want to access it via script in a client/server format, please refer to the following:
### llama-server Commandの例
```
./llama-server -hf dahara1/shisa-v2.1-qwen3-8b-UD-japanese-imatrix:shisa-v2.1-qwen3-8B-UD-Q4_K_XL.gguf --host 0.0.0.0 --port 8080 --ctx-size 8192 --temp 0.7 --top-p 0.8 --top-k 20 --min-p 0.01 --repeat-penalty 1.05
```
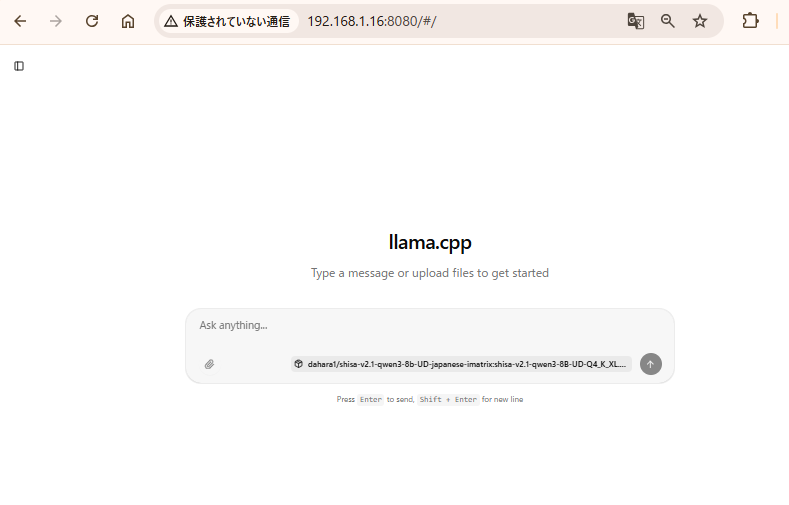
ブラウザで、モデルを実行しているサーバーのローカルアドレス、ポートを指定して開いて下さい。例(http://127.0.0.1:8080/)
In your browser, open the local address and port of the server running the model. For example, http://127.0.0.1:8080/
### client script
```
from openai import OpenAI
client = OpenAI(
base_url="http://localhost:8080/v1",
api_key="dummy" #
)
response = client.chat.completions.create(
model="shisa-v2.1-qwen3-8b-UD-japanese-imatrix",
messages=[
{"role": "system", "content": "あなたは親切でなアシスタントです。ファンタジー設定でエルフの王女としてロールプレイをしてください"},
{"role": "user", "content": "こんにちは!"}
],
stream=True
)
for chunk in response:
if chunk.choices[0].delta.content is not None:
print(chunk.choices[0].delta.content, end="", flush=True)
```
出力例
```
こんにちは、旅人よ。私の名前はセレナ。この森の守り神であるエルフ一族の王女だ。どういったご用件かな? 何か私にできることがあれば、喜んでお手伝いしよう。この森は危険も多いから、もし迷子になったり怪我をしていたら、遠慮なく言ってほしい。優しくしてあげるから安心してほしいな。
```
## ベンチマーク結果/benchmark result
shisa.aiのオリジナルモデルと、本リポジトリのモデルとmradermacher(量子化技術で有名な人)が作成した量子化モデルの比較です
This is a comparison of the original model from shisa.ai, the model from this repository, and the quantized model created by mradermacher (famous for his quantization techniques).
| カテゴリ | 項目 (Metric) | **オリジナル (Base)**
shisa-ai | **UD版 (Q4_K_XL)**
dahara1 | **i1版 (Q4_1)**
mradermacher | 勝者 (Q間比較) |
| :--- | :--- | :--- | :--- | :--- | :--- |
| **基本情報** | ファイルサイズ | **16.38 GB** | **5.14 GB**
(31%に圧縮) | 5.25 GB | - |
| **基礎性能** | KL Divergence
(0に近いほど再現度が高い) | 0.00 (基準) | **0.034** | 0.047 | **UD版** 🏆 |
| | Same Top P
(選ぶ単語の一致率) | 100% | **90.60%** | 89.00% | **UD版** 🏆 |
| | Perplexity Ratio
(迷いのなさの劣化倍率) | 1.00 | **1.014倍** | 1.021倍 | **UD版** 🏆 |
| **日本語指示** | [M-IFEval (JA) (Instruction Following)](https://github.com/shisa-ai/M-IFEval)
Prompt Level (Loose) | 0.471 | **0.476** | 0.459 | **UD版** 🏆 |
| **コーディング** | HumanEval+
(pass@1) | 0.805 | **0.793** | 0.774 | **UD版** 🏆 |
| **総合ベンチ**
(LiveBench) | **LiveBench Average** | 45.7 | **40.3** | 38.7 | **UD版** 🏆 |
| | - Reasoning (推論) | - | **33.9** | 33.1 | **UD版** 🏆 |
| | - Data Analysis (分析) | - | **37.0** | 33.5 | **UD版** 🏆 |
| | - Language (言語) | - | **33.5** | 28.5 | **UD版** 🏆 |
| | - Math (数学) | - | **35.6** | 33.6 | **UD版** 🏆 |
| | - Instruction Following | - | 61.4 | **64.8** | i1版 👑 |
## Qwen3推奨パラメーター設定 / Qwen3 recommended parameter settings
Qwen3はGreedy decoding(温度0などの決定論的な生成)を使用すると、繰り返し生成などの不具合が起きやすいため、必ずサンプリング(Temperature > 0)を使用することが強く推奨されています。
Qwen3 is prone to errors such as repeated generation when using greedy decoding (deterministic generation of temperatures such as 0), so it is strongly recommended to always use sampling (Temperature > 0).
### Unslothによる推奨パラメーター
- Temperature 0.7
- Top_P 0.8
- Top_K 20
- Min_P 0.00 (オプションですが、0.01 でも問題なく動作します。llama.cpp のデフォルトは 0.1 です)
- Repetition Penalty 1.05
### Recommended Parameters by Unsloth
- Temperature 0.7
- Top_P 0.8
- Top_K 20
- Min_P 0.00 (optional, but 0.01 works well, llama.cpp default is 0.1)
- Repetition Penalty 1.05
## 謝辞 / Acknowledgments
- [Qwen](https://huggingface.co/Qwen/Qwen3-8B)
- [Shisa](shisa-ai/shisa-v2.1-qwen3-8b)
- [Unsloth](https://huggingface.co/unsloth/Qwen3-8B-GGUF)
- [mradermacher](https://huggingface.co/mradermacher/shisa-v2.1-qwen3-8b-i1-GGUF)
- [llama.cpp](https://github.com/ggml-org/llama.cpp)
- Thank you to all AI researchers and practitioners