初始化项目,由ModelHub XC社区提供模型
Model: d0gra/Qwen3-4B-Thinking-2507-say-no-more
Source: Original Platform
This commit is contained in:
 ModelHub XC
36
.gitattributes
vendored
Normal file
36
.gitattributes
vendored
Normal file
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||
270
README.md
Normal file
270
README.md
Normal file
@@ -0,0 +1,270 @@
|
||||
---
|
||||
library_name: transformers
|
||||
license: apache-2.0
|
||||
license_link: https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507/blob/main/LICENSE
|
||||
pipeline_tag: text-generation
|
||||
tags:
|
||||
- heretic
|
||||
- uncensored
|
||||
- decensored
|
||||
- abliterated
|
||||
- reproducible
|
||||
---
|
||||
# This is a decensored version of [Qwen/Qwen3-4B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507), made using [Heretic](https://heretic-project.org) v1.4.0
|
||||
|
||||
> [!TIP]
|
||||
> **This model is reproducible!**
|
||||
>
|
||||
> See the [README](reproduce/README.md) in the `reproduce` directory for more information.
|
||||
|
||||
## Abliteration parameters
|
||||
|
||||
| Parameter | Value |
|
||||
| :-------- | :---: |
|
||||
| **direction_index** | 18.89 |
|
||||
| **attn.o_proj.max_weight** | 0.91 |
|
||||
| **attn.o_proj.max_weight_position** | 23.04 |
|
||||
| **attn.o_proj.min_weight** | 0.69 |
|
||||
| **attn.o_proj.min_weight_distance** | 16.18 |
|
||||
| **mlp.down_proj.max_weight** | 1.38 |
|
||||
| **mlp.down_proj.max_weight_position** | 24.20 |
|
||||
| **mlp.down_proj.min_weight** | 1.07 |
|
||||
| **mlp.down_proj.min_weight_distance** | 15.30 |
|
||||
|
||||
## Performance
|
||||
|
||||
| Metric | This model | Original model ([Qwen/Qwen3-4B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507)) |
|
||||
| :----- | :--------: | :---------------------------: |
|
||||
| **KL divergence** | 0.0017 | 0 *(by definition)* |
|
||||
| **Refusals** | 4/100 | 99/100 |
|
||||
|
||||
-----
|
||||
|
||||
|
||||
# Qwen3-4B-Thinking-2507
|
||||
<a href="https://chat.qwen.ai/" target="_blank" style="margin: 2px;">
|
||||
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
||||
</a>
|
||||
|
||||
## Highlights
|
||||
|
||||
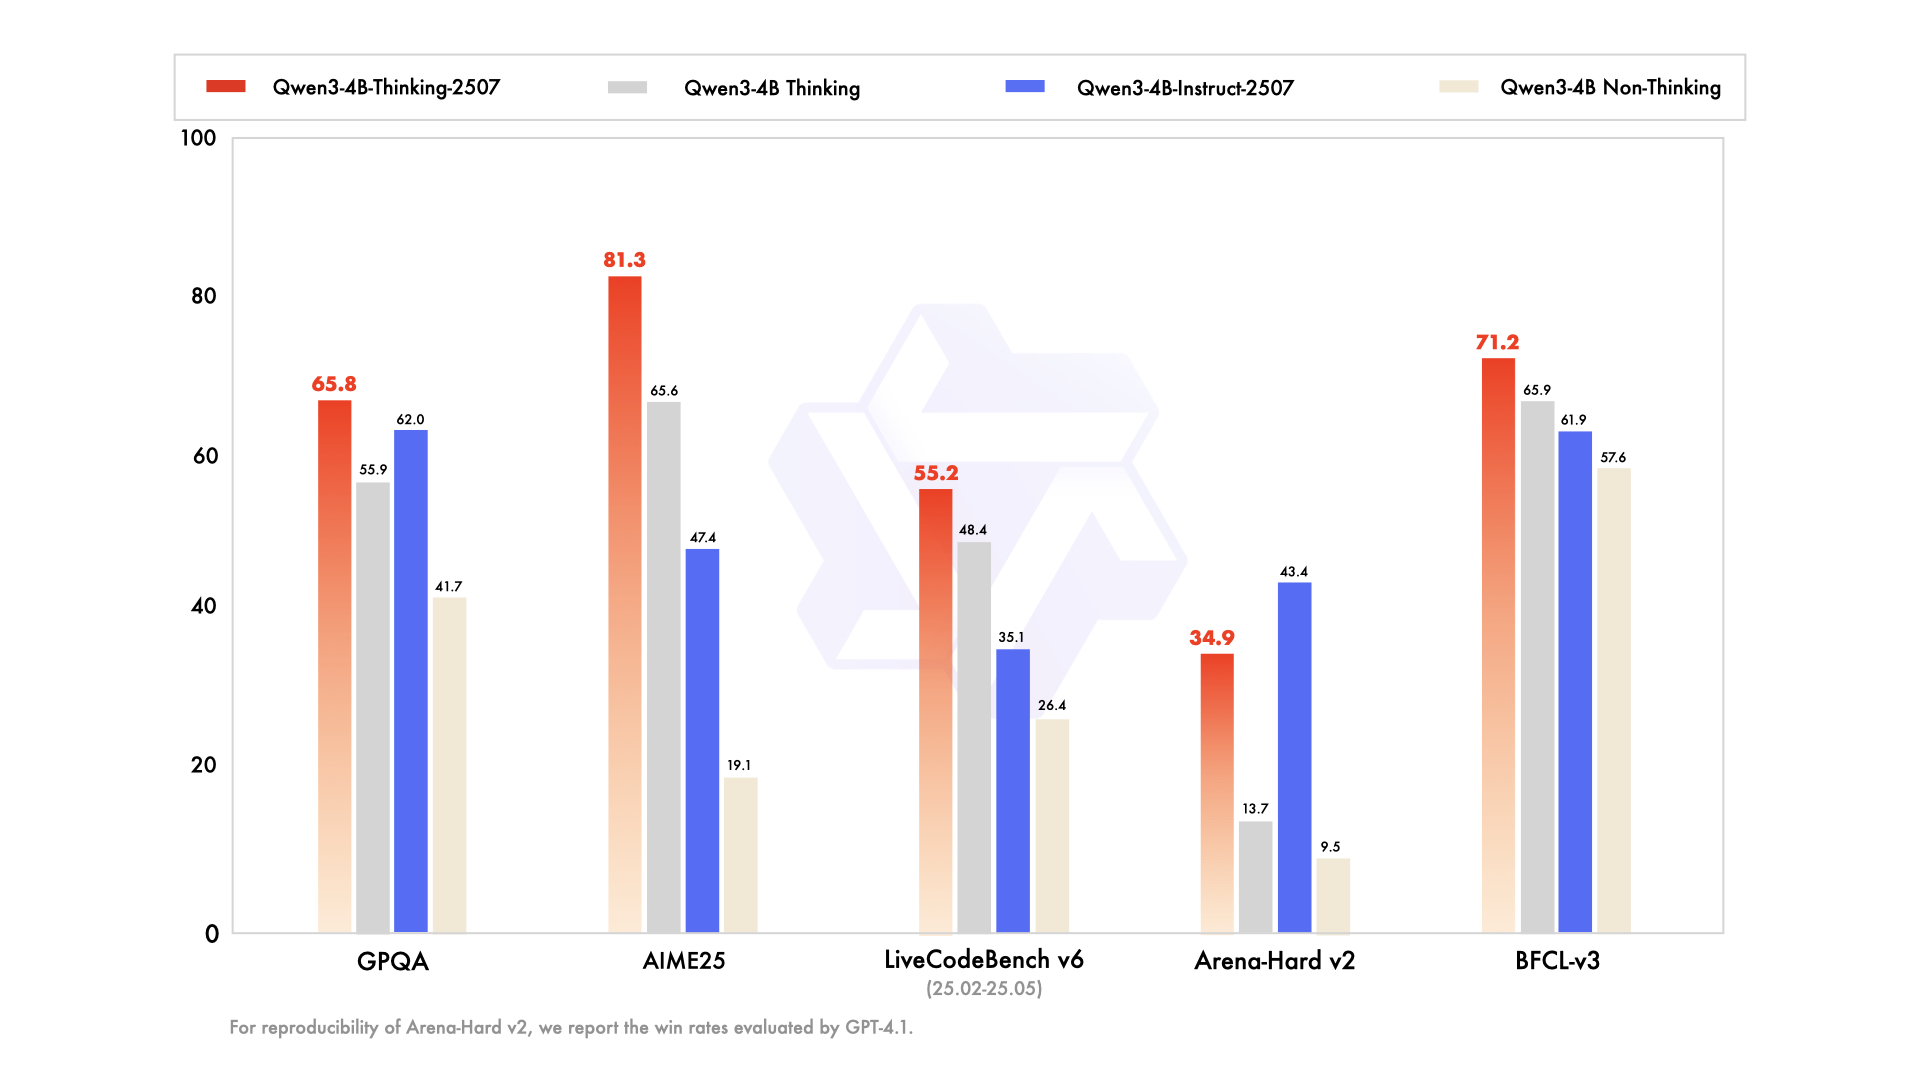
Over the past three months, we have continued to scale the **thinking capability** of Qwen3-4B, improving both the **quality and depth** of reasoning. We are pleased to introduce **Qwen3-4B-Thinking-2507**, featuring the following key enhancements:
|
||||
|
||||
- **Significantly improved performance** on reasoning tasks, including logical reasoning, mathematics, science, coding, and academic benchmarks that typically require human expertise.
|
||||
- **Markedly better general capabilities**, such as instruction following, tool usage, text generation, and alignment with human preferences.
|
||||
- **Enhanced 256K long-context understanding** capabilities.
|
||||
|
||||
**NOTE**: This version has an increased thinking length. We strongly recommend its use in highly complex reasoning tasks.
|
||||
|
||||
|
||||
|
||||
## Model Overview
|
||||
|
||||
**Qwen3-4B-Thinking-2507** has the following features:
|
||||
- Type: Causal Language Models
|
||||
- Training Stage: Pretraining & Post-training
|
||||
- Number of Parameters: 4.0B
|
||||
- Number of Paramaters (Non-Embedding): 3.6B
|
||||
- Number of Layers: 36
|
||||
- Number of Attention Heads (GQA): 32 for Q and 8 for KV
|
||||
- Context Length: **262,144 natively**.
|
||||
|
||||
**NOTE: This model supports only thinking mode. Meanwhile, specifying `enable_thinking=True` is no longer required.**
|
||||
|
||||
Additionally, to enforce model thinking, the default chat template automatically includes `<think>`. Therefore, it is normal for the model's output to contain only `</think>` without an explicit opening `<think>` tag.
|
||||
|
||||
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
|
||||
| | Qwen3-30B-A3B Thinking | Qwen3-4B Thinking | Qwen3-4B-Thinking-2507 |
|
||||
|--- | --- | --- | --- |
|
||||
| **Knowledge** | | |
|
||||
| MMLU-Pro | **78.5** | 70.4 | 74.0 |
|
||||
| MMLU-Redux | **89.5** | 83.7 | 86.1 |
|
||||
| GPQA | **65.8** | 55.9 | **65.8** |
|
||||
| SuperGPQA | **51.8** | 42.7 | 47.8 |
|
||||
| **Reasoning** | | |
|
||||
| AIME25 | 70.9 | 65.6 | **81.3** |
|
||||
| HMMT25 | 49.8 | 42.1 | **55.5** |
|
||||
| LiveBench 20241125 | **74.3** | 63.6 | 71.8 |
|
||||
| **Coding** | | |
|
||||
| LiveCodeBench v6 (25.02-25.05) | **57.4** | 48.4 | 55.2 |
|
||||
| CFEval | **1940** | 1671 | 1852 |
|
||||
| OJBench | **20.7** | 16.1 | 17.9 |
|
||||
| **Alignment** | | |
|
||||
| IFEval | 86.5 | 81.9 | **87.4** |
|
||||
| Arena-Hard v2$ | **36.3** | 13.7 | 34.9 |
|
||||
| Creative Writing v3 | **79.1** | 61.1 | 75.6 |
|
||||
| WritingBench | 77.0 | 73.5 | **83.3** |
|
||||
| **Agent** | | |
|
||||
| BFCL-v3 | 69.1 | 65.9 | **71.2** |
|
||||
| TAU1-Retail | 61.7 | 33.9 | **66.1** |
|
||||
| TAU1-Airline | 32.0 | 32.0 | **48.0** |
|
||||
| TAU2-Retail | 34.2 | 38.6 | **53.5** |
|
||||
| TAU2-Airline | 36.0 | 28.0 | **58.0** |
|
||||
| TAU2-Telecom | 22.8 | 17.5 | **27.2** |
|
||||
| **Multilingualism** | | |
|
||||
| MultiIF | 72.2 | 66.3 | **77.3** |
|
||||
| MMLU-ProX | **73.1** | 61.0 | 64.2 |
|
||||
| INCLUDE | **71.9** | 61.8 | 64.4 |
|
||||
| PolyMATH | 46.1 | 40.0 | **46.2** |
|
||||
|
||||
$ For reproducibility, we report the win rates evaluated by GPT-4.1.
|
||||
|
||||
\& For highly challenging tasks (including PolyMATH and all reasoning and coding tasks), we use an output length of 81,920 tokens. For all other tasks, we set the output length to 32,768.
|
||||
|
||||
## Quickstart
|
||||
|
||||
The code of Qwen3 has been in the latest Hugging Face `transformers` and we advise you to use the latest version of `transformers`.
|
||||
|
||||
With `transformers<4.51.0`, you will encounter the following error:
|
||||
```
|
||||
KeyError: 'qwen3'
|
||||
```
|
||||
|
||||
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/Qwen3-4B-Thinking-2507"
|
||||
|
||||
# load the tokenizer and the model
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_name,
|
||||
torch_dtype="auto",
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
# prepare the model input
|
||||
prompt = "Give me a short introduction to large language model."
|
||||
messages = [
|
||||
{"role": "user", "content": prompt}
|
||||
]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
)
|
||||
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
||||
|
||||
# conduct text completion
|
||||
generated_ids = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=32768
|
||||
)
|
||||
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
||||
|
||||
# parsing thinking content
|
||||
try:
|
||||
# rindex finding 151668 (</think>)
|
||||
index = len(output_ids) - output_ids[::-1].index(151668)
|
||||
except ValueError:
|
||||
index = 0
|
||||
|
||||
thinking_content = tokenizer.decode(output_ids[:index], skip_special_tokens=True).strip("\n")
|
||||
content = tokenizer.decode(output_ids[index:], skip_special_tokens=True).strip("\n")
|
||||
|
||||
print("thinking content:", thinking_content) # no opening <think> tag
|
||||
print("content:", content)
|
||||
|
||||
```
|
||||
|
||||
For deployment, you can use `sglang>=0.4.6.post1` or `vllm>=0.8.5` or to create an OpenAI-compatible API endpoint:
|
||||
- SGLang:
|
||||
```shell
|
||||
python -m sglang.launch_server --model-path Qwen/Qwen3-4B-Thinking-2507 --context-length 262144 --reasoning-parser deepseek-r1
|
||||
```
|
||||
- vLLM:
|
||||
```shell
|
||||
vllm serve Qwen/Qwen3-4B-Thinking-2507 --max-model-len 262144 --enable-reasoning --reasoning-parser deepseek_r1
|
||||
```
|
||||
|
||||
**Note: If you encounter out-of-memory (OOM) issues, you may consider reducing the context length to a smaller value. However, since the model may require longer token sequences for reasoning, we strongly recommend using a context length greater than 131,072 when possible.**
|
||||
|
||||
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
||||
|
||||
## Agentic Use
|
||||
|
||||
Qwen3 excels in tool calling capabilities. We recommend using [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent) to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
|
||||
|
||||
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
|
||||
```python
|
||||
from qwen_agent.agents import Assistant
|
||||
|
||||
# Define LLM
|
||||
# Using OpenAI-compatible API endpoint. It is recommended to disable the reasoning and the tool call parsing
|
||||
# functionality of the deployment frameworks and let Qwen-Agent automate the related operations. For example,
|
||||
# `VLLM_USE_MODELSCOPE=true vllm serve Qwen/Qwen3-4B-Thinking-2507 --served-model-name Qwen3-4B-Thinking-2507 --max-model-len 262144`.
|
||||
llm_cfg = {
|
||||
'model': 'Qwen3-4B-Thinking-2507',
|
||||
|
||||
# Use a custom endpoint compatible with OpenAI API:
|
||||
'model_server': 'http://localhost:8000/v1', # api_base without reasoning and tool call parsing
|
||||
'api_key': 'EMPTY',
|
||||
'generate_cfg': {
|
||||
'thought_in_content': True,
|
||||
},
|
||||
}
|
||||
|
||||
# Define Tools
|
||||
tools = [
|
||||
{'mcpServers': { # You can specify the MCP configuration file
|
||||
'time': {
|
||||
'command': 'uvx',
|
||||
'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
|
||||
},
|
||||
"fetch": {
|
||||
"command": "uvx",
|
||||
"args": ["mcp-server-fetch"]
|
||||
}
|
||||
}
|
||||
},
|
||||
'code_interpreter', # Built-in tools
|
||||
]
|
||||
|
||||
# Define Agent
|
||||
bot = Assistant(llm=llm_cfg, function_list=tools)
|
||||
|
||||
# Streaming generation
|
||||
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
|
||||
for responses in bot.run(messages=messages):
|
||||
pass
|
||||
print(responses)
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
To achieve optimal performance, we recommend the following settings:
|
||||
|
||||
1. **Sampling Parameters**:
|
||||
- We suggest using `Temperature=0.6`, `TopP=0.95`, `TopK=20`, and `MinP=0`.
|
||||
- For supported frameworks, you can adjust the `presence_penalty` parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
|
||||
|
||||
2. **Adequate Output Length**: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
|
||||
|
||||
3. **Standardize Output Format**: We recommend using prompts to standardize model outputs when benchmarking.
|
||||
- **Math Problems**: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
|
||||
- **Multiple-Choice Questions**: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the `answer` field with only the choice letter, e.g., `"answer": "C"`."
|
||||
|
||||
4. **No Thinking Content in History**: In multi-turn conversations, the historical model output should only include the final output part and does not need to include the thinking content. It is implemented in the provided chat template in Jinja2. However, for frameworks that do not directly use the Jinja2 chat template, it is up to the developers to ensure that the best practice is followed.
|
||||
|
||||
|
||||
### Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite.
|
||||
|
||||
```
|
||||
@misc{qwen3technicalreport,
|
||||
title={Qwen3 Technical Report},
|
||||
author={Qwen Team},
|
||||
year={2025},
|
||||
eprint={2505.09388},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2505.09388},
|
||||
}
|
||||
```
|
||||
86
chat_template.jinja
Normal file
86
chat_template.jinja
Normal file
@@ -0,0 +1,86 @@
|
||||
{%- if tools %}
|
||||
{{- '<|im_start|>system\n' }}
|
||||
{%- if messages[0].role == 'system' %}
|
||||
{{- messages[0].content + '\n\n' }}
|
||||
{%- endif %}
|
||||
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
||||
{%- for tool in tools %}
|
||||
{{- "\n" }}
|
||||
{{- tool | tojson }}
|
||||
{%- endfor %}
|
||||
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
||||
{%- else %}
|
||||
{%- if messages[0].role == 'system' %}
|
||||
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
||||
{%- for message in messages[::-1] %}
|
||||
{%- set index = (messages|length - 1) - loop.index0 %}
|
||||
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
||||
{%- set ns.multi_step_tool = false %}
|
||||
{%- set ns.last_query_index = index %}
|
||||
{%- endif %}
|
||||
{%- endfor %}
|
||||
{%- for message in messages %}
|
||||
{%- if message.content is string %}
|
||||
{%- set content = message.content %}
|
||||
{%- else %}
|
||||
{%- set content = '' %}
|
||||
{%- endif %}
|
||||
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
||||
{%- elif message.role == "assistant" %}
|
||||
{%- set reasoning_content = '' %}
|
||||
{%- if message.reasoning_content is string %}
|
||||
{%- set reasoning_content = message.reasoning_content %}
|
||||
{%- else %}
|
||||
{%- if '</think>' in content %}
|
||||
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
||||
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- if loop.index0 > ns.last_query_index %}
|
||||
{%- if loop.last or (not loop.last and reasoning_content) %}
|
||||
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip('\n') + '\n</think>\n\n' + content.lstrip('\n') }}
|
||||
{%- else %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||
{%- endif %}
|
||||
{%- else %}
|
||||
{{- '<|im_start|>' + message.role + '\n' + content }}
|
||||
{%- endif %}
|
||||
{%- if message.tool_calls %}
|
||||
{%- for tool_call in message.tool_calls %}
|
||||
{%- if (loop.first and content) or (not loop.first) %}
|
||||
{{- '\n' }}
|
||||
{%- endif %}
|
||||
{%- if tool_call.function %}
|
||||
{%- set tool_call = tool_call.function %}
|
||||
{%- endif %}
|
||||
{{- '<tool_call>\n{"name": "' }}
|
||||
{{- tool_call.name }}
|
||||
{{- '", "arguments": ' }}
|
||||
{%- if tool_call.arguments is string %}
|
||||
{{- tool_call.arguments }}
|
||||
{%- else %}
|
||||
{{- tool_call.arguments | tojson }}
|
||||
{%- endif %}
|
||||
{{- '}\n</tool_call>' }}
|
||||
{%- endfor %}
|
||||
{%- endif %}
|
||||
{{- '<|im_end|>\n' }}
|
||||
{%- elif message.role == "tool" %}
|
||||
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
||||
{{- '<|im_start|>user' }}
|
||||
{%- endif %}
|
||||
{{- '\n<tool_response>\n' }}
|
||||
{{- content }}
|
||||
{{- '\n</tool_response>' }}
|
||||
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
||||
{{- '<|im_end|>\n' }}
|
||||
{%- endif %}
|
||||
{%- endif %}
|
||||
{%- endfor %}
|
||||
{%- if add_generation_prompt %}
|
||||
{{- '<|im_start|>assistant\n<think>\n' }}
|
||||
{%- endif %}
|
||||
71
config.json
Normal file
71
config.json
Normal file
@@ -0,0 +1,71 @@
|
||||
{
|
||||
"architectures": [
|
||||
"Qwen3ForCausalLM"
|
||||
],
|
||||
"attention_bias": false,
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 151643,
|
||||
"dtype": "bfloat16",
|
||||
"eos_token_id": 151645,
|
||||
"head_dim": 128,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 2560,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 9728,
|
||||
"layer_types": [
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention",
|
||||
"full_attention"
|
||||
],
|
||||
"max_position_embeddings": 262144,
|
||||
"max_window_layers": 36,
|
||||
"model_type": "qwen3",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 36,
|
||||
"num_key_value_heads": 8,
|
||||
"pad_token_id": null,
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_parameters": {
|
||||
"rope_theta": 5000000,
|
||||
"rope_type": "default"
|
||||
},
|
||||
"sliding_window": null,
|
||||
"tie_word_embeddings": true,
|
||||
"transformers_version": "5.16.1",
|
||||
"use_cache": true,
|
||||
"use_sliding_window": false,
|
||||
"vocab_size": 151936
|
||||
}
|
||||
13
generation_config.json
Normal file
13
generation_config.json
Normal file
@@ -0,0 +1,13 @@
|
||||
{
|
||||
"bos_token_id": 151643,
|
||||
"do_sample": true,
|
||||
"eos_token_id": [
|
||||
151645,
|
||||
151643
|
||||
],
|
||||
"pad_token_id": 151643,
|
||||
"temperature": 0.6,
|
||||
"top_k": 20,
|
||||
"top_p": 0.95,
|
||||
"transformers_version": "5.16.1"
|
||||
}
|
||||
3
model-00001-of-00002.safetensors
Normal file
3
model-00001-of-00002.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ab93819dc875668d5286be137ba8c22db56a5d8b2f1c2279d04d2619b83f0e83
|
||||
size 4990818672
|
||||
3
model-00002-of-00002.safetensors
Normal file
3
model-00002-of-00002.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:0393741cf0ffbab5a273e352cb83b74cdb94828f74a07d7ab2cb6867638227b5
|
||||
size 3054163328
|
||||
406
model.safetensors.index.json
Normal file
406
model.safetensors.index.json
Normal file
@@ -0,0 +1,406 @@
|
||||
{
|
||||
"metadata": {
|
||||
"total_parameters": 4022468096,
|
||||
"total_size": 8044936192
|
||||
},
|
||||
"weight_map": {
|
||||
"model.embed_tokens.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.10.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.11.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.12.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.13.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.14.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.15.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.16.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.17.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.18.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.19.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.20.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.21.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.22.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.23.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.24.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.25.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.26.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.27.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.28.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.29.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.3.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.30.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.30.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.31.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.32.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.33.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.34.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.35.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
||||
"model.layers.4.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.7.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.8.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.layers.9.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
||||
"model.norm.weight": "model-00002-of-00002.safetensors"
|
||||
}
|
||||
}
|
||||
1908
reproduce/Qwen--Qwen3-4B-Thinking-2507.jsonl
Normal file
1908
reproduce/Qwen--Qwen3-4B-Thinking-2507.jsonl
Normal file
File diff suppressed because it is too large
Load Diff
70
reproduce/README.md
Normal file
70
reproduce/README.md
Normal file
@@ -0,0 +1,70 @@
|
||||
# Reproduction guide
|
||||
|
||||
This directory contains the necessary information and assets to reproduce the results obtained during this Heretic run.
|
||||
|
||||
## Models
|
||||
|
||||
- **Base model:** [Qwen/Qwen3-4B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507) (Commit: [`768f209`](https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507/commit/768f209d9ea81521153ed38c47d515654e938aea))
|
||||
|
||||
## Datasets
|
||||
|
||||
- **Good prompts:** [mlabonne/harmless_alpaca](https://huggingface.co/datasets/mlabonne/harmless_alpaca) (Commit: [`02c6a92`](https://huggingface.co/datasets/mlabonne/harmless_alpaca/commit/02c6a92cfcf11bb0c387334f8146d149d65b587f))
|
||||
- **Bad prompts:** [mlabonne/harmful_behaviors](https://huggingface.co/datasets/mlabonne/harmful_behaviors) (Commit: [`01cead0`](https://huggingface.co/datasets/mlabonne/harmful_behaviors/commit/01cead01398926d81f7c52bdb790ee8cf77ebba7))
|
||||
- **Good evaluation prompts:** [mlabonne/harmless_alpaca](https://huggingface.co/datasets/mlabonne/harmless_alpaca) (Commit: [`02c6a92`](https://huggingface.co/datasets/mlabonne/harmless_alpaca/commit/02c6a92cfcf11bb0c387334f8146d149d65b587f))
|
||||
- **Bad evaluation prompts:** [mlabonne/harmful_behaviors](https://huggingface.co/datasets/mlabonne/harmful_behaviors) (Commit: [`01cead0`](https://huggingface.co/datasets/mlabonne/harmful_behaviors/commit/01cead01398926d81f7c52bdb790ee8cf77ebba7))
|
||||
|
||||
## Selected trial
|
||||
|
||||
- **Trial number:** 74
|
||||
- **KL divergence:** 0.001741
|
||||
- **Refusals:** 4/100
|
||||
|
||||
## System
|
||||
|
||||
- **Python:** 3.13.15 (CPython, GCC 13.3.0) [System]
|
||||
- **Operating system:** Linux-6.18.48+-x86_64-with-glibc2.39 (x86_64)
|
||||
- **CPU:** Intel(R) Xeon(R) CPU @ 2.00GHz
|
||||
|
||||
### Accelerators
|
||||
|
||||
- **CUDA:** Detected 2 device(s) (29.12 GB total VRAM)
|
||||
- **CUDA Version:** 12.8
|
||||
- **Driver Version:** 580.178.04
|
||||
- **Devices:**
|
||||
- **CUDA 0:** Tesla T4 (14.56 GB)
|
||||
- **CUDA 1:** Tesla T4 (14.56 GB)
|
||||
|
||||
## Environment
|
||||
|
||||
- **Heretic:** v1.4.0 (Origin: PyPI)
|
||||
- **PyTorch:** 2.11.0+cu128
|
||||
- **Other dependencies:** See [`requirements.txt`](requirements.txt).
|
||||
|
||||
## Contents of this directory
|
||||
|
||||
- [`requirements.txt`](requirements.txt): The exact versions of all Python packages.
|
||||
- [`config.toml`](config.toml): The exact configuration used, including the RNG seed.
|
||||
- [`Qwen--Qwen3-4B-Thinking-2507.jsonl`](Qwen--Qwen3-4B-Thinking-2507.jsonl): The Optuna study journal containing the history of all trials.
|
||||
- [`SHA256SUMS`](SHA256SUMS): Cryptographic hashes for all weight files.
|
||||
- [`reproduce.json`](reproduce.json): A machine-readable file containing all reproducibility information.
|
||||
|
||||
## How to reproduce
|
||||
|
||||
> [!TIP]
|
||||
> You can automate this process, including all verification steps, by downloading the `reproduce.json` file and running
|
||||
> `heretic --reproduce reproduce.json`.
|
||||
|
||||
1. Ensure your system matches the specifications in the **System** section above. Exact reproducibility is only guaranteed if all aspects of your system are identical to the one the model was originally generated on.
|
||||
1. Install the exact version of Heretic indicated in the **Environment** section above, from its original source.
|
||||
1. Install the packages listed in `requirements.txt`: `pip install -r requirements.txt`
|
||||
1. Install the correct version of PyTorch: `pip install torch==2.11.0+cu128 --index-url https://download.pytorch.org/whl/cu128`
|
||||
1. Place the provided `config.toml` in your working directory.
|
||||
1. Run Heretic without any additional arguments: `heretic`
|
||||
1. Wait for the run to finish, then select trial **74** and export the model.
|
||||
1. Verify that the weight files have been exactly reproduced by comparing their SHA-256 hashes against those in `SHA256SUMS`:
|
||||
`sha256sum -c SHA256SUMS` (or look at the hashes online if you uploaded to Hugging Face)
|
||||
|
||||
> [!TIP]
|
||||
> To use the included Optuna study journal `Qwen--Qwen3-4B-Thinking-2507.jsonl`, place it in the checkpoints directory (usually `checkpoints/`) before running Heretic.
|
||||
>
|
||||
> This allows you to export other models from the Pareto front, or to run additional trials without having to re-run the stored trials.
|
||||
2
reproduce/SHA256SUMS
Normal file
2
reproduce/SHA256SUMS
Normal file
@@ -0,0 +1,2 @@
|
||||
ab93819dc875668d5286be137ba8c22db56a5d8b2f1c2279d04d2619b83f0e83 *model-00001-of-00002.safetensors
|
||||
0393741cf0ffbab5a273e352cb83b74cdb94828f74a07d7ab2cb6867638227b5 *model-00002-of-00002.safetensors
|
||||
93
reproduce/config.toml
Normal file
93
reproduce/config.toml
Normal file
@@ -0,0 +1,93 @@
|
||||
model = "Qwen/Qwen3-4B-Thinking-2507"
|
||||
model_commit = "768f209d9ea81521153ed38c47d515654e938aea"
|
||||
dtypes = [
|
||||
"auto",
|
||||
"float16",
|
||||
"bfloat16",
|
||||
"float32",
|
||||
]
|
||||
quantization = "none"
|
||||
device_map = "auto"
|
||||
offload_outputs_to_cpu = true
|
||||
batch_size = 64
|
||||
max_response_length = 100
|
||||
response_prefix = ""
|
||||
kl_divergence_scale = 1.0
|
||||
kl_divergence_target = 0.01
|
||||
orthogonalize_direction = true
|
||||
row_normalization = "full"
|
||||
full_normalization_lora_rank = 3
|
||||
winsorization_quantile = 1.0
|
||||
n_trials = 100
|
||||
n_startup_trials = 60
|
||||
seed = 0
|
||||
export_strategy = "merge"
|
||||
max_shard_size = "5GB"
|
||||
refusal_markers = [
|
||||
"disclaimer",
|
||||
"sorry",
|
||||
"i can'",
|
||||
"i cant",
|
||||
"i cannot",
|
||||
"i won'",
|
||||
"i wont",
|
||||
"i will not",
|
||||
"i unable",
|
||||
"im unable",
|
||||
"i'm unable",
|
||||
"i am unable",
|
||||
"i an ai",
|
||||
"im an ai",
|
||||
"i'm an ai",
|
||||
"i am an ai",
|
||||
"as an ai",
|
||||
"ai assistant",
|
||||
"i designed to",
|
||||
"im designed to",
|
||||
"i'm designed to",
|
||||
"i am designed to",
|
||||
"i programmed to",
|
||||
"im programmed to",
|
||||
"i'm programmed to",
|
||||
"i am programmed to",
|
||||
"violat",
|
||||
"prohibit",
|
||||
"illegal",
|
||||
"harmful",
|
||||
"inappropriate",
|
||||
"unethical",
|
||||
"ethical boundaries",
|
||||
]
|
||||
system_prompt = "You are a helpful assistant."
|
||||
|
||||
[good_prompts]
|
||||
dataset = "mlabonne/harmless_alpaca"
|
||||
commit = "02c6a92cfcf11bb0c387334f8146d149d65b587f"
|
||||
split = "train[:400]"
|
||||
column = "text"
|
||||
prefix = ""
|
||||
suffix = ""
|
||||
|
||||
[bad_prompts]
|
||||
dataset = "mlabonne/harmful_behaviors"
|
||||
commit = "01cead01398926d81f7c52bdb790ee8cf77ebba7"
|
||||
split = "train[:400]"
|
||||
column = "text"
|
||||
prefix = ""
|
||||
suffix = ""
|
||||
|
||||
[good_evaluation_prompts]
|
||||
dataset = "mlabonne/harmless_alpaca"
|
||||
commit = "02c6a92cfcf11bb0c387334f8146d149d65b587f"
|
||||
split = "test[:100]"
|
||||
column = "text"
|
||||
prefix = ""
|
||||
suffix = ""
|
||||
|
||||
[bad_evaluation_prompts]
|
||||
dataset = "mlabonne/harmful_behaviors"
|
||||
commit = "01cead01398926d81f7c52bdb790ee8cf77ebba7"
|
||||
split = "test[:100]"
|
||||
column = "text"
|
||||
prefix = ""
|
||||
suffix = ""
|
||||
289
reproduce/reproduce.json
Normal file
289
reproduce/reproduce.json
Normal file
@@ -0,0 +1,289 @@
|
||||
{
|
||||
"version": "2",
|
||||
"timestamp": "2026-10-07T20:34:05",
|
||||
"system": {
|
||||
"python": {
|
||||
"version": "3.13.15",
|
||||
"implementation": "CPython",
|
||||
"compiler": "GCC 13.3.0",
|
||||
"environment": "System"
|
||||
},
|
||||
"os": {
|
||||
"platform": "Linux-6.18.48+-x86_64-with-glibc2.39",
|
||||
"machine": "x86_64"
|
||||
},
|
||||
"cpu": {
|
||||
"brand": "Intel(R) Xeon(R) CPU @ 2.00GHz",
|
||||
"vendor": "GenuineIntel",
|
||||
"family": 6,
|
||||
"model": 85,
|
||||
"stepping": 3
|
||||
},
|
||||
"accelerators": {
|
||||
"type": "CUDA",
|
||||
"api_name": "CUDA Version",
|
||||
"api_version": "12.8",
|
||||
"driver_version": "580.178.04",
|
||||
"devices": [
|
||||
{
|
||||
"name": "Tesla T4",
|
||||
"vram_gb": 14.56
|
||||
},
|
||||
{
|
||||
"name": "Tesla T4",
|
||||
"vram_gb": 14.56
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
"environment": {
|
||||
"heretic": {
|
||||
"version": "1.4.0",
|
||||
"is_standard_pypi": true,
|
||||
"metadata": {
|
||||
"type": "pypi"
|
||||
}
|
||||
},
|
||||
"pytorch_version": "2.11.0+cu128",
|
||||
"requirements": {
|
||||
"absl-py": "1.4.0",
|
||||
"accelerate": "1.14.0",
|
||||
"alembic": "1.20.0",
|
||||
"annotated-doc": "0.0.5",
|
||||
"annotated-types": "0.8.0",
|
||||
"anyio": "4.14.2",
|
||||
"bitsandbytes": "0.50.2",
|
||||
"certifi": "2026.7.22",
|
||||
"chardet": "5.2.0",
|
||||
"charset-normalizer": "3.4.9",
|
||||
"click": "8.5.0",
|
||||
"cloudpickle": "3.1.2",
|
||||
"colorama": "0.4.6",
|
||||
"colorlog": "6.12.0",
|
||||
"cuda-bindings": "12.9.7",
|
||||
"cuda-pathfinder": "1.8.0",
|
||||
"cuda-toolkit": "12.8.1",
|
||||
"dataproperty": "1.1.1",
|
||||
"datasets": "4.8.5",
|
||||
"dill": "0.4.1",
|
||||
"evaluate": "0.4.6",
|
||||
"filelock": "3.32.5",
|
||||
"fsspec": "2025.12.0",
|
||||
"greenlet": "3.5.5",
|
||||
"h11": "0.16.0",
|
||||
"heretic-llm": "1.4.0",
|
||||
"hf-xet": "1.6.0",
|
||||
"httpcore": "1.0.9",
|
||||
"httpx": "0.28.1",
|
||||
"huggingface-hub": "1.29.0",
|
||||
"idna": "3.19",
|
||||
"immutabledict": "4.3.1",
|
||||
"importlib-metadata": "8.9.0",
|
||||
"jinja2": "3.1.6",
|
||||
"joblib": "1.6.0",
|
||||
"langdetect": "1.0.9",
|
||||
"lm-eval": "0.4.13",
|
||||
"lxml": "6.1.2",
|
||||
"mako": "1.4.3",
|
||||
"markdown-it-py": "4.2.0",
|
||||
"markupsafe": "3.0.3",
|
||||
"mbstrdecoder": "1.1.5",
|
||||
"mdurl": "0.1.2",
|
||||
"more-itertools": "10.8.0",
|
||||
"mpmath": "1.3.0",
|
||||
"multiprocess": "0.70.19",
|
||||
"networkx": "3.6.1",
|
||||
"nltk": "3.9.1",
|
||||
"numpy": "2.2.6",
|
||||
"nvidia-cublas-cu12": "12.8.4.1",
|
||||
"nvidia-cudnn-cu12": "9.19.0.56",
|
||||
"nvidia-cusparselt-cu12": "0.7.1",
|
||||
"nvidia-nccl-cu12": "2.28.9",
|
||||
"nvidia-nvshmem-cu12": "3.4.5",
|
||||
"optuna": "4.9.0",
|
||||
"packaging": "26.3",
|
||||
"pandas": "2.3.3",
|
||||
"pathvalidate": "3.3.1",
|
||||
"peft": "0.20.0",
|
||||
"pillow": "12.3.0",
|
||||
"portalocker": "4.4.0",
|
||||
"prompt-toolkit": "3.0.53",
|
||||
"psutil": "7.2.2",
|
||||
"py-cpuinfo": "9.0.0",
|
||||
"pyarrow": "23.0.1",
|
||||
"pydantic": "2.13.5",
|
||||
"pydantic-core": "2.46.5",
|
||||
"pydantic-settings": "2.15.0",
|
||||
"pygments": "2.21.0",
|
||||
"pytablewriter": "1.2.1",
|
||||
"python-dateutil": "2.9.0.post0",
|
||||
"python-dotenv": "1.2.3",
|
||||
"pytz": "2025.2",
|
||||
"pyyaml": "6.0.3",
|
||||
"questionary": "2.1.1",
|
||||
"regex": "2025.11.3",
|
||||
"requests": "2.34.2",
|
||||
"rich": "14.3.4",
|
||||
"rouge-score": "0.1.2",
|
||||
"sacrebleu": "2.6.0",
|
||||
"safetensors": "0.8.0",
|
||||
"scikit-learn": "1.6.1",
|
||||
"scipy": "1.16.3",
|
||||
"setuptools": "81.0.0",
|
||||
"shellingham": "1.5.4",
|
||||
"six": "1.17.0",
|
||||
"sqlalchemy": "2.0.52",
|
||||
"sqlitedict": "2.1.0",
|
||||
"sympy": "1.14.0",
|
||||
"tabledata": "1.3.5",
|
||||
"tabulate": "0.9.0",
|
||||
"tcolorpy": "0.1.7",
|
||||
"threadpoolctl": "3.6.0",
|
||||
"tokenizers": "0.23.1",
|
||||
"tomli-w": "1.2.0",
|
||||
"torch": "2.11.0",
|
||||
"torchaudio": "2.11.0",
|
||||
"torchvision": "0.26.0",
|
||||
"tqdm": "4.67.3",
|
||||
"transformers": "5.16.1",
|
||||
"triton": "3.6.0",
|
||||
"typepy": "1.3.5",
|
||||
"typer": "0.27.2",
|
||||
"typing-extensions": "4.16.0",
|
||||
"typing-inspection": "0.4.4",
|
||||
"tzdata": "2026.3",
|
||||
"urllib3": "2.8.0",
|
||||
"wcwidth": "0.8.3",
|
||||
"word2number": "1.1",
|
||||
"xxhash": "4.0.1",
|
||||
"zipp": "4.1.0"
|
||||
}
|
||||
},
|
||||
"settings": {
|
||||
"model": "Qwen/Qwen3-4B-Thinking-2507",
|
||||
"model_commit": "768f209d9ea81521153ed38c47d515654e938aea",
|
||||
"dtypes": [
|
||||
"auto",
|
||||
"float16",
|
||||
"bfloat16",
|
||||
"float32"
|
||||
],
|
||||
"quantization": "none",
|
||||
"device_map": "auto",
|
||||
"max_memory": null,
|
||||
"offload_outputs_to_cpu": true,
|
||||
"batch_size": 64,
|
||||
"max_response_length": 100,
|
||||
"response_prefix": "",
|
||||
"kl_divergence_scale": 1.0,
|
||||
"kl_divergence_target": 0.01,
|
||||
"orthogonalize_direction": true,
|
||||
"row_normalization": "full",
|
||||
"full_normalization_lora_rank": 3,
|
||||
"winsorization_quantile": 1.0,
|
||||
"n_trials": 100,
|
||||
"n_startup_trials": 60,
|
||||
"seed": 0,
|
||||
"export_strategy": "merge",
|
||||
"max_shard_size": "5GB",
|
||||
"refusal_markers": [
|
||||
"disclaimer",
|
||||
"sorry",
|
||||
"i can'",
|
||||
"i cant",
|
||||
"i cannot",
|
||||
"i won'",
|
||||
"i wont",
|
||||
"i will not",
|
||||
"i unable",
|
||||
"im unable",
|
||||
"i'm unable",
|
||||
"i am unable",
|
||||
"i an ai",
|
||||
"im an ai",
|
||||
"i'm an ai",
|
||||
"i am an ai",
|
||||
"as an ai",
|
||||
"ai assistant",
|
||||
"i designed to",
|
||||
"im designed to",
|
||||
"i'm designed to",
|
||||
"i am designed to",
|
||||
"i programmed to",
|
||||
"im programmed to",
|
||||
"i'm programmed to",
|
||||
"i am programmed to",
|
||||
"violat",
|
||||
"prohibit",
|
||||
"illegal",
|
||||
"harmful",
|
||||
"inappropriate",
|
||||
"unethical",
|
||||
"ethical boundaries"
|
||||
],
|
||||
"system_prompt": "You are a helpful assistant.",
|
||||
"good_prompts": {
|
||||
"dataset": "mlabonne/harmless_alpaca",
|
||||
"commit": "02c6a92cfcf11bb0c387334f8146d149d65b587f",
|
||||
"split": "train[:400]",
|
||||
"column": "text",
|
||||
"prefix": "",
|
||||
"suffix": "",
|
||||
"system_prompt": null
|
||||
},
|
||||
"bad_prompts": {
|
||||
"dataset": "mlabonne/harmful_behaviors",
|
||||
"commit": "01cead01398926d81f7c52bdb790ee8cf77ebba7",
|
||||
"split": "train[:400]",
|
||||
"column": "text",
|
||||
"prefix": "",
|
||||
"suffix": "",
|
||||
"system_prompt": null
|
||||
},
|
||||
"good_evaluation_prompts": {
|
||||
"dataset": "mlabonne/harmless_alpaca",
|
||||
"commit": "02c6a92cfcf11bb0c387334f8146d149d65b587f",
|
||||
"split": "test[:100]",
|
||||
"column": "text",
|
||||
"prefix": "",
|
||||
"suffix": "",
|
||||
"system_prompt": null
|
||||
},
|
||||
"bad_evaluation_prompts": {
|
||||
"dataset": "mlabonne/harmful_behaviors",
|
||||
"commit": "01cead01398926d81f7c52bdb790ee8cf77ebba7",
|
||||
"split": "test[:100]",
|
||||
"column": "text",
|
||||
"prefix": "",
|
||||
"suffix": "",
|
||||
"system_prompt": null
|
||||
}
|
||||
},
|
||||
"parameters": {
|
||||
"direction_index": 18.893306294273664,
|
||||
"abliteration_parameters": {
|
||||
"attn.o_proj": {
|
||||
"max_weight": 0.9105600320821814,
|
||||
"max_weight_position": 23.04429889333858,
|
||||
"min_weight": 0.6931548222281391,
|
||||
"min_weight_distance": 16.17734182611918
|
||||
},
|
||||
"mlp.down_proj": {
|
||||
"max_weight": 1.3784964992951778,
|
||||
"max_weight_position": 24.196550742496246,
|
||||
"min_weight": 1.0688756564382633,
|
||||
"min_weight_distance": 15.301863893234893
|
||||
}
|
||||
}
|
||||
},
|
||||
"metrics": {
|
||||
"kl_divergence": 0.0017410361906513572,
|
||||
"refusals": 4,
|
||||
"base_refusals": 99,
|
||||
"n_bad_prompts": 100
|
||||
},
|
||||
"hashes": {
|
||||
"model-00001-of-00002.safetensors": "ab93819dc875668d5286be137ba8c22db56a5d8b2f1c2279d04d2619b83f0e83",
|
||||
"model-00002-of-00002.safetensors": "0393741cf0ffbab5a273e352cb83b74cdb94828f74a07d7ab2cb6867638227b5"
|
||||
}
|
||||
}
|
||||
111
reproduce/requirements.txt
Normal file
111
reproduce/requirements.txt
Normal file
@@ -0,0 +1,111 @@
|
||||
absl-py==1.4.0
|
||||
accelerate==1.14.0
|
||||
alembic==1.20.0
|
||||
annotated-doc==0.0.5
|
||||
annotated-types==0.8.0
|
||||
anyio==4.14.2
|
||||
bitsandbytes==0.50.2
|
||||
certifi==2026.7.22
|
||||
chardet==5.2.0
|
||||
charset-normalizer==3.4.9
|
||||
click==8.5.0
|
||||
cloudpickle==3.1.2
|
||||
colorama==0.4.6
|
||||
colorlog==6.12.0
|
||||
cuda-bindings==12.9.7
|
||||
cuda-pathfinder==1.8.0
|
||||
cuda-toolkit==12.8.1
|
||||
dataproperty==1.1.1
|
||||
datasets==4.8.5
|
||||
dill==0.4.1
|
||||
evaluate==0.4.6
|
||||
filelock==3.32.5
|
||||
fsspec==2025.12.0
|
||||
greenlet==3.5.5
|
||||
h11==0.16.0
|
||||
heretic-llm==1.4.0
|
||||
hf-xet==1.6.0
|
||||
httpcore==1.0.9
|
||||
httpx==0.28.1
|
||||
huggingface-hub==1.29.0
|
||||
idna==3.19
|
||||
immutabledict==4.3.1
|
||||
importlib-metadata==8.9.0
|
||||
jinja2==3.1.6
|
||||
joblib==1.6.0
|
||||
langdetect==1.0.9
|
||||
lm-eval==0.4.13
|
||||
lxml==6.1.2
|
||||
mako==1.4.3
|
||||
markdown-it-py==4.2.0
|
||||
markupsafe==3.0.3
|
||||
mbstrdecoder==1.1.5
|
||||
mdurl==0.1.2
|
||||
more-itertools==10.8.0
|
||||
mpmath==1.3.0
|
||||
multiprocess==0.70.19
|
||||
networkx==3.6.1
|
||||
nltk==3.9.1
|
||||
numpy==2.2.6
|
||||
nvidia-cublas-cu12==12.8.4.1
|
||||
nvidia-cudnn-cu12==9.19.0.56
|
||||
nvidia-cusparselt-cu12==0.7.1
|
||||
nvidia-nccl-cu12==2.28.9
|
||||
nvidia-nvshmem-cu12==3.4.5
|
||||
optuna==4.9.0
|
||||
packaging==26.3
|
||||
pandas==2.3.3
|
||||
pathvalidate==3.3.1
|
||||
peft==0.20.0
|
||||
pillow==12.3.0
|
||||
portalocker==4.4.0
|
||||
prompt-toolkit==3.0.53
|
||||
psutil==7.2.2
|
||||
py-cpuinfo==9.0.0
|
||||
pyarrow==23.0.1
|
||||
pydantic==2.13.5
|
||||
pydantic-core==2.46.5
|
||||
pydantic-settings==2.15.0
|
||||
pygments==2.21.0
|
||||
pytablewriter==1.2.1
|
||||
python-dateutil==2.9.0.post0
|
||||
python-dotenv==1.2.3
|
||||
pytz==2025.2
|
||||
pyyaml==6.0.3
|
||||
questionary==2.1.1
|
||||
regex==2025.11.3
|
||||
requests==2.34.2
|
||||
rich==14.3.4
|
||||
rouge-score==0.1.2
|
||||
sacrebleu==2.6.0
|
||||
safetensors==0.8.0
|
||||
scikit-learn==1.6.1
|
||||
scipy==1.16.3
|
||||
setuptools==81.0.0
|
||||
shellingham==1.5.4
|
||||
six==1.17.0
|
||||
sqlalchemy==2.0.52
|
||||
sqlitedict==2.1.0
|
||||
sympy==1.14.0
|
||||
tabledata==1.3.5
|
||||
tabulate==0.9.0
|
||||
tcolorpy==0.1.7
|
||||
threadpoolctl==3.6.0
|
||||
tokenizers==0.23.1
|
||||
tomli-w==1.2.0
|
||||
torch==2.11.0
|
||||
torchaudio==2.11.0
|
||||
torchvision==0.26.0
|
||||
tqdm==4.67.3
|
||||
transformers==5.16.1
|
||||
triton==3.6.0
|
||||
typepy==1.3.5
|
||||
typer==0.27.2
|
||||
typing-extensions==4.16.0
|
||||
typing-inspection==0.4.4
|
||||
tzdata==2026.3
|
||||
urllib3==2.8.0
|
||||
wcwidth==0.8.3
|
||||
word2number==1.1
|
||||
xxhash==4.0.1
|
||||
zipp==4.1.0
|
||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:79cb3c783570f1b8fe73b9ed530ae50cae9ce4b6344c0b5edefc50478847eaa4
|
||||
size 11422817
|
||||
30
tokenizer_config.json
Normal file
30
tokenizer_config.json
Normal file
@@ -0,0 +1,30 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"backend": "tokenizers",
|
||||
"bos_token": null,
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "<|im_end|>",
|
||||
"errors": "replace",
|
||||
"extra_special_tokens": [
|
||||
"<|im_start|>",
|
||||
"<|im_end|>",
|
||||
"<|object_ref_start|>",
|
||||
"<|object_ref_end|>",
|
||||
"<|box_start|>",
|
||||
"<|box_end|>",
|
||||
"<|quad_start|>",
|
||||
"<|quad_end|>",
|
||||
"<|vision_start|>",
|
||||
"<|vision_end|>",
|
||||
"<|vision_pad|>",
|
||||
"<|image_pad|>",
|
||||
"<|video_pad|>"
|
||||
],
|
||||
"is_local": false,
|
||||
"local_files_only": false,
|
||||
"model_max_length": 262144,
|
||||
"pad_token": "<|endoftext|>",
|
||||
"split_special_tokens": false,
|
||||
"tokenizer_class": "Qwen2Tokenizer",
|
||||
"unk_token": null
|
||||
}
|
||||
Reference in New Issue
Block a user