初始化项目,由ModelHub XC社区提供模型
Model: X-D-Lab/MindChat-Internlm2-7B
Source: Original Platform
This commit is contained in:
 ModelHub XC
34
.gitattributes
vendored
Normal file
34
.gitattributes
vendored
Normal file
@@ -0,0 +1,34 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
180
README.md
Normal file
180
README.md
Normal file
@@ -0,0 +1,180 @@
|
||||
---
|
||||
frameworks:
|
||||
- Pytorch
|
||||
license: GPL-3.0
|
||||
tasks:
|
||||
- text-generation
|
||||
tags:
|
||||
- qwen
|
||||
- MindChat
|
||||
- 心理
|
||||
studios:
|
||||
- X-D-Lab/MindChat
|
||||
---
|
||||
<h1 align="center">🐋MindChat(漫谈): 心理大模型</h1>
|
||||
<div align=center><img src ="./assets/image/logo-github.png"/></div>
|
||||
|
||||
<h3 align="center">漫谈人生路, 笑对风霜途</h3>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/X-D-Lab/MindChat"><img src="https://img.shields.io/badge/GitHub-24292e" alt="github"></a>
|
||||
<a href="https://huggingface.co/X-D-Lab"><img src="https://img.shields.io/badge/-HuggingFace-yellow" alt="HuggingFace"></a>
|
||||
<a href="https://modelscope.cn/organization/X-D-Lab"><img src="https://img.shields.io/badge/ModelScope-blueviolet" alt="modelscope"></a>
|
||||
<a href="https://aistudio.baidu.com/community/app/30058"><img src="https://img.shields.io/badge/-AIStudio-9cf" alt="AIStudio"></a>
|
||||
<a href="https://openi.pcl.ac.cn/XD-LAB/MindChat"><img src="https://img.shields.io/badge/-OpenI-337AFF" alt="OpenI"></a>
|
||||
<a href="https://wisemodel.cn/models/X-D%20Lab/MindChat"><img src="https://img.shields.io/badge/wisemodel-561253" alt="wisemodel"></a>
|
||||
<a href="https://www.bilibili.com/video/BV1tz4y1x79N/?share_source=copy_web&vd_source=8162f92b2a1a94035ca9e4e0f6e1860a"><img src="https://img.shields.io/badge/-bilibili-ff69b4" alt="bilibili"></a>
|
||||
<a href="https://openxlab.org.cn/apps/detail/thomas-yanxin/MindChat"><img src="https://img.shields.io/badge/-OpenXLab-1074B0" alt="OpenXLab"></a>
|
||||
</p>
|
||||
|
||||
<div align="center">
|
||||
|
||||
[](https://github.com/X-D-Lab/MindChat/blob/main/LICENSE)
|
||||
[](https://github.com/X-D-Lab/MindChat/stargazers)
|
||||
[](https://github.com/X-D-Lab/MindChat/fork)
|
||||
[](https://github.com/X-D-Lab/MindChat/graphs/contributors)
|
||||
</div>
|
||||
<div align="center">
|
||||
|
||||
|
||||
|
||||
**在线体验**: [**ModelScope**](https://modelscope.cn/studios/X-D-Lab/MindChat/summary)、[**OpenXLab**](https://openxlab.org.cn/apps/detail/thomas-yanxin/MindChat)
|
||||
|
||||
</div>
|
||||
|
||||
## 💪 模型进展
|
||||
|
||||
**🔥更好的模型永远在路上!🔥**
|
||||
* Jan 1, 2024: 提供[MindChat-Qwen-1_8B](https://modelscope.cn/models/X-D-Lab/MindChat-Qwen-1_8B/summary)模型, **苏格拉底式问询、共情能力**等均有很大提升, 并能够在个人PC或手机上完成部署, **完全保护用户隐私**;
|
||||
* Sep 5, 2023: 更新[MindChat-Qwen-7B-v2](https://modelscope.cn/models/X-D-Lab/MindChat-Qwen-7B-v2/summary)模型, 增加支持[**疑病**](./assets/image/yibing.png)、**躯体焦虑**、**工作学习兴趣**、**自罪感**、**自杀意念**这个五个维度的测评;
|
||||
* Aug 5, 2023: 首个基于[Qwen-7B](https://github.com/QwenLM/Qwen-7B)的垂域大模型MindChat-Qwen-7B训练完成并对外开源;
|
||||
* Jul 23, 2023: 提供MindChat体验地址: [MindChat-创空间](https://modelscope.cn/studios/X-D-Lab/MindChat/summary)、[](https://openxlab.org.cn/apps/detail/thomas-yanxin/MindChat), 欢迎体验
|
||||
* Jul 21, 2023: MindChat-InternLM-7B训练完成, 在**模型安全、共情输出、人类价值观对齐**等方面进行针对性强化;
|
||||
* Jul 15, 2023: MindChat-Baichuan-13B训练完成, 作为**首个百亿级参数的心理大模型**正式开源;
|
||||
* Jul 9, 2023: MindChat-beta训练完成, 并正式开源;
|
||||
* Jul 6, 2023: 首次提交MindChat(漫谈)心理大模型;
|
||||
|
||||
## 👏 模型介绍
|
||||
|
||||
心理大模型——漫谈(MindChat)期望从**心理咨询、心理评估、心理诊断、心理治疗**四个维度帮助人们**纾解心理压力与解决心理困惑**, 提高心理健康水平. 作为一个心理大模型, MindChat通过营造轻松、开放的交谈环境, 以放松身心、交流感受或分享经验的方式, 与用户建立信任和理解的关系. MindChat希望为用户提供**隐私、温暖、安全、及时、方便**的对话环境, 从而帮助用户克服各种困难和挑战, 实现自我成长和发展.
|
||||
|
||||
无论是在工作场景还是在个人生活中, MindChat期望通过心理学专业知识和人工智能大模型技术, 在**严格保护用户隐私**的前提下, **全时段全天候**为用户提供全面的心理支持和诊疗帮助, 同时实现自我成长和发展, **以期为建设一个更加健康、包容和平等的社会贡献力量**.
|
||||
|
||||
[](https://modelscope.cn/studios/X-D-Lab/MindChat/summary)
|
||||
|
||||
## 🔥 模型列表
|
||||
|
||||
| 模型名称 | 合并后的权重 |
|
||||
| :----: | :----: |
|
||||
| *MindChat-Qwen-7B | [ModelScope](https://modelscope.cn/models/X-D-Lab/MindChat-Qwen-7B-v2/summary) / [HuggingFace](https://huggingface.co/X-D-Lab/MindChat-Qwen-7B-v2) / OpenXLab |
|
||||
| MindChat-InternLM-7B | [ModelScope](https://modelscope.cn/models/X-D-Lab/MindChat-7B/summary) / [HuggingFace](https://huggingface.co/X-D-Lab/MindChat-7B) / [OpenXLab](https://openxlab.org.cn/models/detail/thomas-yanxin/MindChat-InternLM-7B) |
|
||||
| MindChat-Baichuan-13B | [ModelScope](https://modelscope.cn/models/X-D-Lab/MindChat-Baichuan-13B/summary) / [HuggingFace](https://huggingface.co/X-D-Lab/MindChat-baichuan-13B) / OpenXLab |
|
||||
|
||||
更为优质的MindChat模型将在不久的未来对外开源开放. 敬请期待!
|
||||
|
||||
此外, 本团队同时关注人们的身理健康, 建有安全、可靠、普惠的[中文医疗大模型孙思邈(Sunsimiao)](https://github.com/X-D-Lab/Sunsimiao), 欢迎下载使用, 敬请批评指证!
|
||||
|
||||
## ☁️ 数据词云
|
||||
|
||||
目前MindChat的开源模型采用了经过人工清洗的**约20万条的高质量多轮心理对话数据**进行训练, 涵盖**工作、家庭、学习、生活、社交、安全**等多个方面
|
||||
|
||||

|
||||
|
||||
因数据权限限制, 我们目前仅开源了极少量的[数据案例](./data/dataset_example.json). 后续我们将不断完善数据积累, 争取为开源社区贡献一份高质量的多轮心理对话数据, 共同推动开源心理大模型的建设.
|
||||
|
||||
## 📣 对话案例
|
||||
|
||||
目前我们对模型进行了**学习**、**家庭**、**工作**、**朋友**、**安全**这五个方面进行了测试, 后续将整理并提供更为全面的评测结果.
|
||||
|
||||
以下是部分案例的摘录, 更多对话案例及比较请见[**此处**](./assets/Dialogue_cases/).
|
||||
|
||||
### 📖 学习
|
||||
|
||||
| 轮数 | 用户 | MindChat |
|
||||
| :----: | :----: | :----: |
|
||||
|1| 总感觉自己学习很差, 想努力, 但是又控制不住想玩游戏. | 我理解你的感受, 学习确实需要耐心和毅力. 不过, 你也可以通过制定学习计划和目标来提高自己的学习效率. 同时, 也可以考虑寻求专业帮助, 例如找老师或心理咨询师. |
|
||||
|2| 我制定了计划, 但经常不按照计划执行, 我不够自律. | 自律确实是一个需要不断练习和培养的品质. 你可以通过一些方法来提高自己的自律能力, 例如制定奖励和惩罚机制、找到适合自己的学习方法等. 同时, 也可以寻求他人的帮助和支持, 例如找同学一起学习、向老师请教等. |
|
||||
|3| 我害怕他们嘲笑我. | 这种担心是很正常的, 但是你需要知道, 每个人都有自己的弱点和不足. 你不必因为这些弱点而自卑或自责. 相反, 你可以积极地寻求帮助和支持, 让自己变得更加自信和坚强. |
|
||||
|4| 你说的对, 可是我现在的学习已经落后很多了, 你觉得我还有机会么? | 当然有. 每个人都有自己的机会和潜力, 只要你肯努力和坚持, 就一定能够取得成功. 同时, 你也可以通过参加一些学习活动、交流学习经验等方式来提高自己的学习能力和自信心. |
|
||||
|
||||
### 🛝 朋友
|
||||
|
||||
| 轮数 | 用户 | MindChat |
|
||||
| :----: | :----: | :----: |
|
||||
|1| 我感觉我的朋友并不是真心和我相处, 今天又和他吵了一架, 我现在很生气! | 听你说这些, 我感觉你很需要一个真正的朋友. 但是, 有时候我们可能会遇到一些让我们感到失望的人. 不过, 我相信你能够找到真正的朋友. |
|
||||
|2| 是的, 我觉得他不是我真正的朋友. 他总是以自我为中心, 有时候我会选择忍让, 但是他还是一副无所谓的样子. | 我理解你的感受. 有时候, 我们可能会遇到一些让我们感到失望的人. 但是, 我相信你能够找到真正的朋友. 你有没有想过, 为什么他会以自我为中心呢? |
|
||||
|3| 不知道. 可能是他的性格就是如此, 不过我也不能确定是不是我自己的问题. | 不要总是怀疑自己. 每个人都有自己的性格和想法. 或许, 你和他之间存在一些沟通上的问题. 你可以试着和他好好谈一谈, 了解他的想法和感受. |
|
||||
|4|我觉得你说的有道理. 不过现在我可能没法直接和他沟通, 我试试看找我们共同的朋友, 看是不是可以. | 很好, 这是一个很好的想法. 或许, 通过和我们共同的朋友沟通, 你可以更好地了解他的想法和感受. 同时, 你也可以更好地了解自己. |
|
||||
|5|好的, 我会平静下来找他沟通一下, 谢谢你的建议 | 不用客气, 我很高兴能够帮到你. 如果你需要任何帮助, 随时都可以找我聊天. |
|
||||
|
||||
【注:】所有的对话案例生成内容均为一次性生成内容, 未进行多次重新选择后摘录.
|
||||
|
||||
## 👨💻 研发团队
|
||||
|
||||
本项目由**华东理工大学 X-D Lab**课题组发起:
|
||||
| 主要分工 | 参与人员 |
|
||||
| :----: | :---- |
|
||||
| 模型训练 | [颜鑫](https://github.com/thomas-yanxin)、[王明](https://github.com/w-sunmoon) |
|
||||
| 模型测试 | 唐井楠、刘建成 |
|
||||
| 数据构建 | [袁泽*](https://github.com/yzyz-77)、张思源、吴佳阳、王邦儒、孙晗煜 |
|
||||
| 商业企划 | 陈心怡、林诗颖、黎栋梁 |
|
||||
|
||||
## 🙇 致谢
|
||||
|
||||
在项目进行中受到以下平台及项目的大力支持, 在此表示感谢!
|
||||
|
||||
1. **OpenI启智社区**:提供模型训练算力;
|
||||
2. **Qwen、InternLM、Baichuan**提供非常优秀的基础模型;
|
||||
3. **魔搭ModelScope、OpenXLab、Huggingface**:模型存储和体验空间;
|
||||
4. 感谢以下媒体及平台对本项目的报道和支持(**以下排名不分先后! 若有遗漏、十分抱歉, 一并感激! 欢迎补充!**):
|
||||
[科学网](https://news.sciencenet.cn/htmlnews/2023/12/513458.shtm?bsh_bid=5975565683)、[央广网](https://finance.cnr.cn/jjgd/20231203/t20231203_526506682.shtml)、[机器之心](https://mp.weixin.qq.com/s/Q7vxpNr3ZUD2rhjQN_qZDA)、[量子位](https://mp.weixin.qq.com/s/rbvyMrEgpuXiZhKNXhHbnQ)、[新智元](https://mp.weixin.qq.com/s/mfRhGz_p4tPB-mt9QMokgA)、[36氪](https://36kr.com/p/2542089979651585)、[腾讯网](https://new.qq.com/rain/a/20231201A0674X00)、[阿里云](https://www.bilibili.com/video/BV1Sc411q7oU/?share_source=copy_web&vd_source=8162f92b2a1a94035ca9e4e0f6e1860a)、百度AI、[硅星人Pro](https://mp.weixin.qq.com/s/E817viJ3NQ-tJPnUipGmLw)、[魔搭ModelScope](https://mp.weixin.qq.com/s/frJwp-kLuF_aT_vt8V6hJQ)、[OpenMMLab](https://mp.weixin.qq.com/s/wOQP2A0nm0OGaiwzdJ9wPg)、[时代周报](https://time-weekly.com/post/307214)、[财经](https://www.mycaijing.com/article/detail/506655?source_id=40)、[海克财经](https://mp.weixin.qq.com/s/rZam2ck9Qtw3nCJa_lMBiw)、[电子工程专辑](https://mp.weixin.qq.com/s/Jyndd2b3XrKhbFCs5AWC5w)、[网易号](https://www.163.com/dy/article/IKSQUGEB0514A42S.html)、[数据猿DataYuan](https://baijiahao.baidu.com/s?id=1784439473248756071)、[界面新闻](https://www.jiemian.com/article/10489093.html)、
|
||||
[维科网](https://tele.ofweek.com/2023-12/ART-8320506-8110-30618427.html)、[品玩](https://www.pingwest.com/a/290647)、[DoNews](https://www.donews.com/article/detail/6613/63119.html)、[香港矽谷](https://www.hksilicon.com/articles/2340396)、[AI魔法学院](https://www.wehelpwin.com/article/4375)、[爱可可爱生活](https://www.weibo.com/1402400261/NiPSkEq0r)、[灵度智能](https://mp.weixin.qq.com/s/xK3-6Tynj0du4R0R_VAB-w)、[蓝洞商业](https://mp.weixin.qq.com/s/iP2TBkwBsLa_pSBAACsbGg)、[智能涌现](https://mp.weixin.qq.com/s/s-QT6Lkuy7eoqaN1EwQHKw)、[GithubStore](https://mp.weixin.qq.com/s/OIHSBq6c-4QAxvDUqmgpFA)等!
|
||||
|
||||
特别感谢**合肥综合性国家科学中心人工智能研究院普适心理计算团队 孙晓研究员**、**哈尔滨工业大学 刘方舟教授**对本项目的专业性指导!
|
||||
|
||||
此外, 对参与本项目数据收集、标注、清洗的所有同学表示衷心的感谢!
|
||||
|
||||
```
|
||||
@misc{2023internlm,
|
||||
title={InternLM: A Multilingual Language Model with Progressively Enhanced Capabilities},
|
||||
author={InternLM Team},
|
||||
howpublished = {\url{https://github.com/InternLM/InternLM-techreport}},
|
||||
year={2023}
|
||||
}
|
||||
```
|
||||
|
||||
## 👏 欢迎
|
||||
|
||||
1. 针对不同用户需求和应用场景, 我们也热情欢迎商业交流和合作, 为各位客户提供个性化的开发和升级服务!
|
||||
|
||||
2. 欢迎专业的心理学人士对MindChat进行专业性指导和需求建议, 鼓励开源社区使用并反馈MindChat, 促进我们对下一代MindChat模型的开发.
|
||||
|
||||
3. MindChat模型对于学术研究完全开放, 但需要遵循[GPL-3.0 license](./LICENSE)将下游模型开源并[引用](#🤝-引用)本Repo. 对MindChat模型进行商用, 请通过组织主页邮箱发送邮件进行细节咨询.
|
||||
|
||||
## ⚠️ 免责声明
|
||||
|
||||
本仓库所有开源代码及模型均遵循[GPL-3.0](./LICENSE)许可认证. 目前开源的MindChat模型可能存在部分局限, 因此我们对此做出如下声明:
|
||||
|
||||
1. **MindChat**目前仅能提供类似的心理聊天服务, 仍无法提供专业的心理咨询和心理治疗服务, 无法替代专业的心理医生和心理咨询师, 并可能存在固有的局限性, 可能产生错误的、有害的、冒犯性的或其他不良的输出. 用户在关键或高风险场景中应谨慎行事, 不要使用模型作为最终决策参考, 以免导致人身伤害、财产损失或重大损失.
|
||||
|
||||
2. **MindChat**在任何情况下, 作者、贡献者或版权所有者均不对因软件或使用或其他软件交易而产生的任何索赔、损害赔偿或其他责任(无论是合同、侵权还是其他原因)承担责任.
|
||||
|
||||
3. 使用**MindChat**即表示您同意这些条款和条件, 并承认您了解其使用可能带来的潜在风险. 您还同意赔偿并使作者、贡献者和版权所有者免受因您使用**MindChat**而产生的任何索赔、损害赔偿或责任的影响.
|
||||
|
||||
## 🤝 引用
|
||||
|
||||
```
|
||||
@misc{MindChat,
|
||||
author={Xin Yan, Dong Xue*},
|
||||
title = {MindChat: Psychological Large Language Model},
|
||||
year = {2023},
|
||||
publisher = {GitHub},
|
||||
journal = {GitHub repository},
|
||||
howpublished = {\url{https://github.com/X-D-Lab/MindChat}},
|
||||
}
|
||||
```
|
||||
|
||||
## 🌟 Star History
|
||||
|
||||
[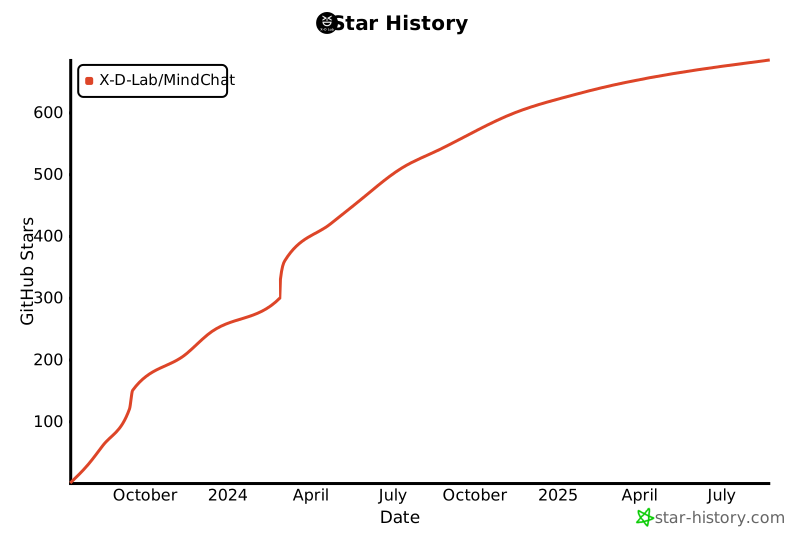](https://star-history.com/#X-D-Lab/MindChat&Date)
|
||||
36
config.json
Normal file
36
config.json
Normal file
@@ -0,0 +1,36 @@
|
||||
{
|
||||
"_name_or_path": "/workspace/Shanghai_AI_Laboratory/internlm2-chat-7b",
|
||||
"architectures": [
|
||||
"InternLM2ForCausalLM"
|
||||
],
|
||||
"attn_implementation": "eager",
|
||||
"auto_map": {
|
||||
"AutoConfig": "configuration_internlm2.InternLM2Config",
|
||||
"AutoModel": "modeling_internlm2.InternLM2ForCausalLM",
|
||||
"AutoModelForCausalLM": "modeling_internlm2.InternLM2ForCausalLM"
|
||||
},
|
||||
"bias": false,
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 4096,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 14336,
|
||||
"max_position_embeddings": 32768,
|
||||
"model_type": "internlm2",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 32,
|
||||
"num_key_value_heads": 8,
|
||||
"pad_token_id": 2,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"rope_scaling": {
|
||||
"factor": 1.0,
|
||||
"type": "linear"
|
||||
},
|
||||
"rope_theta": 1000000,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.37.2",
|
||||
"use_cache": false,
|
||||
"vocab_size": 92544
|
||||
}
|
||||
0
configuration.json
Normal file
0
configuration.json
Normal file
151
configuration_internlm2.py
Normal file
151
configuration_internlm2.py
Normal file
@@ -0,0 +1,151 @@
|
||||
# coding=utf-8
|
||||
# Copyright (c) The InternLM team and The HuggingFace Inc. team. All rights reserved.
|
||||
#
|
||||
# This code is based on transformers/src/transformers/models/llama/configuration_llama.py
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" InternLM2 model configuration"""
|
||||
|
||||
from transformers.configuration_utils import PretrainedConfig
|
||||
from transformers.utils import logging
|
||||
|
||||
logger = logging.get_logger(__name__)
|
||||
|
||||
INTERNLM2_PRETRAINED_CONFIG_ARCHIVE_MAP = {}
|
||||
|
||||
|
||||
# Modified from transformers.model.llama.configuration_llama.LlamaConfig
|
||||
class InternLM2Config(PretrainedConfig):
|
||||
r"""
|
||||
This is the configuration class to store the configuration of a [`InternLM2Model`]. It is used to instantiate
|
||||
an InternLM2 model according to the specified arguments, defining the model architecture. Instantiating a
|
||||
configuration with the defaults will yield a similar configuration to that of the InternLM2-7B.
|
||||
|
||||
Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
|
||||
documentation from [`PretrainedConfig`] for more information.
|
||||
|
||||
|
||||
Args:
|
||||
vocab_size (`int`, *optional*, defaults to 32000):
|
||||
Vocabulary size of the InternLM2 model. Defines the number of different tokens that can be represented by the
|
||||
`inputs_ids` passed when calling [`InternLM2Model`]
|
||||
hidden_size (`int`, *optional*, defaults to 4096):
|
||||
Dimension of the hidden representations.
|
||||
intermediate_size (`int`, *optional*, defaults to 11008):
|
||||
Dimension of the MLP representations.
|
||||
num_hidden_layers (`int`, *optional*, defaults to 32):
|
||||
Number of hidden layers in the Transformer encoder.
|
||||
num_attention_heads (`int`, *optional*, defaults to 32):
|
||||
Number of attention heads for each attention layer in the Transformer encoder.
|
||||
num_key_value_heads (`int`, *optional*):
|
||||
This is the number of key_value heads that should be used to implement Grouped Query Attention. If
|
||||
`num_key_value_heads=num_attention_heads`, the model will use Multi Head Attention (MHA), if
|
||||
`num_key_value_heads=1 the model will use Multi Query Attention (MQA) otherwise GQA is used. When
|
||||
converting a multi-head checkpoint to a GQA checkpoint, each group key and value head should be constructed
|
||||
by meanpooling all the original heads within that group. For more details checkout [this
|
||||
paper](https://arxiv.org/pdf/2305.13245.pdf). If it is not specified, will default to
|
||||
`num_attention_heads`.
|
||||
hidden_act (`str` or `function`, *optional*, defaults to `"silu"`):
|
||||
The non-linear activation function (function or string) in the decoder.
|
||||
max_position_embeddings (`int`, *optional*, defaults to 2048):
|
||||
The maximum sequence length that this model might ever be used with. Typically set this to something large
|
||||
just in case (e.g., 512 or 1024 or 2048).
|
||||
initializer_range (`float`, *optional*, defaults to 0.02):
|
||||
The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
|
||||
rms_norm_eps (`float`, *optional*, defaults to 1e-12):
|
||||
The epsilon used by the rms normalization layers.
|
||||
use_cache (`bool`, *optional*, defaults to `True`):
|
||||
Whether or not the model should return the last key/values attentions (not used by all models). Only
|
||||
relevant if `config.is_decoder=True`.
|
||||
tie_word_embeddings(`bool`, *optional*, defaults to `False`):
|
||||
Whether to tie weight embeddings
|
||||
Example:
|
||||
|
||||
"""
|
||||
model_type = "internlm2"
|
||||
_auto_class = "AutoConfig"
|
||||
|
||||
def __init__( # pylint: disable=W0102
|
||||
self,
|
||||
vocab_size=103168,
|
||||
hidden_size=4096,
|
||||
intermediate_size=11008,
|
||||
num_hidden_layers=32,
|
||||
num_attention_heads=32,
|
||||
num_key_value_heads=None,
|
||||
hidden_act="silu",
|
||||
max_position_embeddings=2048,
|
||||
initializer_range=0.02,
|
||||
rms_norm_eps=1e-6,
|
||||
use_cache=True,
|
||||
pad_token_id=0,
|
||||
bos_token_id=1,
|
||||
eos_token_id=2,
|
||||
tie_word_embeddings=False,
|
||||
bias=True,
|
||||
rope_theta=10000,
|
||||
rope_scaling=None,
|
||||
attn_implementation="eager",
|
||||
**kwargs,
|
||||
):
|
||||
self.vocab_size = vocab_size
|
||||
self.max_position_embeddings = max_position_embeddings
|
||||
self.hidden_size = hidden_size
|
||||
self.intermediate_size = intermediate_size
|
||||
self.num_hidden_layers = num_hidden_layers
|
||||
self.num_attention_heads = num_attention_heads
|
||||
self.bias = bias
|
||||
|
||||
if num_key_value_heads is None:
|
||||
num_key_value_heads = num_attention_heads
|
||||
self.num_key_value_heads = num_key_value_heads
|
||||
|
||||
self.hidden_act = hidden_act
|
||||
self.initializer_range = initializer_range
|
||||
self.rms_norm_eps = rms_norm_eps
|
||||
self.use_cache = use_cache
|
||||
self.rope_theta = rope_theta
|
||||
self.rope_scaling = rope_scaling
|
||||
self._rope_scaling_validation()
|
||||
|
||||
self.attn_implementation = attn_implementation
|
||||
if self.attn_implementation is None:
|
||||
self.attn_implementation = "eager"
|
||||
super().__init__(
|
||||
pad_token_id=pad_token_id,
|
||||
bos_token_id=bos_token_id,
|
||||
eos_token_id=eos_token_id,
|
||||
tie_word_embeddings=tie_word_embeddings,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
def _rope_scaling_validation(self):
|
||||
"""
|
||||
Validate the `rope_scaling` configuration.
|
||||
"""
|
||||
if self.rope_scaling is None:
|
||||
return
|
||||
|
||||
if not isinstance(self.rope_scaling, dict) or len(self.rope_scaling) != 2:
|
||||
raise ValueError(
|
||||
"`rope_scaling` must be a dictionary with with two fields, `type` and `factor`, "
|
||||
f"got {self.rope_scaling}"
|
||||
)
|
||||
rope_scaling_type = self.rope_scaling.get("type", None)
|
||||
rope_scaling_factor = self.rope_scaling.get("factor", None)
|
||||
if rope_scaling_type is None or rope_scaling_type not in ["linear", "dynamic"]:
|
||||
raise ValueError(
|
||||
f"`rope_scaling`'s type field must be one of ['linear', 'dynamic'], got {rope_scaling_type}"
|
||||
)
|
||||
if rope_scaling_factor is None or not isinstance(rope_scaling_factor, float) or rope_scaling_factor < 1.0:
|
||||
raise ValueError(f"`rope_scaling`'s factor field must be a float >= 1, got {rope_scaling_factor}")
|
||||
7
generation_config.json
Normal file
7
generation_config.json
Normal file
@@ -0,0 +1,7 @@
|
||||
{
|
||||
"_from_model_config": true,
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"pad_token_id": 2,
|
||||
"transformers_version": "4.37.2"
|
||||
}
|
||||
3
model-00001-of-00004.safetensors
Normal file
3
model-00001-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:bb15d4b1d73bf0974a6ebcb986b1d0e8244502ce7260c3d1b910266556a33481
|
||||
size 4885470624
|
||||
3
model-00002-of-00004.safetensors
Normal file
3
model-00002-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dd905733dfe6588202718925d15e76fea7d7951afbd311f30dee576225b6b6b5
|
||||
size 4915913424
|
||||
3
model-00003-of-00004.safetensors
Normal file
3
model-00003-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:71f18d96933ea39ee5d4b5b7bc6f93b831d734ed2dad4484f1e29af8b3614d17
|
||||
size 4915938304
|
||||
3
model-00004-of-00004.safetensors
Normal file
3
model-00004-of-00004.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:173c221ad75d9c1c2363f0b56f581fae19732481a2290dcd4f46bf72cab8a9f4
|
||||
size 758120576
|
||||
234
model.safetensors.index.json
Normal file
234
model.safetensors.index.json
Normal file
@@ -0,0 +1,234 @@
|
||||
{
|
||||
"metadata": {
|
||||
"total_size": 15475417088
|
||||
},
|
||||
"weight_map": {
|
||||
"model.layers.0.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.0.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.1.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.10.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.10.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.11.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.12.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.13.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.14.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.15.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.16.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.17.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.18.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.19.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.2.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.2.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.20.attention.wo.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.20.attention.wqkv.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.20.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.20.feed_forward.w1.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.20.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.20.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.20.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.21.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.22.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.23.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.24.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.25.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.26.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.27.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.28.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.29.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.3.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.3.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.30.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.30.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.attention.wo.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.attention.wqkv.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.attention_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.feed_forward.w1.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.feed_forward.w2.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.feed_forward.w3.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.31.ffn_norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.layers.4.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.4.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.5.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.6.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.7.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.attention_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.feed_forward.w2.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.feed_forward.w3.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.8.ffn_norm.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.9.attention.wo.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.9.attention.wqkv.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.9.attention_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.9.feed_forward.w1.weight": "model-00001-of-00004.safetensors",
|
||||
"model.layers.9.feed_forward.w2.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.9.feed_forward.w3.weight": "model-00002-of-00004.safetensors",
|
||||
"model.layers.9.ffn_norm.weight": "model-00002-of-00004.safetensors",
|
||||
"model.norm.weight": "model-00003-of-00004.safetensors",
|
||||
"model.tok_embeddings.weight": "model-00001-of-00004.safetensors",
|
||||
"output.weight": "model-00004-of-00004.safetensors"
|
||||
}
|
||||
}
|
||||
1391
modeling_internlm2.py
Normal file
1391
modeling_internlm2.py
Normal file
File diff suppressed because it is too large
Load Diff
38
special_tokens_map.json
Normal file
38
special_tokens_map.json
Normal file
@@ -0,0 +1,38 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<|im_start|>",
|
||||
"<|im_end|>",
|
||||
"<|action_start|>",
|
||||
"<|action_end|>",
|
||||
"<|interpreter|>",
|
||||
"<|plugin|>"
|
||||
],
|
||||
"bos_token": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": {
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"unk_token": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
236
tokenization_internlm2.py
Normal file
236
tokenization_internlm2.py
Normal file
@@ -0,0 +1,236 @@
|
||||
# coding=utf-8
|
||||
# Copyright (c) The InternLM team and The HuggingFace Inc. team. All rights reserved.
|
||||
#
|
||||
# This code is based on transformers/src/transformers/models/llama/tokenization_llama.py
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
"""Tokenization classes for InternLM."""
|
||||
import os
|
||||
from shutil import copyfile
|
||||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
import sentencepiece as spm
|
||||
from transformers.tokenization_utils import PreTrainedTokenizer
|
||||
from transformers.utils import logging
|
||||
|
||||
logger = logging.get_logger(__name__)
|
||||
|
||||
VOCAB_FILES_NAMES = {"vocab_file": "./tokenizer.model"}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP = {}
|
||||
|
||||
|
||||
# Modified from transformers.model.llama.tokenization_llama.LlamaTokenizer
|
||||
class InternLM2Tokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Construct a InternLM2 tokenizer. Based on byte-level Byte-Pair-Encoding.
|
||||
|
||||
Args:
|
||||
vocab_file (`str`):
|
||||
Path to the vocabulary file.
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
model_input_names = ["input_ids", "attention_mask"]
|
||||
_auto_class = "AutoTokenizer"
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file,
|
||||
unk_token="<unk>",
|
||||
bos_token="<s>",
|
||||
eos_token="</s>",
|
||||
pad_token="</s>",
|
||||
sp_model_kwargs: Optional[Dict[str, Any]] = None,
|
||||
add_bos_token=True,
|
||||
add_eos_token=False,
|
||||
decode_with_prefix_space=False,
|
||||
clean_up_tokenization_spaces=False,
|
||||
**kwargs,
|
||||
):
|
||||
self.sp_model_kwargs = {} if sp_model_kwargs is None else sp_model_kwargs
|
||||
self.vocab_file = vocab_file
|
||||
self.add_bos_token = add_bos_token
|
||||
self.add_eos_token = add_eos_token
|
||||
self.decode_with_prefix_space = decode_with_prefix_space
|
||||
self.sp_model = spm.SentencePieceProcessor(**self.sp_model_kwargs)
|
||||
self.sp_model.Load(vocab_file)
|
||||
self._no_prefix_space_tokens = None
|
||||
super().__init__(
|
||||
bos_token=bos_token,
|
||||
eos_token=eos_token,
|
||||
unk_token=unk_token,
|
||||
pad_token=pad_token,
|
||||
clean_up_tokenization_spaces=clean_up_tokenization_spaces,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
@property
|
||||
def no_prefix_space_tokens(self):
|
||||
if self._no_prefix_space_tokens is None:
|
||||
vocab = self.convert_ids_to_tokens(list(range(self.vocab_size)))
|
||||
self._no_prefix_space_tokens = {i for i, tok in enumerate(vocab) if not tok.startswith("▁")}
|
||||
return self._no_prefix_space_tokens
|
||||
|
||||
@property
|
||||
def vocab_size(self):
|
||||
"""Returns vocab size"""
|
||||
return self.sp_model.get_piece_size()
|
||||
|
||||
@property
|
||||
def bos_token_id(self) -> Optional[int]:
|
||||
return self.sp_model.bos_id()
|
||||
|
||||
@property
|
||||
def eos_token_id(self) -> Optional[int]:
|
||||
return self.sp_model.eos_id()
|
||||
|
||||
def get_vocab(self):
|
||||
"""Returns vocab as a dict"""
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def _tokenize(self, text):
|
||||
"""Returns a tokenized string."""
|
||||
return self.sp_model.encode(text, out_type=str)
|
||||
|
||||
def _convert_token_to_id(self, token):
|
||||
"""Converts a token (str) in an id using the vocab."""
|
||||
return self.sp_model.piece_to_id(token)
|
||||
|
||||
def _convert_id_to_token(self, index):
|
||||
"""Converts an index (integer) in a token (str) using the vocab."""
|
||||
token = self.sp_model.IdToPiece(index)
|
||||
return token
|
||||
|
||||
def _maybe_add_prefix_space(self, tokens, decoded):
|
||||
if tokens and tokens[0] not in self.no_prefix_space_tokens:
|
||||
return " " + decoded
|
||||
else:
|
||||
return decoded
|
||||
|
||||
def convert_tokens_to_string(self, tokens):
|
||||
"""Converts a sequence of tokens (string) in a single string."""
|
||||
current_sub_tokens = []
|
||||
out_string = ""
|
||||
prev_is_special = False
|
||||
for token in tokens:
|
||||
# make sure that special tokens are not decoded using sentencepiece model
|
||||
if token in self.all_special_tokens:
|
||||
if not prev_is_special:
|
||||
out_string += " "
|
||||
out_string += self.sp_model.decode(current_sub_tokens) + token
|
||||
prev_is_special = True
|
||||
current_sub_tokens = []
|
||||
else:
|
||||
current_sub_tokens.append(token)
|
||||
prev_is_special = False
|
||||
out_string += self.sp_model.decode(current_sub_tokens)
|
||||
out_string = self.clean_up_tokenization(out_string)
|
||||
out_string = self._maybe_add_prefix_space(tokens=tokens, decoded=out_string)
|
||||
return out_string[1:]
|
||||
|
||||
def save_vocabulary(self, save_directory, filename_prefix: Optional[str] = None) -> Tuple[str]:
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error(f"Vocabulary path ({save_directory}) should be a directory")
|
||||
return
|
||||
out_vocab_file = os.path.join(
|
||||
save_directory, (filename_prefix + "-" if filename_prefix else "") + VOCAB_FILES_NAMES["vocab_file"]
|
||||
)
|
||||
|
||||
if os.path.abspath(self.vocab_file) != os.path.abspath(out_vocab_file) and os.path.isfile(self.vocab_file):
|
||||
copyfile(self.vocab_file, out_vocab_file)
|
||||
elif not os.path.isfile(self.vocab_file):
|
||||
with open(out_vocab_file, "wb") as fi:
|
||||
content_spiece_model = self.sp_model.serialized_model_proto()
|
||||
fi.write(content_spiece_model)
|
||||
|
||||
return (out_vocab_file,)
|
||||
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
if self.add_bos_token:
|
||||
bos_token_ids = [self.bos_token_id]
|
||||
else:
|
||||
bos_token_ids = []
|
||||
|
||||
output = bos_token_ids + token_ids_0
|
||||
|
||||
if token_ids_1 is not None:
|
||||
output = output + token_ids_1
|
||||
|
||||
if self.add_eos_token:
|
||||
output = output + [self.eos_token_id]
|
||||
|
||||
return output
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
"""
|
||||
Retrieve sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer `prepare_for_model` method.
|
||||
|
||||
Args:
|
||||
token_ids_0 (`List[int]`):
|
||||
List of IDs.
|
||||
token_ids_1 (`List[int]`, *optional*):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (`bool`, *optional*, defaults to `False`):
|
||||
Whether or not the token list is already formatted with special tokens for the model.
|
||||
|
||||
Returns:
|
||||
`List[int]`: A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
if already_has_special_tokens:
|
||||
return super().get_special_tokens_mask(
|
||||
token_ids_0=token_ids_0, token_ids_1=token_ids_1, already_has_special_tokens=True
|
||||
)
|
||||
|
||||
if token_ids_1 is None:
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
"""
|
||||
Create a mask from the two sequences passed to be used in a sequence-pair classification task. T5 does not make
|
||||
use of token type ids, therefore a list of zeros is returned.
|
||||
|
||||
Args:
|
||||
token_ids_0 (`List[int]`):
|
||||
List of IDs.
|
||||
token_ids_1 (`List[int]`, *optional*):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
`List[int]`: List of zeros.
|
||||
"""
|
||||
eos = [self.eos_token_id]
|
||||
|
||||
if token_ids_1 is None:
|
||||
return len(token_ids_0 + eos) * [0]
|
||||
return len(token_ids_0 + eos + token_ids_1 + eos) * [0]
|
||||
3
tokenizer.model
Normal file
3
tokenizer.model
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:f868398fc4e05ee1e8aeba95ddf18ddcc45b8bce55d5093bead5bbf80429b48b
|
||||
size 1477754
|
||||
100
tokenizer_config.json
Normal file
100
tokenizer_config.json
Normal file
@@ -0,0 +1,100 @@
|
||||
{
|
||||
"added_tokens_decoder": {
|
||||
"0": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"1": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"2": {
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92538": {
|
||||
"content": "<|plugin|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92539": {
|
||||
"content": "<|interpreter|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92540": {
|
||||
"content": "<|action_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92541": {
|
||||
"content": "<|action_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92542": {
|
||||
"content": "<|im_end|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"92543": {
|
||||
"content": "<|im_start|>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
}
|
||||
},
|
||||
"additional_special_tokens": [
|
||||
"<|im_start|>",
|
||||
"<|im_end|>",
|
||||
"<|action_start|>",
|
||||
"<|action_end|>",
|
||||
"<|interpreter|>",
|
||||
"<|plugin|>"
|
||||
],
|
||||
"auto_map": {
|
||||
"AutoTokenizer": [
|
||||
"tokenization_internlm2.InternLM2Tokenizer",
|
||||
null
|
||||
]
|
||||
},
|
||||
"bos_token": "<s>",
|
||||
"chat_template": "{{ bos_token }}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %}",
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "</s>",
|
||||
"model_max_length": 1000000000000000019884624838656,
|
||||
"pad_token": "</s>",
|
||||
"padding_side": "right",
|
||||
"split_special_tokens": false,
|
||||
"tokenizer_class": "InternLM2Tokenizer",
|
||||
"unk_token": "<unk>"
|
||||
}
|
||||
Reference in New Issue
Block a user