初始化项目,由ModelHub XC社区提供模型
Model: TheBloke/wizard-vicuna-13B-HF
Source: Original Platform
This commit is contained in:
 ModelHub XC
37
.gitattributes
vendored
Normal file
37
.gitattributes
vendored
Normal file
@@ -0,0 +1,37 @@
|
|||||||
|
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.model filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||||
|
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||||
|
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||||
|
pytorch_model-00001-of-00003.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
pytorch_model-00002-of-00003.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
|
pytorch_model-00003-of-00003.bin filter=lfs diff=lfs merge=lfs -text
|
||||||
128
README.md
Normal file
128
README.md
Normal file
@@ -0,0 +1,128 @@
|
|||||||
|
---
|
||||||
|
language:
|
||||||
|
- en
|
||||||
|
tags:
|
||||||
|
- causal-lm
|
||||||
|
- llama
|
||||||
|
---
|
||||||
|
<!-- header start -->
|
||||||
|
<div style="width: 100%;">
|
||||||
|
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
|
||||||
|
</div>
|
||||||
|
<div style="display: flex; justify-content: space-between; width: 100%;">
|
||||||
|
<div style="display: flex; flex-direction: column; align-items: flex-start;">
|
||||||
|
<p><a href="https://discord.gg/Jq4vkcDakD">Chat & support: my new Discord server</a></p>
|
||||||
|
</div>
|
||||||
|
<div style="display: flex; flex-direction: column; align-items: flex-end;">
|
||||||
|
<p><a href="https://www.patreon.com/TheBlokeAI">Want to contribute? TheBloke's Patreon page</a></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
<!-- header end -->
|
||||||
|
# Wizard-Vicuna-13B-HF
|
||||||
|
|
||||||
|
This is a float16 HF format repo for [junelee's wizard-vicuna 13B](https://huggingface.co/junelee/wizard-vicuna-13b).
|
||||||
|
|
||||||
|
June Lee's repo was also HF format. The reason I've made this is that the original repo was in float32, meaning it required 52GB disk space, VRAM and RAM.
|
||||||
|
|
||||||
|
This model was converted to float16 to make it easier to load and manage.
|
||||||
|
|
||||||
|
## Repositories available
|
||||||
|
|
||||||
|
* [4bit GPTQ models for GPU inference](https://huggingface.co/TheBloke/wizard-vicuna-13B-GPTQ).
|
||||||
|
* [4bit and 5bit GGML models for CPU inference](https://huggingface.co/TheBloke/wizard-vicuna-13B-GGML).
|
||||||
|
* [float16 HF format model for GPU inference](https://huggingface.co/TheBloke/wizard-vicuna-13B-HF).
|
||||||
|
|
||||||
|
<!-- footer start -->
|
||||||
|
## Discord
|
||||||
|
|
||||||
|
For further support, and discussions on these models and AI in general, join us at:
|
||||||
|
|
||||||
|
[TheBloke AI's Discord server](https://discord.gg/Jq4vkcDakD)
|
||||||
|
|
||||||
|
## Thanks, and how to contribute.
|
||||||
|
|
||||||
|
Thanks to the [chirper.ai](https://chirper.ai) team!
|
||||||
|
|
||||||
|
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
|
||||||
|
|
||||||
|
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
|
||||||
|
|
||||||
|
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
|
||||||
|
|
||||||
|
* Patreon: https://patreon.com/TheBlokeAI
|
||||||
|
* Ko-Fi: https://ko-fi.com/TheBlokeAI
|
||||||
|
|
||||||
|
**Patreon special mentions**: Aemon Algiz, Dmitriy Samsonov, Nathan LeClaire, Trenton Dambrowitz, Mano Prime, David Flickinger, vamX, Nikolai Manek, senxiiz, Khalefa Al-Ahmad, Illia Dulskyi, Jonathan Leane, Talal Aujan, V. Lukas, Joseph William Delisle, Pyrater, Oscar Rangel, Lone Striker, Luke Pendergrass, Eugene Pentland, Sebastain Graf, Johann-Peter Hartman.
|
||||||
|
|
||||||
|
Thank you to all my generous patrons and donaters!
|
||||||
|
<!-- footer end -->
|
||||||
|
|
||||||
|
# Original WizardVicuna-13B model card
|
||||||
|
|
||||||
|
Github page: https://github.com/melodysdreamj/WizardVicunaLM
|
||||||
|
|
||||||
|
# WizardVicunaLM
|
||||||
|
### Wizard's dataset + ChatGPT's conversation extension + Vicuna's tuning method
|
||||||
|
I am a big fan of the ideas behind WizardLM and VicunaLM. I particularly like the idea of WizardLM handling the dataset itself more deeply and broadly, as well as VicunaLM overcoming the limitations of single-turn conversations by introducing multi-round conversations. As a result, I combined these two ideas to create WizardVicunaLM. This project is highly experimental and designed for proof of concept, not for actual usage.
|
||||||
|
|
||||||
|
|
||||||
|
## Benchmark
|
||||||
|
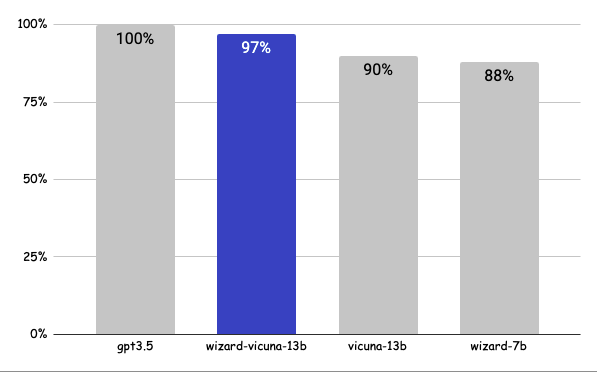
### Approximately 7% performance improvement over VicunaLM
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
### Detail
|
||||||
|
|
||||||
|
The questions presented here are not from rigorous tests, but rather, I asked a few questions and requested GPT-4 to score them. The models compared were ChatGPT 3.5, WizardVicunaLM, VicunaLM, and WizardLM, in that order.
|
||||||
|
|
||||||
|
| | gpt3.5 | wizard-vicuna-13b | vicuna-13b | wizard-7b | link |
|
||||||
|
|-----|--------|-------------------|------------|-----------|----------|
|
||||||
|
| Q1 | 95 | 90 | 85 | 88 | [link](https://sharegpt.com/c/YdhIlby) |
|
||||||
|
| Q2 | 95 | 97 | 90 | 89 | [link](https://sharegpt.com/c/YOqOV4g) |
|
||||||
|
| Q3 | 85 | 90 | 80 | 65 | [link](https://sharegpt.com/c/uDmrcL9) |
|
||||||
|
| Q4 | 90 | 85 | 80 | 75 | [link](https://sharegpt.com/c/XBbK5MZ) |
|
||||||
|
| Q5 | 90 | 85 | 80 | 75 | [link](https://sharegpt.com/c/AQ5tgQX) |
|
||||||
|
| Q6 | 92 | 85 | 87 | 88 | [link](https://sharegpt.com/c/eVYwfIr) |
|
||||||
|
| Q7 | 95 | 90 | 85 | 92 | [link](https://sharegpt.com/c/Kqyeub4) |
|
||||||
|
| Q8 | 90 | 85 | 75 | 70 | [link](https://sharegpt.com/c/M0gIjMF) |
|
||||||
|
| Q9 | 92 | 85 | 70 | 60 | [link](https://sharegpt.com/c/fOvMtQt) |
|
||||||
|
| Q10 | 90 | 80 | 75 | 85 | [link](https://sharegpt.com/c/YYiCaUz) |
|
||||||
|
| Q11 | 90 | 85 | 75 | 65 | [link](https://sharegpt.com/c/HMkKKGU) |
|
||||||
|
| Q12 | 85 | 90 | 80 | 88 | [link](https://sharegpt.com/c/XbW6jgB) |
|
||||||
|
| Q13 | 90 | 95 | 88 | 85 | [link](https://sharegpt.com/c/JXZb7y6) |
|
||||||
|
| Q14 | 94 | 89 | 90 | 91 | [link](https://sharegpt.com/c/cTXH4IS) |
|
||||||
|
| Q15 | 90 | 85 | 88 | 87 | [link](https://sharegpt.com/c/GZiM0Yt) |
|
||||||
|
| | 91 | 88 | 82 | 80 | |
|
||||||
|
|
||||||
|
|
||||||
|
## Principle
|
||||||
|
|
||||||
|
We adopted the approach of WizardLM, which is to extend a single problem more in-depth. However, instead of using individual instructions, we expanded it using Vicuna's conversation format and applied Vicuna's fine-tuning techniques.
|
||||||
|
|
||||||
|
Turning a single command into a rich conversation is what we've done [here](https://sharegpt.com/c/6cmxqq0).
|
||||||
|
|
||||||
|
After creating the training data, I later trained it according to the Vicuna v1.1 [training method](https://github.com/lm-sys/FastChat/blob/main/scripts/train_vicuna_13b.sh).
|
||||||
|
|
||||||
|
|
||||||
|
## Detailed Method
|
||||||
|
|
||||||
|
First, we explore and expand various areas in the same topic using the 7K conversations created by WizardLM. However, we made it in a continuous conversation format instead of the instruction format. That is, it starts with WizardLM's instruction, and then expands into various areas in one conversation using ChatGPT 3.5.
|
||||||
|
|
||||||
|
After that, we applied the following model using Vicuna's fine-tuning format.
|
||||||
|
|
||||||
|
## Training Process
|
||||||
|
|
||||||
|
Trained with 8 A100 GPUs for 35 hours.
|
||||||
|
|
||||||
|
## Weights
|
||||||
|
You can see the [dataset](https://huggingface.co/datasets/junelee/wizard_vicuna_70k) we used for training and the [13b model](https://huggingface.co/junelee/wizard-vicuna-13b) in the huggingface.
|
||||||
|
|
||||||
|
## Conclusion
|
||||||
|
If we extend the conversation to gpt4 32K, we can expect a dramatic improvement, as we can generate 8x more, more accurate and richer conversations.
|
||||||
|
|
||||||
|
## License
|
||||||
|
The model is licensed under the LLaMA model, and the dataset is licensed under the terms of OpenAI because it uses ChatGPT. Everything else is free.
|
||||||
|
|
||||||
|
## Author
|
||||||
|
|
||||||
|
[JUNE LEE](https://github.com/melodysdreamj) - He is active in Songdo Artificial Intelligence Study and GDG Songdo.
|
||||||
23
config.json
Normal file
23
config.json
Normal file
@@ -0,0 +1,23 @@
|
|||||||
|
{
|
||||||
|
"_name_or_path": "/workspace/models/junelee_wizard-vicuna-13b",
|
||||||
|
"architectures": [
|
||||||
|
"LlamaForCausalLM"
|
||||||
|
],
|
||||||
|
"bos_token_id": 1,
|
||||||
|
"eos_token_id": 2,
|
||||||
|
"hidden_act": "silu",
|
||||||
|
"hidden_size": 5120,
|
||||||
|
"initializer_range": 0.02,
|
||||||
|
"intermediate_size": 13824,
|
||||||
|
"max_position_embeddings": 2048,
|
||||||
|
"model_type": "llama",
|
||||||
|
"num_attention_heads": 40,
|
||||||
|
"num_hidden_layers": 40,
|
||||||
|
"pad_token_id": 0,
|
||||||
|
"rms_norm_eps": 1e-06,
|
||||||
|
"tie_word_embeddings": false,
|
||||||
|
"torch_dtype": "float16",
|
||||||
|
"transformers_version": "4.28.1",
|
||||||
|
"use_cache": true,
|
||||||
|
"vocab_size": 32000
|
||||||
|
}
|
||||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||||
7
generation_config.json
Normal file
7
generation_config.json
Normal file
@@ -0,0 +1,7 @@
|
|||||||
|
{
|
||||||
|
"_from_model_config": true,
|
||||||
|
"bos_token_id": 1,
|
||||||
|
"eos_token_id": 2,
|
||||||
|
"pad_token_id": 0,
|
||||||
|
"transformers_version": "4.28.1"
|
||||||
|
}
|
||||||
3
pytorch_model-00001-of-00003.bin
Normal file
3
pytorch_model-00001-of-00003.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:8e5f81c415d27aa6d0bf85af9bdd370c9a983eebeecf959defb5c084f6e77664
|
||||||
|
size 8926320038
|
||||||
3
pytorch_model-00002-of-00003.bin
Normal file
3
pytorch_model-00002-of-00003.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:e8671432ed93ad011f334a1afba809b404f962fb3d6c6a9ecf0fcdab2543bf84
|
||||||
|
size 8881777307
|
||||||
3
pytorch_model-00003-of-00003.bin
Normal file
3
pytorch_model-00003-of-00003.bin
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
version https://git-lfs.github.com/spec/v1
|
||||||
|
oid sha256:cd04ca878d1884346f1af7f53e9de5ff0959d9e0762e52c4b9ec48ce2733b237
|
||||||
|
size 8223780237
|
||||||
410
pytorch_model.bin.index.json
Normal file
410
pytorch_model.bin.index.json
Normal file
@@ -0,0 +1,410 @@
|
|||||||
|
{
|
||||||
|
"metadata": {
|
||||||
|
"total_size": 26031733760
|
||||||
|
},
|
||||||
|
"weight_map": {
|
||||||
|
"lm_head.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.embed_tokens.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.0.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.1.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.10.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.11.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.12.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.13.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.13.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.13.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.13.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.13.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.14.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.14.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.15.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.16.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.17.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.18.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.19.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.2.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.2.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.20.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.20.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.21.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.22.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.23.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.24.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.25.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.input_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.mlp.down_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.mlp.up_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.post_attention_layernorm.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.26.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.27.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.27.mlp.gate_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.27.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.27.self_attn.k_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.self_attn.o_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.self_attn.q_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.self_attn.rotary_emb.inv_freq": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.27.self_attn.v_proj.weight": "pytorch_model-00002-of-00003.bin",
|
||||||
|
"model.layers.28.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.28.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.29.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.3.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.3.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.30.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.30.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.31.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.32.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.33.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.34.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.35.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.36.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.37.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.38.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.input_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.mlp.down_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.mlp.gate_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.mlp.up_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.post_attention_layernorm.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.self_attn.k_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.self_attn.o_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.self_attn.q_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.self_attn.rotary_emb.inv_freq": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.39.self_attn.v_proj.weight": "pytorch_model-00003-of-00003.bin",
|
||||||
|
"model.layers.4.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.4.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.5.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.6.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.7.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.8.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.input_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.mlp.down_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.mlp.gate_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.mlp.up_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.post_attention_layernorm.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.self_attn.k_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.self_attn.o_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.self_attn.q_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.self_attn.rotary_emb.inv_freq": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.layers.9.self_attn.v_proj.weight": "pytorch_model-00001-of-00003.bin",
|
||||||
|
"model.norm.weight": "pytorch_model-00003-of-00003.bin"
|
||||||
|
}
|
||||||
|
}
|
||||||
24
special_tokens_map.json
Normal file
24
special_tokens_map.json
Normal file
@@ -0,0 +1,24 @@
|
|||||||
|
{
|
||||||
|
"bos_token": {
|
||||||
|
"content": "<s>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"eos_token": {
|
||||||
|
"content": "</s>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"pad_token": "<unk>",
|
||||||
|
"unk_token": {
|
||||||
|
"content": "<unk>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
}
|
||||||
|
}
|
||||||
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
34
tokenizer_config.json
Normal file
34
tokenizer_config.json
Normal file
@@ -0,0 +1,34 @@
|
|||||||
|
{
|
||||||
|
"add_bos_token": true,
|
||||||
|
"add_eos_token": false,
|
||||||
|
"bos_token": {
|
||||||
|
"__type": "AddedToken",
|
||||||
|
"content": "<s>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"clean_up_tokenization_spaces": false,
|
||||||
|
"eos_token": {
|
||||||
|
"__type": "AddedToken",
|
||||||
|
"content": "</s>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
},
|
||||||
|
"model_max_length": 2048,
|
||||||
|
"pad_token": null,
|
||||||
|
"padding_side": "right",
|
||||||
|
"sp_model_kwargs": {},
|
||||||
|
"tokenizer_class": "LlamaTokenizer",
|
||||||
|
"unk_token": {
|
||||||
|
"__type": "AddedToken",
|
||||||
|
"content": "<unk>",
|
||||||
|
"lstrip": false,
|
||||||
|
"normalized": true,
|
||||||
|
"rstrip": false,
|
||||||
|
"single_word": false
|
||||||
|
}
|
||||||
|
}
|
||||||
Reference in New Issue
Block a user