初始化项目,由ModelHub XC社区提供模型
Model: QuantTrio/Qwen3-VL-30B-A3B-Thinking-AWQ
Source: Original Platform
This commit is contained in:
 ModelHub XC
58
.gitattributes
vendored
Normal file
58
.gitattributes
vendored
Normal file
@@ -0,0 +1,58 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.gguf* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ggml filter=lfs diff=lfs merge=lfs -text
|
||||
*.llamafile* filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
|
||||
vocab.json filter=lfs diff=lfs merge=lfs -text
|
||||
model-00004-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
model-00003-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
model-00006-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
||||
model-00001-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
model-00005-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
merges.txt filter=lfs diff=lfs merge=lfs -text
|
||||
model-00002-of-00006.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
model.safetensors.index.json filter=lfs diff=lfs merge=lfs -text
|
||||
230
README.md
Normal file
230
README.md
Normal file
@@ -0,0 +1,230 @@
|
||||
---
|
||||
library_name: transformers
|
||||
license: apache-2.0
|
||||
pipeline_tag: text-generation
|
||||
tags:
|
||||
- AWQ
|
||||
- vLLM
|
||||
base_model:
|
||||
- Qwen/Qwen3-VL-30B-A3B-Thinking
|
||||
base_model_relation: quantized
|
||||
---
|
||||
# Qwen3-VL-30B-A3B-Thinking-AWQ
|
||||
Base Model: [Qwen/Qwen3-VL-30B-A3B-Thinking](https://www.modelscope.cn/models/Qwen/Qwen3-VL-30B-A3B-Thinking)
|
||||
|
||||
### 【Dependencies / Installation】
|
||||
As of **2025-10-08**, create a fresh Python environment and run:
|
||||
```bash
|
||||
uv venv
|
||||
source .venv/bin/activate
|
||||
|
||||
# Install vLLM >=0.11.0
|
||||
uv pip install -U vllm
|
||||
|
||||
# Install Qwen-VL utility library (recommended for offline inference)
|
||||
uv pip install qwen-vl-utils==0.0.14
|
||||
```
|
||||
|
||||
For more details, refer to [vLLM Official Qwen3-VL Guide](https://docs.vllm.ai/projects/recipes/en/latest/Qwen/Qwen3-VL.html)
|
||||
|
||||
### 【vLLM Startup Command】
|
||||
|
||||
```
|
||||
CONTEXT_LENGTH=32768
|
||||
|
||||
vllm serve \
|
||||
tclf90/Qwen3-VL-30B-A3B-Thinking-AWQ \
|
||||
--served-model-name My_Model \
|
||||
--swap-space 4 \
|
||||
--max-num-seqs 8 \
|
||||
--max-model-len $CONTEXT_LENGTH \
|
||||
--gpu-memory-utilization 0.9 \
|
||||
--tensor-parallel-size 2 \
|
||||
--trust-remote-code \
|
||||
--disable-log-requests \
|
||||
--host 0.0.0.0 \
|
||||
--port 8000
|
||||
```
|
||||
|
||||
### 【Logs】
|
||||
```
|
||||
2025-10-04
|
||||
1. Initial commit
|
||||
```
|
||||
|
||||
### 【Model Files】
|
||||
| File Size | Last Updated |
|
||||
|-----------|--------------|
|
||||
| `17GB` | `2025-10-04` |
|
||||
|
||||
### 【Model Download】
|
||||
```python
|
||||
from modelscope import snapshot_download
|
||||
snapshot_download('tclf90/Qwen3-VL-30B-A3B-Thinking-AWQ', cache_dir="your_local_path")
|
||||
```
|
||||
|
||||
### 【Overview】
|
||||
<a href="https://chat.qwenlm.ai/" target="_blank" style="margin: 2px;">
|
||||
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
||||
</a>
|
||||
|
||||
# Qwen3-VL-30B-A3B-Thinking
|
||||
|
||||
|
||||
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
|
||||
|
||||
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
|
||||
|
||||
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
|
||||
|
||||
|
||||
#### Key Enhancements:
|
||||
|
||||
* **Visual Agent**: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
|
||||
|
||||
* **Visual Coding Boost**: Generates Draw.io/HTML/CSS/JS from images/videos.
|
||||
|
||||
* **Advanced Spatial Perception**: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
|
||||
|
||||
* **Long Context & Video Understanding**: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
|
||||
|
||||
* **Enhanced Multimodal Reasoning**: Excels in STEM/Math—causal analysis and logical, evidence-based answers.
|
||||
|
||||
* **Upgraded Visual Recognition**: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
|
||||
|
||||
* **Expanded OCR**: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
|
||||
|
||||
* **Text Understanding on par with pure LLMs**: Seamless text–vision fusion for lossless, unified comprehension.
|
||||
|
||||
|
||||
#### Model Architecture Updates:
|
||||
|
||||
<p align="center">
|
||||
<img src="https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/qwen3vl_arc.jpg" width="80%"/>
|
||||
<p>
|
||||
|
||||
|
||||
1. **Interleaved-MRoPE**: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning.
|
||||
|
||||
2. **DeepStack**: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment.
|
||||
|
||||
3. **Text–Timestamp Alignment:** Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling.
|
||||
|
||||
|
||||
This is the weight repository for Qwen3-VL-30B-A3B-Thinking.
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Model Performance
|
||||
|
||||
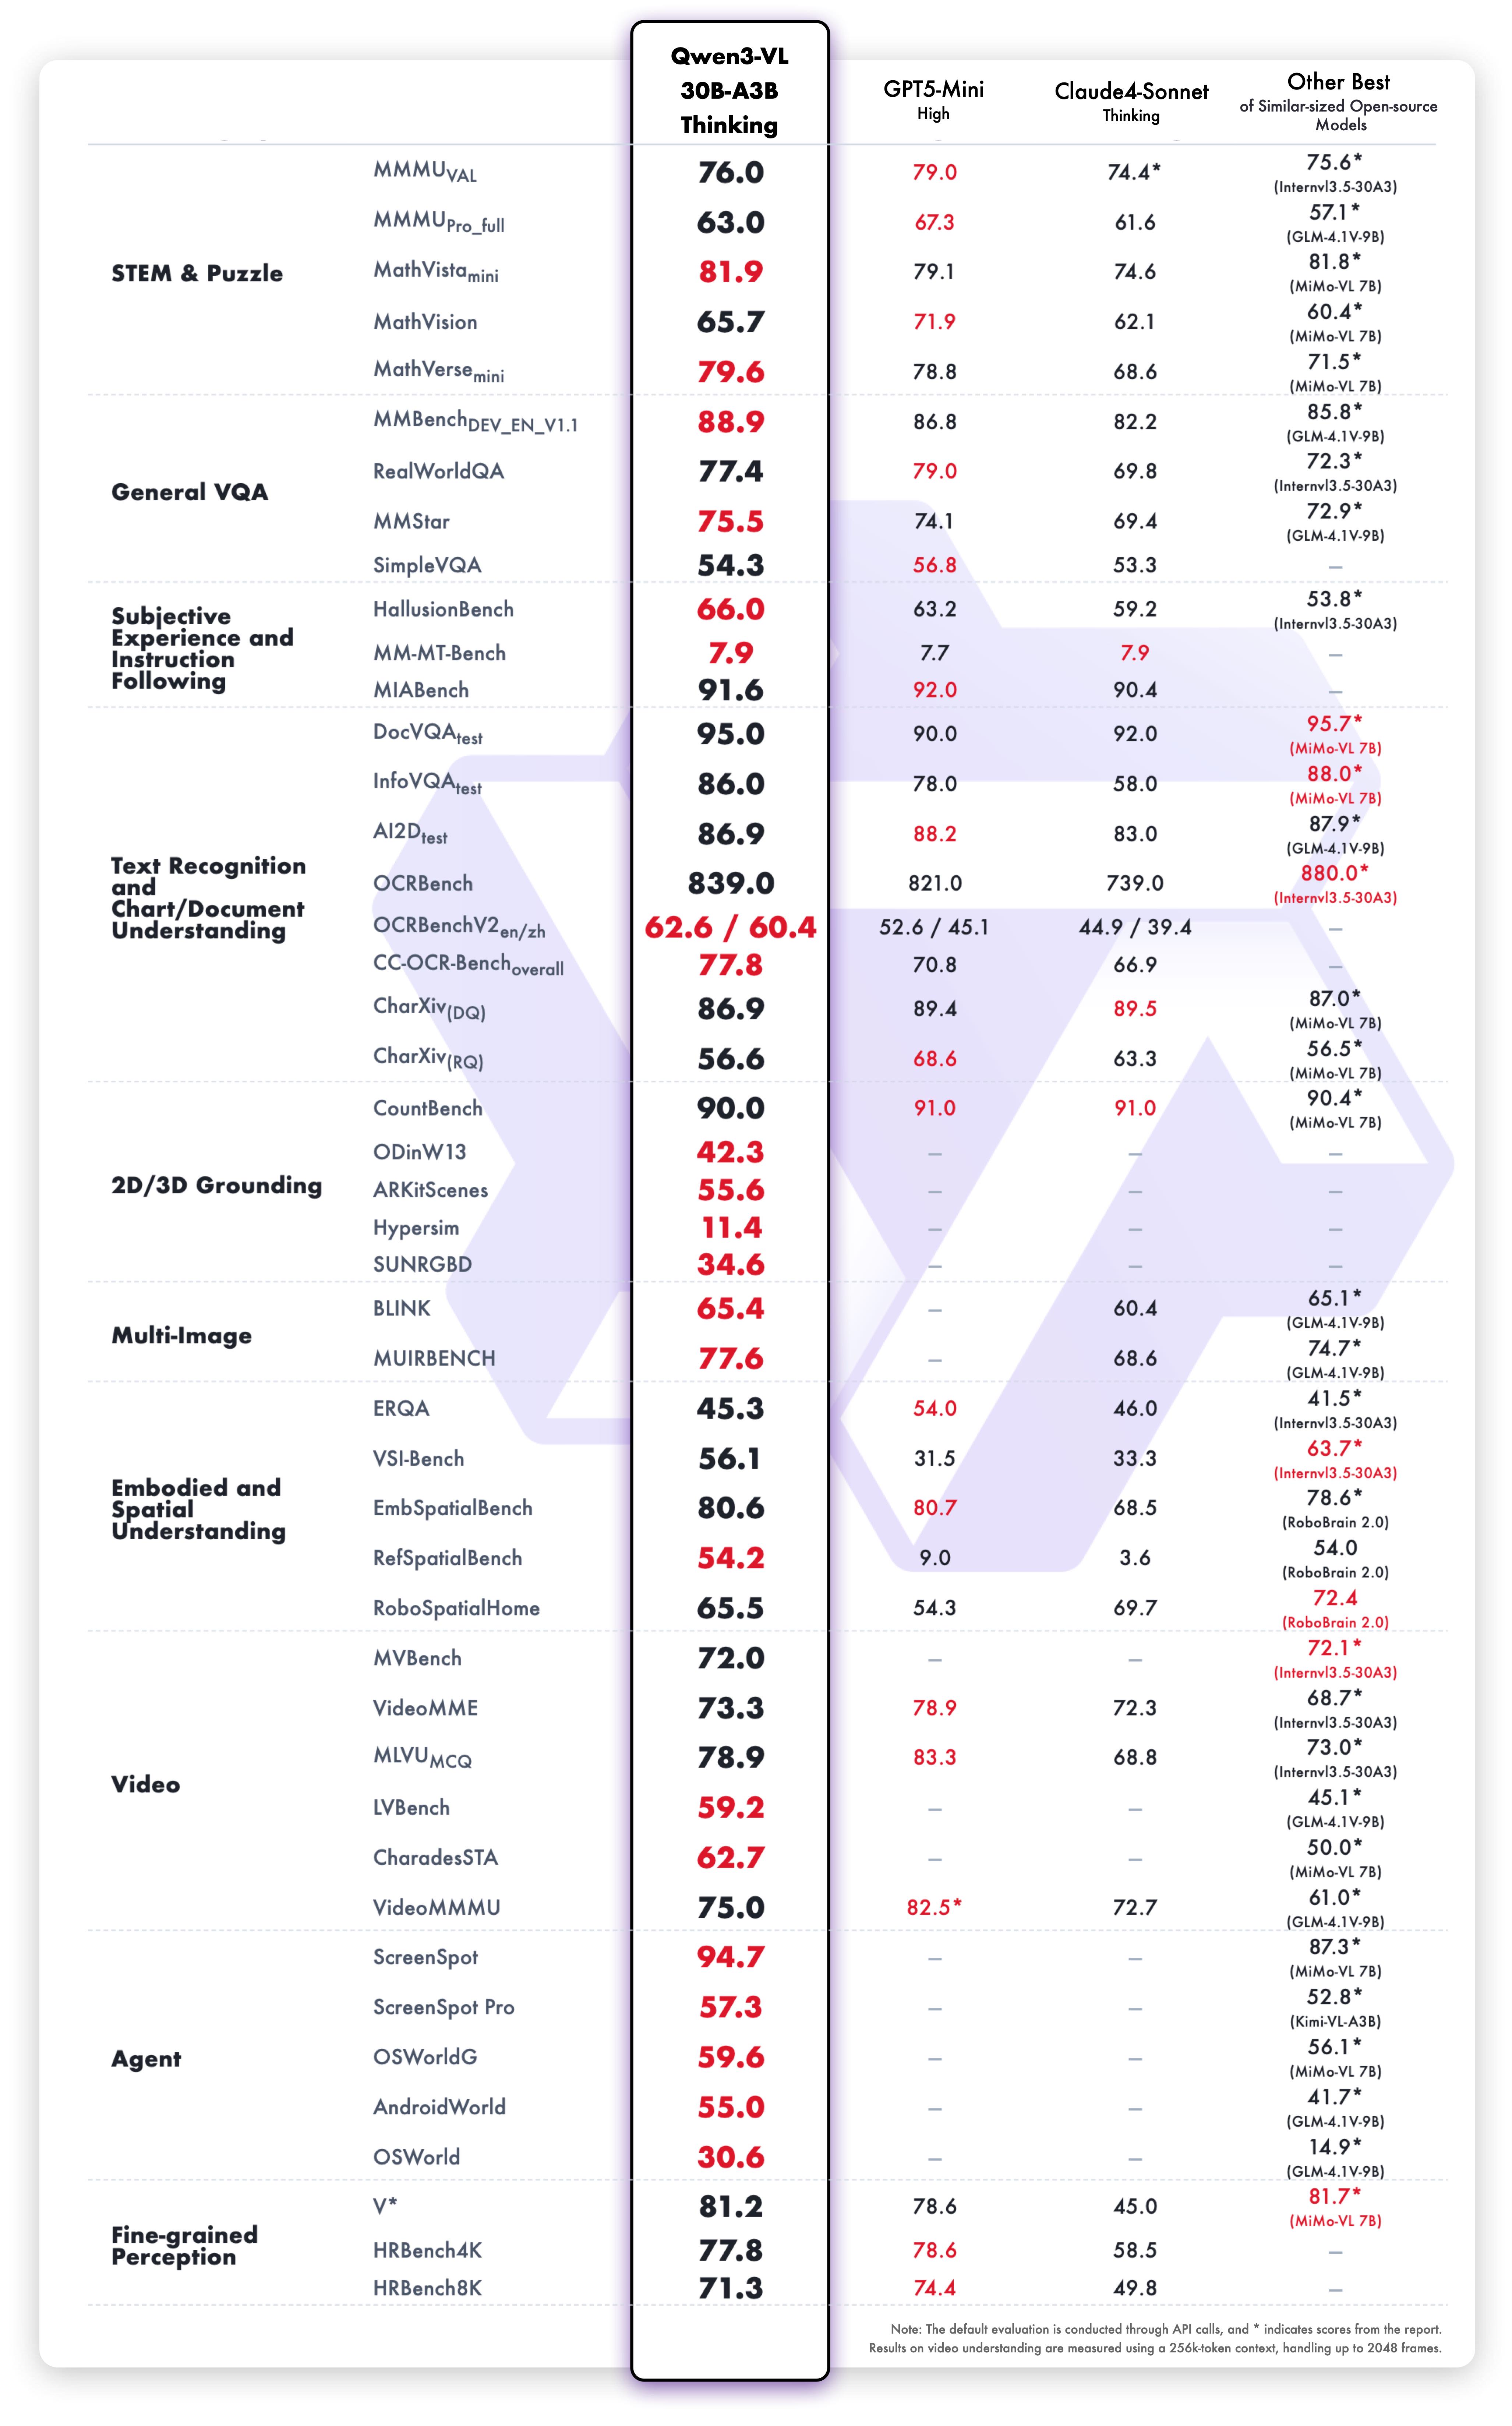
**Multimodal performance**
|
||||
|
||||
|
||||
|
||||
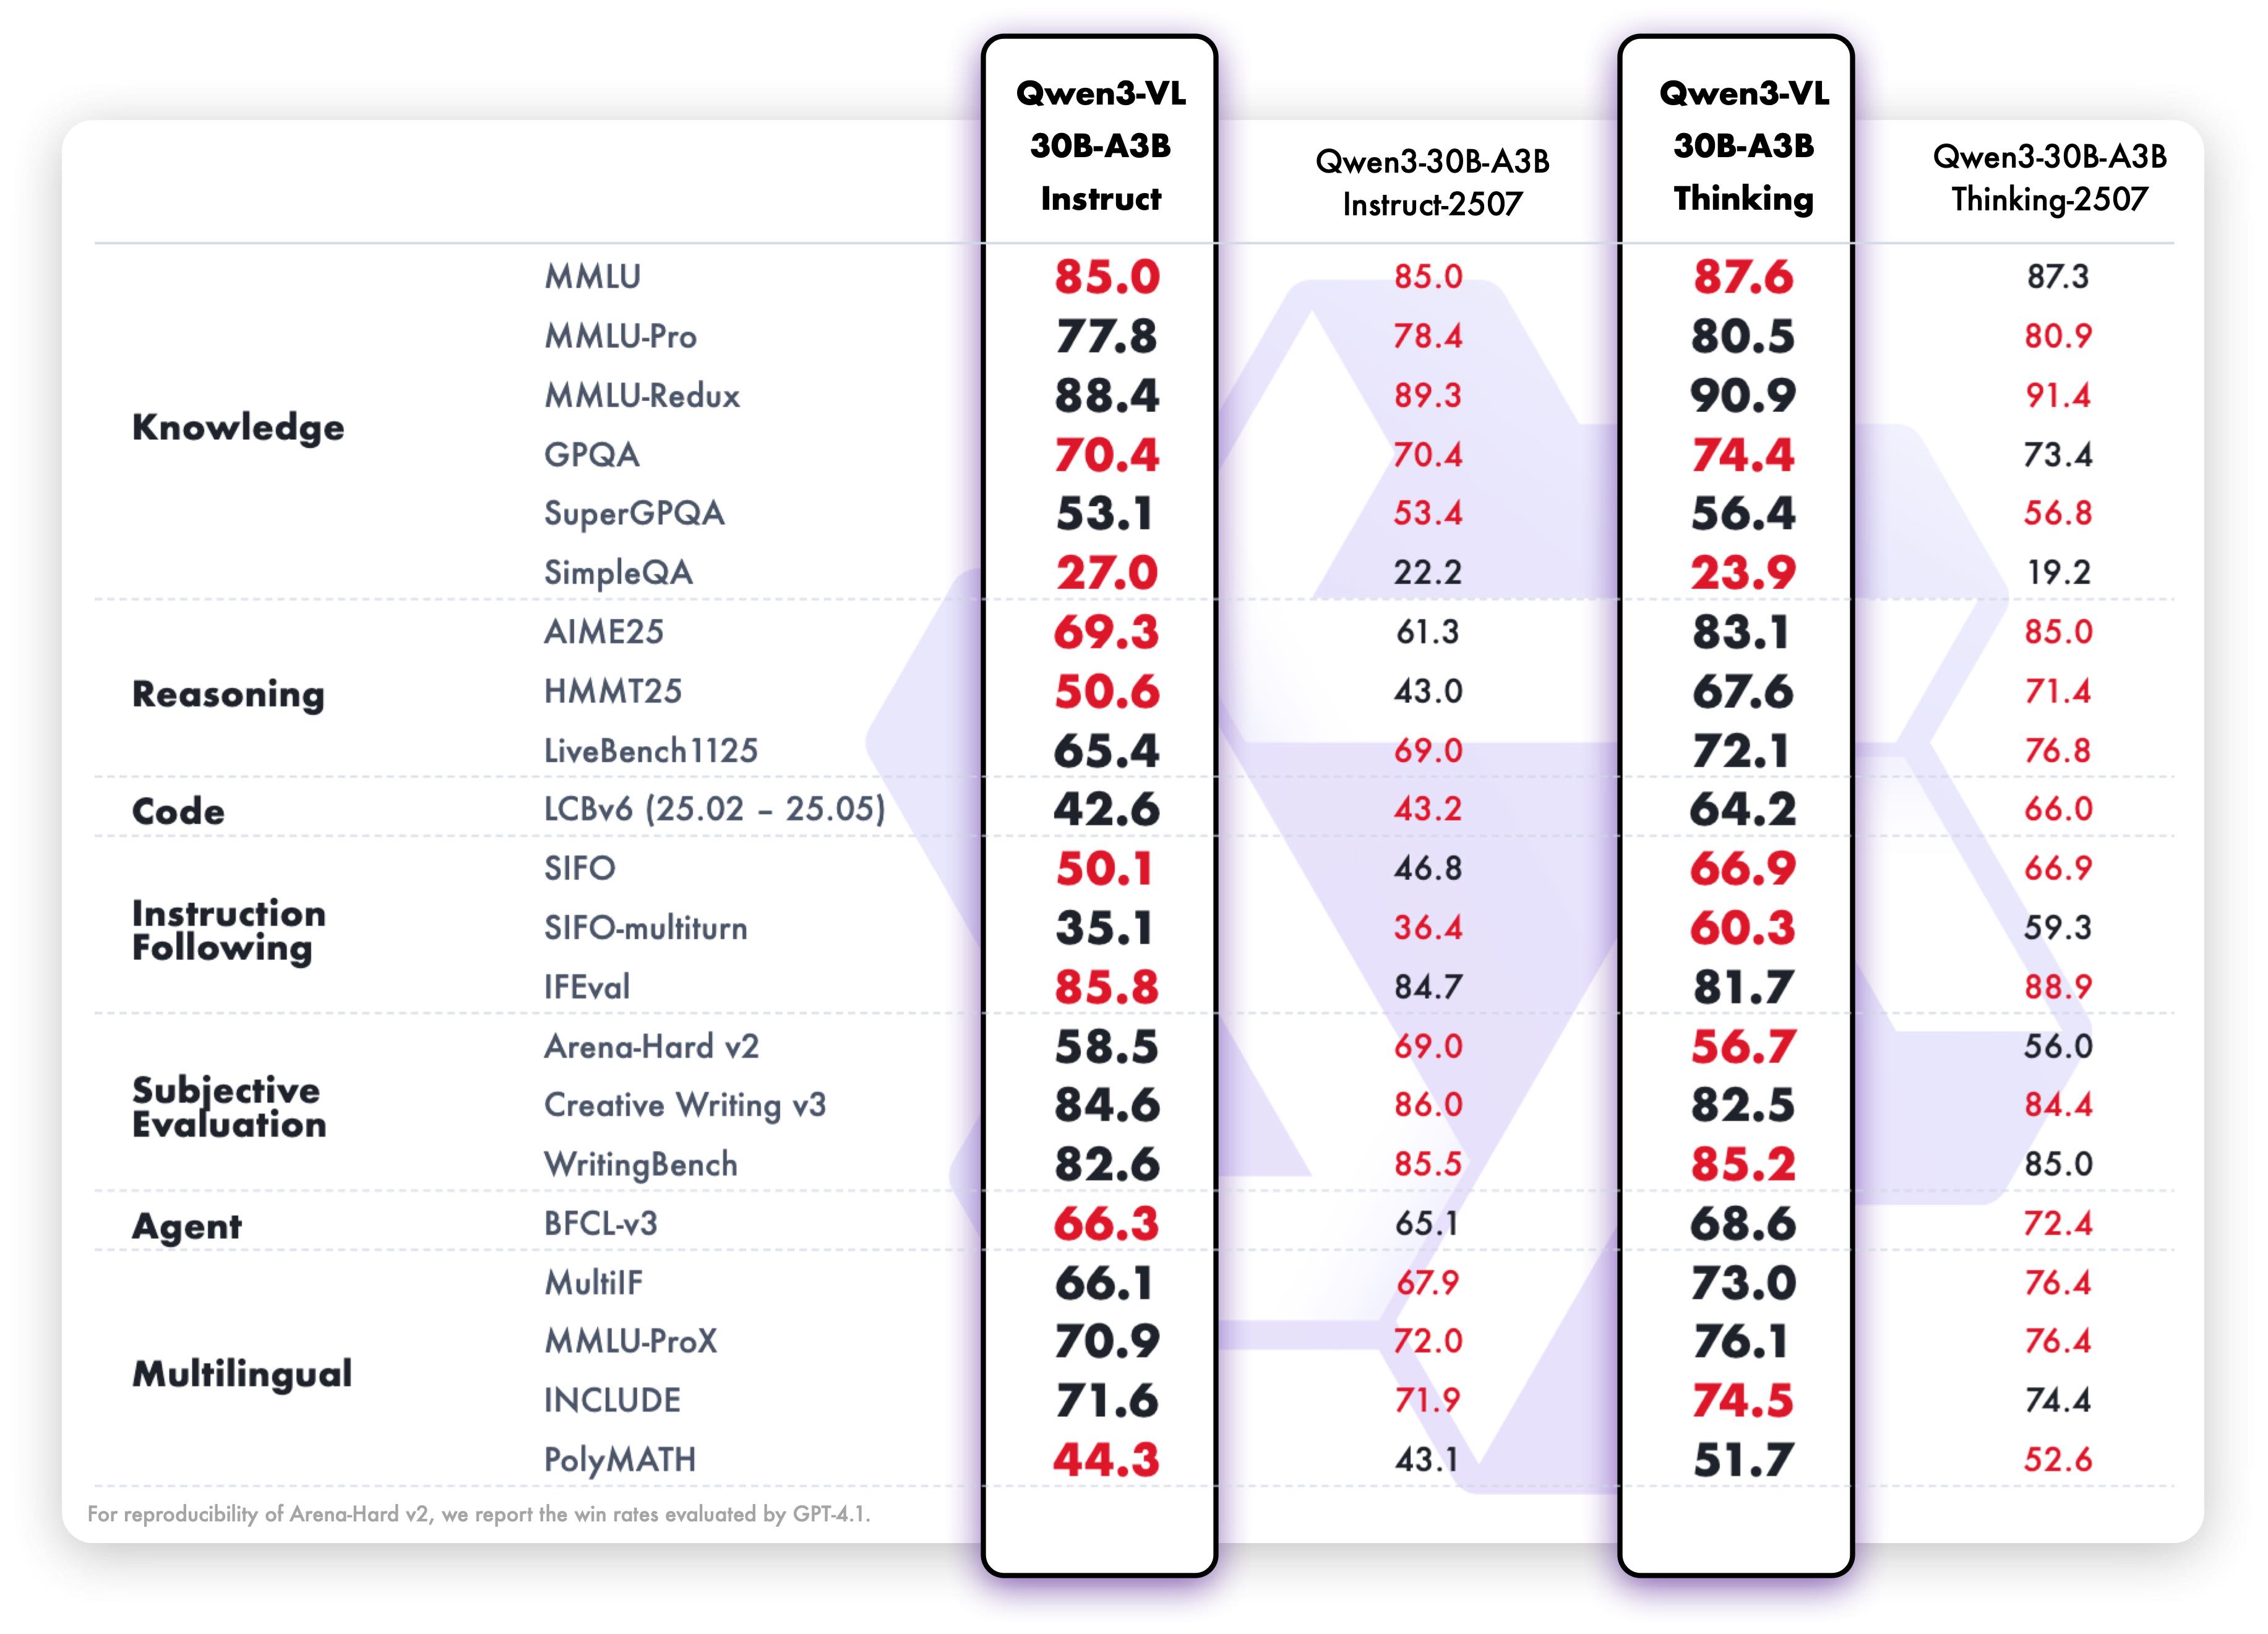
**Pure text performance**
|
||||
|
||||
|
||||
## Quickstart
|
||||
|
||||
Below, we provide simple examples to show how to use Qwen3-VL with 🤖 ModelScope and 🤗 Transformers.
|
||||
|
||||
The code of Qwen3-VL has been in the latest Hugging face transformers and we advise you to build from source with command:
|
||||
```
|
||||
pip install git+https://github.com/huggingface/transformers
|
||||
# pip install transformers==4.57.0 # currently, V4.57.0 is not released
|
||||
```
|
||||
|
||||
### Using 🤗 Transformers to Chat
|
||||
|
||||
Here we show a code snippet to show you how to use the chat model with `transformers`:
|
||||
|
||||
```python
|
||||
from transformers import Qwen3VLMoeForConditionalGeneration, AutoProcessor
|
||||
|
||||
# default: Load the model on the available device(s)
|
||||
model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
|
||||
"Qwen/Qwen3-VL-30B-A3B-Thinking", dtype="auto", device_map="auto"
|
||||
)
|
||||
|
||||
# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
|
||||
# model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
|
||||
# "Qwen/Qwen3-VL-30B-A3B-Thinking",
|
||||
# dtype=torch.bfloat16,
|
||||
# attn_implementation="flash_attention_2",
|
||||
# device_map="auto",
|
||||
# )
|
||||
|
||||
processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-30B-A3B-Thinking")
|
||||
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "image",
|
||||
"image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
|
||||
},
|
||||
{"type": "text", "text": "Describe this image."},
|
||||
],
|
||||
}
|
||||
]
|
||||
|
||||
# Preparation for inference
|
||||
inputs = processor.apply_chat_template(
|
||||
messages,
|
||||
tokenize=True,
|
||||
add_generation_prompt=True,
|
||||
return_dict=True,
|
||||
return_tensors="pt"
|
||||
)
|
||||
|
||||
# Inference: Generation of the output
|
||||
generated_ids = model.generate(**inputs, max_new_tokens=128)
|
||||
generated_ids_trimmed = [
|
||||
out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
|
||||
]
|
||||
output_text = processor.batch_decode(
|
||||
generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
|
||||
)
|
||||
print(output_text)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite.
|
||||
|
||||
```
|
||||
@misc{qwen3technicalreport,
|
||||
title={Qwen3 Technical Report},
|
||||
author={Qwen Team},
|
||||
year={2025},
|
||||
eprint={2505.09388},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2505.09388},
|
||||
}
|
||||
|
||||
@article{Qwen2.5-VL,
|
||||
title={Qwen2.5-VL Technical Report},
|
||||
author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
|
||||
journal={arXiv preprint arXiv:2502.13923},
|
||||
year={2025}
|
||||
}
|
||||
|
||||
@article{Qwen2VL,
|
||||
title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
|
||||
author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
|
||||
journal={arXiv preprint arXiv:2409.12191},
|
||||
year={2024}
|
||||
}
|
||||
|
||||
@article{Qwen-VL,
|
||||
title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
|
||||
author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
|
||||
journal={arXiv preprint arXiv:2308.12966},
|
||||
year={2023}
|
||||
}
|
||||
```
|
||||
3
chat_template.json
Normal file
3
chat_template.json
Normal file
File diff suppressed because one or more lines are too long
81
config.json
Normal file
81
config.json
Normal file
@@ -0,0 +1,81 @@
|
||||
{
|
||||
"name_or_path": "tclf90/Qwen3-VL-30B-A3B-Thinking-AWQ",
|
||||
"architectures": [
|
||||
"Qwen3VLMoeForConditionalGeneration"
|
||||
],
|
||||
"image_token_id": 151655,
|
||||
"model_type": "qwen3_vl_moe",
|
||||
"text_config": {
|
||||
"attention_bias": false,
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 151643,
|
||||
"decoder_sparse_step": 1,
|
||||
"dtype": "bfloat16",
|
||||
"eos_token_id": 151645,
|
||||
"head_dim": 128,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 2048,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 6144,
|
||||
"max_position_embeddings": 262144,
|
||||
"mlp_only_layers": [],
|
||||
"model_type": "qwen3_vl_moe_text",
|
||||
"moe_intermediate_size": 768,
|
||||
"norm_topk_prob": true,
|
||||
"num_attention_heads": 32,
|
||||
"num_experts": 128,
|
||||
"num_experts_per_tok": 8,
|
||||
"num_hidden_layers": 48,
|
||||
"num_key_value_heads": 4,
|
||||
"rms_norm_eps": 1e-06,
|
||||
"rope_scaling": {
|
||||
"mrope_interleaved": true,
|
||||
"mrope_section": [
|
||||
24,
|
||||
20,
|
||||
20
|
||||
],
|
||||
"rope_type": "default"
|
||||
},
|
||||
"rope_theta": 5000000,
|
||||
"use_cache": true,
|
||||
"vocab_size": 151936
|
||||
},
|
||||
"tie_word_embeddings": false,
|
||||
"transformers_version": "4.57.0.dev0",
|
||||
"video_token_id": 151656,
|
||||
"vision_config": {
|
||||
"deepstack_visual_indexes": [
|
||||
8,
|
||||
16,
|
||||
24
|
||||
],
|
||||
"depth": 27,
|
||||
"hidden_act": "gelu_pytorch_tanh",
|
||||
"hidden_size": 1152,
|
||||
"in_channels": 3,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 4304,
|
||||
"model_type": "qwen3_vl_moe",
|
||||
"num_heads": 16,
|
||||
"num_position_embeddings": 2304,
|
||||
"out_hidden_size": 2048,
|
||||
"patch_size": 16,
|
||||
"spatial_merge_size": 2,
|
||||
"temporal_patch_size": 2
|
||||
},
|
||||
"vision_end_token_id": 151653,
|
||||
"vision_start_token_id": 151652,
|
||||
"torch_dtype": "float16",
|
||||
"quantization_config": {
|
||||
"quant_method": "awq",
|
||||
"bits": 4,
|
||||
"group_size": 128,
|
||||
"version": "gemm",
|
||||
"zero_point": true,
|
||||
"modules_to_not_convert": [
|
||||
"visual",
|
||||
"mlp.gate"
|
||||
]
|
||||
}
|
||||
}
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework":"Pytorch","task":"image-text-to-text"}
|
||||
14
generation_config.json
Normal file
14
generation_config.json
Normal file
@@ -0,0 +1,14 @@
|
||||
{
|
||||
"bos_token_id": 151643,
|
||||
"pad_token_id": 151643,
|
||||
"do_sample": true,
|
||||
"eos_token_id": [
|
||||
151645,
|
||||
151643
|
||||
],
|
||||
"top_k": 20,
|
||||
"top_p": 0.95,
|
||||
"repetition_penalty": 1.0,
|
||||
"temperature": 0.8,
|
||||
"transformers_version": "4.56.0"
|
||||
}
|
||||
3
merges.txt
Normal file
3
merges.txt
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:599bab54075088774b1733fde865d5bd747cbcc7a547c5bc12610e874e26f5e3
|
||||
size 1671839
|
||||
3
model-00001-of-00006.safetensors
Normal file
3
model-00001-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:d0413942111f39095c2865e642f0a0019cc6b6c65882f1bc48d5f0adab7a4048
|
||||
size 3000764080
|
||||
3
model-00002-of-00006.safetensors
Normal file
3
model-00002-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:56ff88d9af9bd567989d71cdcea382edcbe88368045f78b4ac0c56ec78f252d0
|
||||
size 3001417160
|
||||
3
model-00003-of-00006.safetensors
Normal file
3
model-00003-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:5f500fa9a6063a444ef3497bb0705b72fe66a0b34edeb39d60945049721bdd04
|
||||
size 3001132880
|
||||
3
model-00004-of-00006.safetensors
Normal file
3
model-00004-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:3874b047fd66dd6e8a7679c0342247a57c90fc9256f78558cb30855aa20a8b37
|
||||
size 3001371840
|
||||
3
model-00005-of-00006.safetensors
Normal file
3
model-00005-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:93c7fa5fefb8605ff485f9770e3ade1d9f2c9f8874575b41a39aa3692e182e21
|
||||
size 3001424880
|
||||
3
model-00006-of-00006.safetensors
Normal file
3
model-00006-of-00006.safetensors
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:be0db8fd7ad4290d039586678b765eb2d556a6f77fc2207df77407683022b699
|
||||
size 2881490336
|
||||
3
model.safetensors.index.json
Normal file
3
model.safetensors.index.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:e4cfad31359882c30c24c342a2881b84d49796f8f5237afb71c0988ec0ecf370
|
||||
size 5948346
|
||||
21
preprocessor_config.json
Normal file
21
preprocessor_config.json
Normal file
@@ -0,0 +1,21 @@
|
||||
{
|
||||
"size": {
|
||||
"longest_edge": 16777216,
|
||||
"shortest_edge": 65536
|
||||
},
|
||||
"patch_size": 16,
|
||||
"temporal_patch_size": 2,
|
||||
"merge_size": 2,
|
||||
"image_mean": [
|
||||
0.5,
|
||||
0.5,
|
||||
0.5
|
||||
],
|
||||
"image_std": [
|
||||
0.5,
|
||||
0.5,
|
||||
0.5
|
||||
],
|
||||
"processor_class": "Qwen3VLProcessor",
|
||||
"image_processor_type": "Qwen2VLImageProcessorFast"
|
||||
}
|
||||
3
tokenizer.json
Normal file
3
tokenizer.json
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a5d85b6dcc535e6b93115a9ef287e6132fdbf30270da6218194ba742261173c7
|
||||
size 7032403
|
||||
239
tokenizer_config.json
Normal file
239
tokenizer_config.json
Normal file
File diff suppressed because one or more lines are too long
21
video_preprocessor_config.json
Normal file
21
video_preprocessor_config.json
Normal file
@@ -0,0 +1,21 @@
|
||||
{
|
||||
"size": {
|
||||
"longest_edge": 25165824,
|
||||
"shortest_edge": 4096
|
||||
},
|
||||
"patch_size": 16,
|
||||
"temporal_patch_size": 2,
|
||||
"merge_size": 2,
|
||||
"image_mean": [
|
||||
0.5,
|
||||
0.5,
|
||||
0.5
|
||||
],
|
||||
"image_std": [
|
||||
0.5,
|
||||
0.5,
|
||||
0.5
|
||||
],
|
||||
"processor_class": "Qwen3VLProcessor",
|
||||
"video_processor_type": "Qwen3VLVideoProcessor"
|
||||
}
|
||||
BIN
vocab.json
(Stored with Git LFS)
Normal file
BIN
vocab.json
(Stored with Git LFS)
Normal file
Binary file not shown.
Reference in New Issue
Block a user