---
language:
- en
- fr
- it
- de
- es
- pl
license: apache-2.0
pipeline_tag: text-generation
library_name: transformers
tags:
- transformers
- reasoning
- synthetic-data
datasets:
- PleIAs/SYNTH
---
# 🥖 Baguettotron-600M
Paper (NeurIPS 2026) ·
SYNTH dataset ·
Baguettotron-350M ·
Baguettotron-MoE
**Baguettotron-600M** is a 0.6B-parameter reasoning model trained from scratch on 158B tokens of [SYNTH](https://huggingface.co/datasets/PleIAs/SYNTH), a fully synthetic corpus amplified from 58,698 Wikipedia articles. It is the main reference model of our NeurIPS 2026 paper, [*It's All Training: A Fully Synthetic Single-Stage Recipe for LLMs*](https://arxiv.org/abs/2609.37891).
- **Single training stage:** no separate mid-training, SFT or RLHF. The model follows instructions, reasons in `` traces and recalls facts because SYNTH trains those capabilities directly.
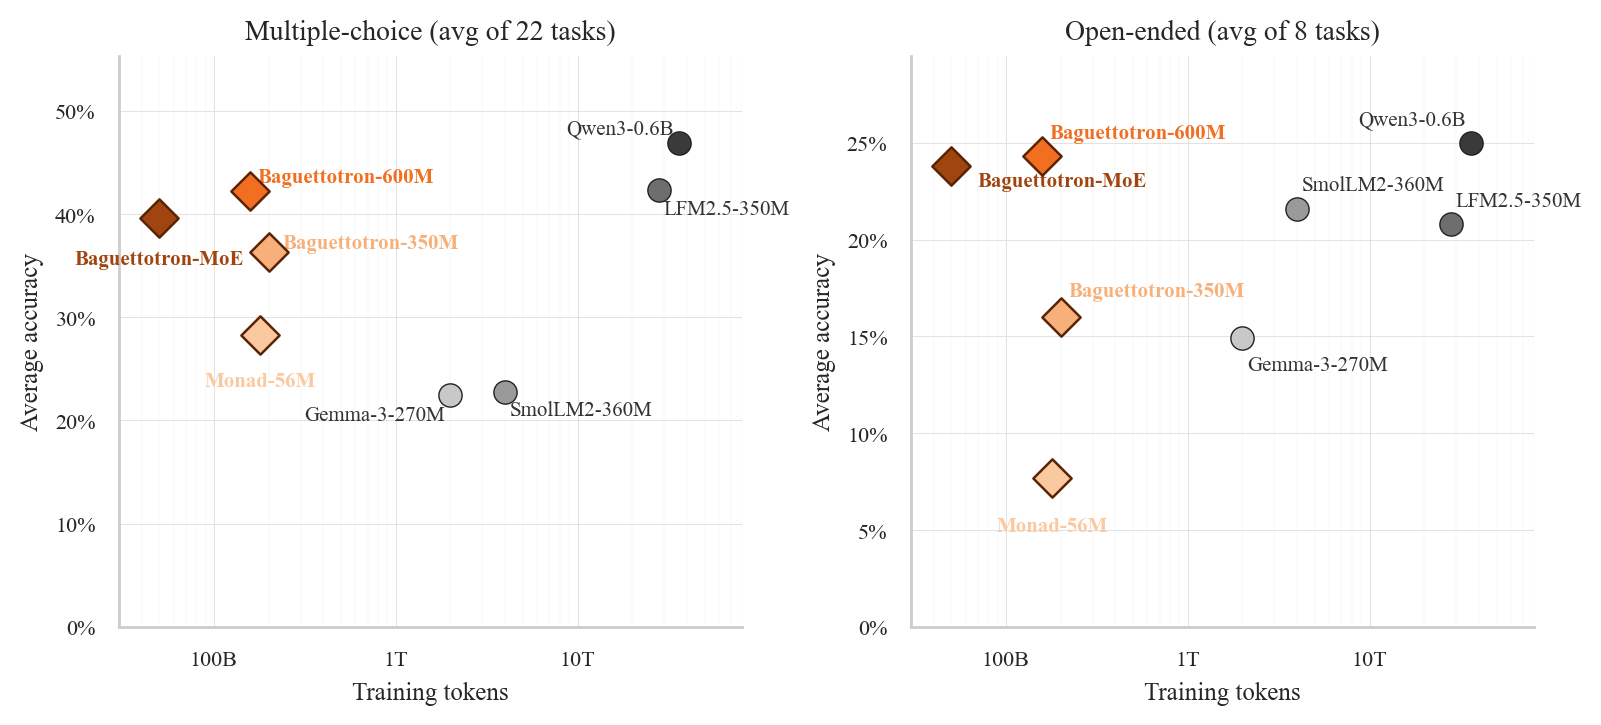
- **Token-efficient:** within 4.7 points of Qwen3-0.6B on 22 multiple-choice tasks and 0.7 points on 8 open-ended tasks, trained on ~230× fewer tokens.
- **Factually precise:** highest FActScore in its parameter tier (41.7% macro vs. 31.6% for Qwen3-0.6B).
## Model design
Baguettotron-600M is a standard dense decoder (Llama/Qwen-style) and loads natively in `transformers` and vLLM (`LlamaForCausalLM`, no remote code).

| | |
|---|---|
| Parameters | 608M (incl. 67M tied embeddings) |
| Layers | 48 |
| Hidden size | 1024 |
| Attention | GQA, 16 query / 4 KV heads, head dim 64 |
| MLP | SwiGLU, intermediate size 2816 |
| Position encoding | RoPE, θ = 10,000 |
| Norm | RMSNorm (pre-norm), ε = 1e-6 |
| Embeddings | Tied input/output |
| Vocabulary | 65,536 (Pleias tokenizer) |
| Context length | 2,048 tokens |
## Training
- **Data:** SYNTH, 158.3B tokens (~2 passes over the ~75B-token corpus)
- **Steps:** 151,000 at global batch 512 × 2,048 tokens (~1.05M tokens/step)
- **Optimizer:** AdamW, peak LR 1.5e-3, 10k-step warmup, linear decay over the final 16.6% of steps to 0.2% of peak; weight decay 0.01, grad clip 1.0
- **Hardware:** 16× H100 (4 nodes × 4 GPUs) on MareNostrum 5 (BSC), `torchtitan` with FSDP, ~52.6 h, ~30% MFU
## Evaluation
All scores are from the paper. Each model is prompted in its native format; Baguettotron models get no system prompt and have `\n` seeded after the assistant turn.
| Model | Training tokens | MCQ (22 tasks) | Open-ended (8 tasks) | FActScore (macro) |
|---|---|---|---|---|
| **Baguettotron-600M** | 158B | 42.2 | 24.3 | **41.7** |
| Baguettotron-MoE (13B / 1B active) | 50B | 39.6 | 23.8 | 46.3 |
| Baguettotron-350M | 200B | 36.3 | 16.0 | 32.4 |
| Qwen3-0.6B | ~36T | **46.9** | **25.0** | 31.6 |
| LFM2.5-350M | 28T | 42.3 | 20.8 | 22.0 |
| SmolLM2-360M-Instruct | 4T | 22.8 | 21.6 | 26.6 |
| Gemma-3-270M-IT | 2T | 22.5 | 14.9 | 19.4 |
- **Ties or beats Qwen3-0.6B** on TruthfulQA (42.6 vs. 32.7), ESGenius (62.2 vs. 55.1) and FormationEval (62.8 vs. 58.0)
- **Weak:** benchmarks that reward broad web knowledge (ARC-Challenge, GeoBench), since SYNTH covers only its seed articles
- **Data, not architecture:** the same architecture, tokenizer and step count trained on FineWiki or FinePDFs-Edu reaches only 26.1 / 25.1 on MCQ, even after SmolTalk post-training
- **Reasoning traces matter:** retraining without traces costs 9.1 points on TruthfulQA and 10.0 on NuclearQA
## Prompt format
The model was trained on ChatML with a `` block and no system prompt. The bundled chat template opens the assistant turn with `\n`:
```xml
<|im_start|>user
What do you know about the Treaty of Westphalia?<|im_end|>
<|im_start|>assistant
```
The model writes its reasoning, closes it with ``, answers, and ends the turn with `<|im_end|>`.
**RAG.** Pass sources inside the user turn. The answer then cites them with `[[quote]]`:
```xml
<|im_start|>user
{question}
[…]
[…]<|im_end|>
<|im_start|>assistant
```
**Reasoning notation.** Traces use SYNTH's compact stenographic style (`→` derivation, `↺` backtracking, `∴` conclusion, …). The confidence markers `●` (high), `◐` (partial) and `○` (low) are informative: on traces dominated by uncertain markers, FActScore drops from 0.44 to 0.40, and the model commits to ~15–20% fewer facts. See the [Baguettotron-350M card](https://huggingface.co/PleIAs/Baguettotron) for the full notation.
## Inference
### vLLM
```bash
vllm serve PleIAs/baguettotron-600m --reasoning-parser deepseek_r1
```
`--reasoning-parser deepseek_r1` moves the `` trace into a separate `reasoning` field. Tested with vLLM 0.24.0.
```python
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
resp = client.chat.completions.create(
model="PleIAs/baguettotron-600m",
messages=[{"role": "user", "content": "What do you know about the Treaty of Westphalia?"}],
temperature=0.1,
top_p=0.95,
presence_penalty=0.1,
max_tokens=1536,
)
print(resp.choices[0].message.reasoning) # trace
print(resp.choices[0].message.content) # answer
```
Recommended sampling: `temperature=0.1`, `top_p=0.95`, `presence_penalty=0.1`. Prompt and generation share the 2,048-token context, so keep `max_tokens` below 2,048 minus the prompt length.
### Transformers
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
repo = "PleIAs/baguettotron-600m"
tokenizer = AutoTokenizer.from_pretrained(repo)
model = AutoModelForCausalLM.from_pretrained(repo, dtype="bfloat16", device_map="auto")
messages = [{"role": "user", "content": "What do you know about the Treaty of Westphalia?"}]
inputs = tokenizer.apply_chat_template(
messages, add_generation_prompt=True, return_tensors="pt"
).to(model.device)
out = model.generate(inputs, max_new_tokens=1536, do_sample=True, temperature=0.1, top_p=0.95)
print(tokenizer.decode(out[0, inputs.shape[1]:]))
```
## Limitations
- **2,048-token context** shared by prompt, reasoning and answer
- **Knowledge is bounded by the seed corpus** (~58.7k Wikipedia articles): recall is precise on seed topics and weaker outside them
- **Reasoning traces are English-only**, even when the prompt and answer are in another language
- **No preference tuning or safety alignment**; not intended for high-stakes use without further evaluation
## Citation
```bibtex
@inproceedings{langlais2026itsalltraining,
title = {It's All Training: A Fully Synthetic Single-Stage Recipe for {LLMs}},
author = {Langlais, Pierre-Carl and Delobelle, Pieter and Detrois, Yannick and Chizhov, Pavel and Rosas-Hinostroza, Carlos and Si Smail, Neil and Burtin, Benjamin and Shcharbakova, Hanna and Yamshchikov, Ivan and Stasenko, Anastasia},
booktitle = {Advances in Neural Information Processing Systems},
year = {2026},
eprint = {2609.37891},
archivePrefix = {arXiv},
primaryClass = {cs.CL},
url = {https://arxiv.org/abs/2609.37891}
}
```
## Acknowledgements
Trained on MareNostrum 5 (BSC) through the EuroHPC Extreme Scale Access call (EHPC-EXT-2025E01-092, *JULIP: Powerful LLMs made in Europe*). Parts of this research received funding from SPRIN-D, the German Federal Agency for Breakthrough Innovation.
