初始化项目,由ModelHub XC社区提供模型
Model: Mungert/Qwen3-4B-Instruct-2507-GGUF
Source: Original Platform
This commit is contained in:
 ModelHub XC
74
.gitattributes
vendored
Normal file
74
.gitattributes
vendored
Normal file
@@ -0,0 +1,74 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zstandard filter=lfs diff=lfs merge=lfs -text
|
||||
*.tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
*.db* filter=lfs diff=lfs merge=lfs -text
|
||||
*.ark* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*data* filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.meta filter=lfs diff=lfs merge=lfs -text
|
||||
**/*ckpt*.index filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
|
||||
*.ggml filter=lfs diff=lfs merge=lfs -text
|
||||
*.llamafile* filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
|
||||
Qwen3-4B-Instruct-2507-q4_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q4_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq2_xxs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-imatrix.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq3_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q4_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq2_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q5_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq3_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq2_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-f16_q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q3_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq2_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q4_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q5_1.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q3_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q6_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q5_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq4_nl.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q2_k_m.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq3_xxs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-iq4_xs.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-bf16.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-q2_k_s.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
Qwen3-4B-Instruct-2507-bf16_q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
||||
3
Qwen3-4B-Instruct-2507-bf16.gguf
Normal file
3
Qwen3-4B-Instruct-2507-bf16.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:7765a9889b07262f4098a897422cc446dba7b47aa2a2b9ef8fd7db0487add01e
|
||||
size 8051284960
|
||||
3
Qwen3-4B-Instruct-2507-bf16_q8_0.gguf
Normal file
3
Qwen3-4B-Instruct-2507-bf16_q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:358a71ca0dc6f9477ba8011dcb4b365bf8f73e668d03921068c967a39ab81f0d
|
||||
size 5927918560
|
||||
3
Qwen3-4B-Instruct-2507-f16_q8_0.gguf
Normal file
3
Qwen3-4B-Instruct-2507-f16_q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:be380e2c128bc86cc66b6c4b09e172653a0cb457f632d9fd65b4c799b3cbb5ce
|
||||
size 5927918560
|
||||
3
Qwen3-4B-Instruct-2507-imatrix.gguf
Normal file
3
Qwen3-4B-Instruct-2507-imatrix.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:82f4b42f83986c180f866551e24d227bbc5a3aba7263c3282a44580d818b9ce2
|
||||
size 3872640
|
||||
3
Qwen3-4B-Instruct-2507-iq2_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq2_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:47a449d6bbf0de4e3b635993e184e267855e66aaf709259326e7f4b1431529ef
|
||||
size 1555746080
|
||||
3
Qwen3-4B-Instruct-2507-iq2_s.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq2_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9b93df7e1c2faa11d110308bd0bccdfbeaed214ca2dee0a2c57540e7d4d0ff9e
|
||||
size 1491520800
|
||||
3
Qwen3-4B-Instruct-2507-iq2_xs.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq2_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:6e8add03df430de2399cbc1a51c1417d1454bd3a17064d9251bab9c0cf05192e
|
||||
size 1446178080
|
||||
3
Qwen3-4B-Instruct-2507-iq2_xxs.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq2_xxs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:9437b46b4b1e2a781021ad7fb633c2f62e1ddfd0ce6c9791aa1adf496f646ad8
|
||||
size 1341934880
|
||||
3
Qwen3-4B-Instruct-2507-iq3_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq3_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:2ab7633dc3f5d6566aa6b1f9ec6bc3ac35e4b108198a644241d5df8c674bb99c
|
||||
size 2003036960
|
||||
3
Qwen3-4B-Instruct-2507-iq3_xs.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq3_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:8028ac2025d250188a439cbf07a2b5c0093999dd6e5d90604949bb3467047c0b
|
||||
size 1824205600
|
||||
3
Qwen3-4B-Instruct-2507-iq3_xxs.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq3_xxs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:24b5e3f8e9703b9bb736f40a2f148f4d5c56c1ced6b0d9135f1627be10af2620
|
||||
size 1773701920
|
||||
3
Qwen3-4B-Instruct-2507-iq4_nl.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq4_nl.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:b4b78c64b95c29bb5db5cb03ef6bfc1e3be640c6991617be002b672f09c0b354
|
||||
size 2281065760
|
||||
3
Qwen3-4B-Instruct-2507-iq4_xs.gguf
Normal file
3
Qwen3-4B-Instruct-2507-iq4_xs.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:38fa515dab245c63d6696c1129b08fc2fcf569d45e214fbb998466da658e5bba
|
||||
size 2270751520
|
||||
3
Qwen3-4B-Instruct-2507-q2_k_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q2_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:049b2cc60bee80f61590dd7bf071d5313d471a51f679a9a99702d7e9968002f2
|
||||
size 1591545120
|
||||
3
Qwen3-4B-Instruct-2507-q2_k_s.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q2_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a3bdb4e206e4fb70ea81d6f5be2932df542a6c972780f1b72de20bf3678f9875
|
||||
size 1542925600
|
||||
3
Qwen3-4B-Instruct-2507-q3_k_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q3_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:7ddba66c25a284265db465bb514e77aa2f52e5f0291e5bc47879c9a31967fb16
|
||||
size 2059561760
|
||||
3
Qwen3-4B-Instruct-2507-q3_k_s.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q3_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:56cc6c9bfc94cf7180116420ee12d94985ca66fe748331c9e7a94e6b945cc892
|
||||
size 2007903520
|
||||
3
Qwen3-4B-Instruct-2507-q4_0.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q4_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:2a01565df6abf21024d1d3fc16dfda24ceaa4066a1d9da3c8e73ea9fd1148f28
|
||||
size 2463747360
|
||||
3
Qwen3-4B-Instruct-2507-q4_1.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q4_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:57ea91fe9f523d2df8944903c8155bd1b8d08d28992a153464107981772c4803
|
||||
size 2544971040
|
||||
3
Qwen3-4B-Instruct-2507-q4_k_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q4_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dd1fb099cb540a081e51cf1206c1e7788a840e2b52b43e682b57cb1795fa98f9
|
||||
size 2572721440
|
||||
3
Qwen3-4B-Instruct-2507-q4_k_s.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q4_k_s.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:f8521e6567c9e502a9d42310c72b5624662dfdcfdb94ecb4c4c7a3ef30a8b765
|
||||
size 2407557920
|
||||
3
Qwen3-4B-Instruct-2507-q5_0.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q5_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:fc363441126575d49e2a9c5c2d901e267ec893712f43fa16fe4e068159561d96
|
||||
size 2917911840
|
||||
3
Qwen3-4B-Instruct-2507-q5_1.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q5_1.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:139cf150bd73016bd928d71e3f4c3738abcf04cdae60a7a679210e8286924a8f
|
||||
size 3144994080
|
||||
3
Qwen3-4B-Instruct-2507-q5_k_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q5_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:531ad176d41a3287ebf8429c186a757ac3455808a9b55a21dba12cc6d9139db9
|
||||
size 2994855200
|
||||
3
Qwen3-4B-Instruct-2507-q6_k_m.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q6_k_m.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:53c5834cbec2579afadcb2c3758015e43ab7cf55161aa0abe1396b00b3466d4c
|
||||
size 3400461600
|
||||
3
Qwen3-4B-Instruct-2507-q8_0.gguf
Normal file
3
Qwen3-4B-Instruct-2507-q8_0.gguf
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:67e4f8d24b2f30b5d78c82443578cae3d04c97f89e0d842d50a7dd3d803713ad
|
||||
size 4280404960
|
||||
310
README.md
Normal file
310
README.md
Normal file
@@ -0,0 +1,310 @@
|
||||
---
|
||||
library_name: transformers
|
||||
license: apache-2.0
|
||||
license_link: https://huggingface.co/Qwen/Qwen3-4B-Instruct-2507/blob/main/LICENSE
|
||||
pipeline_tag: text-generation
|
||||
---
|
||||
|
||||
# <span style="color: #7FFF7F;">Qwen3-4B-Instruct-2507 GGUF Models</span>
|
||||
|
||||
|
||||
## <span style="color: #7F7FFF;">Model Generation Details</span>
|
||||
|
||||
This model was generated using [llama.cpp](https://github.com/ggerganov/llama.cpp) at commit [`cd6983d5`](https://github.com/ggerganov/llama.cpp/commit/cd6983d56d2cce94ecb86bb114ae8379a609073c).
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## <span style="color: #7FFF7F;">Quantization Beyond the IMatrix</span>
|
||||
|
||||
I've been experimenting with a new quantization approach that selectively elevates the precision of key layers beyond what the default IMatrix configuration provides.
|
||||
|
||||
In my testing, standard IMatrix quantization underperforms at lower bit depths, especially with Mixture of Experts (MoE) models. To address this, I'm using the `--tensor-type` option in `llama.cpp` to manually "bump" important layers to higher precision. You can see the implementation here:
|
||||
👉 [Layer bumping with llama.cpp](https://github.com/Mungert69/GGUFModelBuilder/blob/main/model-converter/tensor_list_builder.py)
|
||||
|
||||
While this does increase model file size, it significantly improves precision for a given quantization level.
|
||||
|
||||
### **I'd love your feedback—have you tried this? How does it perform for you?**
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
<a href="https://readyforquantum.com/huggingface_gguf_selection_guide.html" style="color: #7FFF7F;">
|
||||
Click here to get info on choosing the right GGUF model format
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
<!--Begin Original Model Card-->
|
||||
|
||||
|
||||
# Qwen3-4B-Instruct-2507
|
||||
<a href="https://chat.qwen.ai" target="_blank" style="margin: 2px;">
|
||||
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
||||
</a>
|
||||
|
||||
## Highlights
|
||||
|
||||
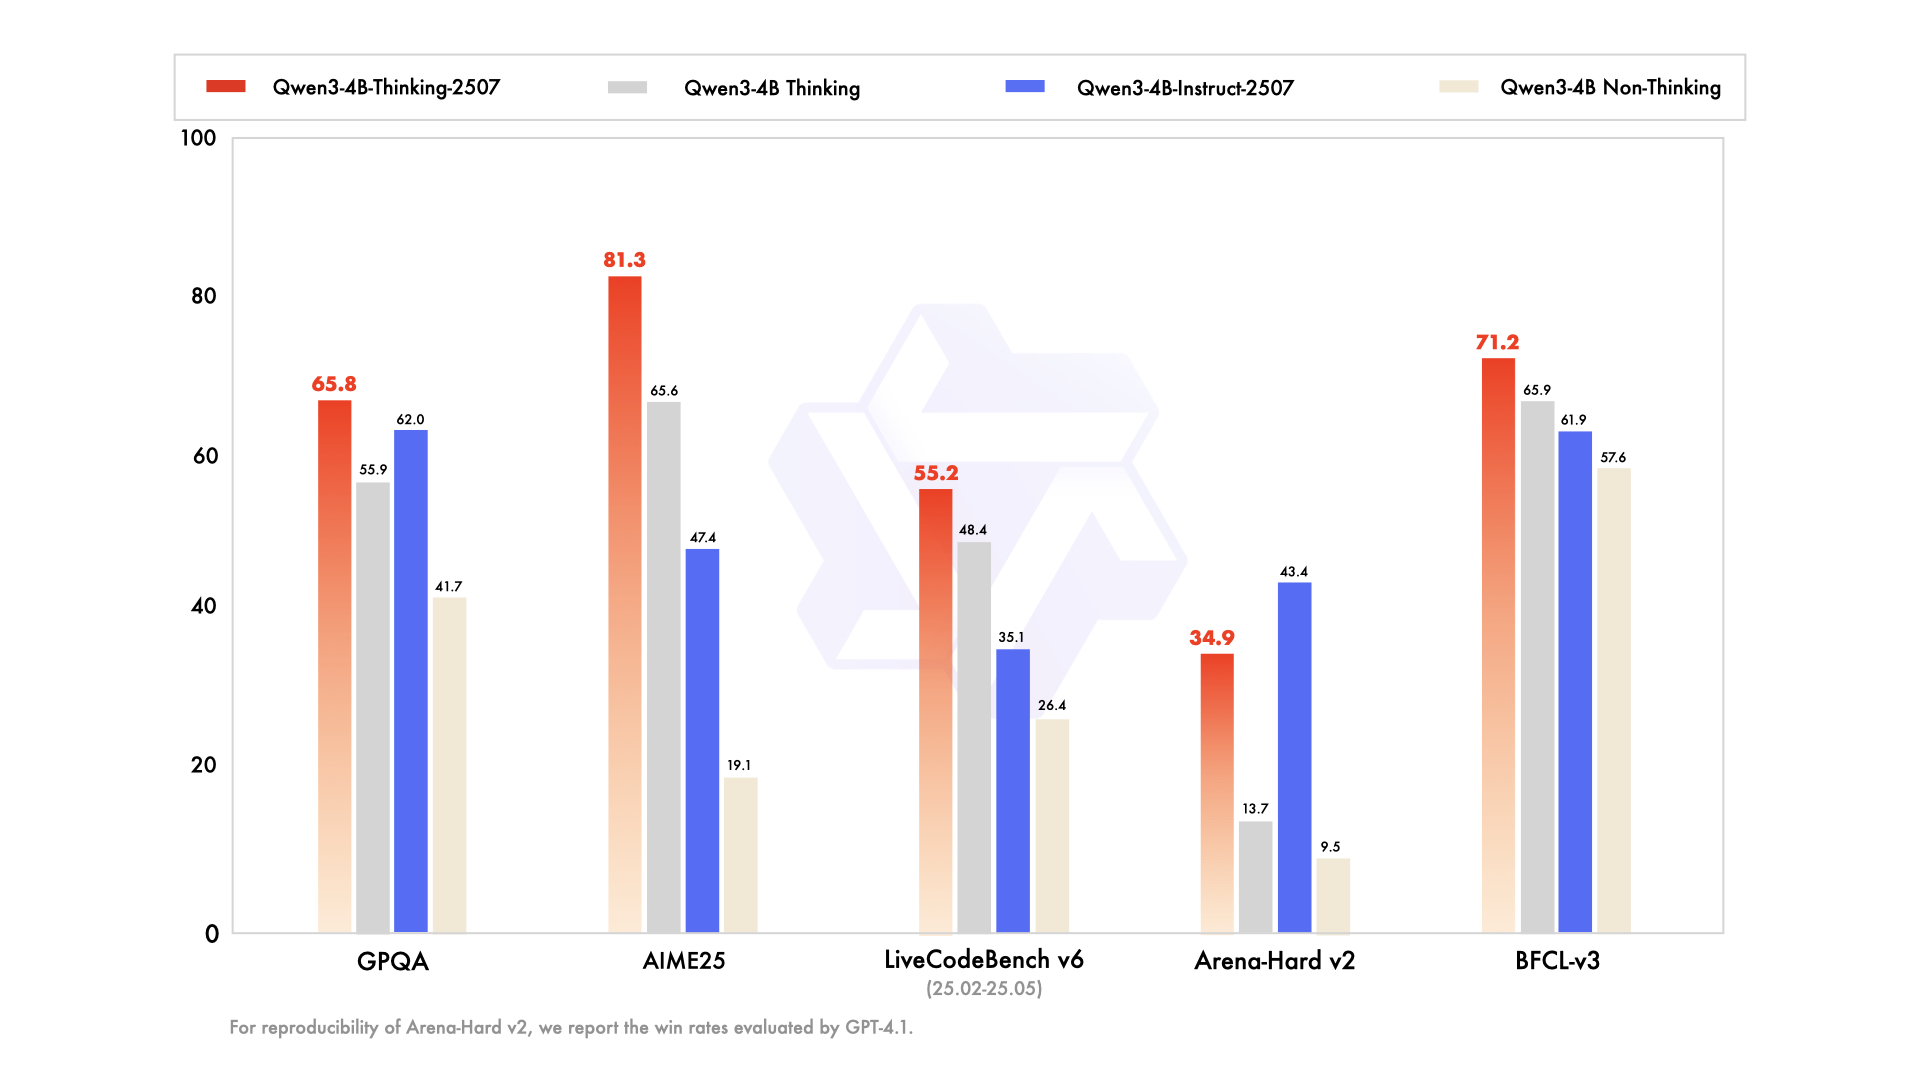
We introduce the updated version of the **Qwen3-4B non-thinking mode**, named **Qwen3-4B-Instruct-2507**, featuring the following key enhancements:
|
||||
|
||||
- **Significant improvements** in general capabilities, including **instruction following, logical reasoning, text comprehension, mathematics, science, coding and tool usage**.
|
||||
- **Substantial gains** in long-tail knowledge coverage across **multiple languages**.
|
||||
- **Markedly better alignment** with user preferences in **subjective and open-ended tasks**, enabling more helpful responses and higher-quality text generation.
|
||||
- **Enhanced capabilities** in **256K long-context understanding**.
|
||||
|
||||
|
||||
|
||||
## Model Overview
|
||||
|
||||
**Qwen3-4B-Instruct-2507** has the following features:
|
||||
- Type: Causal Language Models
|
||||
- Training Stage: Pretraining & Post-training
|
||||
- Number of Parameters: 4.0B
|
||||
- Number of Paramaters (Non-Embedding): 3.6B
|
||||
- Number of Layers: 36
|
||||
- Number of Attention Heads (GQA): 32 for Q and 8 for KV
|
||||
- Context Length: **262,144 natively**.
|
||||
|
||||
**NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
|
||||
|
||||
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/).
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
| | GPT-4.1-nano-2025-04-14 | Qwen3-30B-A3B Non-Thinking | Qwen3-4B Non-Thinking | Qwen3-4B-Instruct-2507 |
|
||||
|--- | --- | --- | --- | --- |
|
||||
| **Knowledge** | | | |
|
||||
| MMLU-Pro | 62.8 | 69.1 | 58.0 | **69.6** |
|
||||
| MMLU-Redux | 80.2 | 84.1 | 77.3 | **84.2** |
|
||||
| GPQA | 50.3 | 54.8 | 41.7 | **62.0** |
|
||||
| SuperGPQA | 32.2 | 42.2 | 32.0 | **42.8** |
|
||||
| **Reasoning** | | | |
|
||||
| AIME25 | 22.7 | 21.6 | 19.1 | **47.4** |
|
||||
| HMMT25 | 9.7 | 12.0 | 12.1 | **31.0** |
|
||||
| ZebraLogic | 14.8 | 33.2 | 35.2 | **80.2** |
|
||||
| LiveBench 20241125 | 41.5 | 59.4 | 48.4 | **63.0** |
|
||||
| **Coding** | | | |
|
||||
| LiveCodeBench v6 (25.02-25.05) | 31.5 | 29.0 | 26.4 | **35.1** |
|
||||
| MultiPL-E | 76.3 | 74.6 | 66.6 | **76.8** |
|
||||
| Aider-Polyglot | 9.8 | **24.4** | 13.8 | 12.9 |
|
||||
| **Alignment** | | | |
|
||||
| IFEval | 74.5 | **83.7** | 81.2 | 83.4 |
|
||||
| Arena-Hard v2* | 15.9 | 24.8 | 9.5 | **43.4** |
|
||||
| Creative Writing v3 | 72.7 | 68.1 | 53.6 | **83.5** |
|
||||
| WritingBench | 66.9 | 72.2 | 68.5 | **83.4** |
|
||||
| **Agent** | | | |
|
||||
| BFCL-v3 | 53.0 | 58.6 | 57.6 | **61.9** |
|
||||
| TAU1-Retail | 23.5 | 38.3 | 24.3 | **48.7** |
|
||||
| TAU1-Airline | 14.0 | 18.0 | 16.0 | **32.0** |
|
||||
| TAU2-Retail | - | 31.6 | 28.1 | **40.4** |
|
||||
| TAU2-Airline | - | 18.0 | 12.0 | **24.0** |
|
||||
| TAU2-Telecom | - | **18.4** | 17.5 | 13.2 |
|
||||
| **Multilingualism** | | | |
|
||||
| MultiIF | 60.7 | **70.8** | 61.3 | 69.0 |
|
||||
| MMLU-ProX | 56.2 | **65.1** | 49.6 | 61.6 |
|
||||
| INCLUDE | 58.6 | **67.8** | 53.8 | 60.1 |
|
||||
| PolyMATH | 15.6 | 23.3 | 16.6 | **31.1** |
|
||||
|
||||
*: For reproducibility, we report the win rates evaluated by GPT-4.1.
|
||||
|
||||
|
||||
## Quickstart
|
||||
|
||||
The code of Qwen3 has been in the latest Hugging Face `transformers` and we advise you to use the latest version of `transformers`.
|
||||
|
||||
With `transformers<4.51.0`, you will encounter the following error:
|
||||
```
|
||||
KeyError: 'qwen3'
|
||||
```
|
||||
|
||||
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
|
||||
```python
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/Qwen3-4B-Instruct-2507"
|
||||
|
||||
# load the tokenizer and the model
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
model_name,
|
||||
torch_dtype="auto",
|
||||
device_map="auto"
|
||||
)
|
||||
|
||||
# prepare the model input
|
||||
prompt = "Give me a short introduction to large language model."
|
||||
messages = [
|
||||
{"role": "user", "content": prompt}
|
||||
]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
)
|
||||
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
|
||||
|
||||
# conduct text completion
|
||||
generated_ids = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=16384
|
||||
)
|
||||
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
|
||||
|
||||
content = tokenizer.decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
print("content:", content)
|
||||
```
|
||||
|
||||
For deployment, you can use `sglang>=0.4.6.post1` or `vllm>=0.8.5` or to create an OpenAI-compatible API endpoint:
|
||||
- SGLang:
|
||||
```shell
|
||||
python -m sglang.launch_server --model-path Qwen/Qwen3-4B-Instruct-2507 --context-length 262144
|
||||
```
|
||||
- vLLM:
|
||||
```shell
|
||||
vllm serve Qwen/Qwen3-4B-Instruct-2507 --max-model-len 262144
|
||||
```
|
||||
|
||||
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
|
||||
|
||||
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
|
||||
|
||||
## Agentic Use
|
||||
|
||||
Qwen3 excels in tool calling capabilities. We recommend using [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent) to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
|
||||
|
||||
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
|
||||
```python
|
||||
from qwen_agent.agents import Assistant
|
||||
|
||||
# Define LLM
|
||||
llm_cfg = {
|
||||
'model': 'Qwen3-4B-Instruct-2507',
|
||||
|
||||
# Use a custom endpoint compatible with OpenAI API:
|
||||
'model_server': 'http://localhost:8000/v1', # api_base
|
||||
'api_key': 'EMPTY',
|
||||
}
|
||||
|
||||
# Define Tools
|
||||
tools = [
|
||||
{'mcpServers': { # You can specify the MCP configuration file
|
||||
'time': {
|
||||
'command': 'uvx',
|
||||
'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
|
||||
},
|
||||
"fetch": {
|
||||
"command": "uvx",
|
||||
"args": ["mcp-server-fetch"]
|
||||
}
|
||||
}
|
||||
},
|
||||
'code_interpreter', # Built-in tools
|
||||
]
|
||||
|
||||
# Define Agent
|
||||
bot = Assistant(llm=llm_cfg, function_list=tools)
|
||||
|
||||
# Streaming generation
|
||||
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
|
||||
for responses in bot.run(messages=messages):
|
||||
pass
|
||||
print(responses)
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
To achieve optimal performance, we recommend the following settings:
|
||||
|
||||
1. **Sampling Parameters**:
|
||||
- We suggest using `Temperature=0.7`, `TopP=0.8`, `TopK=20`, and `MinP=0`.
|
||||
- For supported frameworks, you can adjust the `presence_penalty` parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
|
||||
|
||||
2. **Adequate Output Length**: We recommend using an output length of 16,384 tokens for most queries, which is adequate for instruct models.
|
||||
|
||||
3. **Standardize Output Format**: We recommend using prompts to standardize model outputs when benchmarking.
|
||||
- **Math Problems**: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
|
||||
- **Multiple-Choice Questions**: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the `answer` field with only the choice letter, e.g., `"answer": "C"`."
|
||||
|
||||
### Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite.
|
||||
|
||||
```
|
||||
@misc{qwen3technicalreport,
|
||||
title={Qwen3 Technical Report},
|
||||
author={Qwen Team},
|
||||
year={2025},
|
||||
eprint={2505.09388},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL},
|
||||
url={https://arxiv.org/abs/2505.09388},
|
||||
}
|
||||
```
|
||||
|
||||
<!--End Original Model Card-->
|
||||
|
||||
---
|
||||
|
||||
# <span id="testllm" style="color: #7F7FFF;">🚀 If you find these models useful</span>
|
||||
|
||||
Help me test my **AI-Powered Quantum Network Monitor Assistant** with **quantum-ready security checks**:
|
||||
|
||||
👉 [Quantum Network Monitor](https://readyforquantum.com/?assistant=open&utm_source=huggingface&utm_medium=referral&utm_campaign=huggingface_repo_readme)
|
||||
|
||||
|
||||
The full Open Source Code for the Quantum Network Monitor Service available at my github repos ( repos with NetworkMonitor in the name) : [Source Code Quantum Network Monitor](https://github.com/Mungert69). You will also find the code I use to quantize the models if you want to do it yourself [GGUFModelBuilder](https://github.com/Mungert69/GGUFModelBuilder)
|
||||
|
||||
💬 **How to test**:
|
||||
Choose an **AI assistant type**:
|
||||
- `TurboLLM` (GPT-4.1-mini)
|
||||
- `HugLLM` (Hugginface Open-source models)
|
||||
- `TestLLM` (Experimental CPU-only)
|
||||
|
||||
### **What I’m Testing**
|
||||
I’m pushing the limits of **small open-source models for AI network monitoring**, specifically:
|
||||
- **Function calling** against live network services
|
||||
- **How small can a model go** while still handling:
|
||||
- Automated **Nmap security scans**
|
||||
- **Quantum-readiness checks**
|
||||
- **Network Monitoring tasks**
|
||||
|
||||
🟡 **TestLLM** – Current experimental model (llama.cpp on 2 CPU threads on huggingface docker space):
|
||||
- ✅ **Zero-configuration setup**
|
||||
- ⏳ 30s load time (slow inference but **no API costs**) . No token limited as the cost is low.
|
||||
- 🔧 **Help wanted!** If you’re into **edge-device AI**, let’s collaborate!
|
||||
|
||||
### **Other Assistants**
|
||||
🟢 **TurboLLM** – Uses **gpt-4.1-mini** :
|
||||
- **It performs very well but unfortunatly OpenAI charges per token. For this reason tokens usage is limited.
|
||||
- **Create custom cmd processors to run .net code on Quantum Network Monitor Agents**
|
||||
- **Real-time network diagnostics and monitoring**
|
||||
- **Security Audits**
|
||||
- **Penetration testing** (Nmap/Metasploit)
|
||||
|
||||
🔵 **HugLLM** – Latest Open-source models:
|
||||
- 🌐 Runs on Hugging Face Inference API. Performs pretty well using the lastest models hosted on Novita.
|
||||
|
||||
### 💡 **Example commands you could test**:
|
||||
1. `"Give me info on my websites SSL certificate"`
|
||||
2. `"Check if my server is using quantum safe encyption for communication"`
|
||||
3. `"Run a comprehensive security audit on my server"`
|
||||
4. '"Create a cmd processor to .. (what ever you want)" Note you need to install a [Quantum Network Monitor Agent](https://readyforquantum.com/Download/?utm_source=huggingface&utm_medium=referral&utm_campaign=huggingface_repo_readme) to run the .net code on. This is a very flexible and powerful feature. Use with caution!
|
||||
|
||||
### Final Word
|
||||
|
||||
I fund the servers used to create these model files, run the Quantum Network Monitor service, and pay for inference from Novita and OpenAI—all out of my own pocket. All the code behind the model creation and the Quantum Network Monitor project is [open source](https://github.com/Mungert69). Feel free to use whatever you find helpful.
|
||||
|
||||
If you appreciate the work, please consider [buying me a coffee](https://www.buymeacoffee.com/mahadeva) ☕. Your support helps cover service costs and allows me to raise token limits for everyone.
|
||||
|
||||
I'm also open to job opportunities or sponsorship.
|
||||
|
||||
Thank you! 😊
|
||||
1
configuration.json
Normal file
1
configuration.json
Normal file
@@ -0,0 +1 @@
|
||||
{"framework": "pytorch", "task": "text-generation", "allow_remote": true}
|
||||
Reference in New Issue
Block a user