



Built with Qwen
## Model Description GGUF quantized versions of [GuminiResearch/Gumini-1B-Base](https://huggingface.co/GuminiResearch/Gumini-1B-Base) for use with [llama.cpp](https://github.com/ggerganov/llama.cpp) and compatible tools (Ollama, LM Studio, etc.). All quantizations were created using **importance matrix (imatrix)** calibration for optimal quality preservation. > This is a **BASE model**, not instruction-tuned. > It produces text continuations rather than conversational responses. ## Model Details | Attribute | Value | |-----------|-------| | **Original Model** | [Gumini-1B-Base](https://huggingface.co/GuminiResearch/Gumini-1B-Base) | | **Quantized by** | [Gumin Kwon (권구민)](https://linkedin.com/in/devgumin) | | **Parameters** | 1.08B | | **Layers** | 10 | | **Hidden Size** | 2048 | | **Base PPL (F16)** | 15.36 | ## Quantization Results ### Perplexity Comparison 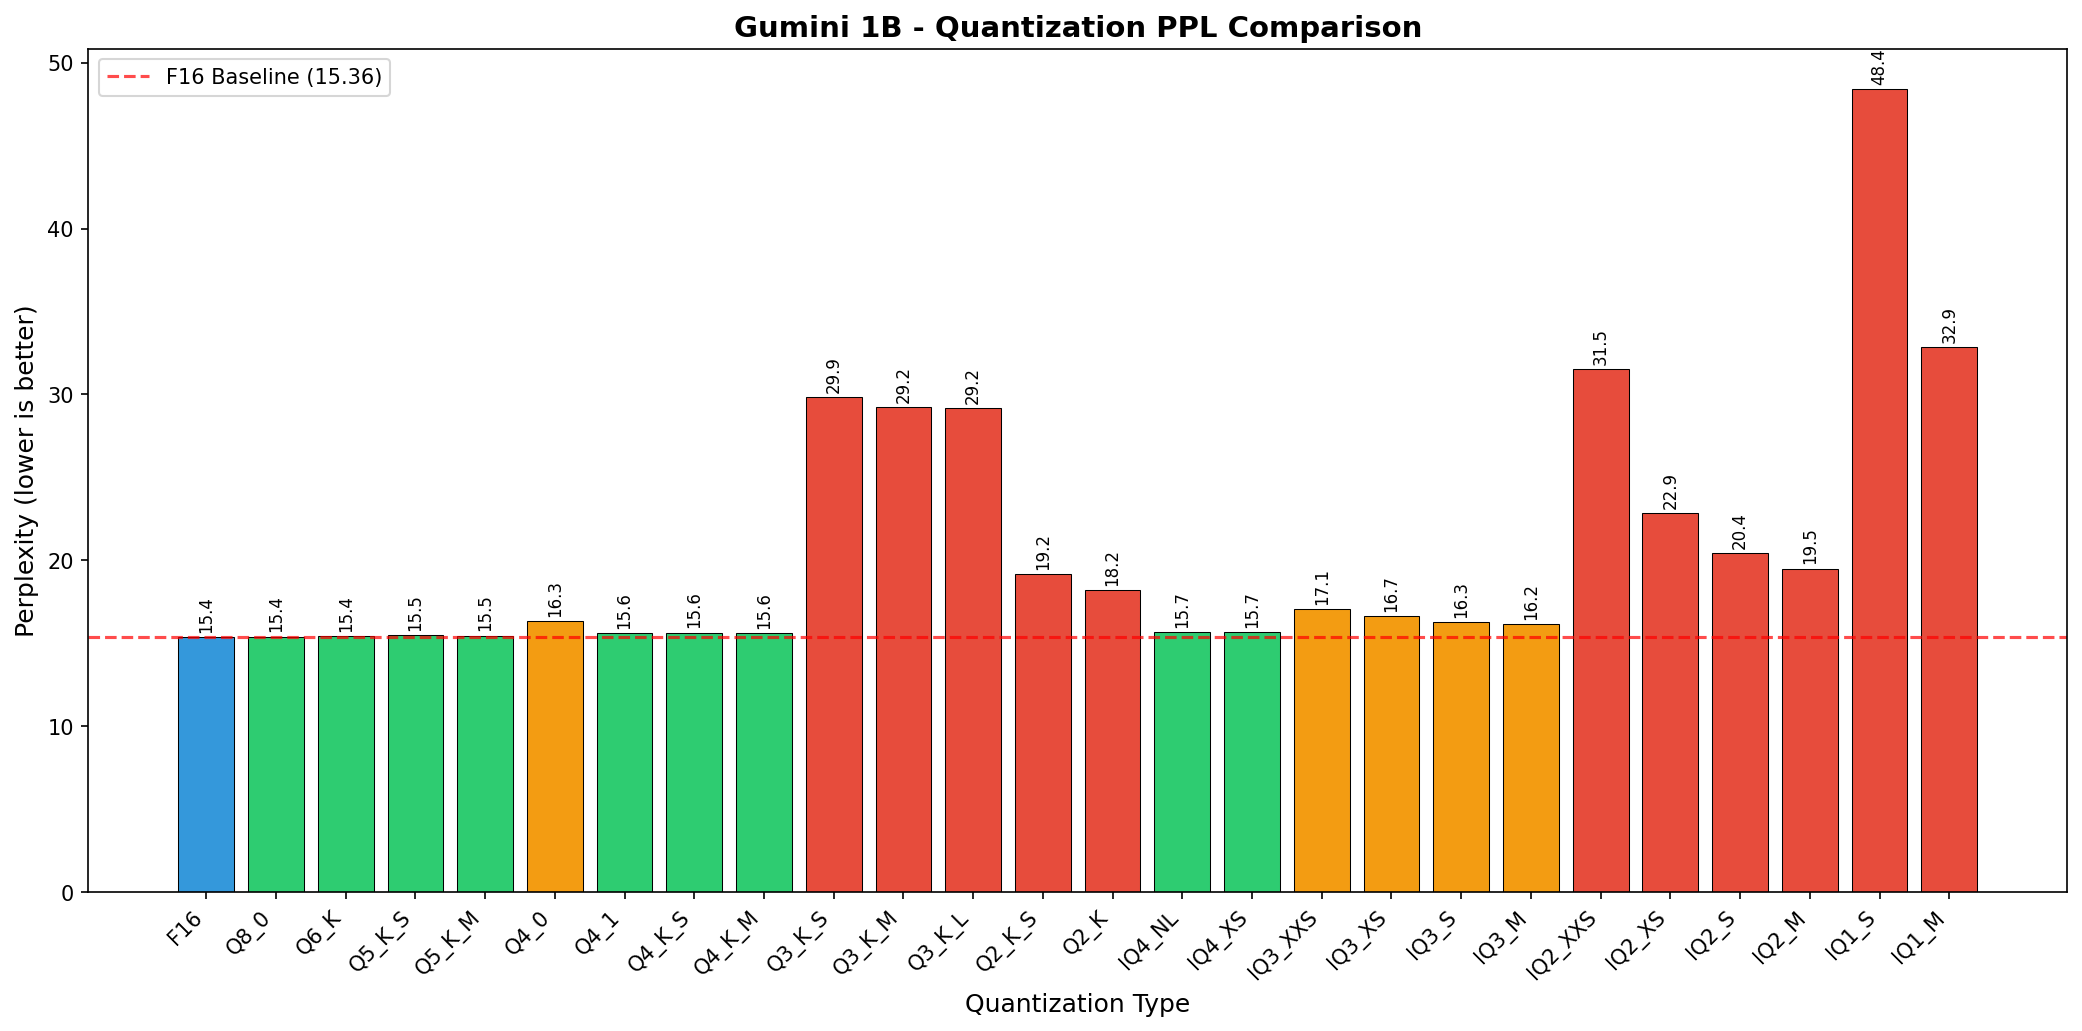 ### PPL vs Size Trade-off  ### Recommended Quantizations | Quant | PPL | Size | PPL Δ | Quality | Use Case | |-------|-----|------|-------|---------|----------| | **Q8_0** | 15.40 | 1.1G | +0.03 | Excellent | Maximum quality | | **Q6_K** | 15.43 | 852M | +0.07 | Excellent | High quality | | **Q5_K_M** | 15.46 | 769M | +0.10 | Excellent | Balanced (recommended) | | **Q4_K_M** | 15.61 | 691M | +0.25 | Very Good | Size optimized | | **IQ4_XS** | 15.69 | 641M | +0.33 | Very Good | imatrix 4-bit | | **IQ3_M** | 16.17 | 574M | +0.81 | Good | Mobile/Edge | ### All Quantization Results  ## Usage ### With llama.cpp ```bash # Download huggingface-cli download GuminiResearch/Gumini-1B-Base-i1-GGUF Gumini-1B-Base.i1-Q4_K_M.gguf # Run ./llama-cli -m Gumini-1B-Base.i1-Q4_K_M.gguf -p "저는 구미니입니다." -n 100 ``` ### With Ollama ```bash echo 'FROM ./Gumini-1B-Base.i1-Q4_K_M.gguf' > Modelfile ollama create gumini-1b -f Modelfile ollama run gumini-1b ``` ### With LM Studio 1. Download any `.gguf` file from this repo 2. Import into LM Studio 3. Start generating! ## Quantization Guide  ### Tips - **Best quality**: Use Q8_0 or Q6_K - **Balanced**: Use Q5_K_M or Q4_K_M - **Mobile/Edge**: Use IQ4_XS or IQ3_M - **"i1" prefix**: Indicates imatrix was used during quantization ## Original Model **Gumini-1B** (구미니) is a bilingual Korean-English base language model created by inheriting the first 10 layers of **Qwen 2.5 3B** using the *Inheritune* methodology. - **Training Method**: Inheritune + Pretraining - **Tokens Trained**: ~393M tokens - **Training Data**: 80% Korean, 20% English See [GuminiResearch/Gumini-1B-Base](https://huggingface.co/GuminiResearch/Gumini-1B-Base) for full details. ## License ### Qwen Research License (Non-Commercial) This model is **Built with Qwen** and derived from Qwen 2.5 3B. ``` Qwen is licensed under the Qwen RESEARCH LICENSE AGREEMENT. Copyright (c) Alibaba Cloud. All Rights Reserved. ``` **This model is for NON-COMMERCIAL / RESEARCH use only.** For commercial use, contact Alibaba Cloud. ## Citation ```bibtex @misc{gumini2025, title={Gumini-1B: Bilingual Language Model Built with Qwen via Inheritune}, author={Gumin Kwon}, year={2025}, note={Built with Qwen}, url={https://huggingface.co/GuminiResearch/Gumini-1B-Base-i1-GGUF} } ``` ## Author **Gumin Kwon (권구민)** - 🔗 LinkedIn: https://linkedin.com/in/devgumin - 🤗 Hugging Face: https://huggingface.co/GuminiResearch - 𝕏 X (Twitter): https://x.com/Gumini_Research - 📸 Instagram: https://www.instagram.com/gumini_research/ ---
Built with Qwen
Gumini - 작지만 똑똑한 AI