初始化项目,由ModelHub XC社区提供模型
Model: BatsResearch/bonito-v1
Source: Original Platform
This commit is contained in:
 ModelHub XC
35
.gitattributes
vendored
Normal file
35
.gitattributes
vendored
Normal file
@@ -0,0 +1,35 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
152
README.md
Normal file
152
README.md
Normal file
@@ -0,0 +1,152 @@
|
||||
---
|
||||
datasets:
|
||||
- BatsResearch/ctga-v1
|
||||
language:
|
||||
- en
|
||||
library_name: transformers
|
||||
pipeline_tag: text2text-generation
|
||||
tags:
|
||||
- data generation
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# Model Card for bonito
|
||||
|
||||
<!-- Provide a quick summary of what the model is/does. -->
|
||||
|
||||
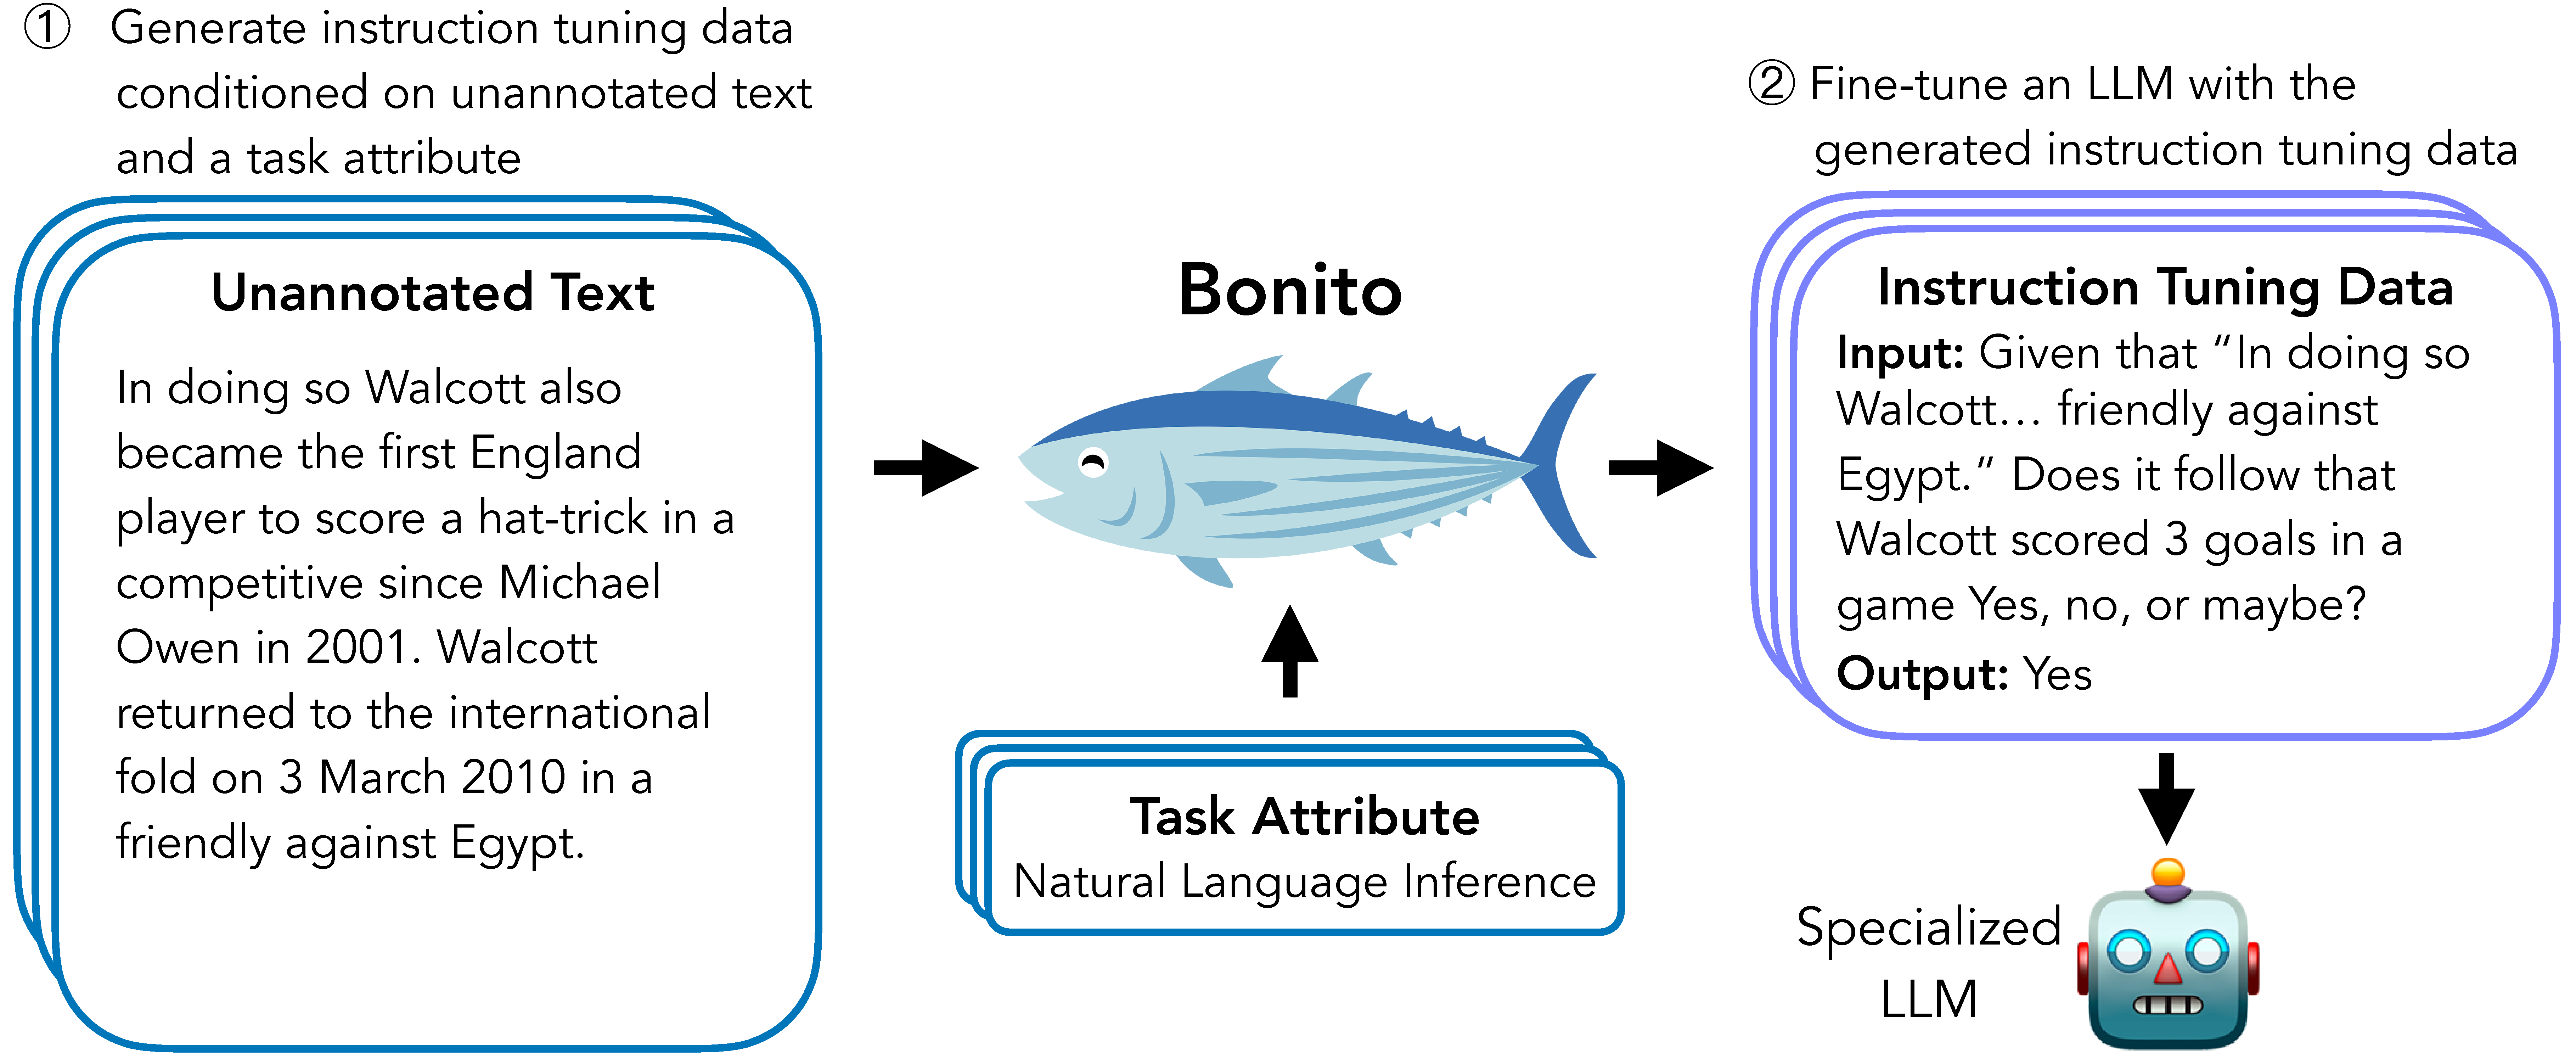
Bonito is an open-source model for conditional task generation: the task of converting unannotated text into task-specific training datasets for instruction tuning.
|
||||
|
||||
|
||||
|
||||
## Model Details
|
||||
|
||||
### Model Description
|
||||
|
||||
<!-- Provide a longer summary of what this model is. -->
|
||||
|
||||
Bonito can be used to create synthetic instruction tuning datasets to adapt large language models on users' specialized, private data.
|
||||
In our [paper](https://arxiv.org/abs/2402.18334), we show that Bonito can be used to adapt both pretrained and instruction tuned models to tasks without any annotations.
|
||||
|
||||
- **Developed by:** Nihal V. Nayak, Yiyang Nan, Avi Trost, and Stephen H. Bach
|
||||
- **Model type:** MistralForCausalLM
|
||||
- **Language(s) (NLP):** English
|
||||
- **License:** Apache 2.0
|
||||
- **Finetuned from model:** `mistralai/Mistral-7B-v0.1`
|
||||
|
||||
### Model Sources
|
||||
|
||||
<!-- Provide the basic links for the model. -->
|
||||
|
||||
- **Repository:** [https://github.com/BatsResearch/bonito](https://github.com/BatsResearch/bonito)
|
||||
- **Paper:** [Learning to Generate Instruction Tuning Datasets for
|
||||
Zero-Shot Task Adaptation](https://arxiv.org/abs/2402.18334)
|
||||
|
||||
## Uses
|
||||
|
||||
<!-- Address questions around how the model is intended to be used, including the foreseeable users of the model and those affected by the model. -->
|
||||
|
||||
### Direct Use
|
||||
|
||||
<!-- This section is for the model use without fine-tuning or plugging into a larger ecosystem/app. -->
|
||||
To easily generate synthetic instruction tuning datasets, we recommend using the [bonito](https://github.com/BatsResearch/bonito) package built using the `transformers` and the `vllm` libraries.
|
||||
|
||||
```python
|
||||
from bonito import Bonito
|
||||
from vllm import SamplingParams
|
||||
from datasets import load_dataset
|
||||
|
||||
# Initialize the Bonito model
|
||||
bonito = Bonito("BatsResearch/bonito-v1")
|
||||
|
||||
# load dataaset with unannotated text
|
||||
unannotated_text = load_dataset(
|
||||
"BatsResearch/bonito-experiment",
|
||||
"unannotated_contract_nli"
|
||||
)["train"].select(range(10))
|
||||
|
||||
# Generate synthetic instruction tuning dataset
|
||||
sampling_params = SamplingParams(max_tokens=256, top_p=0.95, temperature=0.5, n=1)
|
||||
synthetic_dataset = bonito.generate_tasks(
|
||||
unannotated_text,
|
||||
context_col="input",
|
||||
task_type="nli",
|
||||
sampling_params=sampling_params
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
### Out-of-Scope Use
|
||||
|
||||
<!-- This section addresses misuse, malicious use, and uses that the model will not work well for. -->
|
||||
|
||||
Our model is trained to generate the following task types: summarization, sentiment analysis, multiple-choice question answering, extractive question answering, topic classification, natural language inference, question generation, text generation, question answering without choices, paraphrase identification, sentence completion, yes-no question answering, word sense disambiguation, paraphrase generation, textual entailment, and
|
||||
coreference resolution.
|
||||
The model might not produce accurate synthetic tasks beyond these task types.
|
||||
|
||||
## Bias, Risks, and Limitations
|
||||
|
||||
<!-- This section is meant to convey both technical and sociotechnical limitations. -->
|
||||
**Limitations**
|
||||
|
||||
Our work relies on the availability of large amounts of unannotated text.
|
||||
If only a small quantity of unannotated text is present, the target language model, after adaptation, may experience a drop in performance.
|
||||
While we demonstrate positive improvements on pretrained and instruction-tuned models, our observations are limited to the three task types (yes-no question answering, extractive question answering, and natural language inference) considered in our paper.
|
||||
|
||||
**Risks**
|
||||
|
||||
Bonito poses risks similar to those of any large language model.
|
||||
For example, our model could be used to generate factually incorrect datasets in specialized domains.
|
||||
Our model can exhibit the biases and stereotypes of the base model, Mistral-7B, even after extensive supervised fine-tuning.
|
||||
Finally, our model does not include safety training and can potentially generate harmful content.
|
||||
|
||||
### Recommendations
|
||||
|
||||
<!-- This section is meant to convey recommendations with respect to the bias, risk, and technical limitations. -->
|
||||
|
||||
We recommend users thoroughly inspect the generated tasks and benchmark performance on critical datasets before deploying the models trained with the synthetic tasks into the real world.
|
||||
|
||||
## Training Details
|
||||
|
||||
### Training Data
|
||||
|
||||
<!-- This should link to a Dataset Card, perhaps with a short stub of information on what the training data is all about as well as documentation related to data pre-processing or additional filtering. -->
|
||||
To train Bonito, we create a new dataset called conditional task generation with attributes by remixing existing instruction tuning datasets.
|
||||
See [ctga-v1](https://huggingface.co/datasets/BatsResearch/ctga-v1) for more details.
|
||||
|
||||
### Training Procedure
|
||||
|
||||
<!-- This relates heavily to the Technical Specifications. Content here should link to that section when it is relevant to the training procedure. -->
|
||||
|
||||
#### Training Hyperparameters
|
||||
|
||||
- **Training regime:** <!--fp32, fp16 mixed precision, bf16 mixed precision, bf16 non-mixed precision, fp16 non-mixed precision, fp8 mixed precision -->
|
||||
We train the model using [Q-LoRA](https://github.com/artidoro/qlora) by optimizing the cross entropy loss over the output tokens.
|
||||
The model is trained for 100,000 steps.
|
||||
The training takes about 4 days on four GPUs to complete.
|
||||
|
||||
We use the following hyperparameters:
|
||||
- Q-LoRA rank (r): 64
|
||||
- Q-LoRA scaling factor (alpha): 4
|
||||
- Q-LoRA dropout: 0
|
||||
- Optimizer: Paged AdamW
|
||||
- Learning rate scheduler: linear
|
||||
- Max. learning rate: 1e-04
|
||||
- Min. learning rate: 0
|
||||
- Weight decay: 0
|
||||
- Dropout: 0
|
||||
- Max. gradient norm: 0.3
|
||||
- Effective batch size: 16
|
||||
- Max. input length: 2,048
|
||||
- Max. output length: 2,048
|
||||
- Num. steps: 100,000
|
||||
|
||||
## Citation
|
||||
|
||||
<!-- If there is a paper or blog post introducing the model, the APA and Bibtex information for that should go in this section. -->
|
||||
```
|
||||
@inproceedings{bonito:aclfindings24,
|
||||
title = {Learning to Generate Instruction Tuning Datasets for Zero-Shot Task Adaptation},
|
||||
author = {Nayak, Nihal V. and Nan, Yiyang and Trost, Avi and Bach, Stephen H.},
|
||||
booktitle = {Findings of the Association for Computational Linguistics: ACL 2024},
|
||||
year = {2024}}
|
||||
```
|
||||
5
added_tokens.json
Normal file
5
added_tokens.json
Normal file
@@ -0,0 +1,5 @@
|
||||
{
|
||||
"</s>": 2,
|
||||
"<s>": 1,
|
||||
"<unk>": 0
|
||||
}
|
||||
25
config.json
Normal file
25
config.json
Normal file
@@ -0,0 +1,25 @@
|
||||
{
|
||||
"_name_or_path": "mistralai/Mistral-7B-v0.1",
|
||||
"architectures": [
|
||||
"MistralForCausalLM"
|
||||
],
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "silu",
|
||||
"hidden_size": 4096,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 14336,
|
||||
"max_position_embeddings": 32768,
|
||||
"model_type": "mistral",
|
||||
"num_attention_heads": 32,
|
||||
"num_hidden_layers": 32,
|
||||
"num_key_value_heads": 8,
|
||||
"rms_norm_eps": 1e-05,
|
||||
"rope_theta": 10000.0,
|
||||
"sliding_window": 4096,
|
||||
"tie_word_embeddings": false,
|
||||
"torch_dtype": "bfloat16",
|
||||
"transformers_version": "4.34.0",
|
||||
"use_cache": true,
|
||||
"vocab_size": 32000
|
||||
}
|
||||
6
generation_config.json
Normal file
6
generation_config.json
Normal file
@@ -0,0 +1,6 @@
|
||||
{
|
||||
"_from_model_config": true,
|
||||
"bos_token_id": 1,
|
||||
"eos_token_id": 2,
|
||||
"transformers_version": "4.34.0"
|
||||
}
|
||||
3
pytorch_model-00001-of-00002.bin
Normal file
3
pytorch_model-00001-of-00002.bin
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:37d51988247d0def4e308d08429cf3f85b5771003a7233a61d5665634cf12603
|
||||
size 9943028044
|
||||
3
pytorch_model-00002-of-00002.bin
Normal file
3
pytorch_model-00002-of-00002.bin
Normal file
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:7155a02177dc9948496e6acf3c1df4d5b2003aa21e897fc30a5f0cada1ff7677
|
||||
size 5064823659
|
||||
298
pytorch_model.bin.index.json
Normal file
298
pytorch_model.bin.index.json
Normal file
@@ -0,0 +1,298 @@
|
||||
{
|
||||
"metadata": {
|
||||
"total_size": 14483464192
|
||||
},
|
||||
"weight_map": {
|
||||
"lm_head.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.embed_tokens.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.0.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.1.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.10.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.11.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.12.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.13.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.14.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.15.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.16.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.17.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.18.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.19.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.2.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.20.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.21.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.22.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.22.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.22.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.22.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.22.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.22.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.22.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.22.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.22.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.23.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.23.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.24.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.25.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.26.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.27.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.28.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.29.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.3.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.3.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.30.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.30.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.input_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.mlp.down_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.mlp.gate_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.mlp.up_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.post_attention_layernorm.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.self_attn.k_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.self_attn.o_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.self_attn.q_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.31.self_attn.v_proj.weight": "pytorch_model-00002-of-00002.bin",
|
||||
"model.layers.4.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.4.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.5.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.6.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.7.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.8.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.input_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.mlp.down_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.mlp.gate_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.mlp.up_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.post_attention_layernorm.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.self_attn.k_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.self_attn.o_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.self_attn.q_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.layers.9.self_attn.v_proj.weight": "pytorch_model-00001-of-00002.bin",
|
||||
"model.norm.weight": "pytorch_model-00002-of-00002.bin"
|
||||
}
|
||||
}
|
||||
10
special_tokens_map.json
Normal file
10
special_tokens_map.json
Normal file
@@ -0,0 +1,10 @@
|
||||
{
|
||||
"additional_special_tokens": [
|
||||
"<unk>",
|
||||
"<s>",
|
||||
"</s>"
|
||||
],
|
||||
"bos_token": "<s>",
|
||||
"eos_token": "</s>",
|
||||
"unk_token": "<unk>"
|
||||
}
|
||||
91122
tokenizer.json
Normal file
91122
tokenizer.json
Normal file
File diff suppressed because it is too large
Load Diff
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
BIN
tokenizer.model
(Stored with Git LFS)
Normal file
Binary file not shown.
44
tokenizer_config.json
Normal file
44
tokenizer_config.json
Normal file
@@ -0,0 +1,44 @@
|
||||
{
|
||||
"added_tokens_decoder": {
|
||||
"0": {
|
||||
"content": "<unk>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"1": {
|
||||
"content": "<s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
},
|
||||
"2": {
|
||||
"content": "</s>",
|
||||
"lstrip": false,
|
||||
"normalized": false,
|
||||
"rstrip": false,
|
||||
"single_word": false,
|
||||
"special": true
|
||||
}
|
||||
},
|
||||
"additional_special_tokens": [
|
||||
"<unk>",
|
||||
"<s>",
|
||||
"</s>"
|
||||
],
|
||||
"bos_token": "<s>",
|
||||
"clean_up_tokenization_spaces": false,
|
||||
"eos_token": "</s>",
|
||||
"legacy": true,
|
||||
"model_max_length": 1000000000000000019884624838656,
|
||||
"pad_token": null,
|
||||
"sp_model_kwargs": {},
|
||||
"spaces_between_special_tokens": false,
|
||||
"tokenizer_class": "LlamaTokenizer",
|
||||
"unk_token": "<unk>",
|
||||
"use_default_system_prompt": true
|
||||
}
|
||||
Reference in New Issue
Block a user